---
license: other
license_name: ltx-2.x-community-license
license_link: https://github.com/Lightricks/LTX-2/blob/main/LICENSE-2_x
base_model: Lightricks/LTX-2.5
base_model_relation: adapter
library_name: diffusion-single-file
language:
- en
tags:
- ltx-2.5
- ltx-video
- ic-lora
- lora
- video-to-video
- comfyui
- smoke
- fire
- vfx
---
# ainvfx-fluid ยท paint your fluid, skip the simulation, generate the result
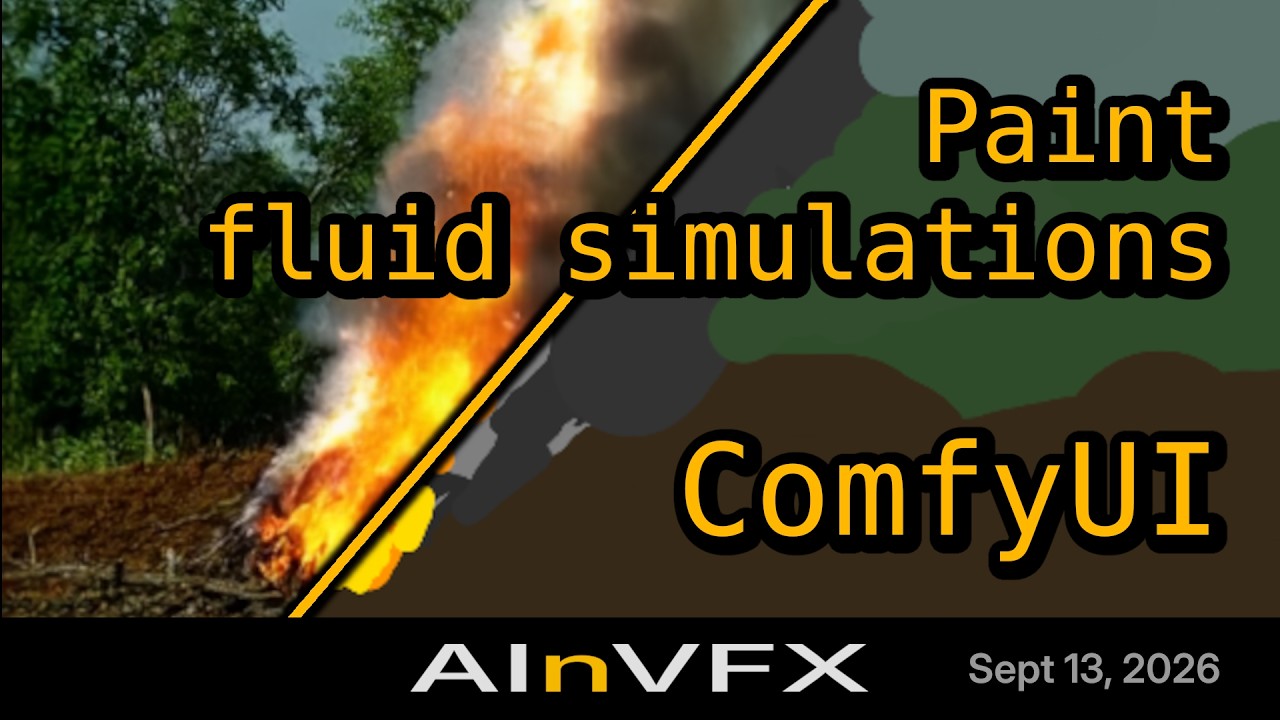
An **IC-LoRA for LTX 2.5** (22B) by [AInVFX](https://www.ainvfx.com). You paint flat colour blobs on a first frame and a last frame (and, if you want, a few frames in between); the LoRA replaces the blobs with smoke, steam or fire and animates from one keyframe to the next. Trigger word: **`ainvfxfluid`**.
Made for compositing and previz as an art-directable stock footage generator.
๐บ **[Watch the 45-minute tutorial](https://www.youtube.com/watch?v=Ho4tmJzEkIs)** ยท ๐ฐ **[Read the article](https://www.ainvfx.com/blog/paint-your-fluid-simulations-a-free-ltx-2-5-ic-lora-for-smoke-and-fire-in-comfyui/)** โ setup, control video rules, painting, prompting, and how the model was trained.
| | |
|---|---|
| **File** | [`ltx-2.5/ainvfx-fluid.safetensors`](ltx-2.5/ainvfx-fluid.safetensors) (654 MB, ComfyUI format, rank 32) |
| **Base model** | [Lightricks/LTX-2.5](https://huggingface.co/Lightricks/LTX-2.5), 22B transformer, dev or distilled |
| **Control** | a video, same resolution and length as the output: keyframes painted in flat colours, black frames in between |
| **Workflow** | [`workflow/ainvfx-fluid_painted_smoke_plume.json`](workflow/ainvfx-fluid_painted_smoke_plume.json), paints both frames inside ComfyUI |
| **Tutorial** | [45-minute deep dive on YouTube](https://www.youtube.com/watch?v=Ho4tmJzEkIs) |
| **Article** | [Paint your fluid simulations](https://www.ainvfx.com/blog/paint-your-fluid-simulations-a-free-ltx-2-5-ic-lora-for-smoke-and-fire-in-comfyui/) |
| **License** | LTX-2.x Community License (see below) |
## Samples
Left: the control video. Right: the result. Six pairs, none of the source clips was in the training set. All results were generated with the LTX 2.5 22B distilled transformer (int8), 8 steps, CFG 1, seed 42, sampler `euler_ancestral`, LoRA strength 1.0, negative prompt `blurry, low quality, distorted, watermark`. The frame rate follows the control video (24, 25 or 50 fps). **Every `_result` video is AI-generated** with LTX 2.5 and this LoRA; the files carry no C2PA manifest, this line and the file names are the disclosure.
| Control (painted keyframes, black in between) | Result |
|
|
01 ยท 960 x 512 ยท ainvfxfluid, wild fire |
|
|
02 ยท 960 x 512 ยท ainvfxfluid, smoke plume |
|
|
03 ยท 512 x 960 (portrait) ยท ainvfxfluid, fire |
|
|
04 ยท 960 x 512 ยท ainvfxfluid, fire ball exploding towards camera |
|
|
05 ยท 960 x 512 ยท a real photo with the smoke painted on top; the result keeps the composition and colours, not the exact photo ยท ainvfxfluid, smoke plume rising over a city, blue sky, aerial view |
|
|
06 ยท 512 x 512 ยท the two frames painted in ComfyUI with the workflow below ยท ainvfxfluid, smoke plume |
## Samples from the community
From [Nathan Shipley](https://www.nathanshipley.com/):
## How to use it in ComfyUI
1. Put `ainvfx-fluid.safetensors` in `ComfyUI/models/loras/`. You need ComfyUI with the **[ComfyUI-LTXVideo](https://github.com/Lightricks/ComfyUI-LTXVideo)** node pack by Lightricks (Manager: search ยซ LTXVideo ยป; the IC-LoRA loader and guide nodes come from it) and the LTX 2.5 models of its example workflows (transformer, video and audio VAE, Gemma text encoder).
2. Load it with **`LTX IC-LoRA Loader Model Only`**, strength 1.0. The loader reads the reference downscale factor (2) from the file: nothing to set.
3. Build the **control video**, same size and length as the shot you want:
* width and height **multiples of 64** (512 x 512, 960 x 512, 512 x 960, 1024 x 576, 1920 x 1088 all work);
* **121 frames** is the tested length; 24, 25 and 50 fps were trained;
* your painted first frame at index **0**, your painted last frame at index **120**, **black** frames everywhere else;
* optional keyframes in between must sit on the 8-frame grid of the LTX VAE: index 1, 9, 17, ... 113 (a multiple of 8, plus 1). A keyframe can be a single frame or held over its 8 frames; both were trained.
* paint **flat colours**: one blob per volume (e.g. light grey for smoke, white for steam, orange and yellow for fire), a black background or a few flat zones for sky and ground. Sharp, deliberate shapes are followed closely.
4. Prompt: `ainvfxfluid, ` then what the fluid is and how it is lit. `ainvfxfluid, smoke plume` is enough; a fuller sentence helps for what the LoRA saw less.
5. Generate with the distilled model (8 steps, CFG 1) or the dev model with its usual sampler settings. Strength 0 gives the "no LoRA" comparison.
Every step above is shown on screen in the [tutorial](https://www.youtube.com/watch?v=Ho4tmJzEkIs), including the ComfyUI-LTXVideo install, the Kornia `pad` import fix, and where each gated LTX 2.5 file goes.
The shipped workflow does steps 2 to 5 with two **Painter** nodes and opens **pre-painted** with a smoke plume: copy the two PNGs from [`workflow/inputs/`](workflow/inputs) into `ComfyUI/input/` once, load the workflow, queue. Then repaint: the first frame, and the changes on the last frame. Replace the Painters with a `Load Video` of your own 121-frame control clip if you prefer to paint elsewhere. Apart from the LTXVideo pack, every node is ComfyUI core (the `Painter` node needs a recent ComfyUI and `Nodes 2.0` enabled).
**Painting over a photo.** You can paint a fluid on a real photograph and use that as first and last frame. The result keeps the composition and the colours of the photograph and puts the fluid where you painted it, but it is a video *inspired by* the photo, not a pixel-exact match of it (see sample 05 above). For a locked plate, generate the fluid over a black background and composite it back over the plate.
## Limitations
* Trained on **smoke, steam and fire** only. Liquids such as water and ink may not work as well; guiding the model with a more detailed prompt helps.
* A control clip that leaves the 8-frame grid, or whose size is not a multiple of 64, degrades quickly.
* 121 frames at 24, 25 or 50 fps were tested. The trainer also saw 321-frame and 33-frame clips, so other 8k + 1 lengths should work; testing there was limited.
* The base model's own limits apply (text, faces, fine motion).
## Training
* **Trainer**: [musubi-tuner](https://github.com/kohya-ss/musubi-tuner) (kohya-ss), the LTX-2 fork by [AkaneTendo25, branch `ltx-2-dev`](https://github.com/AkaneTendo25/musubi-tuner/tree/ltx-2-dev). Base weights `ltx-2.5-22b-dev-transformer-bf16`, loaded in fp8, gradient checkpointing, 8-bit AdamW, batch 1. LoRA rank 32, alpha 32, `--lora_target_preset v2v` (attention and feed-forward of every block), `--reference_downscale 2` (the control is encoded at half resolution), `--ltx2_first_frame_conditioning_p 0.2`, the control always present.
* **Dataset**: 52 stock clips from Pexels (bonfires, wildfires, grass fires, smoke over forests, chimney steam), 44 landscape and 8 portrait, at 24, 25, 30 and 60 fps (30 was resampled to 25 and 60 to 50, by timestamp, so the motion speed is unchanged). Captions by Qwen3-VL-8B, trigger word first. The control videos were generated from the clips themselves: each clip painted over in **6 flat colours** (a palette chosen among the colours present in the frame, zones smoothed), **2 to 5 keyframes** per clip on the 8-frame grid (first and last frame always), each keyframe held for 1 to 8 frames, black frames elsewhere. This is what we would expect an artist to paint by hand, produced automatically for training.
* **Three-stage resolution chain** (the LTX LoRA guide's recipe), each stage warm-started from the previous one, one dataset block per frame rate (24, 25, 50 fps):
| Stage | Pairs | Geometry | Steps | Learning rate | Time |
|---|---|---|---|---|---|
| 1 ยท motion | 40 | 576 x 320 x 321 frames | 2000 | 1e-4 | 3 h 48 |
| 2 ยท shape and material | 94 (+ 3 held out) | 1024 x 576 x 121 | 1000 | 5e-5 | 2 h 26 |
| 3 ยท fine detail | 206 | 1920 x 1088 x 33 | 500 | 2e-5 | 1 h 32 |
* **Compute**: one NVIDIA RTX PRO 6000 (96 GB) on Runpod, **7 h 47 min** wall-clock for the whole chain, caching and previews included (5.8, 8.1 and 8.9 s per step; peak 24 GB of VRAM). At the card's 600 W maximum that is at most about 4.7 kWh; we did not meter it.
* **Loss**: about 0.26 at the end, noisy; the previews on held-out controls were the signal, not the curve.
## Transparency, data and ethics
This model follows the [AInVFX statement of AI ethics](https://www.ainvfx.com/ai-ethics/): open weights first, documented training data, creator consent, labelled generated content, frugal compute, a human who stays in control of the shot.
* **Data provenance.** All training clips come from [Pexels](https://www.pexels.com) under the [Pexels License](https://www.pexels.com/license/): free for personal and commercial use, modification allowed, attribution not required. No clip is redistributed here, only the weights and the six sample controls (painted paint-overs of four unseen Pexels clips, one photo, one blank canvas). Attribution is appreciated by Pexels contributors, so here are the clips, by Pexels video id:
52 training clips
[854521](https://www.pexels.com/video/854521/) ยท [856227](https://www.pexels.com/video/856227/) ยท [856295](https://www.pexels.com/video/856295/) ยท [1943483](https://www.pexels.com/video/1943483/) ยท [2908584](https://www.pexels.com/video/2908584/) ยท [6176867](https://www.pexels.com/video/6176867/) ยท [6179509](https://www.pexels.com/video/6179509/) ยท [6618025](https://www.pexels.com/video/6618025/) ยท [6618036](https://www.pexels.com/video/6618036/) ยท [7897557](https://www.pexels.com/video/7897557/) ยท [8201040](https://www.pexels.com/video/8201040/) ยท [8201049](https://www.pexels.com/video/8201049/) ยท [8365988](https://www.pexels.com/video/8365988/) ยท [9666929](https://www.pexels.com/video/9666929/) ยท [9667143](https://www.pexels.com/video/9667143/) ยท [9667144](https://www.pexels.com/video/9667144/) ยท [9808289](https://www.pexels.com/video/9808289/) ยท [9939406](https://www.pexels.com/video/9939406/) ยท [10157164](https://www.pexels.com/video/10157164/) ยท [10157172](https://www.pexels.com/video/10157172/) ยท [11210466](https://www.pexels.com/video/11210466/) ยท [11509050](https://www.pexels.com/video/11509050/) ยท [11574595](https://www.pexels.com/video/11574595/) ยท [11574636](https://www.pexels.com/video/11574636/) ยท [11584956](https://www.pexels.com/video/11584956/) ยท [11646227](https://www.pexels.com/video/11646227/) ยท [11925064](https://www.pexels.com/video/11925064/) ยท [12556476](https://www.pexels.com/video/12556476/) ยท [12773237](https://www.pexels.com/video/12773237/) ยท [12871894](https://www.pexels.com/video/12871894/) ยท [13228922](https://www.pexels.com/video/13228922/) ยท [13301380](https://www.pexels.com/video/13301380/) ยท [13301390](https://www.pexels.com/video/13301390/) ยท [14234580](https://www.pexels.com/video/14234580/) ยท [14296626](https://www.pexels.com/video/14296626/) ยท [14296662](https://www.pexels.com/video/14296662/) ยท [14296769](https://www.pexels.com/video/14296769/) ยท [14302096](https://www.pexels.com/video/14302096/) ยท [14435886](https://www.pexels.com/video/14435886/) ยท [14595146](https://www.pexels.com/video/14595146/) ยท [14886704](https://www.pexels.com/video/14886704/) ยท [15084556](https://www.pexels.com/video/15084556/) ยท [15084591](https://www.pexels.com/video/15084591/) ยท [15182505](https://www.pexels.com/video/15182505/) ยท [15240404](https://www.pexels.com/video/15240404/) ยท [15305558](https://www.pexels.com/video/15305558/) ยท [15305560](https://www.pexels.com/video/15305560/) ยท [17429991](https://www.pexels.com/video/17429991/) ยท [19681479](https://www.pexels.com/video/19681479/) ยท [19681480](https://www.pexels.com/video/19681480/) ยท [20706788](https://www.pexels.com/video/20706788/) ยท [20706803](https://www.pexels.com/video/20706803/)
4 clips used for the samples (never trained on)
[14294889](https://www.pexels.com/video/14294889/) ยท [15305551](https://www.pexels.com/video/15305551/) ยท [3942763](https://www.pexels.com/video/3942763/) ยท [4404141](https://www.pexels.com/video/4404141/)
* **Generated content.** The `_result` videos are AI-generated and this README is the written disclosure.
* **Compute.** Stated above, in GPU-hours and an energy upper bound, so you can judge the cost of reproducing it.
* **What it is for.** Adding a visual effect to a shot you own. Do not use it to depict a real place, event or person without appropriate consent.
## License
The LoRA is a derivative of LTX-2.5 and is released under the **LTX-2.x Community License**, the same license as the base model; a full copy is in [`LICENSE`](LICENSE). Notice required by that license: this derivative is subject to its Section 4 (use restrictions) and Attachment A (acceptable use policy) in their entirety. Worth knowing before you ship: a Commercial Entity (annual revenue of 10 M USD or more) needs a paid Commercial Use Agreement from Lightricks (ltxv-licensing@lightricks.com) for any use of LTX-2.x or its derivatives beyond testing and evaluation. This paragraph is a summary, not legal advice: read the file.
## Who made it, and come build with us
Trained by **Adrien Toupet** as the instructor's demo during cohort 1 of the **AInVFX Generative AI Bootcamp for Film and TV**.
Cohort 2 starts **2 October 2026**, cohort 3 on **6 January 2027**: 60 hours of live training online, in English, project based with cloud GPU included. **Come learn and build with us! [ainvfx.com/bootcamp](https://www.ainvfx.com/bootcamp/)**.
Questions, results, bugs: [contact AInVFX](https://www.ainvfx.com/contact-us/) or open a discussion on this repo.
## Credits
[Lightricks](https://www.lightricks.com) for LTX-2.5 and the IC-LoRA design ยท [kohya-ss](https://github.com/kohya-ss/musubi-tuner) and [AkaneTendo25](https://github.com/AkaneTendo25/musubi-tuner/tree/ltx-2-dev) for the trainer ยท [ComfyUI](https://github.com/Comfy-Org/ComfyUI) ยท the Pexels contributors listed above ยท [Runpod](https://www.runpod.io) for the GPU.