---
license: other
base_model: 0xSero/INTELLECT-3-REAP-50
library_name: transformers
tags:
- mixture-of-experts
- moe
- llmcompressor
- fp8
- quantization
- glm4_moe
- text-generation-inference
- REAP
model_creator: Akicou
model_type: glm4_moe
pipeline_tag: text-generation
---
# INTELLECT-3-REAP-50-FP8-Dynamic
## Model Overview
This is a quantized version of **INTELLECT-3-REAP-50**, a Router Expert Activation Pruned (REAP) Mixture of Experts (MoE) model. This version has been compressed to **FP8-Dynamic** precision using the `llmcompressor` library to optimize it for high-performance inference with a reduced memory footprint.
## Key Features
* **Quantization:** FP8-Dynamic (activations and weights).
* **Architecture:** REAP-optimized MoE based on GLM-4.
* **Efficiency:** Designed to run on modern GPUs (NVIDIA Ada Lovelace and Hopper architectures) with significant VRAM savings.
* **Algorithm:** One-Shot Post-Training Quantization (PTQ).
## REAP Optimization
**REAP (Router Expert Activation Pruning)** enhances MoE efficiency by pruning the activation of experts through a specialized routing mechanism. By combining this architecture with **FP8-Dynamic** quantization, the model achieves a balance between the high parameter count of MoE and the low latency required for production environments.
## Installation
To run this model, ensure you have the latest `transformers` and `torch` versions installed:
```bash
pip install torch torchvision transformers typing_extensions llmcompressor
```
## Usage Example
```python
from transformers import AutoTokenizer, AutoModelForCausalLM
MODEL_ID = "Akicou/INTELLECT-3-REAP-50-FP8-Dynamic"
model = AutoModelForCausalLM.from_pretrained(
MODEL_ID,
device_map="auto",
torch_dtype="auto",
)
tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
prompt = "Write a technical summary of how FP8 quantization improves LLM inference."
inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
output = model.generate(**inputs, max_new_tokens=150)
print(tokenizer.decode(output[0], skip_special_tokens=True))
```
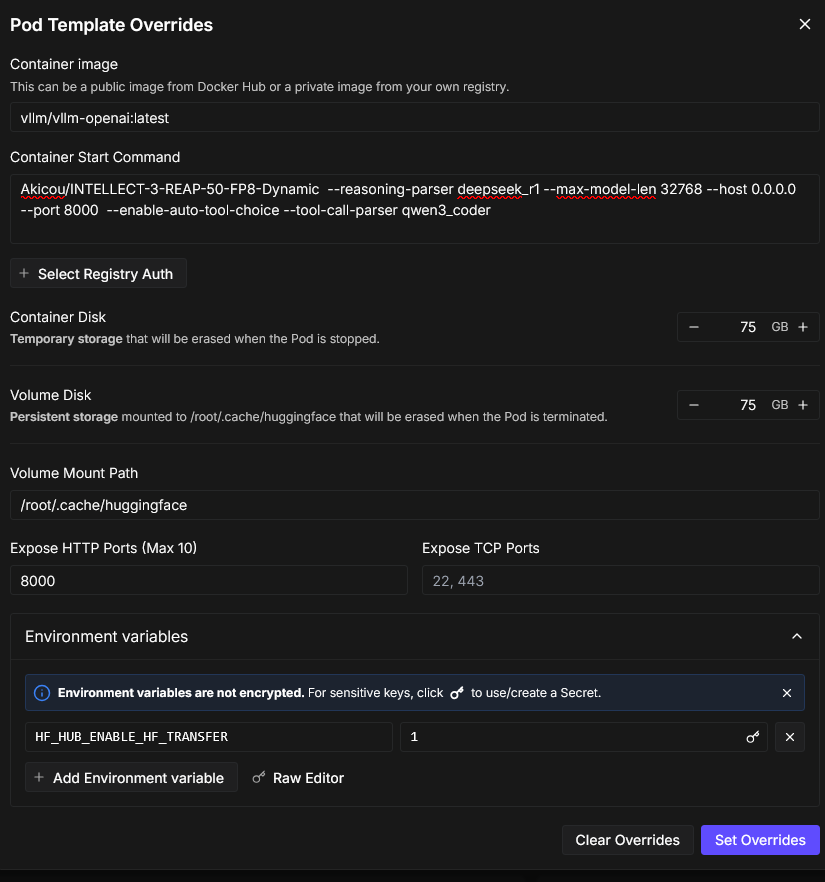
## Usage on Runpod
## Quantization Details
The model was quantized using the following `llmcompressor` configuration:
* **Targets:** Linear layers.
* **Scheme:** FP8_DYNAMIC.
* **Ignored Layers:** `lm_head`.
* **Calibration:** Performed with `oneshot` algorithm.
## Limitations
* **Hardware:** Native FP8 support requires NVIDIA Blackwell, Hopper, or Ada Lovelace GPUs.
* **Precision:** While dynamic scaling minimizes loss, slight accuracy deviations may occur compared to the original BF16 weights in highly niche benchmarks.
## Licensing
This model inherits the license from the base model [0xSero/INTELLECT-3-REAP-50](https://huggingface.co/0xSero/INTELLECT-3-REAP-50). Please refer to the original repository for specific usage rights.