---
license: apache-2.0
pipeline_tag: image-to-video
tags:
- video-generation
- human-animation
- one-shot
---
# ONE-SHOT: Compositional Human-Environment Video Synthesis via Spatial-Decoupled Motion Injection and Hybrid Context Integration
Fengyuan Yang1,2
Luying Huang2,†
Jiazhi Guan2,✉
Quanwei Yang2
Dongwei Pan2
Jianglin Fu2
Haocheng Feng2
Wei He2
Kaisiyuan Wang2
Hang Zhou2,✉
Angela Yao1
1 National University of Singapore
2 Baidu, AMU
† Project leader ✉ Corresponding authors
Work done during Fengyuan's internship at Baidu
Official inference code for **ONE-SHOT: Compositional Human-Environment Video Synthesis via Spatial-Decoupled Motion Injection and Hybrid Context Integration**.
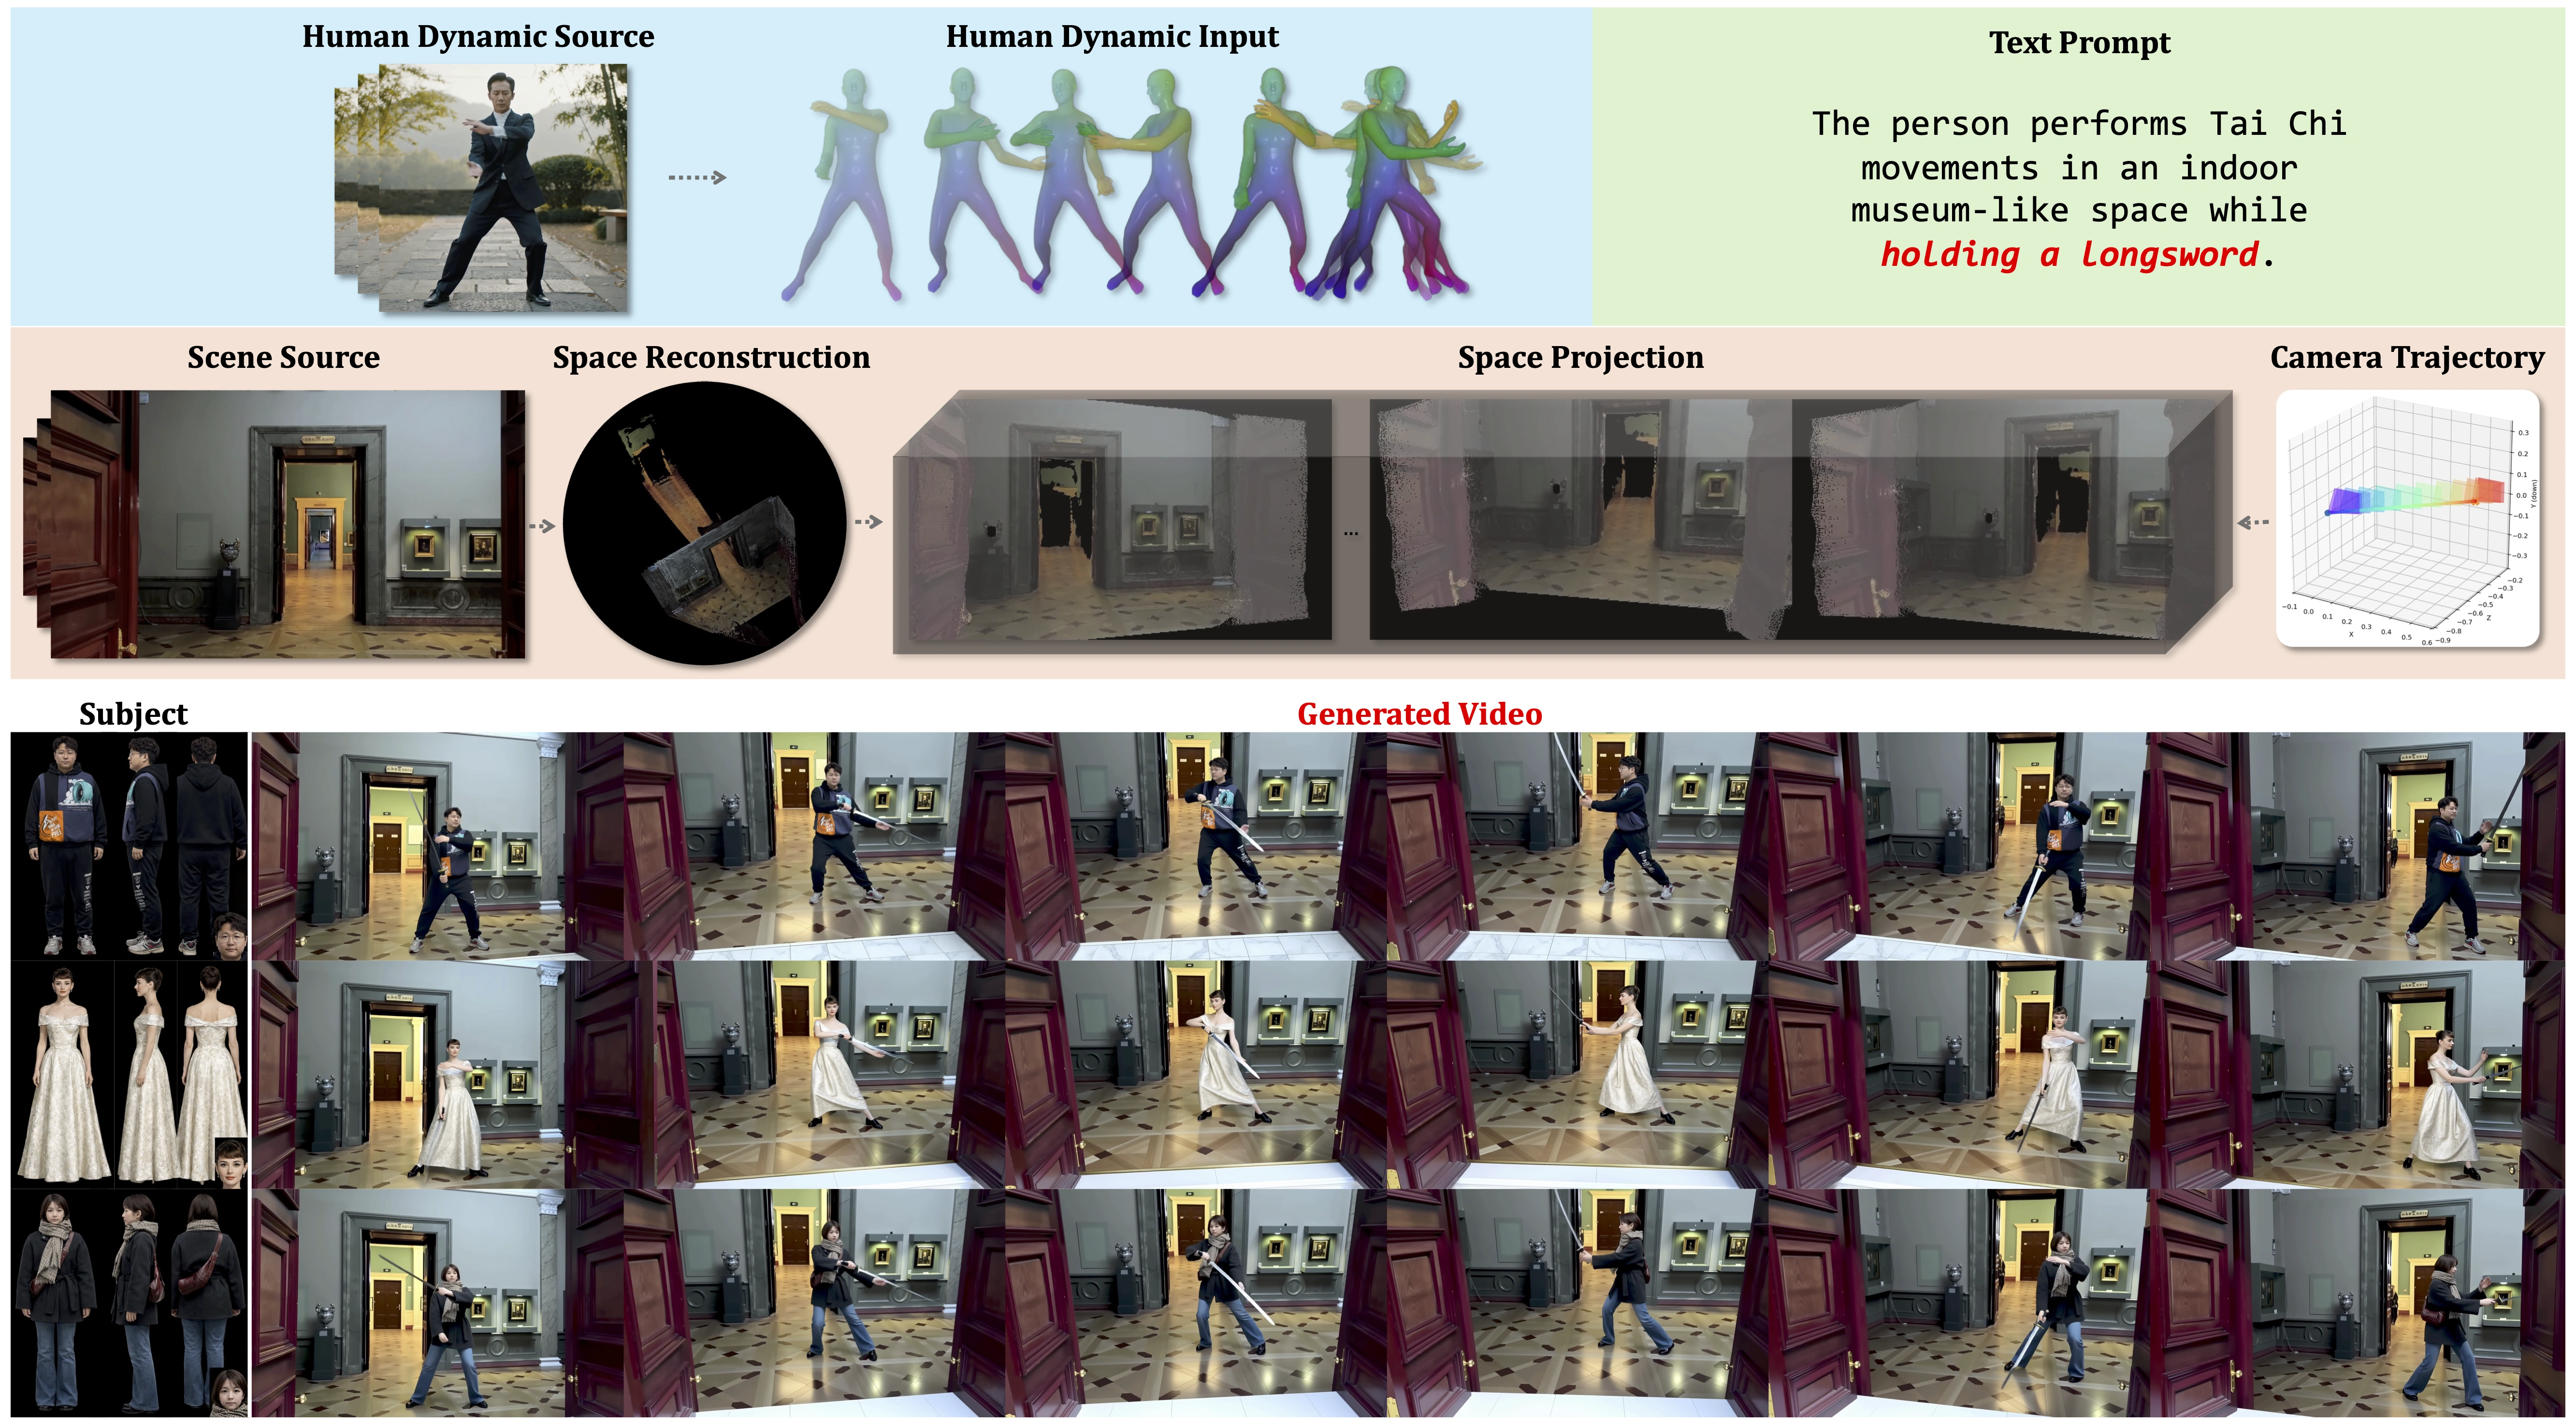
ONE-SHOT is a parameter-efficient framework for controllable human-environment video synthesis. It supports independent control over subject identity, human motion, scene context, and camera trajectory while preserving persistent identity and stable interactions in long generations.
## 🧾 Abstract
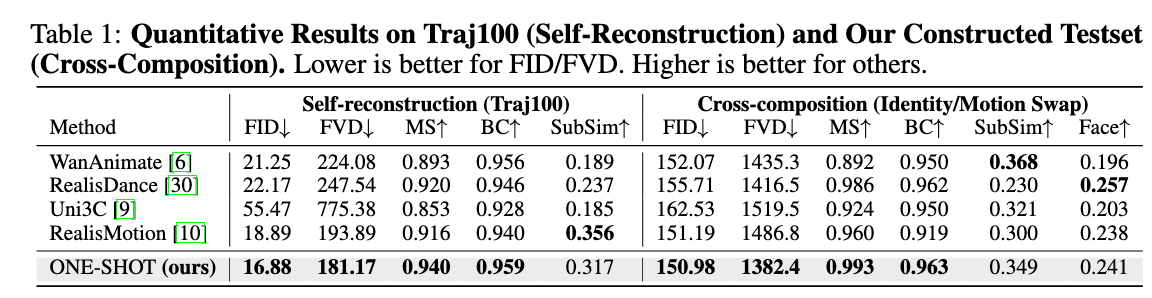
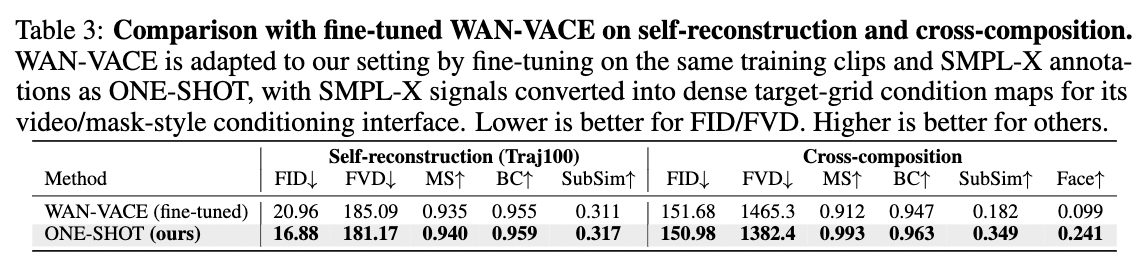
Recent advances in Video Foundation Models (VFMs) have revolutionized human-centric video synthesis, yet fine-grained and independent editing of subjects and scenes remains a critical challenge. We introduce **ONE-SHOT**, a parameter-efficient framework built upon pre-trained VFMs that achieves high-fidelity synthesis of human-environment videos with independent control over subject appearance, human dynamics, spatial environments, and camera trajectories. By optimizing only a sparse set of parameters, it achieves precise control while preserving responsiveness to textual instructions. A canonical-space motion injection mechanism mitigates conditioning competition between rigid human priors and text prompts. By anchoring static and dynamic context, ONE-SHOT ensures persistent subject identity and stable human-environment interactions across minute-scale generations. Extensive experiments demonstrate that ONE-SHOT significantly outperforms existing methods in structural control and creative diversity.
## 🖼️ Overview
## 📰 News
- 🔥 **`2026/05/31`**: The `ONE-SHOT-14B` diffusers checkpoint can be downloaded from [Hugging Face](https://huggingface.co/MartaYang007/ONE-SHOT-14B).
- 🔥 **`2026/04/01`**: The ONE-SHOT paper is available on [arXiv](https://arxiv.org/abs/2604.01043).
- 🔥 **`2026/04/01`**: ONE-SHOT project materials are available on the [project page](https://martayang.github.io/ONE-SHOT/).
## 📊 Metrics
## 🚀 Quick Start
### 🛠️ Installation
Recommended environment:
- Linux
- NVIDIA GPU
- CUDA 12.1 compatible driver
- Python 3.12
- `ffmpeg` with `libx264` support
```bash
git clone https://github.com/MartaYang/ONE-SHOT-code.git
cd ONE-SHOT-code
bash install.sh
conda activate oneshot
```
The installer creates the `oneshot` conda environment, installs a GPL-enabled `ffmpeg`, installs PyTorch `2.5.1+cu121`, installs the vendored PyTorch3D wheel, and then installs `requirements.txt`.
Manual installation commands
```bash
conda create -n oneshot python=3.12 -y
conda activate oneshot
conda install 'ffmpeg=*=*gpl*' -y
pip install --index-url https://download.pytorch.org/whl/cu121 \
torch==2.5.1+cu121 torchvision==0.20.1+cu121 torchaudio==2.5.1+cu121
pip install Preprocessing/third_party/wheels/pytorch3d-0.7.9-cp312-cp312-manylinux_2_31_x86_64.whl
pip install -r requirements.txt
```
### 📦 Checkpoints
Download the released checkpoint and set `ONESHOT_MODEL_DIR`:
```bash
hf download MartaYang007/ONE-SHOT-14B \
--local-dir pretrained_models/ONESHOT-14B-diffusers
export ONESHOT_MODEL_DIR=pretrained_models/ONESHOT-14B-diffusers
```
A recommended local checkpoint layout is:
```text
pretrained_models/
└── ONESHOT-14B-diffusers/
├── transformer/
├── vae/
├── text_encoder/
├── tokenizer/
├── scheduler/
├── model_index.json
├── preprocess/
│ ├── human3r.pth
│ ├── DA3NESTED-GIANT-LARGE-1.1/
│ ├── smpl_models/
│ │ └── smplx/
│ │ └── SMPLX_NEUTRAL.npz # YOU MUST DOWNLOAD THIS — see below
│ └── torch_hub/
└── demo/
```
#### SMPL-X body model (manual download)
The SMPL-X license prohibits third-party redistribution, so `SMPLX_NEUTRAL.npz`
is not included in the Hugging Face checkpoint.
1. Register at and accept the model license.
2. From the **Downloads** page, fetch the latest `SMPL-X (NPZ format)` release.
3. Place the file at:
```text
$ONESHOT_MODEL_DIR/preprocess/smpl_models/smplx/SMPLX_NEUTRAL.npz
```
If the file is missing at runtime, the pipeline fails fast with an error
pointing back to this section.
### ▶️ Inference
The end-to-end entrypoint is:
```bash
bash scripts/run_pipeline.sh [task arguments]
```
Supported tasks:
| Task | Required inputs | Description |
| --- | --- | --- |
| `id_swap` | source video, identity profile video or identity profile images, prompt | Replace the actor identity while preserving the source motion and scene. |
| `motion_swap` | source video, motion video, prompt | Apply a new motion to the original subject and scene. |
| `scene_swap` | source video, scene video, prompt | Place the person into a different environment. |
Example commands:
ID swap
```bash
bash scripts/run_pipeline.sh id_swap \
--video_path "$ONESHOT_MODEL_DIR/demo/walkinforest.mp4" \
--id_profile_video "$ONESHOT_MODEL_DIR/demo/WillSmith.mp4" \
--prompt "A sunlit forest trail with dense green trees and soft natural light filtering through the leaves. Will Smith, wearing a black suit, walks steadily along the forest path while holding a wooden walking stick, looking slightly upward as he moves forward."
# --id_profile_video: recommended — video with multi-angle coverage of the target person
# (front + side + other angles) for best identity fidelity.
# Alternative: --id_profile_dir with 4 images named exactly:
# ref1.png (front view) ref2.png (back / 3/4 view) ref3.png (side view) face.png (face crop)
```
`--id_profile_video` is recommended when the identity reference contains multi-angle coverage. Alternatively, provide `--id_profile_dir ` with `ref1.png`, `ref2.png`, `ref3.png`, and `face.png`.
Motion swap
```bash
bash scripts/run_pipeline.sh motion_swap \
--video_path "$ONESHOT_MODEL_DIR/demo/museum4_human.mp4" \
--motion_video_path "$ONESHOT_MODEL_DIR/demo/taiji.mp4" \
--prompt "An indoor space resembling the interior of a museum. A man in a suit is performing tai chi movements."
# to also swap identity: add --id_profile_video $ONESHOT_MODEL_DIR/demo/WillSmith.mp4
# Note: update the prompt accordingly (e.g., gender, name) to match the new identity and avoid conflicts with the video content.
```
To also swap identity, add `--id_profile_video "$ONESHOT_MODEL_DIR/demo/WillSmith.mp4"` and update the prompt so the identity description does not conflict with the video content.
Scene swap
```bash
bash scripts/run_pipeline.sh scene_swap \
--video_path "$ONESHOT_MODEL_DIR/demo/palace_human.mp4" \
--scene_video_path "$ONESHOT_MODEL_DIR/demo/museum4_scene.mp4" \
--id_profile_video "$ONESHOT_MODEL_DIR/demo/WillSmith.mp4" \
--prompt "An indoor space resembling the interior of a museum. Will Smith is walking, wearing a black suit."
# --scene_video_path: must be a pure background video (no human subjects).
# Strongly recommended to choose a background video whose depth-of-field
# matches the person in --video_path for best generation quality.
# to also swap identity: add --id_profile_video $ONESHOT_MODEL_DIR/demo/WillSmith.mp4
# Note: update the prompt accordingly (e.g., gender, name) to match the new identity and avoid conflicts with the video content.
```
To preserve the original identity, omit `--id_profile_video` and update the prompt accordingly.
Generated videos are saved to:
```text
exp/__/.mp4
```
For example:
```text
exp/lcm_id_swap_20260527_221947/ID_WillSmith-SMPLX_clip_000-006-Scene_C01_gen_xxx_ourGen81.mp4
```
## 🤗 Available Models
| Model | Status | Link |
| --- | --- | --- |
| ONE-SHOT-14B | Available | [MartaYang007/ONE-SHOT-14B](https://huggingface.co/MartaYang007/ONE-SHOT-14B) |
## 📝 Notes
- `scripts/run_pipeline.sh` builds a task CSV, selects available GPUs with the most free memory, and launches `scripts/inference_short.sh`.
- Set `ONESHOT_ENV` if your conda environment name is not `oneshot`.
- The demo videos are included in the checkpoint download, but using your own videos is recommended for real experiments.
- The prompt should match any swapped identity, motion, or scene to avoid conflicts between text and visual conditions.
## 🗺️ TODO
- [ ] Multi-GPU inference with FSDP-based model sharding and sequence parallelism.
- [ ] ComfyUI support for node-based experimentation and demos.
- [ ] Fully compositional generation with explicit identity, motion, scene, and position controls.
## 📁 Repository Layout
```text
ONE-SHOT-code/
├── install.sh # one-shot conda environment installer
├── requirements.txt
├── tools/
│ ├── inference_short.py # short-video inference entrypoint
│ └── inference_long.py # long-video inference with scene memory
├── scripts/
│ ├── run_pipeline.sh # preprocessing + inference pipeline
│ ├── inference_short.sh
│ └── inference_long.sh
├── Preprocessing/
│ ├── preprocess_video.py # per-video preprocessing
│ ├── build_csv.py # task CSV builder
│ ├── make_scene_masked_dilate.py
│ └── third_party/ # vendored DUSt3R, Human3R, CroCo, and utilities
├── oneshot_diffusers/ # ONE-SHOT diffusers overrides
│ ├── transformer_wan_oneshot.py
│ ├── pipeline_wan_oneshot.py
│ └── oneshot_util.py
├── utils/ # ODE solvers and video I/O helpers
└── datasets/ # DWPose drawing and data utilities
```
## 🙏 Acknowledgement
This project builds on:
- [Wan2.1](https://github.com/Wan-Video/Wan2.1)
- [Human3R](https://github.com/fanegg/Human3R)
- [DUSt3R](https://github.com/naver/dust3r)
- [Depth-Anything-3](https://github.com/DepthAnything/Depth-Anything-V2)
- [SMPL-X](https://smpl-x.is.tue.mpg.de/)
- [PyTorch3D](https://github.com/facebookresearch/pytorch3d)
- [Diffusers](https://github.com/huggingface/diffusers)
## 📚 Citation
```bibtex
@misc{yang2026oneshot,
title={ONE-SHOT: Compositional Human-Environment Video Synthesis via Spatial-Decoupled Motion Injection and Hybrid Context Integration},
author={Fengyuan Yang and Luying Huang and Jiazhi Guan and Quanwei Yang and Dongwei Pan and Jianglin Fu and Haocheng Feng and Wei He and Kaisiyuan Wang and Hang Zhou and Angela Yao},
year={2026},
eprint={2604.01043},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2604.01043}
}
```


