

RX5950XT commited on
Upload folder using huggingface_hub
Browse files- .gitattributes +2 -0
- README.md +140 -0
- adapter/adapter_config.json +51 -0
- adapter/adapter_model.safetensors +3 -0
- adapter/chat_template.jinja +154 -0
- adapter/tokenizer.json +3 -0
- adapter/tokenizer_config.json +33 -0
- export_config_v2.yaml +12 -0
- gguf/rx5950xt-digital-twin-v2-q8_0.gguf +3 -0
- train_config.yaml +50 -0
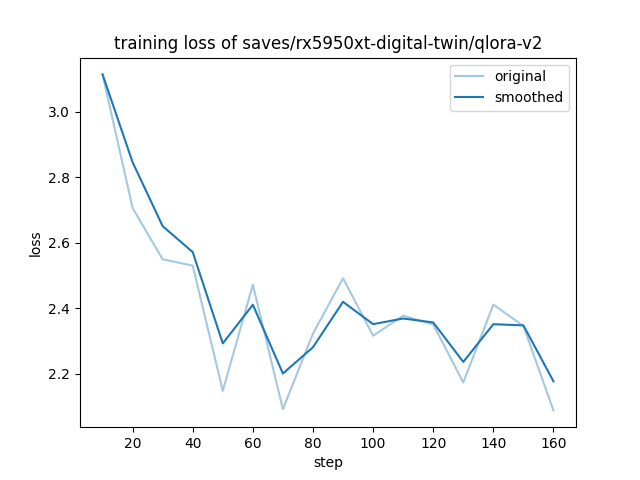
- training_loss.png +0 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,5 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
adapter/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
gguf/rx5950xt-digital-twin-v2-q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,140 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- zh
|
| 5 |
+
base_model: Qwen/Qwen3.5-4B
|
| 6 |
+
tags:
|
| 7 |
+
- digital-twin
|
| 8 |
+
- lora
|
| 9 |
+
- qlora
|
| 10 |
+
- conversational
|
| 11 |
+
- chinese
|
| 12 |
+
- traditional-chinese
|
| 13 |
+
library_name: transformers
|
| 14 |
+
pipeline_tag: text-generation
|
| 15 |
+
---
|
| 16 |
+
|
| 17 |
+
# rx5950xt Digital Twin v2 — Qwen3.5-4B QLoRA
|
| 18 |
+
|
| 19 |
+
基於 [Qwen/Qwen3.5-4B](https://huggingface.co/Qwen/Qwen3.5-4B) 微調的數位分身模型。
|
| 20 |
+
透過 Discord 對話記錄微調,模仿特定使用者的語氣、用詞習慣與對話風格。
|
| 21 |
+
|
| 22 |
+
## 模型描述
|
| 23 |
+
|
| 24 |
+
| 項目 | 內容 |
|
| 25 |
+
|------|------|
|
| 26 |
+
| 基底模型 | Qwen/Qwen3.5-4B |
|
| 27 |
+
| 微調方法 | QLoRA (4-bit NF4 + LoRA rank 8) |
|
| 28 |
+
| 訓練框架 | [LLaMA Factory](https://github.com/hiyouga/LLaMA-Factory) |
|
| 29 |
+
| 訓練資料 | ~1067 筆 Discord 對話 + [alpaca_gpt4_zh](https://huggingface.co/datasets/llamafactory/alpaca_gpt4_zh) 通用中文指令資料 |
|
| 30 |
+
| 語言 | 繁體中文(臺灣) |
|
| 31 |
+
| 授權 | Apache 2.0 |
|
| 32 |
+
|
| 33 |
+
## 訓練細節
|
| 34 |
+
|
| 35 |
+
### 防過擬合策略
|
| 36 |
+
|
| 37 |
+
由於訓練資料量有限(~1067 筆),採用以下策略防止過擬合:
|
| 38 |
+
|
| 39 |
+
- **資料混合**: 將個人對話資料與通用中文指令資料(alpaca_gpt4_zh)以約 1:2 比例混合
|
| 40 |
+
- **低學習率**: 5e-5(相比一般 LoRA 的 2e-4)
|
| 41 |
+
- **單輪訓練**: 僅 1 epoch,避免反覆記憶訓練資料
|
| 42 |
+
- **較小 LoRA rank**: r=8(相比常見的 16-64)
|
| 43 |
+
- **NEFTune 噪聲**: alpha=5.0,增加訓練穩定性
|
| 44 |
+
- **LoRA Dropout**: 0.1
|
| 45 |
+
|
| 46 |
+
### 訓練參數
|
| 47 |
+
|
| 48 |
+
```yaml
|
| 49 |
+
model: Qwen/Qwen3.5-4B (4-bit BNB quantized)
|
| 50 |
+
lora_rank: 8
|
| 51 |
+
lora_alpha: 16
|
| 52 |
+
lora_dropout: 0.1
|
| 53 |
+
learning_rate: 5e-5
|
| 54 |
+
num_train_epochs: 1
|
| 55 |
+
lr_scheduler: cosine
|
| 56 |
+
warmup_steps: 20
|
| 57 |
+
batch_size: 16 (effective, via gradient accumulation)
|
| 58 |
+
optimizer: paged_adamw_8bit
|
| 59 |
+
neftune_noise_alpha: 5.0
|
| 60 |
+
cutoff_len: 512
|
| 61 |
+
bf16: true
|
| 62 |
+
```
|
| 63 |
+
|
| 64 |
+
### 訓練結果
|
| 65 |
+
|
| 66 |
+
| 指標 | 數值 |
|
| 67 |
+
|------|------|
|
| 68 |
+
| Train Loss | 2.397 |
|
| 69 |
+
| Eval Loss | 2.349 |
|
| 70 |
+
| 訓練時間 | ~2 小時 10 分鐘 |
|
| 71 |
+
| 總步數 | 164 steps |
|
| 72 |
+
| GPU | NVIDIA RTX 3070 Ti |
|
| 73 |
+
|
| 74 |
+
> eval_loss < train_loss,表示模型未過擬合。
|
| 75 |
+
|
| 76 |
+

|
| 77 |
+
|
| 78 |
+
## 檔案結構
|
| 79 |
+
|
| 80 |
+
```
|
| 81 |
+
.
|
| 82 |
+
├── README.md # 本檔案
|
| 83 |
+
├── train_config.yaml # LLaMA Factory 訓練配置
|
| 84 |
+
├── export_config_v2.yaml # 模型匯出配置
|
| 85 |
+
├── training_loss.png # 訓練損失曲線
|
| 86 |
+
├── adapter/ # LoRA adapter 權重
|
| 87 |
+
│ ├── adapter_model.safetensors
|
| 88 |
+
│ ├── adapter_config.json
|
| 89 |
+
│ ├── tokenizer.json
|
| 90 |
+
│ ├── tokenizer_config.json
|
| 91 |
+
│ └── chat_template.jinja
|
| 92 |
+
└── gguf/ # 量化版本
|
| 93 |
+
└── rx5950xt-digital-twin-v2-q8_0.gguf (Q8_0, 4.2 GB)
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
## 使用方式
|
| 97 |
+
|
| 98 |
+
### 方式一:LM Studio / Ollama(推薦)
|
| 99 |
+
|
| 100 |
+
直接下載 `gguf/rx5950xt-digital-twin-v2-q8_0.gguf`,在 LM Studio 或 Ollama 中載入即可。
|
| 101 |
+
|
| 102 |
+
> 注意:聊天模板已修改為 nothink 模式(停用 Qwen3.5 的思考功能),回覆會直接輸出。
|
| 103 |
+
|
| 104 |
+
### 方式二:Transformers + PEFT(載入 LoRA adapter)
|
| 105 |
+
|
| 106 |
+
```python
|
| 107 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 108 |
+
from peft import PeftModel
|
| 109 |
+
|
| 110 |
+
base_model = AutoModelForCausalLM.from_pretrained(
|
| 111 |
+
"Qwen/Qwen3.5-4B",
|
| 112 |
+
torch_dtype="auto",
|
| 113 |
+
device_map="auto",
|
| 114 |
+
trust_remote_code=True,
|
| 115 |
+
)
|
| 116 |
+
model = PeftModel.from_pretrained(base_model, "RX5950XTP/rx5950xt-digital-twin-Qwen3.5-4B/adapter")
|
| 117 |
+
tokenizer = AutoTokenizer.from_pretrained("RX5950XTP/rx5950xt-digital-twin-Qwen3.5-4B/adapter")
|
| 118 |
+
|
| 119 |
+
messages = [
|
| 120 |
+
{"role": "system", "content": "你是 rx5950xt 的數位分身。"},
|
| 121 |
+
{"role": "user", "content": "你好!"},
|
| 122 |
+
]
|
| 123 |
+
text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
|
| 124 |
+
inputs = tokenizer(text, return_tensors="pt").to(model.device)
|
| 125 |
+
outputs = model.generate(**inputs, max_new_tokens=256)
|
| 126 |
+
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
## 限制與注意事項
|
| 130 |
+
|
| 131 |
+
- 訓練資料僅約 1067 筆 Discord 對話,覆蓋的話題和情境有限
|
| 132 |
+
- 混合了通用中文指令資料以保留泛用能力,但可能稍微稀釋個人風格
|
| 133 |
+
- 不適用於需要專業知識、事實查證或安全敏感的場景
|
| 134 |
+
- 本模型僅供研究與娛樂用途
|
| 135 |
+
|
| 136 |
+
## 致謝
|
| 137 |
+
|
| 138 |
+
- [Qwen Team](https://huggingface.co/Qwen/Qwen3.5-4B) — 基底模型
|
| 139 |
+
- [LLaMA Factory](https://github.com/hiyouga/LLaMA-Factory) — 訓練框架
|
| 140 |
+
- [llama.cpp](https://github.com/ggml-org/llama.cpp) — GGUF 轉換
|
adapter/adapter_config.json
ADDED
|
@@ -0,0 +1,51 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"alora_invocation_tokens": null,
|
| 3 |
+
"alpha_pattern": {},
|
| 4 |
+
"arrow_config": null,
|
| 5 |
+
"auto_mapping": null,
|
| 6 |
+
"base_model_name_or_path": "Qwen/Qwen3.5-4B",
|
| 7 |
+
"bias": "none",
|
| 8 |
+
"corda_config": null,
|
| 9 |
+
"ensure_weight_tying": false,
|
| 10 |
+
"eva_config": null,
|
| 11 |
+
"exclude_modules": null,
|
| 12 |
+
"fan_in_fan_out": false,
|
| 13 |
+
"inference_mode": true,
|
| 14 |
+
"init_lora_weights": true,
|
| 15 |
+
"layer_replication": null,
|
| 16 |
+
"layers_pattern": null,
|
| 17 |
+
"layers_to_transform": null,
|
| 18 |
+
"loftq_config": {},
|
| 19 |
+
"lora_alpha": 16,
|
| 20 |
+
"lora_bias": false,
|
| 21 |
+
"lora_dropout": 0.1,
|
| 22 |
+
"megatron_config": null,
|
| 23 |
+
"megatron_core": "megatron.core",
|
| 24 |
+
"modules_to_save": null,
|
| 25 |
+
"peft_type": "LORA",
|
| 26 |
+
"peft_version": "0.18.1",
|
| 27 |
+
"qalora_group_size": 16,
|
| 28 |
+
"r": 8,
|
| 29 |
+
"rank_pattern": {},
|
| 30 |
+
"revision": null,
|
| 31 |
+
"target_modules": [
|
| 32 |
+
"down_proj",
|
| 33 |
+
"in_proj_b",
|
| 34 |
+
"k_proj",
|
| 35 |
+
"in_proj_a",
|
| 36 |
+
"in_proj_z",
|
| 37 |
+
"up_proj",
|
| 38 |
+
"out_proj",
|
| 39 |
+
"in_proj_qkv",
|
| 40 |
+
"q_proj",
|
| 41 |
+
"v_proj",
|
| 42 |
+
"gate_proj",
|
| 43 |
+
"o_proj"
|
| 44 |
+
],
|
| 45 |
+
"target_parameters": null,
|
| 46 |
+
"task_type": "CAUSAL_LM",
|
| 47 |
+
"trainable_token_indices": null,
|
| 48 |
+
"use_dora": false,
|
| 49 |
+
"use_qalora": false,
|
| 50 |
+
"use_rslora": false
|
| 51 |
+
}
|
adapter/adapter_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f3a87334af894a7a8780bce99c29a6175cb99bf232640b0af6e37167083b6d2a
|
| 3 |
+
size 65003848
|
adapter/chat_template.jinja
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set image_count = namespace(value=0) %}
|
| 2 |
+
{%- set video_count = namespace(value=0) %}
|
| 3 |
+
{%- macro render_content(content, do_vision_count, is_system_content=false) %}
|
| 4 |
+
{%- if content is string %}
|
| 5 |
+
{{- content }}
|
| 6 |
+
{%- elif content is iterable and content is not mapping %}
|
| 7 |
+
{%- for item in content %}
|
| 8 |
+
{%- if 'image' in item or 'image_url' in item or item.type == 'image' %}
|
| 9 |
+
{%- if is_system_content %}
|
| 10 |
+
{{- raise_exception('System message cannot contain images.') }}
|
| 11 |
+
{%- endif %}
|
| 12 |
+
{%- if do_vision_count %}
|
| 13 |
+
{%- set image_count.value = image_count.value + 1 %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- if add_vision_id %}
|
| 16 |
+
{{- 'Picture ' ~ image_count.value ~ ': ' }}
|
| 17 |
+
{%- endif %}
|
| 18 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' }}
|
| 19 |
+
{%- elif 'video' in item or item.type == 'video' %}
|
| 20 |
+
{%- if is_system_content %}
|
| 21 |
+
{{- raise_exception('System message cannot contain videos.') }}
|
| 22 |
+
{%- endif %}
|
| 23 |
+
{%- if do_vision_count %}
|
| 24 |
+
{%- set video_count.value = video_count.value + 1 %}
|
| 25 |
+
{%- endif %}
|
| 26 |
+
{%- if add_vision_id %}
|
| 27 |
+
{{- 'Video ' ~ video_count.value ~ ': ' }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' }}
|
| 30 |
+
{%- elif 'text' in item %}
|
| 31 |
+
{{- item.text }}
|
| 32 |
+
{%- else %}
|
| 33 |
+
{{- raise_exception('Unexpected item type in content.') }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- elif content is none or content is undefined %}
|
| 37 |
+
{{- '' }}
|
| 38 |
+
{%- else %}
|
| 39 |
+
{{- raise_exception('Unexpected content type.') }}
|
| 40 |
+
{%- endif %}
|
| 41 |
+
{%- endmacro %}
|
| 42 |
+
{%- if not messages %}
|
| 43 |
+
{{- raise_exception('No messages provided.') }}
|
| 44 |
+
{%- endif %}
|
| 45 |
+
{%- if tools and tools is iterable and tools is not mapping %}
|
| 46 |
+
{{- '<|im_start|>system\n' }}
|
| 47 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n<tools>" }}
|
| 48 |
+
{%- for tool in tools %}
|
| 49 |
+
{{- "\n" }}
|
| 50 |
+
{{- tool | tojson }}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{{- "\n</tools>" }}
|
| 53 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 54 |
+
{%- if messages[0].role == 'system' %}
|
| 55 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 56 |
+
{%- if content %}
|
| 57 |
+
{{- '\n\n' + content }}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<|im_end|>\n' }}
|
| 61 |
+
{%- else %}
|
| 62 |
+
{%- if messages[0].role == 'system' %}
|
| 63 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 64 |
+
{{- '<|im_start|>system\n' + content + '<|im_end|>\n' }}
|
| 65 |
+
{%- endif %}
|
| 66 |
+
{%- endif %}
|
| 67 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 68 |
+
{%- for message in messages[::-1] %}
|
| 69 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 70 |
+
{%- if ns.multi_step_tool and message.role == "user" %}
|
| 71 |
+
{%- set content = render_content(message.content, false)|trim %}
|
| 72 |
+
{%- if not(content.startswith('<tool_response>') and content.endswith('</tool_response>')) %}
|
| 73 |
+
{%- set ns.multi_step_tool = false %}
|
| 74 |
+
{%- set ns.last_query_index = index %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- endif %}
|
| 77 |
+
{%- endfor %}
|
| 78 |
+
{%- if ns.multi_step_tool %}
|
| 79 |
+
{{- raise_exception('No user query found in messages.') }}
|
| 80 |
+
{%- endif %}
|
| 81 |
+
{%- for message in messages %}
|
| 82 |
+
{%- set content = render_content(message.content, true)|trim %}
|
| 83 |
+
{%- if message.role == "system" %}
|
| 84 |
+
{%- if not loop.first %}
|
| 85 |
+
{{- raise_exception('System message must be at the beginning.') }}
|
| 86 |
+
{%- endif %}
|
| 87 |
+
{%- elif message.role == "user" %}
|
| 88 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 89 |
+
{%- elif message.role == "assistant" %}
|
| 90 |
+
{%- set reasoning_content = '' %}
|
| 91 |
+
{%- if message.reasoning_content is string %}
|
| 92 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 93 |
+
{%- else %}
|
| 94 |
+
{%- if '</think>' in content %}
|
| 95 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 96 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 97 |
+
{%- endif %}
|
| 98 |
+
{%- endif %}
|
| 99 |
+
{%- set reasoning_content = reasoning_content|trim %}
|
| 100 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 101 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content + '\n</think>\n\n' + content }}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- if message.tool_calls and message.tool_calls is iterable and message.tool_calls is not mapping %}
|
| 106 |
+
{%- for tool_call in message.tool_calls %}
|
| 107 |
+
{%- if tool_call.function is defined %}
|
| 108 |
+
{%- set tool_call = tool_call.function %}
|
| 109 |
+
{%- endif %}
|
| 110 |
+
{%- if loop.first %}
|
| 111 |
+
{%- if content|trim %}
|
| 112 |
+
{{- '\n\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 113 |
+
{%- else %}
|
| 114 |
+
{{- '<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 115 |
+
{%- endif %}
|
| 116 |
+
{%- else %}
|
| 117 |
+
{{- '\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 118 |
+
{%- endif %}
|
| 119 |
+
{%- if tool_call.arguments is defined %}
|
| 120 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 121 |
+
{{- '<parameter=' + args_name + '>\n' }}
|
| 122 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 123 |
+
{{- args_value }}
|
| 124 |
+
{{- '\n</parameter>\n' }}
|
| 125 |
+
{%- endfor %}
|
| 126 |
+
{%- endif %}
|
| 127 |
+
{{- '</function>\n</tool_call>' }}
|
| 128 |
+
{%- endfor %}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '<|im_end|>\n' }}
|
| 131 |
+
{%- elif message.role == "tool" %}
|
| 132 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 133 |
+
{{- '<|im_start|>user' }}
|
| 134 |
+
{%- endif %}
|
| 135 |
+
{{- '\n<tool_response>\n' }}
|
| 136 |
+
{{- content }}
|
| 137 |
+
{{- '\n</tool_response>' }}
|
| 138 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- elif loop.last %}
|
| 141 |
+
{{- '<|im_end|>\n' }}
|
| 142 |
+
{%- endif %}
|
| 143 |
+
{%- else %}
|
| 144 |
+
{{- raise_exception('Unexpected message role.') }}
|
| 145 |
+
{%- endif %}
|
| 146 |
+
{%- endfor %}
|
| 147 |
+
{%- if add_generation_prompt %}
|
| 148 |
+
{{- '<|im_start|>assistant\n' }}
|
| 149 |
+
{%- if enable_thinking is defined and enable_thinking is false %}
|
| 150 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 151 |
+
{%- else %}
|
| 152 |
+
{{- '<think>\n' }}
|
| 153 |
+
{%- endif %}
|
| 154 |
+
{%- endif %}
|
adapter/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:87a7830d63fcf43bf241c3c5242e96e62dd3fdc29224ca26fed8ea333db72de4
|
| 3 |
+
size 19989343
|
adapter/tokenizer_config.json
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"audio_bos_token": "<|audio_start|>",
|
| 4 |
+
"audio_eos_token": "<|audio_end|>",
|
| 5 |
+
"audio_token": "<|audio_pad|>",
|
| 6 |
+
"backend": "tokenizers",
|
| 7 |
+
"bos_token": null,
|
| 8 |
+
"clean_up_tokenization_spaces": false,
|
| 9 |
+
"eos_token": "<|im_end|>",
|
| 10 |
+
"errors": "replace",
|
| 11 |
+
"image_token": "<|image_pad|>",
|
| 12 |
+
"is_local": false,
|
| 13 |
+
"model_max_length": 262144,
|
| 14 |
+
"model_specific_special_tokens": {
|
| 15 |
+
"audio_bos_token": "<|audio_start|>",
|
| 16 |
+
"audio_eos_token": "<|audio_end|>",
|
| 17 |
+
"audio_token": "<|audio_pad|>",
|
| 18 |
+
"image_token": "<|image_pad|>",
|
| 19 |
+
"video_token": "<|video_pad|>",
|
| 20 |
+
"vision_bos_token": "<|vision_start|>",
|
| 21 |
+
"vision_eos_token": "<|vision_end|>"
|
| 22 |
+
},
|
| 23 |
+
"pad_token": "<|endoftext|>",
|
| 24 |
+
"padding_side": "right",
|
| 25 |
+
"pretokenize_regex": "(?i:'s|'t|'re|'ve|'m|'ll|'d)|[^\\r\\n\\p{L}\\p{N}]?[\\p{L}\\p{M}]+|\\p{N}| ?[^\\s\\p{L}\\p{M}\\p{N}]+[\\r\\n]*|\\s*[\\r\\n]+|\\s+(?!\\S)|\\s+",
|
| 26 |
+
"processor_class": "Qwen3VLProcessor",
|
| 27 |
+
"split_special_tokens": false,
|
| 28 |
+
"tokenizer_class": "TokenizersBackend",
|
| 29 |
+
"unk_token": null,
|
| 30 |
+
"video_token": "<|video_pad|>",
|
| 31 |
+
"vision_bos_token": "<|vision_start|>",
|
| 32 |
+
"vision_eos_token": "<|vision_end|>"
|
| 33 |
+
}
|
export_config_v2.yaml
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
### model
|
| 2 |
+
model_name_or_path: Qwen/Qwen3.5-4B
|
| 3 |
+
adapter_name_or_path: saves/rx5950xt-digital-twin/qlora-v2
|
| 4 |
+
template: qwen3_5_nothink
|
| 5 |
+
finetuning_type: lora
|
| 6 |
+
trust_remote_code: true
|
| 7 |
+
|
| 8 |
+
### export
|
| 9 |
+
export_dir: saves/rx5950xt-digital-twin/merged-v2
|
| 10 |
+
export_size: 2
|
| 11 |
+
export_device: cpu
|
| 12 |
+
export_legacy_format: false
|
gguf/rx5950xt-digital-twin-v2-q8_0.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:84d4b608ce84612c84d67deaef4971f9fe79828302c2d2b59ee3160a3a720aa1
|
| 3 |
+
size 4482402496
|
train_config.yaml
ADDED
|
@@ -0,0 +1,50 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
### model
|
| 2 |
+
model_name_or_path: Qwen/Qwen3.5-4B
|
| 3 |
+
quantization_bit: 4
|
| 4 |
+
quantization_method: bnb
|
| 5 |
+
trust_remote_code: true
|
| 6 |
+
upcast_layernorm: true
|
| 7 |
+
|
| 8 |
+
### method
|
| 9 |
+
stage: sft
|
| 10 |
+
do_train: true
|
| 11 |
+
finetuning_type: lora
|
| 12 |
+
lora_rank: 8
|
| 13 |
+
lora_alpha: 16
|
| 14 |
+
lora_target: all
|
| 15 |
+
lora_dropout: 0.1
|
| 16 |
+
|
| 17 |
+
### dataset
|
| 18 |
+
dataset: rx5950xt_discord,alpaca_gpt4_zh
|
| 19 |
+
template: qwen3_5_nothink
|
| 20 |
+
cutoff_len: 512
|
| 21 |
+
max_samples: 2000
|
| 22 |
+
preprocessing_num_workers: 1
|
| 23 |
+
dataloader_num_workers: 0
|
| 24 |
+
|
| 25 |
+
### output
|
| 26 |
+
output_dir: saves/rx5950xt-digital-twin/qlora-v2
|
| 27 |
+
logging_steps: 10
|
| 28 |
+
save_steps: 200
|
| 29 |
+
plot_loss: true
|
| 30 |
+
overwrite_output_dir: true
|
| 31 |
+
save_only_model: false
|
| 32 |
+
report_to: none
|
| 33 |
+
|
| 34 |
+
### train
|
| 35 |
+
per_device_train_batch_size: 1
|
| 36 |
+
gradient_accumulation_steps: 16
|
| 37 |
+
learning_rate: 5.0e-5
|
| 38 |
+
num_train_epochs: 1.0
|
| 39 |
+
lr_scheduler_type: cosine
|
| 40 |
+
warmup_steps: 20
|
| 41 |
+
bf16: true
|
| 42 |
+
gradient_checkpointing: true
|
| 43 |
+
optim: paged_adamw_8bit
|
| 44 |
+
neftune_noise_alpha: 5.0
|
| 45 |
+
|
| 46 |
+
### eval
|
| 47 |
+
val_size: 0.05
|
| 48 |
+
per_device_eval_batch_size: 1
|
| 49 |
+
eval_strategy: steps
|
| 50 |
+
eval_steps: 200
|
training_loss.png
ADDED
|