


Add HyperClick-3B model card with usage and evaluation
Browse files
README.md
ADDED
|
@@ -0,0 +1,135 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: other
|
| 3 |
+
license_name: qwen-research
|
| 4 |
+
license_link: https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct/blob/main/LICENSE
|
| 5 |
+
base_model: Qwen/Qwen2.5-VL-3B-Instruct
|
| 6 |
+
base_model_relation: finetune
|
| 7 |
+
library_name: transformers
|
| 8 |
+
pipeline_tag: image-text-to-text
|
| 9 |
+
tags:
|
| 10 |
+
- hyperclick
|
| 11 |
+
- gui-grounding
|
| 12 |
+
- multimodal
|
| 13 |
+
- confidence-calibration
|
| 14 |
+
- reinforcement-learning
|
| 15 |
+
- arxiv:2510.27266
|
| 16 |
+
---
|
| 17 |
+
|
| 18 |
+
# HyperClick-3B
|
| 19 |
+
|
| 20 |
+
[Paper](https://arxiv.org/pdf/2510.27266) · [Code](https://github.com/xiaomi-research/hyperclick) · [3B model](https://huggingface.co/SeerRay-Lab/Qwen2.5-VL-3B-HyperClick) · [7B model](https://huggingface.co/SeerRay-Lab/Qwen2.5-VL-7B-HyperClick)
|
| 21 |
+
|
| 22 |
+
## Overview
|
| 23 |
+
|
| 24 |
+
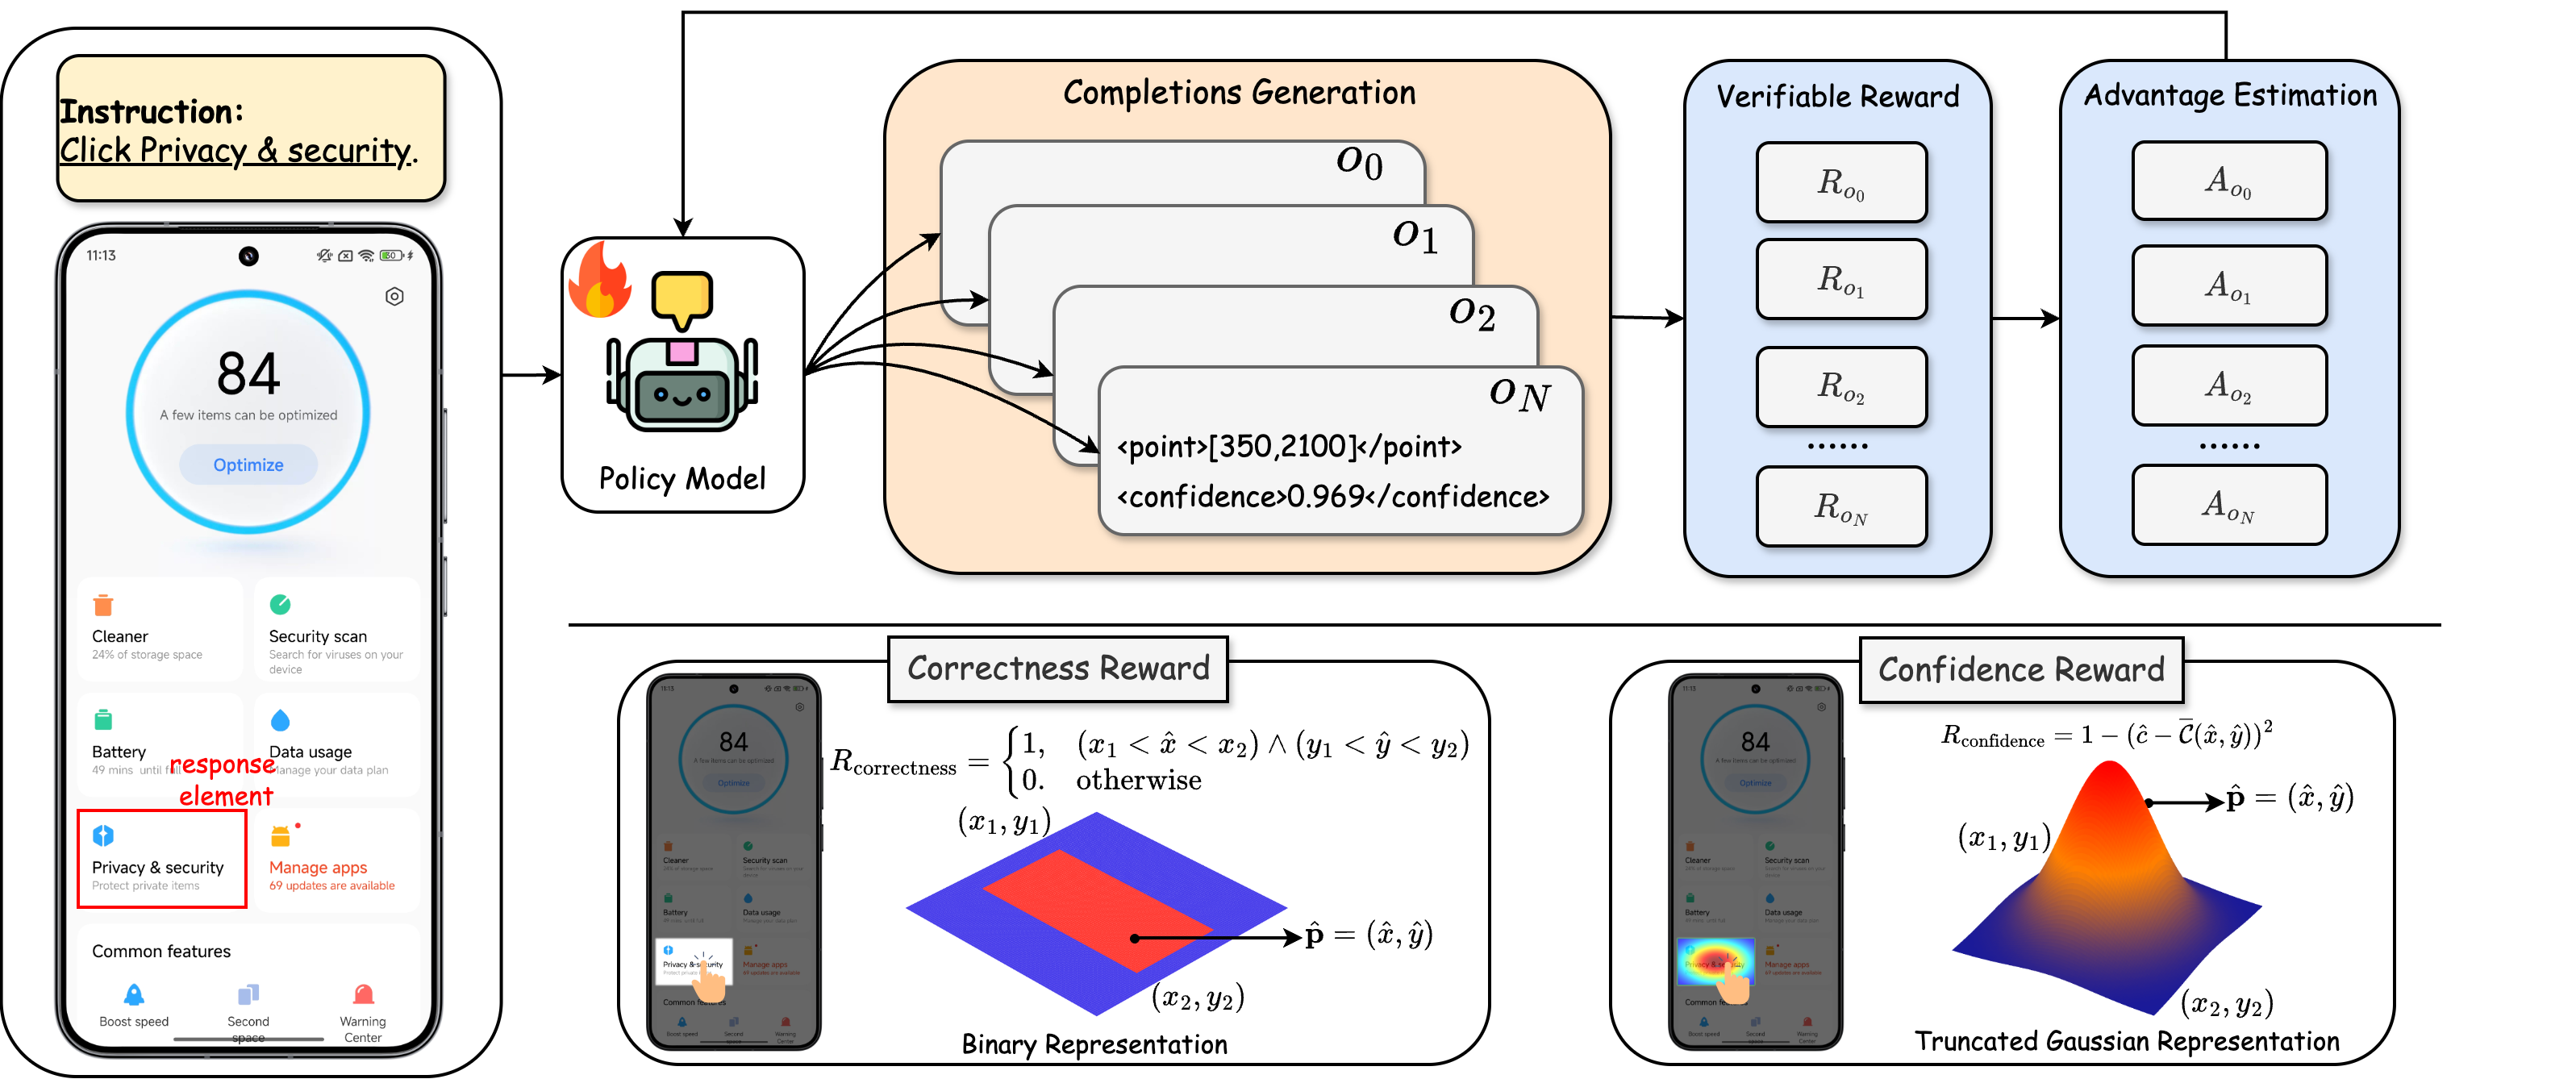
HyperClick grounds natural-language instructions in GUI screenshots and predicts a click point together with an explicit confidence score. This repository contains the **3B checkpoint**, based on [Qwen2.5-VL-3B-Instruct](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct), with full model weights in Safetensors format.
|
| 25 |
+
|
| 26 |
+
The training framework combines supervised fine-tuning with reinforcement fine-tuning. Its rewards check output format, grounding correctness, and confidence alignment using a truncated Gaussian spatial target and the Brier score. See the [training code](https://github.com/xiaomi-research/hyperclick/blob/main/src/open-r1-multimodal/src/open_r1/hyperclick.py) for details.
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
## Reported results
|
| 31 |
+
|
| 32 |
+
Grounding accuracy (%) from the [project evaluation table](https://github.com/xiaomi-research/hyperclick#evaluation). These are the project's reported results, not a new evaluation of the uploaded files.
|
| 33 |
+
|
| 34 |
+
| Model | ScreenSpot | ScreenSpot-v2 | ScreenSpot-Pro | MMBench-GUI | UI-I2E-Bench | CAGUI | UI-Vision |
|
| 35 |
+
| --- | ---: | ---: | ---: | ---: | ---: | ---: | ---: |
|
| 36 |
+
| HyperClick-3B | 88.5 | 90.6 | 41.3 | 71.4 | 71.8 | 81.0 | 19.6 |
|
| 37 |
+
| HyperClick-7B | 91.5 | 93.7 | 48.2 | 79.6 | 76.5 | 82.9 | 25.7 |
|
| 38 |
+
|
| 39 |
+
## Quick start
|
| 40 |
+
|
| 41 |
+
The example below uses Transformers on a CUDA GPU. Install PyTorch for your CUDA environment, then install the inference dependencies:
|
| 42 |
+
|
| 43 |
+
```bash
|
| 44 |
+
pip install "transformers==4.49.0" "accelerate==1.10.0" "qwen-vl-utils==0.0.11" pillow
|
| 45 |
+
```
|
| 46 |
+
|
| 47 |
+
Replace `screenshot.png` and the instruction with your own input. The prompt follows the HyperClick training template.
|
| 48 |
+
|
| 49 |
+
```python
|
| 50 |
+
import torch
|
| 51 |
+
from PIL import Image
|
| 52 |
+
from transformers import AutoProcessor, Qwen2_5_VLForConditionalGeneration
|
| 53 |
+
from qwen_vl_utils import process_vision_info
|
| 54 |
+
|
| 55 |
+
model_id = "SeerRay-Lab/Qwen2.5-VL-3B-HyperClick"
|
| 56 |
+
model = Qwen2_5_VLForConditionalGeneration.from_pretrained(
|
| 57 |
+
model_id, torch_dtype=torch.bfloat16, device_map="auto"
|
| 58 |
+
).eval()
|
| 59 |
+
processor = AutoProcessor.from_pretrained(
|
| 60 |
+
model_id, min_pixels=3136, max_pixels=4390400, use_fast=False
|
| 61 |
+
)
|
| 62 |
+
|
| 63 |
+
screenshot = Image.open("screenshot.png").convert("RGB")
|
| 64 |
+
instruction = "Click the search button"
|
| 65 |
+
messages = [dict(role="user", content=[
|
| 66 |
+
dict(type="image", image=screenshot, min_pixels=3136, max_pixels=4390400),
|
| 67 |
+
dict(type="text", text=(
|
| 68 |
+
f'Point to the element related to the instruction "{instruction}" '
|
| 69 |
+
'on the screenshot with your confidence.'
|
| 70 |
+
)),
|
| 71 |
+
])]
|
| 72 |
+
prompt = processor.apply_chat_template(
|
| 73 |
+
messages, tokenize=False, add_generation_prompt=True
|
| 74 |
+
)
|
| 75 |
+
images, _ = process_vision_info(messages)
|
| 76 |
+
inputs = processor(text=[prompt], images=images, return_tensors="pt").to(model.device)
|
| 77 |
+
with torch.inference_mode():
|
| 78 |
+
generated = model.generate(**inputs, max_new_tokens=128, do_sample=False)
|
| 79 |
+
answer = processor.batch_decode(
|
| 80 |
+
generated[:, inputs.input_ids.shape[1]:], skip_special_tokens=True
|
| 81 |
+
)[0]
|
| 82 |
+
print(answer)
|
| 83 |
+
|
| 84 |
+
# Dimensions of the image coordinate space used by the model.
|
| 85 |
+
patch_size = processor.image_processor.patch_size
|
| 86 |
+
_, grid_h, grid_w = inputs.image_grid_thw[0].tolist()
|
| 87 |
+
input_width, input_height = grid_w * patch_size, grid_h * patch_size
|
| 88 |
+
print("Model image size:", input_width, input_height)
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
### Output format and coordinates
|
| 92 |
+
|
| 93 |
+
The expected output format is:
|
| 94 |
+
|
| 95 |
+
```text
|
| 96 |
+
<point>[x,y]</point><confidence>conf</confidence>
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
`x` and `y` are pixel coordinates in the processed image; `conf` is a confidence estimate between 0 and 1. To map a predicted point back to the original screenshot, use:
|
| 100 |
+
|
| 101 |
+
```python
|
| 102 |
+
# x and y are parsed from the model response.
|
| 103 |
+
x_original = x * screenshot.width / input_width
|
| 104 |
+
y_original = y * screenshot.height / input_height
|
| 105 |
+
```
|
| 106 |
+
|
| 107 |
+
Image resizing affects the coordinate system. Validate the response format and point bounds before using a prediction. Confidence is a learned estimate and can be incorrect, especially for unfamiliar interfaces or ambiguous instructions.
|
| 108 |
+
|
| 109 |
+
## Training
|
| 110 |
+
|
| 111 |
+
The [GitHub repository](https://github.com/xiaomi-research/hyperclick) provides training setup, example annotation formats, and the reinforcement fine-tuning entry points:
|
| 112 |
+
|
| 113 |
+
```bash
|
| 114 |
+
bash src/open-r1-multimodal/run_hyperclick_3b.sh
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
## License
|
| 118 |
+
|
| 119 |
+
This model is derived from Qwen2.5-VL-3B-Instruct. See the upstream [Qwen Research License](https://huggingface.co/Qwen/Qwen2.5-VL-3B-Instruct/blob/main/LICENSE) for the base model terms.
|
| 120 |
+
|
| 121 |
+
## Citation
|
| 122 |
+
|
| 123 |
+
The latest arXiv version is titled *Enhancing Trustworthy GUI Grounding via Self-Critiqued Reinforcement Learning*.
|
| 124 |
+
|
| 125 |
+
```bibtex
|
| 126 |
+
@misc{zhang2025hyperclick,
|
| 127 |
+
title={Enhancing Trustworthy GUI Grounding via Self-Critiqued Reinforcement Learning},
|
| 128 |
+
author={Shaojie Zhang and Pei Fu and Ruoceng Zhang and Jiahui Yang and Anan Du and Xiuwen Xi and Shaokang Wang and Ying Huang and Bin Qin and Zhenbo Luo and Jian Luan},
|
| 129 |
+
year={2025},
|
| 130 |
+
eprint={2510.27266},
|
| 131 |
+
archivePrefix={arXiv},
|
| 132 |
+
primaryClass={cs.CV},
|
| 133 |
+
url={https://arxiv.org/abs/2510.27266}
|
| 134 |
+
}
|
| 135 |
+
```
|