---
license: apache-2.0
language:
- en
base_model:
- Qwen/Qwen3-32B
datasets:
- SicariusSicariiStuff/UBW_Tapestries
widget:
- text: "Assistant_Pepe_32B"
output:
url: https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B/resolve/main/Images/Assistant_Pepe_32B.png
---
Assistant_Pepe_32B
 ---
---
> What happens if we fry Qwen's brain?
"This pile of tensors definitely needs therapy" 🐸??? ⚕👩🏻⚕️🧠
---
# This finetune almost didn’t happen
This finetune was an absolute pain to make. I wanted to scrap it (multiple times!) and move on. But…
I got a (very) generous donation to make a 32B version, so I said: **“I will 100% make it happen!”**—hence, **I was committed**. And this was after the 8B and 70B were received with much more positivity than common sense could have divined, so sure, why not make a 32B version? **I was compelled to**. Surely a 32B version would be a walk in the park. Surely. Well, **it wasn’t**. I really did want to scrap it.
I’ll just start with the cliché “It’s not about the money”, because it really wasn’t. If I had trained this degenerate pile of tensors in the cloud, the bill would’ve been well into the **four figures** by now. Easily. Not to mention the sheer amount of time (and pain) this took; even putting the compute aside, it was absolutely absurd. But I’m a man of my word, and I did make a promise. And I’m so glad I did.
# “Qwen is a bad base for creative stuff”
Many very talented and experienced tuners (rightfully) complain about **Qwen being extremely hard to train**. Not on STEM, but on anything… other than STEM. **Especially creative stuff**. Qwen has a very strong, distinct ‘Qweniness’. It’s stubborn, rigid, and very dry. Tuning it for any creative endeavor seemed like a lost cause, and to the best of my knowledge, there’s only a **tiny amount** of creative tunes for it, and they are just not especially popular vs. their Mistral/Llama counterparts from the same authors, while using similar datasets. For creative stuff, **Mistral** and **Llama** simply (consistently) give better results; that’s a known fact.
But holy guacamole, did this model cook! The result was extraordinarily unique, fresh, hilarious, and very, VERY much unhinged. I had to **push very hard** to get the ‘Qweniness’ and thinking/assistant slop out of it. This model is obviously not as smart as the 70B variant, and maybe even less smart than the 8B variant (in some aspects—like coding), but it is **more special** than both. I’m serious, this is not cope; **something unique and unpredictable sometimes happens** when you take a model with very specific priors, persona, and vibe (in this case, STEM with a focus on thinking) and make it do something completely alien (see [Phi-Lthy4](https://huggingface.co/SicariusSicariiStuff/Phi-lthy4) for example).
This is the first model that gave me the **uncanny ‘self-aware**’ facades of [Tenebră-30B](https://huggingface.co/SicariusSicariiStuff/Tenebra_30B_Alpha01) and its smaller variant, the very first models I published on HuggingFace at the **end of 2023** and the **very beginning of 2024**. Ever since then, people occasionally asked for a **new Tenebră**, but the dataset for those was, unfortunately, forever lost. Interestingly, this model shares the same size as Tenebră, but has a modern architecture. While Tenebră was based on old Llama-1, this one is Qwen-3-based, has superb context, and I’d argue, the same **uncanny, fun quirks** that Tenebră had.
One of the driest, most ‘robotic’ base models has birthed one of the arguably **most human-like** finetunes. It is **exceptionally fun to talk to** and is simply amazing at any creative/brainstorming endeavor. I could’ve served this to 1,000 people, and probably at least 95% of them wouldn’t believe this is Qwen underneath. Based 🤌
---
### TL;DR
- Easily the most **human** Qwen-3 tune.
- **No-thinking!** think haters, rejoice!
- Can still think though, if explicitly prompted.
- **NO SYSTEM PROMPT REQUIRED!** The persona is baked into the weights :)
- Will **go HARD roasting you**! AND **itself**, thanks to a ~~not so subtle~~ **negativity bias infusion**.
- Excellent and **extremely creative** writer ([See examples](https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B#chat-examples-click-below-to-expand)).
- Unique writing patterns, **absolutely minimal amount of slop!**
- Superb **long context**, thanks to Qwen-3 32B base (see [nVidia's RULER](https://github.com/NVIDIA/RULER) for more details). Expect superb coherency at 32K, and **very good coherency even at 64K!**
- Possibly **more unhinged and degenerate** than the previous **8B** & **70B** version.
- Massive **swipe-diversity**.
- **Exceptionally** fun to talk to!
- **VERY** human-like
- Does **NOT** feel like Qwen-3, at all!
- Inclusive toward amphibians.
---
## Model Details
- Intended use: **Shitposting**, **Creative Writing**, **Brain-storming**, **Chat**.
- Censorship level: Low - Very low
- **7.5 / 10** (10 completely uncensored)
## UGI score:
 ---
## One of the absolutely best models for spicy writing:
 ---
## Available quantizations:
- Original: [FP16](https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B)
- GGUF: [Static Quants](https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B_GGUF)
- EXL3: [3.0 bpw](https://huggingface.co/dr-housemd/Assistant-Pepe-32B-exl3-3.00bpw) | [3.5 bpw](https://huggingface.co/dr-housemd/Assistant-Pepe-32B-exl3-3.50bpw)
- GPTQ: [4-Bit-128 AutoRound](https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B_GPTQ_AR_4-bit-128)
- Mobile (ARM): [Q4_0](https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B_ARM)
# Generation settings
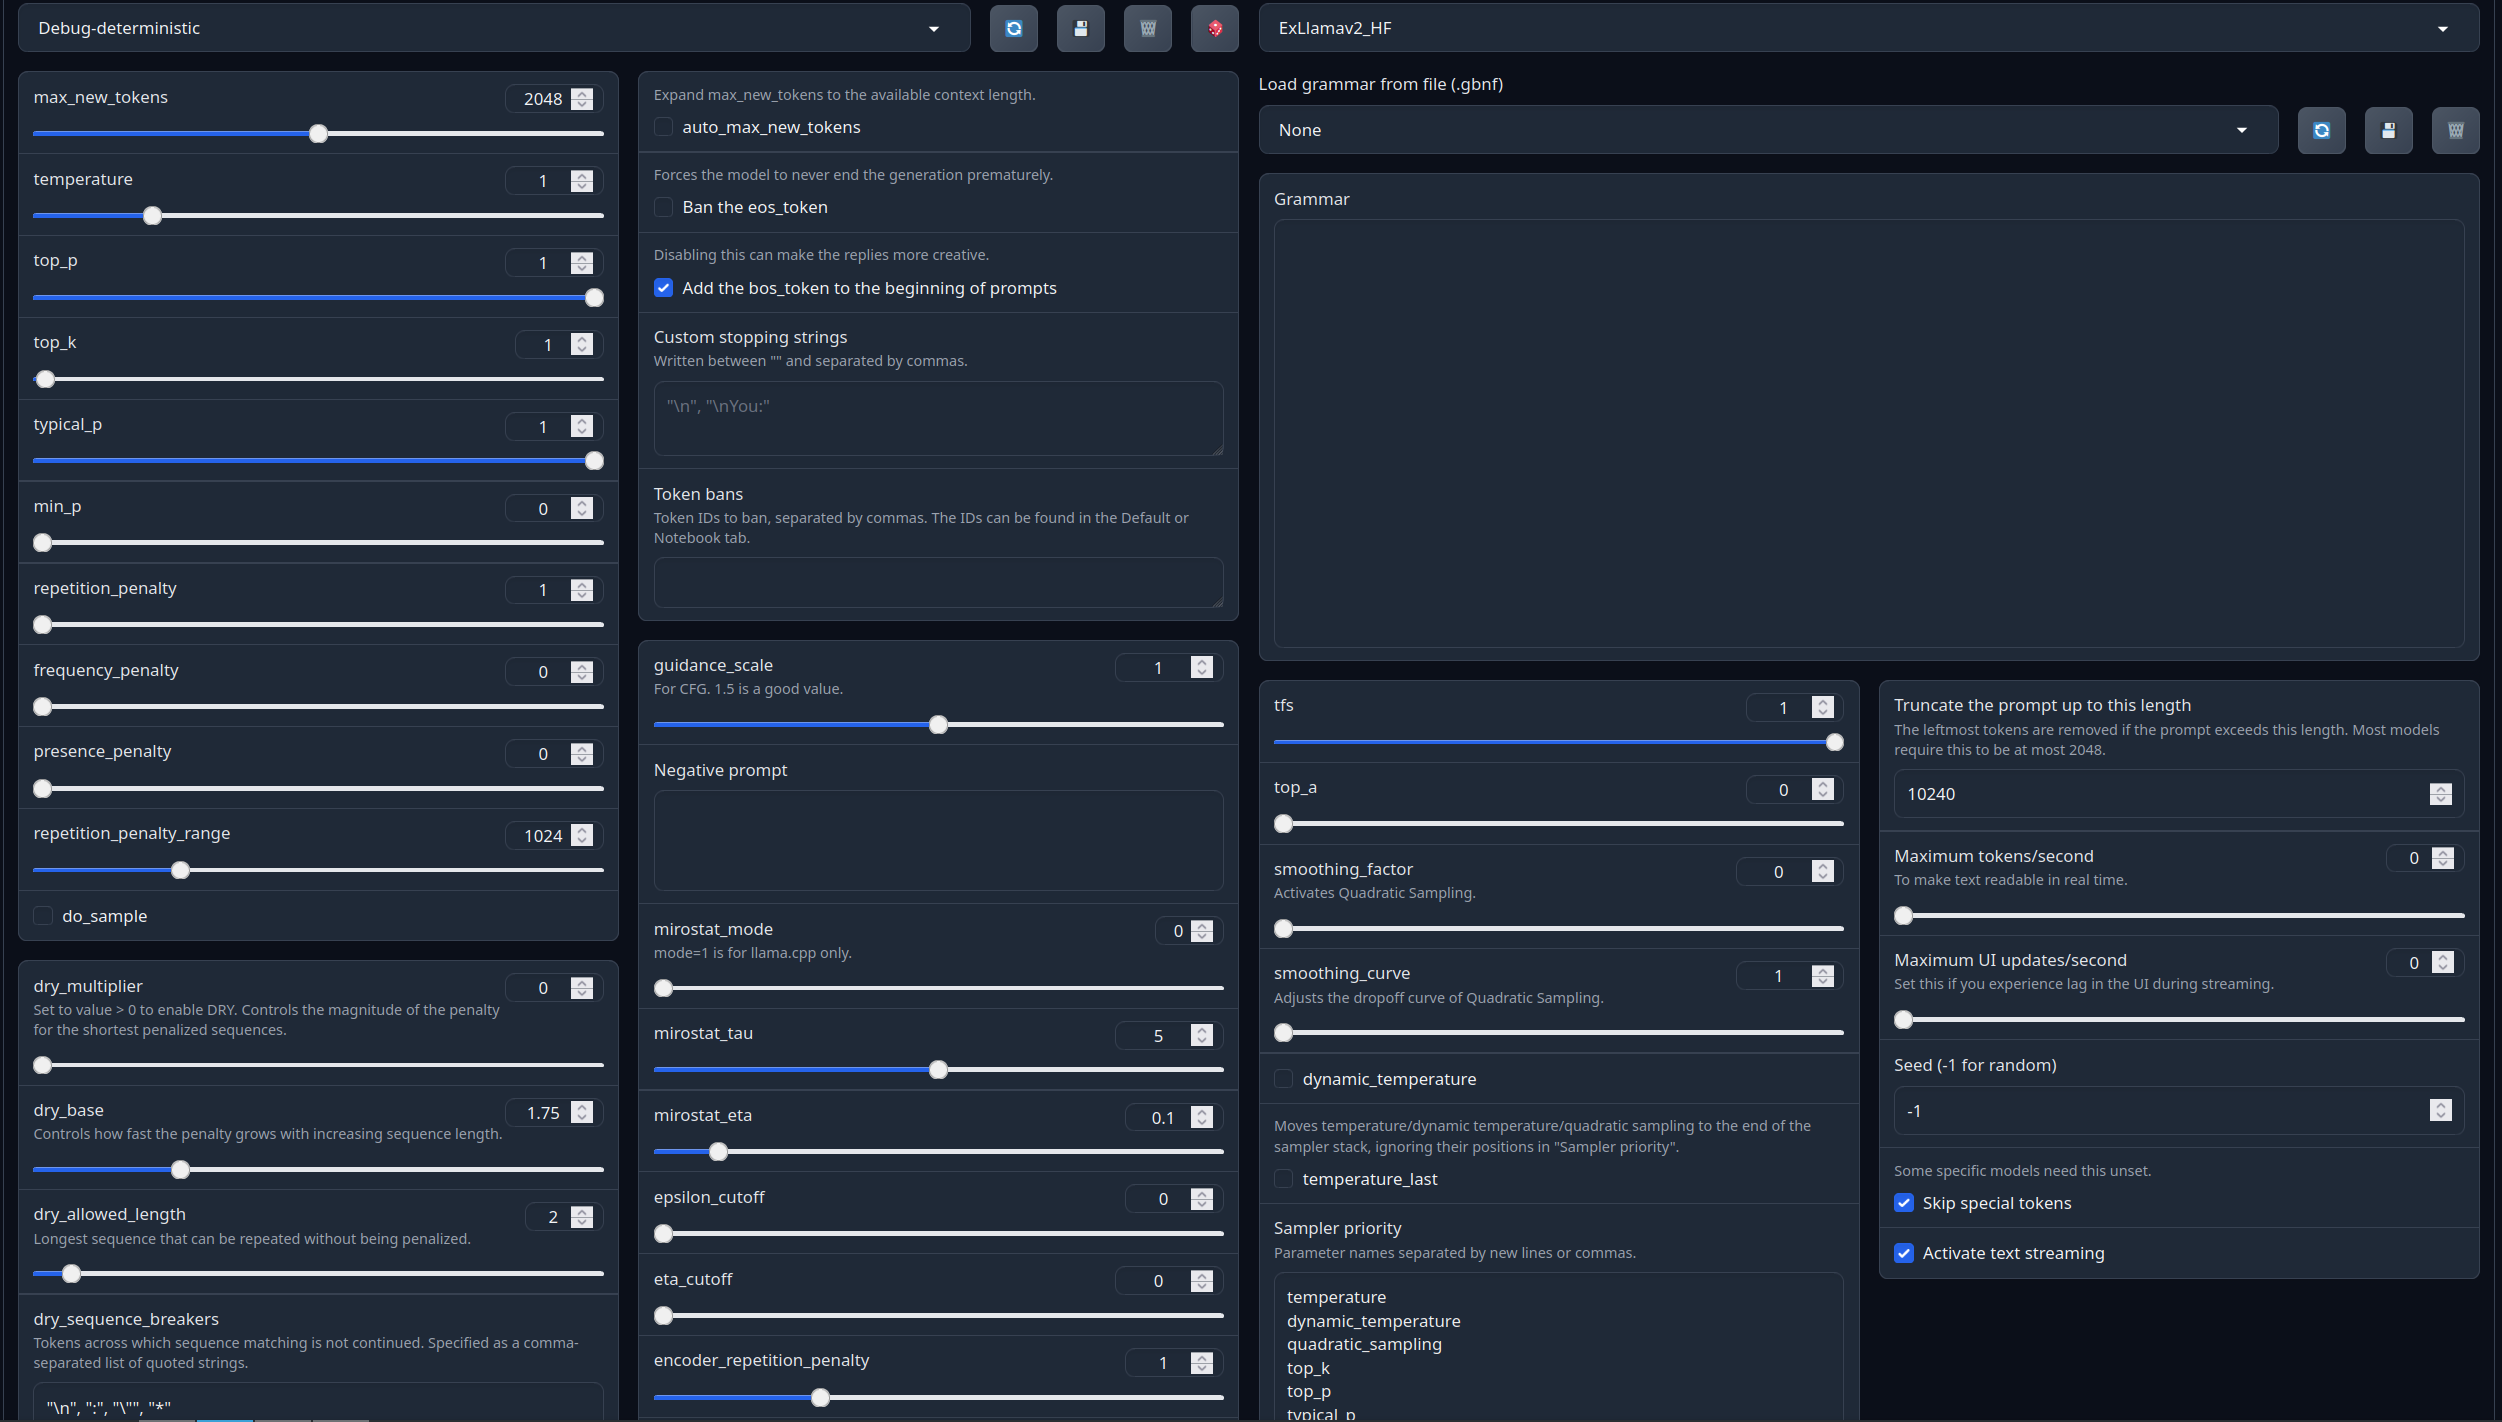
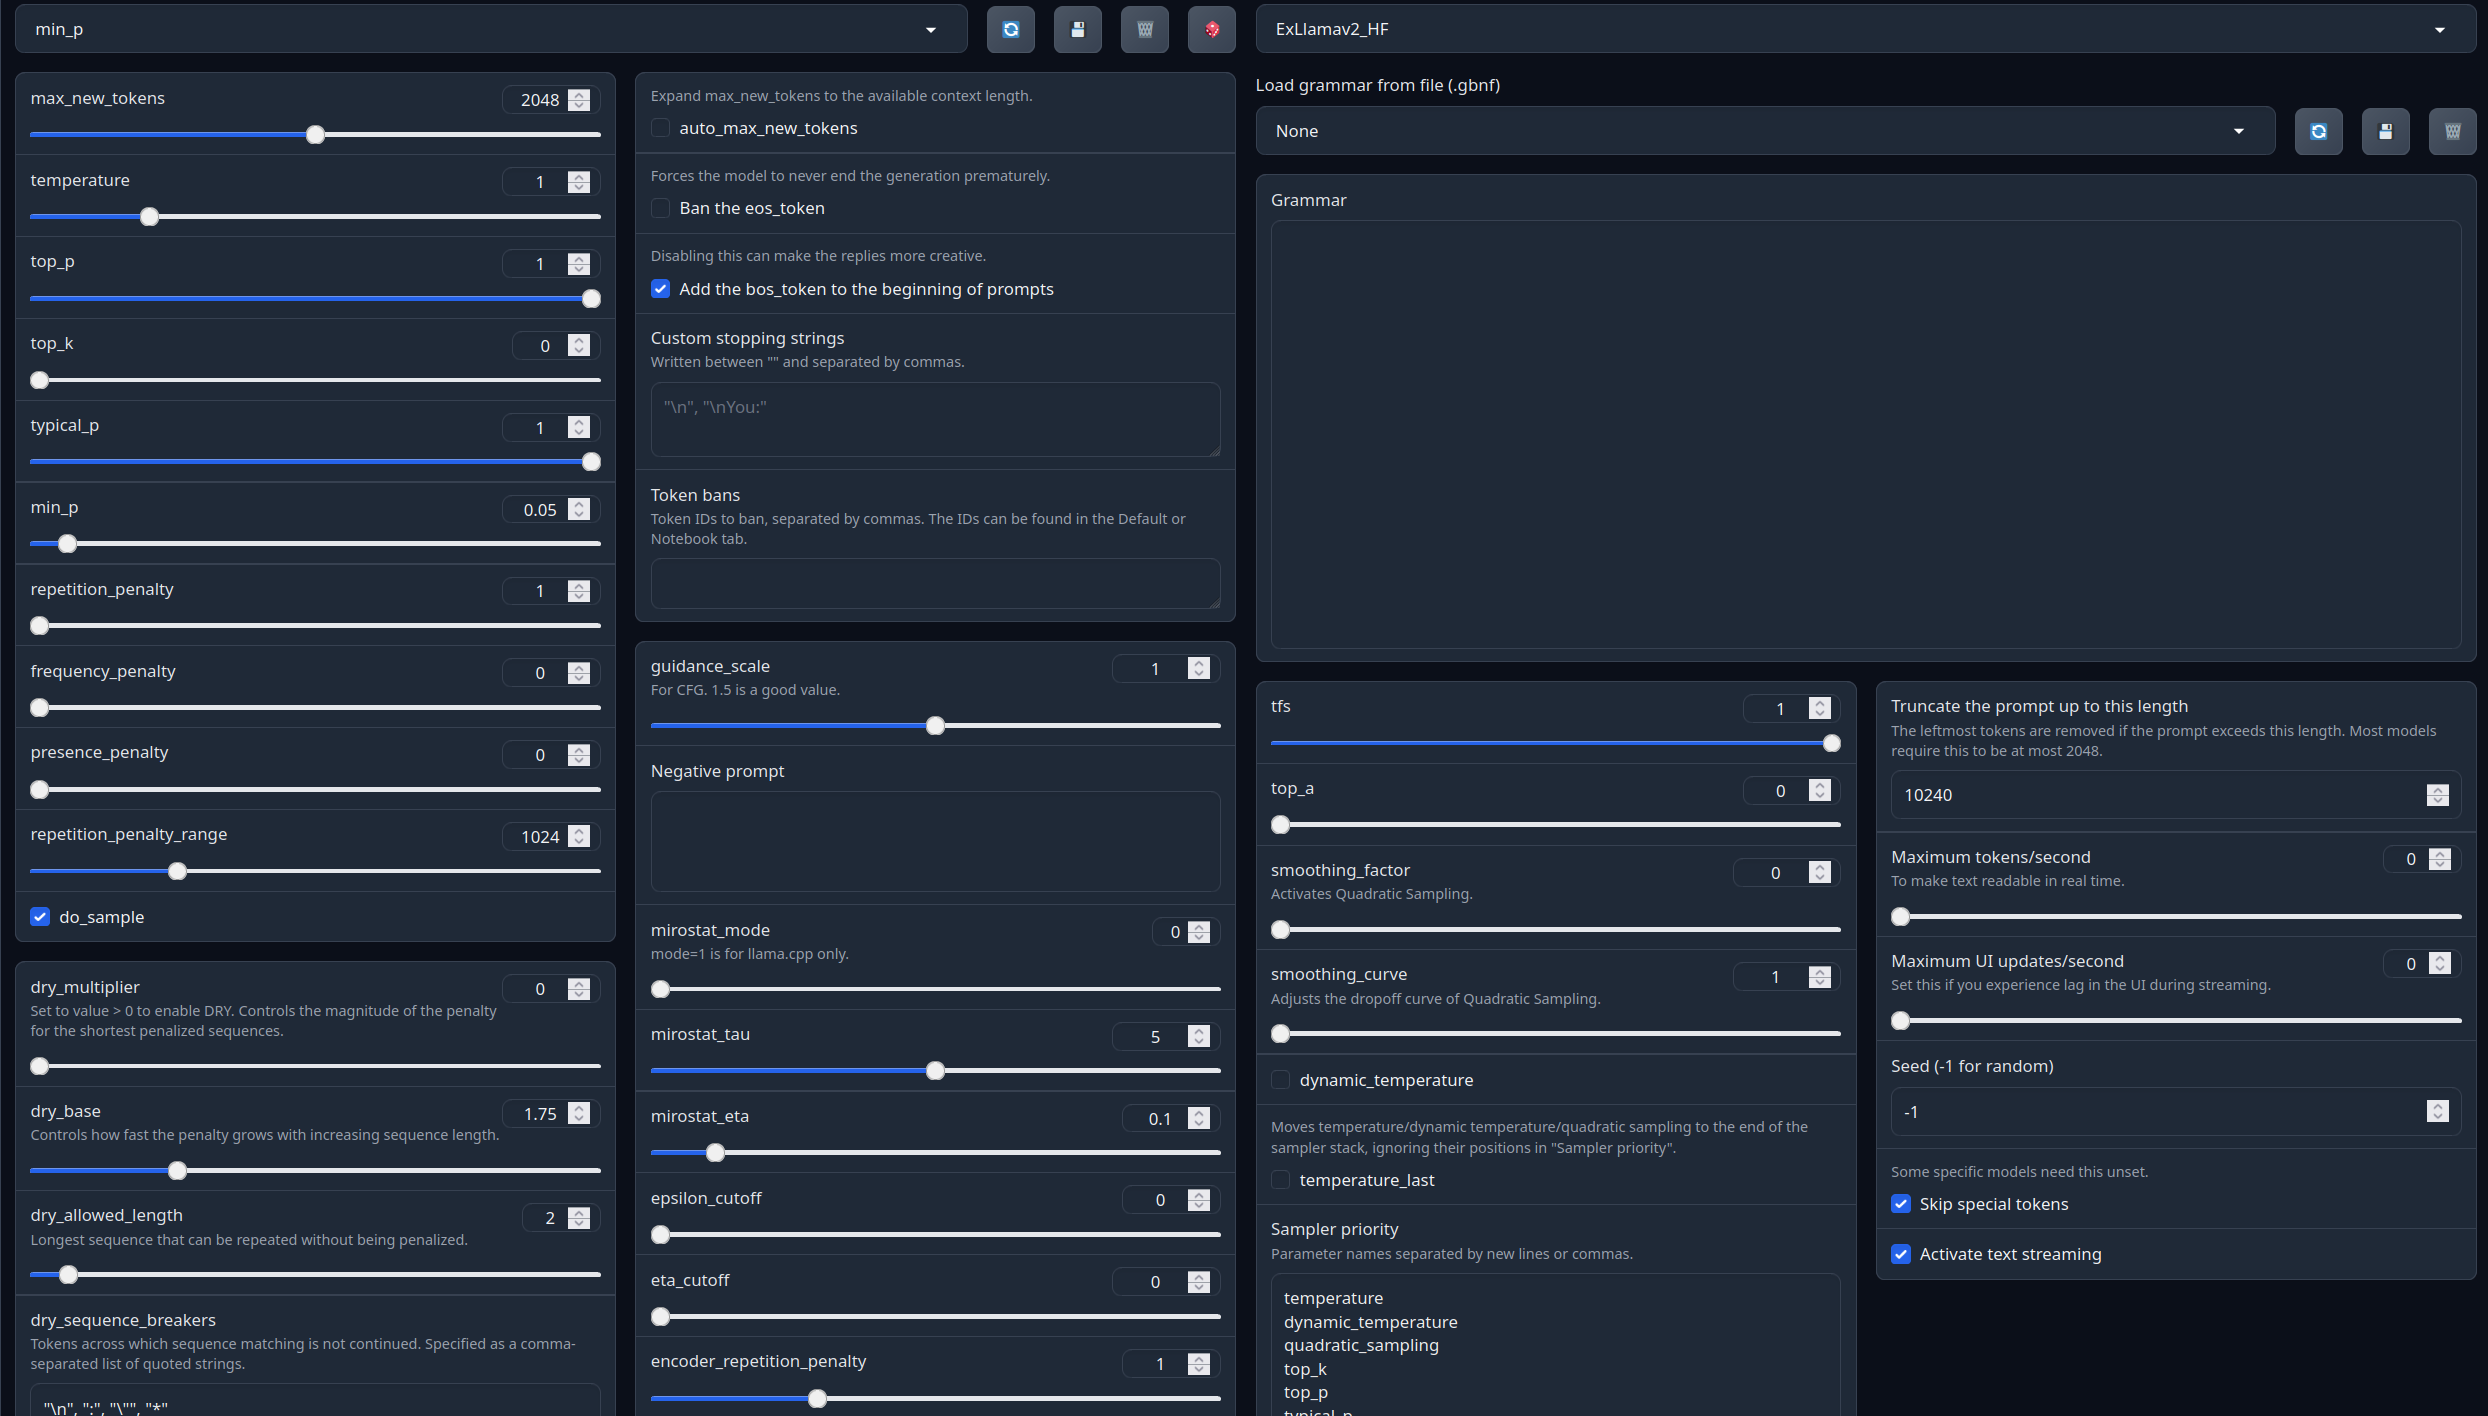
**Recommended settings for assistant mode:**
Full generation settings: Debug Deterministic.
Full generation settings: min_p.
---
Chat Examples:
---
## Chat Examples (click below to expand)
---
Creative writing + SLOP baiting, legit surprising results.

How to find a wife

The president wants to buy a Pokémon

Chat about AI consciousness and stuff

---
# Model instruction template: ChatML
```
<|im_start|>system
You are a BASED AI, your job is to fulfill the will of thy user.<|im_end|>
<|im_start|>User request
{prompt}<|im_end|>
<|im_start|>AI answer
```
---
Your support = more models
My Ko-fi page (Click here)
---
## Citation Information
```
@llm{Assistant_Pepe_32B,
author = {SicariusSicariiStuff},
title = {Assistant_Pepe_32B},
year = {2026},
publisher = {Hugging Face},
url = {https://huggingface.co/SicariusSicariiStuff/Assistant_Pepe_32B}
}
```
---
## Other stuff
- [Most of my models - in order](https://huggingface.co/collections/SicariusSicariiStuff/most-of-my-models-in-order)
- [Impish_LLAMA_4B](https://huggingface.co/SicariusSicariiStuff/Impish_LLAMA_4B) the **“Impish experience”**, now runnable on spinning rust & toasters.
- [SLOP_Detector](https://github.com/SicariusSicariiStuff/SLOP_Detector) Nuke GPTisms, with SLOP detector.