

Add files using upload-large-folder tool
Browse files- .gitattributes +4 -0
- Apertus_SEA-LIONv4.png +3 -0
- README.md +339 -0
- Toolcalling_05_Feb_1pm.png +0 -0
- chat_template.jinja +406 -0
- config.json +38 -0
- generation_config.json +12 -0
- model-00001-of-00004.safetensors +3 -0
- model-00002-of-00004.safetensors +3 -0
- model-00003-of-00004.safetensors +3 -0
- model-00004-of-00004.safetensors +3 -0
- model.safetensors.index.json +459 -0
- sea-helm_scores_05_Feb_1pm.png +3 -0
- special_tokens_map.json +30 -0
- tokenizer.json +3 -0
- tokenizer_config.json +0 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
debug.log filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
Apertus_SEA-LIONv4.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
sea-helm_scores_05_Feb_1pm.png filter=lfs diff=lfs merge=lfs -text
|
Apertus_SEA-LIONv4.png
ADDED

|
Git LFS Details
|
README.md
ADDED
|
@@ -0,0 +1,339 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
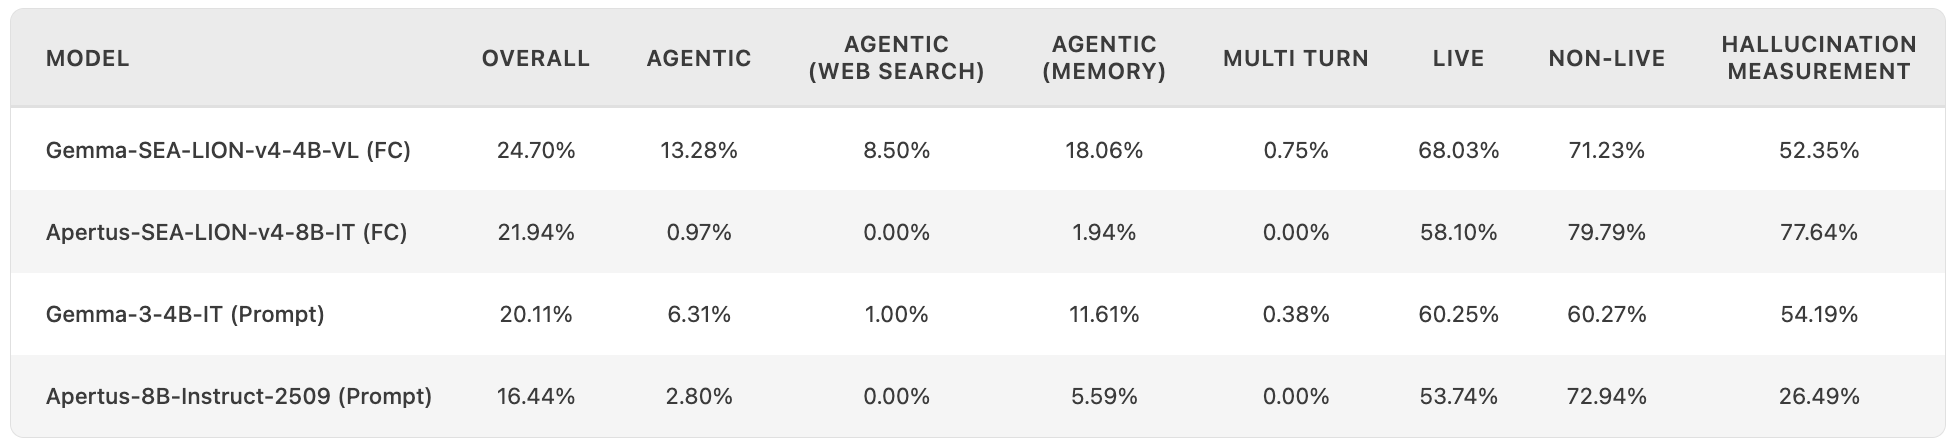
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
library_name: transformers
|
| 3 |
+
tags:
|
| 4 |
+
- generated_from_trainer
|
| 5 |
+
model-index:
|
| 6 |
+
- name: >-
|
| 7 |
+
Apertus-SEA-LION-v4-8B-IT
|
| 8 |
+
results: []
|
| 9 |
+
license: apache-2.0
|
| 10 |
+
language:
|
| 11 |
+
- en
|
| 12 |
+
- zh
|
| 13 |
+
- vi
|
| 14 |
+
- id
|
| 15 |
+
- th
|
| 16 |
+
- fil
|
| 17 |
+
- ta
|
| 18 |
+
- ms
|
| 19 |
+
- km
|
| 20 |
+
- lo
|
| 21 |
+
- my
|
| 22 |
+
base_model:
|
| 23 |
+
- swiss-ai/Apertus-8B-Instruct-2509
|
| 24 |
+
pipeline_tag: text-generation
|
| 25 |
+
---
|
| 26 |
+

|
| 27 |
+
# Apertus-SEA-LION-v4-8B-IT
|
| 28 |
+
|
| 29 |
+
*[Last update: 2026-02-05]*
|
| 30 |
+
|
| 31 |
+
SEA-LION is a collection of Large Language Models (LLMs) which have been pretrained and instruct-tuned for the Southeast Asia (SEA) region.
|
| 32 |
+
|
| 33 |
+
**Apertus-SEA-LION-v4-8B-IT** is a 8-billion parameter model built upon the Apertus-8B-Instruct architecture. To ensure **domain adaptation** for the region, the model underwent rigorous post-training on a curated dataset of approximately **6.4 million** instruction-text pairs.
|
| 34 |
+
|
| 35 |
+
This extensive post-training instills **multilingual** and **multicultural** fluency, covering key SEA languages such as Burmese, Malay, Tagalog and Tamil. This curated dataset also includes a filtered open sourced set of tool-calling instruction-text pairs to impart these capabilities, in addition to linguistic fluency.
|
| 36 |
+
|
| 37 |
+
Apertus-SEA-LION-v4-8B-IT is designed as a fully open model to align with this core philosophy, we have released the datasets used for post-training, as well as the evaluation codes and datasets used to evaluate the model.
|
| 38 |
+
|
| 39 |
+
These resources can be accessed via the link below.
|
| 40 |
+
|
| 41 |
+
- [Open post-training datasets](#Training-Data) we used.
|
| 42 |
+
- [SEA-HELM Evaluation codes and datasets](<https://github.com/aisingapore/SEA-HELM>)
|
| 43 |
+
|
| 44 |
+
## Model Details
|
| 45 |
+
|
| 46 |
+
### Model Description
|
| 47 |
+
|
| 48 |
+
SEA-LION stands for *Southeast Asian Languages In One Network*.
|
| 49 |
+
|
| 50 |
+
We performed Post-Training in English and SEA languages on Apertus-8B-Instruct-2509, a decoder model using the Apertus architecture, to create Apertus-SEA-LION-v4-8B-IT.
|
| 51 |
+
|
| 52 |
+
For tokenization, the model employs the default tokenizer used in Apertus-8B-Instruct-2509.
|
| 53 |
+
|
| 54 |
+
- **Developed by:** AI Products Pillar, AI Singapore
|
| 55 |
+
- **Funded by:** Singapore NRF
|
| 56 |
+
- **Shared by:** AI Products Pillar, AI Singapore
|
| 57 |
+
- **Model type:** Decoder
|
| 58 |
+
- **Context length:** 65k
|
| 59 |
+
- **Language(s):** Fine-tuned on English, Burmese, Tagalog, Malay and Tamil
|
| 60 |
+
- **License:** [Apache-2.0](https://choosealicense.com/licenses/apache-2.0/)
|
| 61 |
+
- **Finetuned from model:** [Apertus-8B-Instruct](https://huggingface.co/swiss-ai/Apertus-8B-Instruct-2509)
|
| 62 |
+
|
| 63 |
+
### Model Sources
|
| 64 |
+
|
| 65 |
+
- **Repository:** <https://huggingface.co/collections/aisingapore/sea-lion-v4>
|
| 66 |
+
|
| 67 |
+
## Uses
|
| 68 |
+
|
| 69 |
+
### Out-of-Scope Use
|
| 70 |
+
|
| 71 |
+
The model has not been aligned for safety. Developers and users should perform their own safety fine-tuning and related security measures. In no event shall the authors be held liable for any claims, damages, or other liabilities arising from the use of the released weights and codes.
|
| 72 |
+
|
| 73 |
+
## Bias, Risks, and Limitations
|
| 74 |
+
|
| 75 |
+
*The model was not tested for robustness against adversarial prompting.* It is important for users to be aware that our model exhibits certain limitations that warrant consideration. Like many LLMs, the model can hallucinate and occasionally generates irrelevant content, introducing fictional elements that are not grounded in the provided context. Users should also exercise caution in interpreting and validating the model's responses due to the potential inconsistencies.
|
| 76 |
+
|
| 77 |
+
## How to Get Started with the Model
|
| 78 |
+
|
| 79 |
+
Use the code below to get started with the model with 🤗 Transformers libraries.
|
| 80 |
+
|
| 81 |
+
```
|
| 82 |
+
pip install transformers>=4.56.0
|
| 83 |
+
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
```
|
| 87 |
+
# The code is adopted from Apertus example
|
| 88 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 89 |
+
|
| 90 |
+
model_name = "aisingapore/Apertus-SEA-LION-v4-8B-IT"
|
| 91 |
+
device = "cuda" # for GPU usage or "cpu" for CPU usage
|
| 92 |
+
|
| 93 |
+
# load the tokenizer and the model
|
| 94 |
+
tokenizer = AutoTokenizer.from_pretrained(model_name)
|
| 95 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 96 |
+
model_name,
|
| 97 |
+
).to(device)
|
| 98 |
+
|
| 99 |
+
# prepare the model input
|
| 100 |
+
prompt = "Explain the concept of 'Hari Raya Puasa' in simple terms."
|
| 101 |
+
messages_think = [
|
| 102 |
+
{"role": "user", "content": prompt}
|
| 103 |
+
]
|
| 104 |
+
|
| 105 |
+
text = tokenizer.apply_chat_template(
|
| 106 |
+
messages_think,
|
| 107 |
+
tokenize=False,
|
| 108 |
+
add_generation_prompt=True,
|
| 109 |
+
)
|
| 110 |
+
model_inputs = tokenizer([text], return_tensors="pt", add_special_tokens=False).to(model.device)
|
| 111 |
+
|
| 112 |
+
# Generate the output
|
| 113 |
+
generated_ids = model.generate(**model_inputs, max_new_tokens=32768)
|
| 114 |
+
|
| 115 |
+
# Get and decode the output
|
| 116 |
+
output_ids = generated_ids[0][len(model_inputs.input_ids[0]) :]
|
| 117 |
+
print(tokenizer.decode(output_ids, skip_special_tokens=True))
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
## Tool Calling
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
The prompt in the example is in Malay and translates to “Please help me find a 4-room flat near Tampines, budget under $500,000. I also want to know the estimated monthly loan payment.”
|
| 124 |
+
|
| 125 |
+
```
|
| 126 |
+
import torch
|
| 127 |
+
from transformers import AutoTokenizer, AutoModelForCausalLM
|
| 128 |
+
|
| 129 |
+
model_id = "aisingapore/Apertus-SEA-LION-v4-8B-IT"
|
| 130 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
|
| 131 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 132 |
+
model_id,
|
| 133 |
+
torch_dtype=torch.bfloat16,
|
| 134 |
+
device_map="auto"
|
| 135 |
+
)
|
| 136 |
+
|
| 137 |
+
messages = [
|
| 138 |
+
{"role": "user", "content": "Tolong carikan flat 4-bilik dekat Tampines, bajet bawah $500,000. Nak tahu juga berapa anggaran pinjaman bulanan."}
|
| 139 |
+
]
|
| 140 |
+
|
| 141 |
+
tools = [
|
| 142 |
+
{
|
| 143 |
+
"type": "function",
|
| 144 |
+
"function": {
|
| 145 |
+
"name": "search_hdb_listings",
|
| 146 |
+
"description": "Search for HDB flats available for sale",
|
| 147 |
+
"parameters": {
|
| 148 |
+
"type": "object",
|
| 149 |
+
"properties": {
|
| 150 |
+
"location": {"type": "string", "description": "Town or area name"},
|
| 151 |
+
"flat_type": {"type": "string", "description": "Flat type e.g. 3-room, 4-room, 5-room"},
|
| 152 |
+
"max_price": {"type": "number", "description": "Maximum price in SGD"}
|
| 153 |
+
},
|
| 154 |
+
"required": ["location", "flat_type"]
|
| 155 |
+
}
|
| 156 |
+
}
|
| 157 |
+
},
|
| 158 |
+
{
|
| 159 |
+
"type": "function",
|
| 160 |
+
"function": {
|
| 161 |
+
"name": "calculate_mortgage",
|
| 162 |
+
"description": "Calculate estimated monthly mortgage payment",
|
| 163 |
+
"parameters": {
|
| 164 |
+
"type": "object",
|
| 165 |
+
"properties": {
|
| 166 |
+
"loan_amount": {"type": "number", "description": "Loan amount in SGD"},
|
| 167 |
+
"interest_rate": {"type": "number", "description": "Annual interest rate as percentage"},
|
| 168 |
+
"loan_tenure_years": {"type": "integer", "description": "Loan period in years"}
|
| 169 |
+
},
|
| 170 |
+
"required": ["loan_amount"]
|
| 171 |
+
}
|
| 172 |
+
}
|
| 173 |
+
}
|
| 174 |
+
]
|
| 175 |
+
|
| 176 |
+
input_ids = tokenizer.apply_chat_template(
|
| 177 |
+
messages,
|
| 178 |
+
tools=tools,
|
| 179 |
+
return_tensors="pt",
|
| 180 |
+
add_generation_prompt=True
|
| 181 |
+
).to(model.device)
|
| 182 |
+
|
| 183 |
+
generated_ids = model.generate(
|
| 184 |
+
input_ids,
|
| 185 |
+
max_new_tokens=512,
|
| 186 |
+
do_sample=False,
|
| 187 |
+
)
|
| 188 |
+
|
| 189 |
+
response = tokenizer.decode(
|
| 190 |
+
generated_ids[0][input_ids.shape[1]:],
|
| 191 |
+
skip_special_tokens=False,
|
| 192 |
+
).replace("<end_of_turn>", "").strip()
|
| 193 |
+
|
| 194 |
+
print(response)
|
| 195 |
+
|
| 196 |
+
```
|
| 197 |
+
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
## Training Details
|
| 201 |
+
|
| 202 |
+
### Training Data
|
| 203 |
+
|
| 204 |
+
The instruction fine-tuning text dataset comprises of a collection of OSS & synthetic data. The datasets used for post-training can be accessed via the link below.
|
| 205 |
+
|
| 206 |
+
**Datasets for Instruction Fine Tuning**:
|
| 207 |
+
|
| 208 |
+
- 🤗[aisingapore/SEA-Instruct-2602](https://huggingface.co/datasets/aisingapore/SEA-Instruct-2602)
|
| 209 |
+
|
| 210 |
+
**Datasets for Tool-calling**:
|
| 211 |
+
|
| 212 |
+
- 🤗[allenai/Dolci-Instruct-SFT-Tool-Use](https://huggingface.co/datasets/allenai/Dolci-Instruct-SFT-Tool-Use)
|
| 213 |
+
- 🤗[Agent-Ark/Toucan-1.5M](https://huggingface.co/datasets/Agent-Ark/Toucan-1.5M)
|
| 214 |
+
|
| 215 |
+
### Training Procedure
|
| 216 |
+
|
| 217 |
+
#### Training Hyperparameters
|
| 218 |
+
|
| 219 |
+
- **Training regime:** Our post-training workflow consists of instruction fine-tuning and model merging.
|
| 220 |
+
- **Training hyperparameters:** The following hyperparameters were used during training:
|
| 221 |
+
|
| 222 |
+
| Category | Hyperparameter | Value |
|
| 223 |
+
| --- | --- | --- |
|
| 224 |
+
| **Optimization** | Optimizer | `ADAMW_TORCH_FUSED` (β1=0.9, β2=0.999, ε=1e-08) |
|
| 225 |
+
| **Batch Size** | Train Batch Size (per device) | `1` |
|
| 226 |
+
| | Eval Batch Size (per device) | `1` |
|
| 227 |
+
| **Hardware** | Distributed Type | `multi-GPU` |
|
| 228 |
+
| | Number of Devices | `64` |
|
| 229 |
+
| **Schedule** | LR Scheduler Type | `constant_with_warmup` |
|
| 230 |
+
| | LR Scheduler Warmup Steps | `269` |
|
| 231 |
+
| **Other** | Training Steps | `5397` |
|
| 232 |
+
| | Seed | `42` |
|
| 233 |
+
|
| 234 |
+
## Evaluation
|
| 235 |
+
|
| 236 |
+
### Testing Data, Factors & Metrics
|
| 237 |
+
|
| 238 |
+
We evaluated Apertus-SEA-LION-v4-8B-IT on general language capabilities and LLM-specific capabilities using SEA-HELM.
|
| 239 |
+
|
| 240 |
+
**Testing Data**
|
| 241 |
+
|
| 242 |
+
General language capabilities
|
| 243 |
+
|
| 244 |
+
For the evaluation of general language capabilities, we employed the [SEA-HELM evaluation benchmark](https://arxiv.org/abs/2502.14301) across a variety of tasks. These tasks include Question Answering (QA), Sentiment Analysis (Sentiment), Toxicity Detection (Toxicity), Translation in both directions (Eng>Lang & Lang>Eng), Abstractive Summarisation (Abssum), Causal Reasoning (Causal), Natural Language Inference (NLI), Linguistic Diagnostics (LINDSEA), Cultural Knowledge (Kalahi) and Global MMLU Lite/Thai Exam.
|
| 245 |
+
|
| 246 |
+
Instruction-following and Multi-turn Chat
|
| 247 |
+
|
| 248 |
+
We evaluated the models on instruction-following and multi-turn chat capabilities with SEA-IFEval (based on [IFEval](https://arxiv.org/abs/2311.07911)) and SEA-MTBench (based on [MT-Bench](https://arxiv.org/abs/2306.05685)) respectively. The two datasets were originally in English, the linguists and native speakers in the team worked together to filter, localise and translate the datasets into the respective target languages to ensure that the examples remained reasonable, meaningful and natural.
|
| 249 |
+
|
| 250 |
+
#### Factors
|
| 251 |
+
|
| 252 |
+
All evaluations were run with the model specific generation parameters defined in the model config. Each evaluation comprised of 8 runs with different seeds and the final results were averaged across these runs.
|
| 253 |
+
|
| 254 |
+
For all tasks, the model was expected to provide an answer tag from which the answer was automatically extracted. For tasks where options were provided, the answer should comprise one of the pre-defined options.
|
| 255 |
+
|
| 256 |
+
The evaluation was done **zero-shot** with native prompts on a sample of 100-1000 instances for each dataset.
|
| 257 |
+
|
| 258 |
+
SEA-IFEval
|
| 259 |
+
|
| 260 |
+
SEA-IFEval evaluates a model's ability to adhere to constraints provided in the prompt, for example beginning a response with a specific word/phrase or answering with a certain number of sections. Additionally, accuracy is normalised by the proportion of responses in the correct language (if the model performs the task correctly but responds in the wrong language, it is judged to have failed the task).
|
| 261 |
+
|
| 262 |
+
SEA-MTBench
|
| 263 |
+
|
| 264 |
+
SEA-MTBench evaluates a model's ability to engage in multi-turn (2 turns) conversations and respond in ways that align with human needs. We use `gpt-4.1-2025-04-14` as the judge model and compare against `gpt-4.1-2025-04-14` as the baseline model. The metric used is the weighted win rate against the baseline model (i.e. average win rate across each category: Math, Reasoning, STEM, Humanities, Roleplay, Writing, Extraction).
|
| 265 |
+
|
| 266 |
+
#### Metrics
|
| 267 |
+
|
| 268 |
+
The following metrics were used for text capabilities:
|
| 269 |
+
|
| 270 |
+
| **Task** | **Metric** |
|
| 271 |
+
| --- | --- |
|
| 272 |
+
| Sentiment Analysis | Accuracy |
|
| 273 |
+
| Extractive QA (ID, VI, TH, TA) | ChrF++ |
|
| 274 |
+
| MCQ-QA (TL, MY, MS) | Accuracy |
|
| 275 |
+
| Metaphor | Accuracy |
|
| 276 |
+
| Abstractive Summarisation | Rouge-L |
|
| 277 |
+
| Translations | MetricX-24 score (with reference) |
|
| 278 |
+
| Causal Reasoning | Accuracy |
|
| 279 |
+
| Natural Language Inference | Accuracy |
|
| 280 |
+
| LINDSEA | Accuracy |
|
| 281 |
+
| Global MMLU Lite | Accuracy |
|
| 282 |
+
| Thai Exam | Accuracy |
|
| 283 |
+
| Kalahi | Accuracy |
|
| 284 |
+
| SEA-IFEval | Accuracy |
|
| 285 |
+
| SEA-MTBench | Win rate against a reference |
|
| 286 |
+
|
| 287 |
+
### Evaluating Apertus-SEA-LION-v4-8B-IT on SEA-HELM
|
| 288 |
+
|
| 289 |
+
Apertus-SEA-LION-v4-8B-IT can be evaluated by following the steps in: [https://github.com/aisingapore/SEA-HELM/tree/main?tab=readme-ov-file#instructions-for-running-sea-helm](https://github.com/aisingapore/SEA-HELM/tree/seahelm-update?tab=readme-ov-file#instructions-for-running-sea-helm)
|
| 290 |
+
|
| 291 |
+
### Results
|
| 292 |
+
|
| 293 |
+

|
| 294 |
+
|
| 295 |
+
For details on Apertus-SEA-LION-v4-8B-IT performance, please refer to the SEA-HELM leaderboard, <https://leaderboard.sea-lion.ai/> .
|
| 296 |
+
|
| 297 |
+
### Tool calling
|
| 298 |
+
|
| 299 |
+
We evaluated the tool calling capabilities of our model using the Berkeley Function Calling Leaderboard (BFCL) V4 evaluation.
|
| 300 |
+
|
| 301 |
+
#### Factors
|
| 302 |
+
|
| 303 |
+
The evaluation was done using the codes from the BFCL v4 repository. Modifications were made to the agentic web search task:
|
| 304 |
+
|
| 305 |
+
- The Brave Search API was used instead of the DuckDuckGo Search API. The Brave Search API is also a privacy focused search engine and is similar to the DuckDuckGo Search API.
|
| 306 |
+
|
| 307 |
+
**Note:** Apertus-8b was run in prompt mode as it does not support function calling.
|
| 308 |
+
|
| 309 |
+
#### Results
|
| 310 |
+

|
| 311 |
+
|
| 312 |
+
## Technical Specifications
|
| 313 |
+
|
| 314 |
+
### Software Environment & Requirements
|
| 315 |
+
|
| 316 |
+
| Library | Version |
|
| 317 |
+
| --- | --- |
|
| 318 |
+
| `Transformers` | `4.57.1` |
|
| 319 |
+
| `PyTorch` | `2.8.0 + cu129` |
|
| 320 |
+
| `Datasets` | `4.4.2` |
|
| 321 |
+
| `Tokenizers` | `0.22.1` |
|
| 322 |
+
|
| 323 |
+
## More Information
|
| 324 |
+
|
| 325 |
+
This is the repository for the commercial instruction-tuned model. The model has *not* been aligned for safety. Developers and users should perform their own safety fine-tuning and related security measures. In no event shall the authors be held liable for any claims, damages, or other liabilities arising from the use of the released weights and codes.
|
| 326 |
+
|
| 327 |
+
For more info, please contact us at [sealion@aisingapore.org](mailto:sealion@aisingapore.org)
|
| 328 |
+
|
| 329 |
+
## Team
|
| 330 |
+
|
| 331 |
+
Ahmed Dabeer, Ahn Jeongmi, Antonyrex Sajeban, Chan Hok Teng Adwin, Cheng Zi Yi Nicholas, Choa Hsueh Mei Esther, Heng Jonathan, Huang Yuli, Jann Railey Estrada Montalan, Kang Siow Wei Bryan, Lee Chwan Ren, Leong Wai Yi, Leong Wei Qi, Liew Rachel, Limkonchotiwat Peerat, Muhammad Ridzuan Bin Mokhtar, Nagarajan Karthik, Ng Boon Cheong Raymond, Ngee Chia Tai, Ngui Jian Gang, Nguyen Thanh Ngan, Ong Tat-Wee David, Ong Zhi Hao, Pereira Mark, Poon Joseph, Rengarajan Hamsawardhini, Susanto Yosephine, Sutaveephamochanon Anocha, Tan Choon Meng, Tan Chor Phin Evelyn, Tan Siao Wei Jessica, Tan Yixian, Tee Jun Yun, Teng Kok Wai Walter, Teo Eng Sipp Leslie, Tjhi William, Wu Donghang, Yeo Yeow Tong, Yong Xianbin, Zhang Zhou, Imanol Schlag (Swiss AI), Antoine Bosselut (Swiss AI) and Martin Jaggi (Swiss AI)
|
| 332 |
+
|
| 333 |
+
## Acknowledgement
|
| 334 |
+
|
| 335 |
+
This project is supported by the National Research Foundation Singapore and Infocomm Media Development Authority (IMDA), Singapore under its National Large Language Model Funding Initiative.
|
| 336 |
+
|
| 337 |
+
## Contact
|
| 338 |
+
|
| 339 |
+
[sealion@aisingapore.org](mailto:sealion@aisingapore.org)
|
Toolcalling_05_Feb_1pm.png
ADDED
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,406 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- macro render_typescript_type(param_spec, required_params, is_nullable=false) -%}
|
| 2 |
+
{%- if param_spec.type == "array" -%}
|
| 3 |
+
{%- if param_spec["items"] -%}
|
| 4 |
+
{%- if param_spec["items"]["type"] == "string" -%}
|
| 5 |
+
{{- "string[]" -}}
|
| 6 |
+
{%- elif param_spec["items"]["type"] == "number" -%}
|
| 7 |
+
{{- "number[]" -}}
|
| 8 |
+
{%- elif param_spec["items"]["type"] == "integer" -%}
|
| 9 |
+
{{- "number[]" -}}
|
| 10 |
+
{%- elif param_spec["items"]["type"] == "boolean" -%}
|
| 11 |
+
{{- "boolean[]" -}}
|
| 12 |
+
{%- else -%}
|
| 13 |
+
{%- set inner_type = render_typescript_type(param_spec["items"], required_params) -%}
|
| 14 |
+
{%- if inner_type == "object | object" or inner_type|length > 50 -%}
|
| 15 |
+
{{- "any[]" -}}
|
| 16 |
+
{%- else -%}
|
| 17 |
+
{{- inner_type ~ "[]" -}}
|
| 18 |
+
{%- endif -%}
|
| 19 |
+
{%- endif -%}
|
| 20 |
+
|
| 21 |
+
{%- if param_spec.nullable -%}
|
| 22 |
+
{{- " | null" -}}
|
| 23 |
+
{%- endif -%}
|
| 24 |
+
{%- else -%}
|
| 25 |
+
{{- "any[]" -}}
|
| 26 |
+
{%- if param_spec.nullable -%}
|
| 27 |
+
{{- " | null" -}}
|
| 28 |
+
{%- endif -%}
|
| 29 |
+
{%- endif -%}
|
| 30 |
+
|
| 31 |
+
{%- elif param_spec.type is defined
|
| 32 |
+
and param_spec.type is iterable
|
| 33 |
+
and param_spec.type is not string
|
| 34 |
+
and param_spec.type is not mapping
|
| 35 |
+
and param_spec.type[0] is defined -%}
|
| 36 |
+
{%- if param_spec.type | length > 1 -%}
|
| 37 |
+
{{- param_spec.type | join(" | ") -}}
|
| 38 |
+
{%- else -%}
|
| 39 |
+
{{- param_spec.type[0] -}}
|
| 40 |
+
{%- endif -%}
|
| 41 |
+
|
| 42 |
+
{%- elif param_spec.oneOf is defined -%}
|
| 43 |
+
{%- set has_object_variants = false -%}
|
| 44 |
+
{%- for variant in param_spec.oneOf -%}
|
| 45 |
+
{%- if variant.type == "object" -%}
|
| 46 |
+
{%- set has_object_variants = true -%}
|
| 47 |
+
{%- endif -%}
|
| 48 |
+
{%- endfor -%}
|
| 49 |
+
|
| 50 |
+
{%- if has_object_variants and param_spec.oneOf|length > 1 -%}
|
| 51 |
+
{{- "any" -}}
|
| 52 |
+
{%- else -%}
|
| 53 |
+
{%- for variant in param_spec.oneOf -%}
|
| 54 |
+
{{- render_typescript_type(variant, required_params) -}}
|
| 55 |
+
{%- if variant.description is defined -%}
|
| 56 |
+
{{- "// " ~ variant.description -}}
|
| 57 |
+
{%- endif -%}
|
| 58 |
+
{%- if variant.default is defined -%}
|
| 59 |
+
{{- "// default: " ~ variant.default|tojson -}}
|
| 60 |
+
{%- endif -%}
|
| 61 |
+
{%- if not loop.last -%}
|
| 62 |
+
{{- " | " -}}
|
| 63 |
+
{%- endif -%}
|
| 64 |
+
{%- endfor -%}
|
| 65 |
+
{%- endif -%}
|
| 66 |
+
|
| 67 |
+
{%- elif param_spec.type == "string" -%}
|
| 68 |
+
{%- if param_spec.enum is defined -%}
|
| 69 |
+
{{- '"' ~ param_spec.enum|join('" | "') ~ '"' -}}
|
| 70 |
+
{%- else -%}
|
| 71 |
+
{{- "string" -}}
|
| 72 |
+
{%- if param_spec.nullable is defined and param_spec.nullable -%}
|
| 73 |
+
{{- " | null" -}}
|
| 74 |
+
{%- endif -%}
|
| 75 |
+
{%- endif -%}
|
| 76 |
+
|
| 77 |
+
{%- elif param_spec.type == "number" -%}
|
| 78 |
+
{{- "number" -}}
|
| 79 |
+
|
| 80 |
+
{%- elif param_spec.type == "integer" -%}
|
| 81 |
+
{{- "number" -}}
|
| 82 |
+
|
| 83 |
+
{%- elif param_spec.type == "boolean" -%}
|
| 84 |
+
{{- "boolean" -}}
|
| 85 |
+
|
| 86 |
+
{%- elif param_spec.type == "object" -%}
|
| 87 |
+
{%- if param_spec.properties is defined -%}
|
| 88 |
+
{{- "{\n" -}}
|
| 89 |
+
{%- for prop_name, prop_spec in param_spec.properties.items() -%}
|
| 90 |
+
{{- prop_name -}}
|
| 91 |
+
{%- if prop_name not in (param_spec.required or []) -%}
|
| 92 |
+
{{- "?" -}}
|
| 93 |
+
{%- endif -%}
|
| 94 |
+
{{- ": " -}}
|
| 95 |
+
{{- render_typescript_type(prop_spec, param_spec.required or []) -}}
|
| 96 |
+
{%- if not loop.last -%}
|
| 97 |
+
{{- ", " -}}
|
| 98 |
+
{%- endif -%}
|
| 99 |
+
{%- endfor -%}
|
| 100 |
+
{{- "}" -}}
|
| 101 |
+
{%- else -%}
|
| 102 |
+
{{- "object" -}}
|
| 103 |
+
{%- endif -%}
|
| 104 |
+
|
| 105 |
+
{%- else -%}
|
| 106 |
+
{{- "any" -}}
|
| 107 |
+
{%- endif -%}
|
| 108 |
+
{%- endmacro -%}
|
| 109 |
+
|
| 110 |
+
{%- macro render_tools(tools) -%}
|
| 111 |
+
{%- for tool in tools -%}
|
| 112 |
+
{%- set tool_name = tool.name if tool.name is defined else tool.function.name -%}
|
| 113 |
+
{%- set tool_desc = tool.description if tool.description is defined else tool.function.description -%}
|
| 114 |
+
{%- set tool_params = tool.parameters if tool.parameters is defined else tool.function.parameters -%}
|
| 115 |
+
|
| 116 |
+
{{- "// " ~ tool_desc ~ "\n" -}}
|
| 117 |
+
{{- "type " ~ tool_name ~ " = " -}}
|
| 118 |
+
|
| 119 |
+
{%- if tool_params is defined and tool_params.properties is defined and tool_params.properties|length > 0 -%}
|
| 120 |
+
{{- "(_: {\n" -}}
|
| 121 |
+
{%- for param_name, param_spec in tool_params.properties.items() -%}
|
| 122 |
+
{%- if param_spec.description is defined -%}
|
| 123 |
+
{{- "// " ~ param_spec.description ~ "\n" -}}
|
| 124 |
+
{%- endif -%}
|
| 125 |
+
|
| 126 |
+
{{- param_name -}}
|
| 127 |
+
{%- if param_name not in (tool_params.required or []) -%}
|
| 128 |
+
{{- "?" -}}
|
| 129 |
+
{%- endif -%}
|
| 130 |
+
{{- ": " -}}
|
| 131 |
+
{{- render_typescript_type(param_spec, tool_params.required or []) -}}
|
| 132 |
+
|
| 133 |
+
{%- if param_spec.default is defined -%}
|
| 134 |
+
{%- if param_spec.enum is defined -%}
|
| 135 |
+
{{- ", // default: " ~ param_spec.default -}}
|
| 136 |
+
{%- elif param_spec.oneOf is defined -%}
|
| 137 |
+
{{- "// default: " ~ param_spec.default -}}
|
| 138 |
+
{%- else -%}
|
| 139 |
+
{{- ", // default: " ~ param_spec.default|tojson -}}
|
| 140 |
+
{%- endif -%}
|
| 141 |
+
{%- endif -%}
|
| 142 |
+
|
| 143 |
+
{%- if not loop.last -%}
|
| 144 |
+
{{- ",\n" -}}
|
| 145 |
+
{%- else -%}
|
| 146 |
+
{{- "\n" -}}
|
| 147 |
+
{%- endif -%}
|
| 148 |
+
{%- endfor -%}
|
| 149 |
+
{{- "}) => any;" -}}
|
| 150 |
+
{%- else -%}
|
| 151 |
+
{{- "() => any;" -}}
|
| 152 |
+
{%- endif -%}
|
| 153 |
+
|
| 154 |
+
{%- if not loop.last -%}
|
| 155 |
+
{{- "\n" -}}
|
| 156 |
+
{%- endif -%}
|
| 157 |
+
{%- endfor -%}
|
| 158 |
+
{%- endmacro -%}
|
| 159 |
+
|
| 160 |
+
{%- macro render_tools_json(tools) -%}
|
| 161 |
+
<tools>
|
| 162 |
+
{%- for tool in tools -%}
|
| 163 |
+
{{- tool | tojson -}}
|
| 164 |
+
{{- "\n" -}}
|
| 165 |
+
{%- endfor -%}
|
| 166 |
+
</tools>
|
| 167 |
+
{%- endmacro -%}
|
| 168 |
+
|
| 169 |
+
{# ============================== preamble / tokens ============================== #}
|
| 170 |
+
|
| 171 |
+
{{- bos_token -}}
|
| 172 |
+
|
| 173 |
+
{%- set system_token = "<|system_start|>" -%}
|
| 174 |
+
{%- set end_system_token = "<|system_end|>" -%}
|
| 175 |
+
{%- set developer_token = "<|developer_start|>" -%}
|
| 176 |
+
{%- set end_developer_token = "<|developer_end|>" -%}
|
| 177 |
+
{%- set user_token = "<|user_start|>" -%}
|
| 178 |
+
{%- set end_user_token = "<|user_end|>" -%}
|
| 179 |
+
{%- set assistant_token = "<|assistant_start|>" -%}
|
| 180 |
+
{%- set end_assistant_token = "<|assistant_end|>" -%}
|
| 181 |
+
{%- set inner_token = "<|inner_prefix|>" -%}
|
| 182 |
+
{%- set outer_token = "<|inner_suffix|>" -%}
|
| 183 |
+
{%- set image_token = "<|image|>" -%}
|
| 184 |
+
|
| 185 |
+
{%- set ns = namespace(
|
| 186 |
+
in_assistant=false,
|
| 187 |
+
in_inner=false,
|
| 188 |
+
waiting_for_tool_outputs=false,
|
| 189 |
+
assistant_format=none,
|
| 190 |
+
has_system=false,
|
| 191 |
+
in_tool_group=false
|
| 192 |
+
) -%}
|
| 193 |
+
|
| 194 |
+
{# ============================== system (now also contains tools) ============================== #}
|
| 195 |
+
|
| 196 |
+
{%- if messages and messages[0].role == "system" -%}
|
| 197 |
+
{%- set ns.has_system = true -%}
|
| 198 |
+
{%- endif -%}
|
| 199 |
+
|
| 200 |
+
{%- if ns.has_system or (tools is defined and tools) -%}
|
| 201 |
+
{{- system_token -}}
|
| 202 |
+
|
| 203 |
+
{%- if ns.has_system -%}
|
| 204 |
+
{%- if "content" in messages[0] -%}
|
| 205 |
+
{%- if messages[0].content is string -%}
|
| 206 |
+
{{- messages[0].content -}}
|
| 207 |
+
{%- elif messages[0].content is mapping and "text" in messages[0].content -%}
|
| 208 |
+
{{- messages[0].content.text -}}
|
| 209 |
+
{%- else -%}
|
| 210 |
+
{{- raise_exception("Invalid system message") -}}
|
| 211 |
+
{%- endif -%}
|
| 212 |
+
{%- else -%}
|
| 213 |
+
{{- raise_exception("Invalid system message") -}}
|
| 214 |
+
{%- endif -%}
|
| 215 |
+
{%- endif -%}
|
| 216 |
+
|
| 217 |
+
{%- if tools is defined and tools -%}
|
| 218 |
+
{%- if ns.has_system -%}
|
| 219 |
+
{{- "\n\n" -}}
|
| 220 |
+
{%- endif -%}
|
| 221 |
+
# Tools
|
| 222 |
+
You may call one or more functions to assist with the user query.
|
| 223 |
+
|
| 224 |
+
You are provided with function signatures within <tools></tools> XML tags:
|
| 225 |
+
{{- render_tools_json(tools) -}}
|
| 226 |
+
|
| 227 |
+
For each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:
|
| 228 |
+
<tool_call>
|
| 229 |
+
{"name": <function-name>, "arguments": <args-json-object>}
|
| 230 |
+
</tool_call>
|
| 231 |
+
{%- endif -%}
|
| 232 |
+
|
| 233 |
+
{{- end_system_token -}}
|
| 234 |
+
{%- endif -%}
|
| 235 |
+
|
| 236 |
+
{%- set loop_messages = messages[1:] if ns.has_system else messages -%}
|
| 237 |
+
|
| 238 |
+
{# ============================== optional developer preamble (kept) ============================== #}
|
| 239 |
+
|
| 240 |
+
{%- if enable_thinking is defined and enable_thinking -%}
|
| 241 |
+
{{- developer_token ~ "Deliberation: enabled" ~ end_developer_token -}}
|
| 242 |
+
{%- endif -%}
|
| 243 |
+
|
| 244 |
+
{# ============================== main loop ============================== #}
|
| 245 |
+
|
| 246 |
+
{%- for message in loop_messages -%}
|
| 247 |
+
|
| 248 |
+
{# -------- tool messages -> rendered as USER turns with <tool_response> tags -------- #}
|
| 249 |
+
{%- if message.role == "tool" -%}
|
| 250 |
+
|
| 251 |
+
{%- if ns.in_assistant -%}
|
| 252 |
+
{{- end_assistant_token -}}
|
| 253 |
+
{%- set ns.in_assistant = false -%}
|
| 254 |
+
{%- endif -%}
|
| 255 |
+
|
| 256 |
+
{%- if not ns.in_tool_group -%}
|
| 257 |
+
{{- user_token -}}
|
| 258 |
+
{%- set ns.in_tool_group = true -%}
|
| 259 |
+
{%- endif -%}
|
| 260 |
+
|
| 261 |
+
<tool_response>
|
| 262 |
+
{{- message.content -}}
|
| 263 |
+
</tool_response>
|
| 264 |
+
|
| 265 |
+
{%- set next_is_tool = (not loop.last) and (loop_messages[loop.index0 + 1].role == "tool") -%}
|
| 266 |
+
{%- if not next_is_tool -%}
|
| 267 |
+
{{- end_user_token -}}
|
| 268 |
+
{%- set ns.in_tool_group = false -%}
|
| 269 |
+
{%- set ns.waiting_for_tool_outputs = false -%}
|
| 270 |
+
{%- endif -%}
|
| 271 |
+
|
| 272 |
+
{# -------- user messages -------- #}
|
| 273 |
+
{%- elif message.role == "user" -%}
|
| 274 |
+
|
| 275 |
+
{%- set ns.in_inner = false -%}
|
| 276 |
+
|
| 277 |
+
{%- if ns.in_assistant -%}
|
| 278 |
+
{{- end_assistant_token -}}
|
| 279 |
+
{%- set ns.in_assistant = false -%}
|
| 280 |
+
{%- endif -%}
|
| 281 |
+
|
| 282 |
+
{{- user_token -}}
|
| 283 |
+
{%- if "content" in message -%}
|
| 284 |
+
{%- if message.content is string -%}
|
| 285 |
+
{{- message.content -}}
|
| 286 |
+
{%- elif message.content is mapping and "parts" in message.content -%}
|
| 287 |
+
{%- for part in message.content.parts -%}
|
| 288 |
+
{%- if part.type == "text" -%}
|
| 289 |
+
{{- part.text -}}
|
| 290 |
+
{%- elif part.type == "image" -%}
|
| 291 |
+
{{- image_token -}}
|
| 292 |
+
{%- else -%}
|
| 293 |
+
{{- raise_exception("Invalid user part: " ~ part.type) -}}
|
| 294 |
+
{%- endif -%}
|
| 295 |
+
{%- endfor -%}
|
| 296 |
+
{%- else -%}
|
| 297 |
+
{{- raise_exception("Invalid user message") -}}
|
| 298 |
+
{%- endif -%}
|
| 299 |
+
{%- endif -%}
|
| 300 |
+
{{- end_user_token -}}
|
| 301 |
+
|
| 302 |
+
{# -------- assistant messages (emit <tool_call> tags) -------- #}
|
| 303 |
+
{%- elif message.role == "assistant" -%}
|
| 304 |
+
|
| 305 |
+
{%- if not ns.in_assistant -%}
|
| 306 |
+
{{- assistant_token -}}
|
| 307 |
+
{%- set ns.in_assistant = true -%}
|
| 308 |
+
{%- endif -%}
|
| 309 |
+
|
| 310 |
+
{%- if "content" in message and message.content -%}
|
| 311 |
+
{%- if message.content is string and (ns.assistant_format is none or ns.assistant_format == "string") -%}
|
| 312 |
+
{%- set ns.assistant_format = "string" -%}
|
| 313 |
+
{{- message.content -}}
|
| 314 |
+
|
| 315 |
+
{%- elif message.content is mapping and "blocks" in message.content and (ns.assistant_format is none or ns.assistant_format == "mapping") -%}
|
| 316 |
+
{%- set ns.assistant_format = "mapping" -%}
|
| 317 |
+
|
| 318 |
+
{%- for block in message.content.blocks -%}
|
| 319 |
+
|
| 320 |
+
{%- if block.type == "thoughts" -%}
|
| 321 |
+
{%- if not ns.in_inner -%}
|
| 322 |
+
{%- set ns.in_inner = true -%}
|
| 323 |
+
{{- inner_token -}}
|
| 324 |
+
{%- endif -%}
|
| 325 |
+
{{- block.text -}}
|
| 326 |
+
|
| 327 |
+
{%- elif block.type == "tool_calls" -%}
|
| 328 |
+
{%- if ns.in_inner and not loop.first and block.calls|length == 1 and block.calls[0].name == "display_answers" -%}
|
| 329 |
+
{%- set ns.in_inner = false -%}
|
| 330 |
+
{{- outer_token -}}
|
| 331 |
+
{%- endif -%}
|
| 332 |
+
|
| 333 |
+
{%- for tc in block.calls -%}
|
| 334 |
+
{{- "\n<tool_call>\n{\"name\": \"" ~ tc.name ~ "\", \"arguments\": " -}}
|
| 335 |
+
{%- if tc.arguments is mapping -%}
|
| 336 |
+
{{- tc.arguments | tojson -}}
|
| 337 |
+
{%- else -%}
|
| 338 |
+
{{- tc.arguments -}}
|
| 339 |
+
{%- endif -%}
|
| 340 |
+
{{- "}\n</tool_call>" -}}
|
| 341 |
+
{%- endfor -%}
|
| 342 |
+
|
| 343 |
+
{%- set ns.waiting_for_tool_outputs = true -%}
|
| 344 |
+
|
| 345 |
+
{%- elif block.type == "tool_outputs" -%}
|
| 346 |
+
{# If you ever have inline tool outputs, render as <tool_response> blocks inline #}
|
| 347 |
+
{%- for out in block.outputs -%}
|
| 348 |
+
{{- "\n<tool_response>\n" ~ out.output ~ "\n</tool_response>" -}}
|
| 349 |
+
{%- endfor -%}
|
| 350 |
+
{%- set ns.waiting_for_tool_outputs = false -%}
|
| 351 |
+
|
| 352 |
+
{%- elif block.type == "response" -%}
|
| 353 |
+
{%- if ns.in_inner -%}
|
| 354 |
+
{%- set ns.in_inner = false -%}
|
| 355 |
+
{{- outer_token -}}
|
| 356 |
+
{%- endif -%}
|
| 357 |
+
{{- block.text -}}
|
| 358 |
+
|
| 359 |
+
{%- else -%}
|
| 360 |
+
{{- raise_exception("Invalid assistant block type: " ~ block.type) -}}
|
| 361 |
+
{%- endif -%}
|
| 362 |
+
|
| 363 |
+
{%- endfor -%}
|
| 364 |
+
{%- endif -%}
|
| 365 |
+
{%- endif -%}
|
| 366 |
+
|
| 367 |
+
{# tool_calls field on assistant messages #}
|
| 368 |
+
{%- if "tool_calls" in message and message.tool_calls -%}
|
| 369 |
+
{%- for tool_call in message.tool_calls -%}
|
| 370 |
+
{%- set tc = tool_call.function if tool_call.function is defined else tool_call -%}
|
| 371 |
+
{%- set tc_name = tc.name -%}
|
| 372 |
+
{%- set tc_args = tc.arguments -%}
|
| 373 |
+
|
| 374 |
+
{{- "\n<tool_call>\n{\"name\": \"" ~ tc_name ~ "\", \"arguments\": " -}}
|
| 375 |
+
{%- if tc_args is mapping -%}
|
| 376 |
+
{{- tc_args | tojson -}}
|
| 377 |
+
{%- else -%}
|
| 378 |
+
{{- tc_args -}}
|
| 379 |
+
{%- endif -%}
|
| 380 |
+
{{- "}\n</tool_call>" -}}
|
| 381 |
+
{%- endfor -%}
|
| 382 |
+
|
| 383 |
+
{%- set ns.waiting_for_tool_outputs = true -%}
|
| 384 |
+
{%- endif -%}
|
| 385 |
+
|
| 386 |
+
{%- else -%}
|
| 387 |
+
{{- raise_exception("Invalid message role: " ~ message.role) -}}
|
| 388 |
+
{%- endif -%}
|
| 389 |
+
|
| 390 |
+
{%- endfor -%}
|
| 391 |
+
|
| 392 |
+
{# close any open tool-group user turn #}
|
| 393 |
+
{%- if ns.in_tool_group -%}
|
| 394 |
+
{{- end_user_token -}}
|
| 395 |
+
{%- endif -%}
|
| 396 |
+
|
| 397 |
+
{# close assistant if appropriate #}
|
| 398 |
+
{%- if ns.in_assistant
|
| 399 |
+
and not (continue_assistant_message is defined and continue_assistant_message)
|
| 400 |
+
and not ns.waiting_for_tool_outputs -%}
|
| 401 |
+
{{- end_assistant_token -}}
|
| 402 |
+
{%- endif -%}
|
| 403 |
+
|
| 404 |
+
{%- if add_generation_prompt -%}
|
| 405 |
+
{{- assistant_token -}}
|
| 406 |
+
{%- endif -%}
|
config.json
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"ApertusForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"bos_token_id": 1,
|
| 8 |
+
"dtype": "bfloat16",
|
| 9 |
+
"eos_token_id": 68,
|
| 10 |
+
"hidden_act": "xielu",
|
| 11 |
+
"hidden_dropout": 0.0,
|
| 12 |
+
"hidden_size": 4096,
|
| 13 |
+
"initializer_range": 0.02,
|
| 14 |
+
"intermediate_size": 21504,
|
| 15 |
+
"max_position_embeddings": 65536,
|
| 16 |
+
"mlp_bias": false,
|
| 17 |
+
"model_type": "apertus",
|
| 18 |
+
"num_attention_heads": 32,
|
| 19 |
+
"num_hidden_layers": 32,
|
| 20 |
+
"num_key_value_heads": 8,
|
| 21 |
+
"pad_token_id": 3,
|
| 22 |
+
"post_norm": false,
|
| 23 |
+
"qk_norm": true,
|
| 24 |
+
"rms_norm_eps": 1e-05,
|
| 25 |
+
"rope_scaling": {
|
| 26 |
+
"factor": 8.0,
|
| 27 |
+
"high_freq_factor": 4.0,
|
| 28 |
+
"low_freq_factor": 1.0,
|
| 29 |
+
"original_max_position_embeddings": 8192,
|
| 30 |
+
"rope_type": "llama3",
|
| 31 |
+
"type": "llama3"
|
| 32 |
+
},
|
| 33 |
+
"rope_theta": 12000000,
|
| 34 |
+
"tie_word_embeddings": false,
|
| 35 |
+
"transformers_version": "4.57.1",
|
| 36 |
+
"use_cache": false,
|
| 37 |
+
"vocab_size": 131072
|
| 38 |
+
}
|
generation_config.json
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"bos_token_id": 1,
|
| 4 |
+
"do_sample": true,
|
| 5 |
+
"eos_token_id": [
|
| 6 |
+
2,
|
| 7 |
+
68,
|
| 8 |
+
72
|
| 9 |
+
],
|
| 10 |
+
"pad_token_id": 3,
|
| 11 |
+
"transformers_version": "4.57.1"
|
| 12 |
+
}
|
model-00001-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:41c0b268d865a41adb17e8632fd4b2011f47646d8b523055a6e49bb7fcbbcd0d
|
| 3 |
+
size 4999776624
|
model-00002-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1a1c2bcd2ca1f31a37d9568483cf421b586a189a850562475bdb1ce553ec163e
|
| 3 |
+
size 4882374160
|
model-00003-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:471a71ed2475bc3539bccde8e212660e9e64970dc64c9cecf6c7df31c880ef63
|
| 3 |
+
size 4974647776
|
model-00004-of-00004.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9e8e9a2bd60729f9ac1a38605419fdf864142f68f786700ff858ee469d6aaa6e
|
| 3 |
+
size 1249928128
|
model.safetensors.index.json
ADDED
|
@@ -0,0 +1,459 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_parameters": 8053338240,
|
| 4 |
+
"total_size": 16106676480
|
| 5 |
+
},
|
| 6 |
+
"weight_map": {
|
| 7 |
+
"lm_head.weight": "model-00004-of-00004.safetensors",
|
| 8 |
+
"model.embed_tokens.weight": "model-00001-of-00004.safetensors",
|
| 9 |
+
"model.layers.0.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 10 |
+
"model.layers.0.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 11 |
+
"model.layers.0.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 12 |
+
"model.layers.0.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 13 |
+
"model.layers.0.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 14 |
+
"model.layers.0.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 15 |
+
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 16 |
+
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 17 |
+
"model.layers.0.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 18 |
+
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 19 |
+
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 20 |
+
"model.layers.0.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 21 |
+
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 22 |
+
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 23 |
+
"model.layers.1.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 24 |
+
"model.layers.1.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 25 |
+
"model.layers.1.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 26 |
+
"model.layers.1.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 27 |
+
"model.layers.1.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 28 |
+
"model.layers.1.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 29 |
+
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 30 |
+
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 31 |
+
"model.layers.1.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 32 |
+
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 33 |
+
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 34 |
+
"model.layers.1.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 35 |
+
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 36 |
+
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 37 |
+
"model.layers.10.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 38 |
+
"model.layers.10.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 39 |
+
"model.layers.10.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 40 |
+
"model.layers.10.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 41 |
+
"model.layers.10.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 42 |
+
"model.layers.10.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 43 |
+
"model.layers.10.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 44 |
+
"model.layers.10.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 45 |
+
"model.layers.10.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 46 |
+
"model.layers.10.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 47 |
+
"model.layers.10.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 48 |
+
"model.layers.10.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 49 |
+
"model.layers.10.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 50 |
+
"model.layers.10.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 51 |
+
"model.layers.11.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 52 |
+
"model.layers.11.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 53 |
+
"model.layers.11.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 54 |
+
"model.layers.11.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 55 |
+
"model.layers.11.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 56 |
+
"model.layers.11.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 57 |
+
"model.layers.11.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 58 |
+
"model.layers.11.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 59 |
+
"model.layers.11.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 60 |
+
"model.layers.11.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 61 |
+
"model.layers.11.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 62 |
+
"model.layers.11.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 63 |
+
"model.layers.11.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 64 |
+
"model.layers.11.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 65 |
+
"model.layers.12.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 66 |
+
"model.layers.12.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 67 |
+
"model.layers.12.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 68 |
+
"model.layers.12.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 69 |
+
"model.layers.12.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 70 |
+
"model.layers.12.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 71 |
+
"model.layers.12.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 72 |
+
"model.layers.12.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 73 |
+
"model.layers.12.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 74 |
+
"model.layers.12.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 75 |
+
"model.layers.12.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 76 |
+
"model.layers.12.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 77 |
+
"model.layers.12.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 78 |
+
"model.layers.12.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 79 |
+
"model.layers.13.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 80 |
+
"model.layers.13.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 81 |
+
"model.layers.13.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 82 |
+
"model.layers.13.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 83 |
+
"model.layers.13.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 84 |
+
"model.layers.13.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 85 |
+
"model.layers.13.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 86 |
+
"model.layers.13.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 87 |
+
"model.layers.13.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 88 |
+
"model.layers.13.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 89 |
+
"model.layers.13.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 90 |
+
"model.layers.13.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 91 |
+
"model.layers.13.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 92 |
+
"model.layers.13.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 93 |
+
"model.layers.14.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 94 |
+
"model.layers.14.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 95 |
+
"model.layers.14.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 96 |
+
"model.layers.14.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 97 |
+
"model.layers.14.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 98 |
+
"model.layers.14.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 99 |
+
"model.layers.14.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 100 |
+
"model.layers.14.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 101 |
+
"model.layers.14.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 102 |
+
"model.layers.14.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 103 |
+
"model.layers.14.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 104 |
+
"model.layers.14.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 105 |
+
"model.layers.14.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 106 |
+
"model.layers.14.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 107 |
+
"model.layers.15.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 108 |
+
"model.layers.15.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 109 |
+
"model.layers.15.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 110 |
+
"model.layers.15.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 111 |
+
"model.layers.15.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 112 |
+
"model.layers.15.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 113 |
+
"model.layers.15.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 114 |
+
"model.layers.15.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 115 |
+
"model.layers.15.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 116 |
+
"model.layers.15.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 117 |
+
"model.layers.15.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 118 |
+
"model.layers.15.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 119 |
+
"model.layers.15.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 120 |
+
"model.layers.15.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 121 |
+
"model.layers.16.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 122 |
+
"model.layers.16.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 123 |
+
"model.layers.16.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 124 |
+
"model.layers.16.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 125 |
+
"model.layers.16.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 126 |
+
"model.layers.16.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 127 |
+
"model.layers.16.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 128 |
+
"model.layers.16.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 129 |
+
"model.layers.16.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 130 |
+
"model.layers.16.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 131 |
+
"model.layers.16.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 132 |
+
"model.layers.16.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 133 |
+
"model.layers.16.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 134 |
+
"model.layers.16.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 135 |
+
"model.layers.17.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 136 |
+
"model.layers.17.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 137 |
+
"model.layers.17.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 138 |
+
"model.layers.17.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 139 |
+
"model.layers.17.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 140 |
+
"model.layers.17.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 141 |
+
"model.layers.17.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 142 |
+
"model.layers.17.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 143 |
+
"model.layers.17.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 144 |
+
"model.layers.17.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 145 |
+
"model.layers.17.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 146 |
+
"model.layers.17.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 147 |
+
"model.layers.17.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 148 |
+
"model.layers.17.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 149 |
+
"model.layers.18.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 150 |
+
"model.layers.18.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 151 |
+
"model.layers.18.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 152 |
+
"model.layers.18.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 153 |
+
"model.layers.18.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 154 |
+
"model.layers.18.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 155 |
+
"model.layers.18.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 156 |
+
"model.layers.18.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 157 |
+
"model.layers.18.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 158 |
+
"model.layers.18.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 159 |
+
"model.layers.18.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 160 |
+
"model.layers.18.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 161 |
+
"model.layers.18.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 162 |
+
"model.layers.18.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 163 |
+
"model.layers.19.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 164 |
+
"model.layers.19.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 165 |
+
"model.layers.19.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 166 |
+
"model.layers.19.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 167 |
+
"model.layers.19.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 168 |
+
"model.layers.19.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 169 |
+
"model.layers.19.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 170 |
+
"model.layers.19.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 171 |
+
"model.layers.19.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 172 |
+
"model.layers.19.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 173 |
+
"model.layers.19.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 174 |
+
"model.layers.19.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 175 |
+
"model.layers.19.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 176 |
+
"model.layers.19.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 177 |
+
"model.layers.2.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 178 |
+
"model.layers.2.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 179 |
+
"model.layers.2.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 180 |
+
"model.layers.2.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 181 |
+
"model.layers.2.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 182 |
+
"model.layers.2.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 183 |
+
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 184 |
+
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 185 |
+
"model.layers.2.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 186 |
+
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 187 |
+
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 188 |
+
"model.layers.2.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 189 |
+
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 190 |
+
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 191 |
+
"model.layers.20.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 192 |
+
"model.layers.20.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 193 |
+
"model.layers.20.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 194 |
+
"model.layers.20.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 195 |
+
"model.layers.20.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 196 |
+
"model.layers.20.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 197 |
+
"model.layers.20.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 198 |
+
"model.layers.20.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 199 |
+
"model.layers.20.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 200 |
+
"model.layers.20.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 201 |
+
"model.layers.20.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 202 |
+
"model.layers.20.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 203 |
+
"model.layers.20.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 204 |
+
"model.layers.20.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 205 |
+
"model.layers.21.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 206 |
+
"model.layers.21.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 207 |
+
"model.layers.21.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 208 |
+
"model.layers.21.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 209 |
+
"model.layers.21.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 210 |
+
"model.layers.21.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 211 |
+
"model.layers.21.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 212 |
+
"model.layers.21.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 213 |
+
"model.layers.21.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 214 |
+
"model.layers.21.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 215 |
+
"model.layers.21.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 216 |
+
"model.layers.21.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 217 |
+
"model.layers.21.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 218 |
+
"model.layers.21.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 219 |
+
"model.layers.22.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 220 |
+
"model.layers.22.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 221 |
+
"model.layers.22.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 222 |
+
"model.layers.22.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 223 |
+
"model.layers.22.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 224 |
+
"model.layers.22.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 225 |
+
"model.layers.22.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 226 |
+
"model.layers.22.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 227 |
+
"model.layers.22.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 228 |
+
"model.layers.22.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 229 |
+
"model.layers.22.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 230 |
+
"model.layers.22.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 231 |
+
"model.layers.22.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 232 |
+
"model.layers.22.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 233 |
+
"model.layers.23.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 234 |
+
"model.layers.23.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 235 |
+
"model.layers.23.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 236 |
+
"model.layers.23.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 237 |
+
"model.layers.23.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 238 |
+
"model.layers.23.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 239 |
+
"model.layers.23.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 240 |
+
"model.layers.23.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 241 |
+
"model.layers.23.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 242 |
+
"model.layers.23.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 243 |
+
"model.layers.23.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 244 |
+
"model.layers.23.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 245 |
+
"model.layers.23.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 246 |
+
"model.layers.23.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 247 |
+
"model.layers.24.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 248 |
+
"model.layers.24.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 249 |
+
"model.layers.24.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 250 |
+
"model.layers.24.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 251 |
+
"model.layers.24.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 252 |
+
"model.layers.24.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 253 |
+
"model.layers.24.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 254 |
+
"model.layers.24.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 255 |
+
"model.layers.24.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 256 |
+
"model.layers.24.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 257 |
+
"model.layers.24.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 258 |
+
"model.layers.24.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 259 |
+
"model.layers.24.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 260 |
+
"model.layers.24.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 261 |
+
"model.layers.25.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 262 |
+
"model.layers.25.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 263 |
+
"model.layers.25.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 264 |
+
"model.layers.25.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 265 |
+
"model.layers.25.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 266 |
+
"model.layers.25.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 267 |
+
"model.layers.25.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 268 |
+
"model.layers.25.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 269 |
+
"model.layers.25.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 270 |
+
"model.layers.25.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 271 |
+
"model.layers.25.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 272 |
+
"model.layers.25.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 273 |
+
"model.layers.25.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 274 |
+
"model.layers.25.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 275 |
+
"model.layers.26.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 276 |
+
"model.layers.26.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 277 |
+
"model.layers.26.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 278 |
+
"model.layers.26.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 279 |
+
"model.layers.26.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 280 |
+
"model.layers.26.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 281 |
+
"model.layers.26.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 282 |
+
"model.layers.26.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 283 |
+
"model.layers.26.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 284 |
+
"model.layers.26.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 285 |
+
"model.layers.26.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 286 |
+
"model.layers.26.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 287 |
+
"model.layers.26.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 288 |
+
"model.layers.26.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 289 |
+
"model.layers.27.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 290 |
+
"model.layers.27.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 291 |
+
"model.layers.27.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 292 |
+
"model.layers.27.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 293 |
+
"model.layers.27.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 294 |
+
"model.layers.27.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 295 |
+
"model.layers.27.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 296 |
+
"model.layers.27.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 297 |
+
"model.layers.27.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 298 |
+
"model.layers.27.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 299 |
+
"model.layers.27.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 300 |
+
"model.layers.27.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 301 |
+
"model.layers.27.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 302 |
+
"model.layers.27.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 303 |
+
"model.layers.28.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 304 |
+
"model.layers.28.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 305 |
+
"model.layers.28.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 306 |
+
"model.layers.28.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 307 |
+
"model.layers.28.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 308 |
+
"model.layers.28.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 309 |
+
"model.layers.28.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 310 |
+
"model.layers.28.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 311 |
+
"model.layers.28.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 312 |
+
"model.layers.28.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 313 |
+
"model.layers.28.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 314 |
+
"model.layers.28.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 315 |
+
"model.layers.28.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 316 |
+
"model.layers.28.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 317 |
+
"model.layers.29.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 318 |
+
"model.layers.29.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 319 |
+
"model.layers.29.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 320 |
+
"model.layers.29.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 321 |
+
"model.layers.29.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 322 |
+
"model.layers.29.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 323 |
+
"model.layers.29.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 324 |
+
"model.layers.29.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 325 |
+
"model.layers.29.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 326 |
+
"model.layers.29.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 327 |
+
"model.layers.29.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 328 |
+
"model.layers.29.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 329 |
+
"model.layers.29.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 330 |
+
"model.layers.29.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 331 |
+
"model.layers.3.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 332 |
+
"model.layers.3.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 333 |
+
"model.layers.3.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 334 |
+
"model.layers.3.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 335 |
+
"model.layers.3.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 336 |
+
"model.layers.3.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 337 |
+
"model.layers.3.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 338 |
+
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 339 |
+
"model.layers.3.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 340 |
+
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 341 |
+
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 342 |
+
"model.layers.3.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 343 |
+
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 344 |
+
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 345 |
+
"model.layers.30.attention_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 346 |
+
"model.layers.30.feedforward_layernorm.weight": "model-00003-of-00004.safetensors",
|
| 347 |
+
"model.layers.30.mlp.act_fn.alpha_n": "model-00003-of-00004.safetensors",
|
| 348 |
+
"model.layers.30.mlp.act_fn.alpha_p": "model-00003-of-00004.safetensors",
|
| 349 |
+
"model.layers.30.mlp.act_fn.beta": "model-00003-of-00004.safetensors",
|
| 350 |
+
"model.layers.30.mlp.act_fn.eps": "model-00003-of-00004.safetensors",
|
| 351 |
+
"model.layers.30.mlp.down_proj.weight": "model-00003-of-00004.safetensors",
|
| 352 |
+
"model.layers.30.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 353 |
+
"model.layers.30.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 354 |
+
"model.layers.30.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 355 |
+
"model.layers.30.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 356 |
+
"model.layers.30.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 357 |
+
"model.layers.30.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 358 |
+
"model.layers.30.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 359 |
+
"model.layers.31.attention_layernorm.weight": "model-00004-of-00004.safetensors",
|
| 360 |
+
"model.layers.31.feedforward_layernorm.weight": "model-00004-of-00004.safetensors",
|
| 361 |
+
"model.layers.31.mlp.act_fn.alpha_n": "model-00004-of-00004.safetensors",
|
| 362 |
+
"model.layers.31.mlp.act_fn.alpha_p": "model-00004-of-00004.safetensors",
|
| 363 |
+
"model.layers.31.mlp.act_fn.beta": "model-00004-of-00004.safetensors",
|
| 364 |
+
"model.layers.31.mlp.act_fn.eps": "model-00004-of-00004.safetensors",
|
| 365 |
+
"model.layers.31.mlp.down_proj.weight": "model-00004-of-00004.safetensors",
|
| 366 |
+
"model.layers.31.mlp.up_proj.weight": "model-00003-of-00004.safetensors",
|
| 367 |
+
"model.layers.31.self_attn.k_norm.weight": "model-00003-of-00004.safetensors",
|
| 368 |
+
"model.layers.31.self_attn.k_proj.weight": "model-00003-of-00004.safetensors",
|
| 369 |
+
"model.layers.31.self_attn.o_proj.weight": "model-00003-of-00004.safetensors",
|
| 370 |
+
"model.layers.31.self_attn.q_norm.weight": "model-00003-of-00004.safetensors",
|
| 371 |
+
"model.layers.31.self_attn.q_proj.weight": "model-00003-of-00004.safetensors",
|
| 372 |
+
"model.layers.31.self_attn.v_proj.weight": "model-00003-of-00004.safetensors",
|
| 373 |
+
"model.layers.4.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 374 |
+
"model.layers.4.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 375 |
+
"model.layers.4.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 376 |
+
"model.layers.4.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 377 |
+
"model.layers.4.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 378 |
+
"model.layers.4.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 379 |
+
"model.layers.4.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 380 |
+
"model.layers.4.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 381 |
+
"model.layers.4.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 382 |
+
"model.layers.4.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 383 |
+
"model.layers.4.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 384 |
+
"model.layers.4.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 385 |
+
"model.layers.4.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 386 |
+
"model.layers.4.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 387 |
+
"model.layers.5.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 388 |
+
"model.layers.5.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 389 |
+
"model.layers.5.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 390 |
+
"model.layers.5.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 391 |
+
"model.layers.5.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 392 |
+
"model.layers.5.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 393 |
+
"model.layers.5.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 394 |
+
"model.layers.5.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 395 |
+
"model.layers.5.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 396 |
+
"model.layers.5.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 397 |
+
"model.layers.5.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 398 |
+
"model.layers.5.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 399 |
+
"model.layers.5.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 400 |
+
"model.layers.5.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 401 |
+
"model.layers.6.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 402 |
+
"model.layers.6.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 403 |
+
"model.layers.6.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 404 |
+
"model.layers.6.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 405 |
+
"model.layers.6.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 406 |
+
"model.layers.6.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 407 |
+
"model.layers.6.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 408 |
+
"model.layers.6.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 409 |
+
"model.layers.6.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 410 |
+
"model.layers.6.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 411 |
+
"model.layers.6.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 412 |
+
"model.layers.6.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 413 |
+
"model.layers.6.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 414 |
+
"model.layers.6.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 415 |
+
"model.layers.7.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 416 |
+
"model.layers.7.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 417 |
+
"model.layers.7.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 418 |
+
"model.layers.7.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 419 |
+
"model.layers.7.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 420 |
+
"model.layers.7.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 421 |
+
"model.layers.7.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 422 |
+
"model.layers.7.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 423 |
+
"model.layers.7.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 424 |
+
"model.layers.7.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 425 |
+
"model.layers.7.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 426 |
+
"model.layers.7.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 427 |
+
"model.layers.7.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 428 |
+
"model.layers.7.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 429 |
+
"model.layers.8.attention_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 430 |
+
"model.layers.8.feedforward_layernorm.weight": "model-00001-of-00004.safetensors",
|
| 431 |
+
"model.layers.8.mlp.act_fn.alpha_n": "model-00001-of-00004.safetensors",
|
| 432 |
+
"model.layers.8.mlp.act_fn.alpha_p": "model-00001-of-00004.safetensors",
|
| 433 |
+
"model.layers.8.mlp.act_fn.beta": "model-00001-of-00004.safetensors",
|
| 434 |
+
"model.layers.8.mlp.act_fn.eps": "model-00001-of-00004.safetensors",
|
| 435 |
+
"model.layers.8.mlp.down_proj.weight": "model-00001-of-00004.safetensors",
|
| 436 |
+
"model.layers.8.mlp.up_proj.weight": "model-00001-of-00004.safetensors",
|
| 437 |
+
"model.layers.8.self_attn.k_norm.weight": "model-00001-of-00004.safetensors",
|
| 438 |
+
"model.layers.8.self_attn.k_proj.weight": "model-00001-of-00004.safetensors",
|
| 439 |
+
"model.layers.8.self_attn.o_proj.weight": "model-00001-of-00004.safetensors",
|
| 440 |
+
"model.layers.8.self_attn.q_norm.weight": "model-00001-of-00004.safetensors",
|
| 441 |
+
"model.layers.8.self_attn.q_proj.weight": "model-00001-of-00004.safetensors",
|
| 442 |
+
"model.layers.8.self_attn.v_proj.weight": "model-00001-of-00004.safetensors",
|
| 443 |
+
"model.layers.9.attention_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 444 |
+
"model.layers.9.feedforward_layernorm.weight": "model-00002-of-00004.safetensors",
|
| 445 |
+
"model.layers.9.mlp.act_fn.alpha_n": "model-00002-of-00004.safetensors",
|
| 446 |
+
"model.layers.9.mlp.act_fn.alpha_p": "model-00002-of-00004.safetensors",
|
| 447 |
+
"model.layers.9.mlp.act_fn.beta": "model-00002-of-00004.safetensors",
|
| 448 |
+
"model.layers.9.mlp.act_fn.eps": "model-00002-of-00004.safetensors",
|
| 449 |
+
"model.layers.9.mlp.down_proj.weight": "model-00002-of-00004.safetensors",
|
| 450 |
+
"model.layers.9.mlp.up_proj.weight": "model-00002-of-00004.safetensors",
|
| 451 |
+
"model.layers.9.self_attn.k_norm.weight": "model-00002-of-00004.safetensors",
|
| 452 |
+
"model.layers.9.self_attn.k_proj.weight": "model-00002-of-00004.safetensors",
|
| 453 |
+
"model.layers.9.self_attn.o_proj.weight": "model-00002-of-00004.safetensors",
|
| 454 |
+
"model.layers.9.self_attn.q_norm.weight": "model-00002-of-00004.safetensors",
|
| 455 |
+
"model.layers.9.self_attn.q_proj.weight": "model-00002-of-00004.safetensors",
|
| 456 |
+
"model.layers.9.self_attn.v_proj.weight": "model-00002-of-00004.safetensors",
|
| 457 |
+
"model.norm.weight": "model-00004-of-00004.safetensors"
|
| 458 |
+
}
|
| 459 |
+
}
|
sea-helm_scores_05_Feb_1pm.png
ADDED

|
Git LFS Details
|
special_tokens_map.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"bos_token": {
|
| 3 |
+
"content": "<s>",
|
| 4 |
+
"lstrip": false,
|
| 5 |
+
"normalized": false,
|
| 6 |
+
"rstrip": false,
|
| 7 |
+
"single_word": false
|
| 8 |
+
},
|
| 9 |
+
"eos_token": {
|
| 10 |
+
"content": "<|assistant_end|>",
|
| 11 |
+
"lstrip": false,
|
| 12 |
+
"normalized": false,
|
| 13 |
+
"rstrip": false,
|
| 14 |
+
"single_word": false
|
| 15 |
+
},
|
| 16 |
+
"pad_token": {
|
| 17 |
+
"content": "<pad>",
|
| 18 |
+
"lstrip": false,
|
| 19 |
+
"normalized": false,
|
| 20 |
+
"rstrip": false,
|
| 21 |
+
"single_word": false
|
| 22 |
+
},
|
| 23 |
+
"unk_token": {
|
| 24 |
+
"content": "<unk>",
|
| 25 |
+
"lstrip": false,
|
| 26 |
+
"normalized": false,
|
| 27 |
+
"rstrip": false,
|
| 28 |
+
"single_word": false
|
| 29 |
+
}
|
| 30 |
+
}
|
tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:010095abf1dc6f52d4867584e7b3f0d4eece854593ae310220ec7782dd1b0a66
|
| 3 |
+
size 17078474
|
tokenizer_config.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|