

Add files using upload-large-folder tool
Browse files- README.md +104 -0
- code/gr00t_p150/__init__.py +17 -0
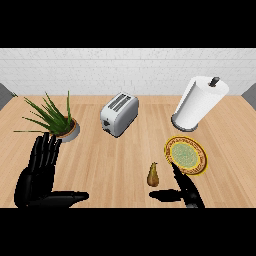
- code/gr00t_p150/demo/n15/frames/ego_view_t0.png +0 -0
- code/models/common/utility_functions.py +1266 -0
- code/models/experimental/gr00t/__init__.py +0 -0
- code/models/experimental/gr00t/reference/__init__.py +4 -0
- code/models/experimental/gr00t/reference/action_head.py +1093 -0
- code/models/experimental/gr00t/reference/model.py +524 -0
- code/models/experimental/gr00t/reference/qwen3vl_vision.py +381 -0
- code/models/experimental/gr00t/reference/sampler.py +239 -0
- code/models/experimental/gr00t/tests/__init__.py +2 -0
- code/scripts/bench_http.py +127 -0
- code/scripts/download_weights.sh +21 -0
- image/blobs/sha256/0b8bee58599dd50ebcc83819b473ea1eb586d722ee381103cbef6f32a1e1c780 +1 -0
- image/blobs/sha256/1d1bc46ff8841de85f975ecd5e1203308bc2d6faf331d4aa9427d032f4fcc935 +1 -0
- image/blobs/sha256/2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac +0 -0
- image/blobs/sha256/370bb95b39281a3ded169a86bb7972b898b349503342e491db98470ce5b1af87 +1 -0
- image/blobs/sha256/3ac026cc87fbebb2f96c2cffe83a97e3c0593da7fd6dd97bbdbd84f934ab0751 +1 -0
- image/blobs/sha256/443501bd3b7afce579bf743eeedd64809886653c29a9d7125614e8451cd61a7b +1 -0
- image/blobs/sha256/4568a8cf3754ec6555dfd72c99498a8a6d81c756cb843f869c32db42000f4f07 +1 -0
- image/blobs/sha256/4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c +0 -0
- image/blobs/sha256/514ee738d1ef907136a924293b5033e43461f7b14c90428f3fdaf082d4bca600 +1 -0
- image/blobs/sha256/5628e13ce208b83d793af15fa41c28d1702e7a43e27c8c72944442d01e959a71 +1 -0
- image/blobs/sha256/5f1f271cd6c23c85e2bbe2b1601abb2143184d033d1e93853029f959402b64c3 +1 -0
- image/blobs/sha256/5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef +0 -0
- image/blobs/sha256/60d99486d4e943a3a234fd3001d031f22c99fa65f933b048f3bc272051148d81 +1 -0
- image/blobs/sha256/6c3dd1840f3cb732d89c764a387e4742bffa52990892993301bc49819ef39be5 +1 -0
- image/blobs/sha256/746d6df035900c8d4ad4ad98c30b5cd4050eb272fb1ef5d19d0330c27a38f18e +1 -0
- image/blobs/sha256/75df73761a6599a1f76198e180ea6ea4845564fd787cdb1a85bb96fc9490e4e2 +1 -0
- image/blobs/sha256/7da1668187b2357115d5ede196f3848c315c32695c103c2991fe8d09bcea1fb5 +1 -0
- image/blobs/sha256/8836ac07b9ab1d87c8f9759bcc86240cb196a2de00ed7efbd06d8b91b25cd4d9 +1 -0
- image/blobs/sha256/8b2c5066cae93333c326dc28469add1060522ce7553473cc67a464531afd31e9 +1 -0
- image/blobs/sha256/92387b8093f65f78b3f65ac14f4c1fface25891d185815c29ca124a9cacb5a9e +1 -0
- image/blobs/sha256/95a774a140ea0bdf3c88f347e5a26834bef4d22301cd5300cc925c9cd0a728dd +1 -0
- image/blobs/sha256/9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623 +0 -0
- image/blobs/sha256/a2491fe22925746efefa576db546cd62a39b33b9378a7205bb119d6f5a2d06b4 +1 -0
- image/blobs/sha256/bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed +0 -0
- image/blobs/sha256/ceda6a792461a030c40385b7e455fcfd3b56ab238855e2af19f623ff962e325a +1 -0
- image/blobs/sha256/cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c +0 -0
- image/blobs/sha256/dfdf267c677095544bf7ac50b1a0f6678eb93662a45aeb30f77f976ac4ace6de +1 -0
- image/blobs/sha256/e0c4814cde1d85e88a2dd6121d00c886b5b04f8206434ec4a0e14aca6a8a1769 +1 -0
- image/blobs/sha256/e13438a9103dc3ce3126a1a1711007fdf9c31bfabfeadeae010327901fc39b88 +1 -0
- image/blobs/sha256/e8d4979d8340f3b13fb626dab5702018f87bd5b44295909f6fdd0c2734a7910f +1 -0
- image/blobs/sha256/ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8 +0 -0
- image/index.json +1 -0
- image/manifest.json +1 -0
- image/oci-layout +1 -0
- image/repositories +1 -0
- requirements.lock +87 -0
- tt_kernel_manifest.json +138 -0
README.md
ADDED
|
@@ -0,0 +1,104 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
tags:
|
| 3 |
+
- blackhole
|
| 4 |
+
- p150
|
| 5 |
+
- tt-dit-server
|
| 6 |
+
- tt-model-cache
|
| 7 |
+
- tt-model-container
|
| 8 |
+
---
|
| 9 |
+
|
| 10 |
+
# gr00t-n1.5-3b-p150
|
| 11 |
+
|
| 12 |
+
NVIDIA Isaac GR00T N1.5 (3B vision-language-action policy: SigLIP ViT (224², 256 tokens/image) → linear projector → 12-layer Qwen3-1.7B backbone → 4-block VL self-attention → 16-block cross/self AdaLN DiT, 4 Euler flow-matching steps) running on one Tenstorrent Blackhole p150a via tt-nn: one camera frame + proprioceptive state + a task instruction in, a 16-step chunk of GR1 arm/hand joint targets out. Stage-1 release: every op is a TTNN op replayed from four Metal traces (DiT block matmul weights bfp8, everything else bf16); the persistent-megakernel denoise is in progress and not in this image.
|
| 13 |
+
Weights: [nvidia/GR00T-N1.5-3B](https://huggingface.co/nvidia/GR00T-N1.5-3B) (NVIDIA License, non-commercial) · Paper: [arXiv:2503.14734](https://arxiv.org/abs/2503.14734) (GR00T N1 report; the N1.5 changes are described in the [N1.5 model card](https://huggingface.co/nvidia/GR00T-N1.5-3B)) · Upstream code: [NVIDIA/Isaac-GR00T](https://github.com/NVIDIA/Isaac-GR00T) (tag `n1.5-release`) · Port: `code/models/experimental/gr00t` in this repo (tt-metal-tree layout, frozen snapshot `5dc0517ee3b`) + the policy server `code/gr00t_p150`
|
| 14 |
+
|
| 15 |
+
Runs on **p150** (mesh `P150`).
|
| 16 |
+
|
| 17 |
+
Packaged and published with [tt-model-manager](https://github.com/tenstorrent/tt-model-manager) 0.1.0 (manifest schema 5.1).
|
| 18 |
+
|
| 19 |
+
## Quickstart
|
| 20 |
+
|
| 21 |
+
```bash
|
| 22 |
+
tt-model pull changh95/GR00T-N1.5-3B-p150 --with-weights
|
| 23 |
+
tt-model serve changh95/GR00T-N1.5-3B-p150
|
| 24 |
+
```
|
| 25 |
+
|
| 26 |
+
`pull --with-weights` downloads the Docker image and the [`nvidia/GR00T-N1.5-3B`](https://huggingface.co/nvidia/GR00T-N1.5-3B) weights at `869830fc749c35f34771aa5209f923ac57e4564e` (into your HF cache; they are not in the image). `serve` starts the model's own HTTP server on port 20000 (or the next free port, if that one is busy); the first start compiles kernels for your device, which takes several minutes, and the server is ready when it logs `Application startup complete`.
|
| 27 |
+
|
| 28 |
+
### Run with tt-cli
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
tt serve changh95/GR00T-N1.5-3B-p150
|
| 32 |
+
python3 - <<'EOF'
|
| 33 |
+
import base64, json
|
| 34 |
+
body = json.load(open("media/demo_observation.json")) # GR1 PickNPlace demo step: raw joint state + instruction
|
| 35 |
+
body.pop("_note", None)
|
| 36 |
+
body["images"] = {"ego_view": base64.b64encode(open("media/demo_ego_view.png", "rb").read()).decode()}
|
| 37 |
+
json.dump(body, open("req.json", "w"))
|
| 38 |
+
EOF
|
| 39 |
+
curl -s localhost:20000/predict -H 'Content-Type: application/json' -d @req.json
|
| 40 |
+
tt model stop changh95/GR00T-N1.5-3B-p150
|
| 41 |
+
```
|
| 42 |
+
|
| 43 |
+
- `POST /predict`: `images` (`{"ego_view": <base64 PNG/JPEG>}` — the one GR1 camera; any size with sides in 64–4096 px, the server applies the checkpoint's own eval chain: 0.95 centre crop → bilinear 224×224 → Eagle2.5 normalisation), `state` (`{group: [[floats]]}`: `left_arm` 7, `right_arm` 7, `left_hand` 6, `right_hand` 6 — raw joint values, one time step), `instruction` (task text, ≤ 102 BPE tokens); optional `embodiment` (`gr1`, the only layout in this image), `seed` (initial flow-matching noise; default 0 = the deployed policy's seed → deterministic) or `noise` (an explicit `[16][32]` initial noise), `state_dtype` (`float64` default, as the GR1 dataset), `return_normalized` (also return the model-space chunk).
|
| 44 |
+
- `GET /health`, `GET /info` (the full input/output contract, weights/tree provenance, warm-up latency and fidelity), `GET /demo` (the shipped demo request and its fp32 reference actions).
|
| 45 |
+
|
| 46 |
+
### Response
|
| 47 |
+
|
| 48 |
+
```json
|
| 49 |
+
{"actions": {"left_arm": [[0.0069, 0.2107, 0.0483, -1.8136, -0.1264, -0.0548, 0.0147], "... 16 steps"],
|
| 50 |
+
"right_arm": [[-0.0177, -0.1731, 0.3702, -1.7429, 0.4968, -0.0567, 0.9849], "..."],
|
| 51 |
+
"left_hand": [[0.0081, 0.0155, 0.0033, 0.0064, 0.0169, 0.0438], "..."],
|
| 52 |
+
"right_hand": [[-1.4880, -1.4915, -1.4781, -1.4810, -2.9609, 2.9904], "..."]},
|
| 53 |
+
"action_horizon": 16, "action_keys": ["left_arm", "right_arm", "left_hand", "right_hand"], "action_dims": {"left_arm": 7, "right_arm": 7, "left_hand": 6, "right_hand": 6},
|
| 54 |
+
"normalized": false, "embodiment": "gr1", "embodiment_id": 24, "version": "n15", "model": "GR00T-N1.5-3B-p150", "layout": "gr1",
|
| 55 |
+
"images": {"ego_view": {"frames": 1, "received_hw": [256, 256]}}, "seq_len": 296, "prompt_tokens": 14, "state_dtype": "float64",
|
| 56 |
+
"noise_source": "client", "seed": null,
|
| 57 |
+
"timing_ms": {"decode": 1.5, "encode": 2.6, "device": 43.0, "decode_actions": 0.1, "total": 47.2}}
|
| 58 |
+
```
|
| 59 |
+
|
| 60 |
+
- `actions` are **physical, un-normalised** joint targets (radians) in the GR1 arms-and-hands action space of the checkpoint's `experiment_cfg/metadata.json` statistics, 16 steps × [7, 7, 6, 6] dims — what `Gr00tPolicy.get_action` returns for this checkpoint; the values above are abridged from the shipped demo request (`GET /demo`) with its golden initial noise. `seq_len` is the LLM prompt length the request produced (296 for the demo; padded to 384 on device). `timing_ms.device` covers input upload, the four trace replays and the action readback; `total` is the whole handler.
|
| 61 |
+
|
| 62 |
+
### Demo
|
| 63 |
+
|
| 64 |
+
| Input (`media/demo_ego_view.png`, GR1 sim `robot_sim.PickNPlace` traj 0 / step 100, 256×256) | Instruction | p150a actions vs the fp32 reference (`media/demo_actions.png`) |
|
| 65 |
+
|:---:|:---|:---:|
|
| 66 |
+
|  | `pick the pear from the counter and place it in the plate` |  |
|
| 67 |
+
|
| 68 |
+
### Accuracy and speed
|
| 69 |
+
|
| 70 |
+
| Metric | Value |
|
| 71 |
+
|---|---:|
|
| 72 |
+
| Action chunk vs the fp32 reference (`Gr00tPolicy`, same observation, same initial noise) | PCC `left_arm` 0.99995 · `right_arm` 0.99997 · `right_hand` 0.99999 (gates 0.9999; max\|d\| 0.021 / 0.017 / 0.029 rad) · `left_hand` max\|d\| 0.018 rad ≤ 0.046 (PCC 0.943 reported only: the golden chunk is near-constant there, spread 0.1 rad — NVIDIA's own bf16 GPU path scores 0.952) · normalised chunk `action_pred_normalized` 0.99998 (max\|d\| 0.014 ≤ 0.027) |
|
| 73 |
+
| Intermediate taps vs the fp32 reference (untraced path from pixels, 57 gated taps + determinism row) | **58/58 rows pass**; tightest: `vit_block_first` 0.99994 (gate 0.9999), `backbone_features` 0.99586 (0.995), `vl_self_attention_out` 0.99119 (0.991), `vit_post_ln` 0.99506 (0.993) |
|
| 74 |
+
| Traced == untraced, determinism, stale state | traced `action_pred` / `backbone_features` / hoisted K,V bit-equal to the untraced run; 5 trace replays bit-identical; mutated inputs (`n_text` > L_max, other shapes) refused before any device write; A→B→A→B alternating observations on one captured model pass |
|
| 75 |
+
| Inference on p150a (port benchmark, warm, batch 1, one 224² image, LLM S 296→384, median of 50; `benchmarks/results/e2e_stage1_n15.json`) | **43.4 ms end-to-end** (p90 44.1) = host encode 1.5 + upload 3.8 + 4 traces 37.8 (vision 8.7 · LLM 8.7 · adapter 4.5 · denoise 16.0) + readback 0.1 + decode 0.2 |
|
| 76 |
+
| Served over HTTP by this image (`tt-model serve`, warm, batch 1, the demo request, 10 warm-ups + 50 timed; `scripts/bench_http.py`) | **42.4 ms device · 45.4 ms server-side** (medians; p90 43.2 / 49.2; min 41.7 / 44.5) = image decode 1.1 + host encode 1.6 + device 42.4 (upload, 4 trace replays, readback) + un-normalise 0.1; 47.6 ms client wall on the same host (p90 51.8). Under a heavily loaded host (two concurrent tt-metal builds, load average 16–110) the same loop read 44.3 / 44.5 ms device and 53.6 / 58.1 ms server-side medians with p90s of 55 / 91–97 ms — the host-side stages, not the device, absorb the contention. The served actions are bit-identical to the port's device test and to the host run |
|
| 77 |
+
| Same policy on an RTX 5090 (same host, NVIDIA's unmodified `Gr00tPolicy`, eager PyTorch bf16 autocast + flash-attn 2, batch 1) | `get_action` e2e **58.0 ms** (preprocessing 2.2, model 55.4 = backbone 20.8 + action head 34.6) → the p150a is 1.34× faster end-to-end (43.4 vs 58.0) and 1.33× on the model (41.7 device vs 55.4); NVIDIA's N1.5 README quotes 47.9 ms on an H100 (backbone 23.2 + head 4 × 6.2) |
|
| 78 |
+
|
| 79 |
+
### Caveats
|
| 80 |
+
|
| 81 |
+
- **Stage-1 path.** Vision / LLM / adapter / denoise are TTNN ops captured in four Metal traces; DiT block matmul weights are bfp8_b, everything else bf16 (`mixed_dit`). The persistent-megakernel denoise (Stage 2) is at rung K1 — its weight-streaming kernel measures 464 GB/s bf16 / 414 GB/s bfp8 (90.6 % of DRAM peak) on the full DiT block set — and is **not** in this image.
|
| 82 |
+
- **One embodiment, one layout.** The image is built for GR1 arms-and-hands (`gr1`, embodiment slot 24, one `ego_view` camera, ≤ 102 text tokens → LLM sequence padded to 384); other embodiments, cameras or longer instructions are refused with 400, nothing is truncated. Batch 1; requests are serialised on one lock.
|
| 83 |
+
- **Noise is seeded** (seed 0, as the deployed policy); pass `seed` or `noise` for another draw. The reference noise of the shipped demo is not seed-reproducible, so the smoke test sends it as `noise`. Outputs are the base checkpoint's actions for the GR1 sim data config — a real robot needs NVIDIA's post-training.
|
| 84 |
+
- Not an OpenAI-compatible API; `GET /v1/models` is a stub so the tt-model ready card does not 404.
|
| 85 |
+
- Validated on tt-metal main `668c2907575` (`v0.79.0-dev20260914-1`), single p150a only, with this exact image (`tt-model serve` → smoke test → 50-request benchmark → `tt-model stop`, three boots). **First boot is cold**: the checkpoint is converted into the port's device layout under `~/.cache/tt-model/gr00t-n1.5-3b-p150/weights` (6.4 GB, 9 s) and the kernels of the four traces are JIT-compiled into `…/cache` (411 MB, ~87 s incl. trace capture) — `tt-model serve` reported READY after 1 min 43 s; the next boots reused both caches and were ready in 20 s (loaded host) and 9.7 s (quiet host). Every boot re-checks the warm-up actions against the shipped fp32 reference (PCC 0.999982 here) and refuses to serve below 0.999.
|
| 86 |
+
- GPU comparison: the RTX 5090 row is NVIDIA's unmodified `Gr00tPolicy` path (`Isaac-GR00T` `n1.5-release`, torch 2.7.1+cu128, transformers 4.51.3, flash-attn 2.8.3), best median of 3 × (20 warm-ups + 20 timed calls), GPU idle, no `torch.compile` / TensorRT; the p150a rows are the Stage-1 trace path incl. upload and readback. p150a power was not measured, so no efficiency comparison is made. Full table: [`GPU_COMPARISON.md`](GPU_COMPARISON.md).
|
| 87 |
+
|
| 88 |
+
### Licensing
|
| 89 |
+
|
| 90 |
+
- Weights: [nvidia/GR00T-N1.5-3B](https://huggingface.co/nvidia/GR00T-N1.5-3B), **NVIDIA License** — use limited to research or evaluation (non-commercial), redistribution only under the same licence (copy in [`LICENSE`](LICENSE)). Not redistributed here; `tt-model serve` fetches the pinned snapshot into your HF cache.
|
| 91 |
+
- Tokenizer files under `code/gr00t_p150/assets/tokenizer/n15/` (Qwen2 BPE + Eagle2.5 special tokens) are copied from [NVIDIA/Isaac-GR00T `n1.5-release`](https://github.com/NVIDIA/Isaac-GR00T/tree/n1.5-release) (Apache-2.0).
|
| 92 |
+
- Port and serving code (`code/models/experimental/gr00t`, `code/gr00t_p150`, `code/scripts`): Apache-2.0 (SPDX headers), © 2026 Tenstorrent; as a derivative work of the weights it is distributed here under the same non-commercial use limitation (NVIDIA License §3.2). tt-metal / tt-nn: Apache-2.0.
|
| 93 |
+
- Demo frame and state (`media/`): one step of the GR1 `robot_sim.PickNPlace` demo data shipped with Isaac-GR00T.
|
| 94 |
+
|
| 95 |
+
## Provenance
|
| 96 |
+
|
| 97 |
+
The exact sources the image was built from — `code/` in this repo is byte-identical to the model code inside the image:
|
| 98 |
+
|
| 99 |
+
| component | built from |
|
| 100 |
+
| --- | --- |
|
| 101 |
+
| tt-metal | [`668c290757550588d0ce46b180c344a462a2aaf5`](https://github.com/tenstorrent/tt-metal/commit/668c290757550588d0ce46b180c344a462a2aaf5) |
|
| 102 |
+
| `code/` digest | `a2771515bca98527` (sha256, first 16 hex digits) |
|
| 103 |
+
| built | 2026-09-14T15:17:00+00:00 by tt-model 0.1.0 |
|
| 104 |
+
|
code/gr00t_p150/__init__.py
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
"""``gr00t_p150``: the HTTP policy server shipped by the ``changh95/GR00T-N1.5-3B-p150`` and
|
| 4 |
+
``changh95/GR00T-N1.6-3B-p150`` tt-model container packages.
|
| 5 |
+
|
| 6 |
+
The device port itself lives in ``models.experimental.gr00t`` (tt-metal tree layout, shipped under ``code/models/``
|
| 7 |
+
in the same repos); this package only adds the FastAPI server (:mod:`gr00t_p150.server.app`), its request /
|
| 8 |
+
response schemas (:mod:`gr00t_p150.server.schemas`), a stdlib-only smoke test (:mod:`gr00t_p150.server.smoke_test`),
|
| 9 |
+
the canonical demo observations of both versions (``demo/<version>/``) and the vendored Qwen2 tokenizer files the
|
| 10 |
+
port's prompt builder needs (``assets/tokenizer/<version>/``).
|
| 11 |
+
|
| 12 |
+
Importing this package has no side effects.
|
| 13 |
+
"""
|
| 14 |
+
|
| 15 |
+
__version__ = "0.1.0"
|
| 16 |
+
|
| 17 |
+
__all__ = ["__version__"]
|
code/gr00t_p150/demo/n15/frames/ego_view_t0.png
ADDED
|
code/models/common/utility_functions.py
ADDED
|
@@ -0,0 +1,1266 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2023 Tenstorrent USA, Inc.
|
| 2 |
+
|
| 3 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 4 |
+
|
| 5 |
+
import math
|
| 6 |
+
import os
|
| 7 |
+
import struct
|
| 8 |
+
import time
|
| 9 |
+
from typing import Union
|
| 10 |
+
|
| 11 |
+
import numpy as np
|
| 12 |
+
import torch
|
| 13 |
+
from loguru import logger
|
| 14 |
+
from ttnn.device import Arch
|
| 15 |
+
from typing_extensions import deprecated
|
| 16 |
+
|
| 17 |
+
import ttnn
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
def get_mesh_device():
|
| 21 |
+
"""Fixture to provide mesh device configuration."""
|
| 22 |
+
mesh_device = os.environ.get("MESH_DEVICE", "N150")
|
| 23 |
+
mesh_config = {
|
| 24 |
+
"N150": (1, 1),
|
| 25 |
+
"N300": (2, 1),
|
| 26 |
+
"T3K": (8, 1),
|
| 27 |
+
"TG": (8, 4),
|
| 28 |
+
}.get(mesh_device, (ttnn.get_num_devices(), 1))
|
| 29 |
+
return mesh_config
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
### Math operations ###
|
| 33 |
+
def _nearest_32(x):
|
| 34 |
+
return math.ceil(x / 32) * 32
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
def nearest_32(
|
| 38 |
+
x,
|
| 39 |
+
): # needs refctoring; to match alias called in some scripts (e.g. test_padding_test in unit tests)
|
| 40 |
+
return _nearest_32(x)
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def _nearest_y(x, y):
|
| 44 |
+
return math.ceil(x / y) * y
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def nearest_y(x, y):
|
| 48 |
+
return _nearest_y(x, y)
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def divup(a, b):
|
| 52 |
+
return (a + b - 1) // b
|
| 53 |
+
|
| 54 |
+
|
| 55 |
+
def roundup(a, b):
|
| 56 |
+
result = divup(a, b) * b
|
| 57 |
+
return result
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
def roundup32(a):
|
| 61 |
+
return roundup(a, 32)
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def float_to_bits(x):
|
| 65 |
+
s = struct.pack(">f", x)
|
| 66 |
+
return struct.unpack(">l", s)[0]
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
def torch_random(shape, low, high, dtype):
|
| 70 |
+
if dtype in [torch.int64, torch.int32, torch.int16, torch.int8]:
|
| 71 |
+
return torch.randint(low, high, shape, dtype=dtype)
|
| 72 |
+
return torch.zeros(shape, dtype=dtype).uniform_(low, high)
|
| 73 |
+
|
| 74 |
+
|
| 75 |
+
def torch_random_with_zeros(shape, low, high, dtype, zero_fraction=0.1):
|
| 76 |
+
total_elements = torch.prod(torch.tensor(shape)).item()
|
| 77 |
+
num_zeros = int(total_elements * zero_fraction)
|
| 78 |
+
num_random = total_elements - num_zeros
|
| 79 |
+
|
| 80 |
+
# Generate random values between low and high
|
| 81 |
+
random_values = torch.empty(num_random).uniform_(low, high)
|
| 82 |
+
zeros = torch.zeros(num_zeros)
|
| 83 |
+
|
| 84 |
+
# Combine zeros and random values
|
| 85 |
+
combined = torch.cat([zeros, random_values])
|
| 86 |
+
|
| 87 |
+
# Shuffle the tensor
|
| 88 |
+
shuffled = combined[torch.randperm(combined.size(0))]
|
| 89 |
+
|
| 90 |
+
# Reshape to the desired shape. Tensor.to is not in-place, so return the converted tensor.
|
| 91 |
+
result_tensor = shuffled.view(shape)
|
| 92 |
+
return result_tensor.to(dtype)
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
### Profiling ###
|
| 96 |
+
class Profiler:
|
| 97 |
+
def __init__(self):
|
| 98 |
+
self.start_times = dict()
|
| 99 |
+
self.times = dict()
|
| 100 |
+
self.disabled = False
|
| 101 |
+
|
| 102 |
+
def clear(self):
|
| 103 |
+
self.start_times = dict()
|
| 104 |
+
self.times = dict()
|
| 105 |
+
self.disabled = False
|
| 106 |
+
|
| 107 |
+
def enable(self):
|
| 108 |
+
self.disabled = False
|
| 109 |
+
|
| 110 |
+
def disable(self):
|
| 111 |
+
self.disabled = True
|
| 112 |
+
|
| 113 |
+
def start(self, key, force_enable=False):
|
| 114 |
+
if self.disabled and not force_enable:
|
| 115 |
+
return
|
| 116 |
+
|
| 117 |
+
self.start_times[key] = time.time()
|
| 118 |
+
|
| 119 |
+
def end(self, key, PERF_CNT=1, force_enable=False):
|
| 120 |
+
if self.disabled and not force_enable:
|
| 121 |
+
return
|
| 122 |
+
|
| 123 |
+
if key not in self.start_times:
|
| 124 |
+
return
|
| 125 |
+
|
| 126 |
+
diff = time.time() - self.start_times[key]
|
| 127 |
+
|
| 128 |
+
if key not in self.times:
|
| 129 |
+
self.times[key] = []
|
| 130 |
+
|
| 131 |
+
self.times[key].append(diff / PERF_CNT)
|
| 132 |
+
|
| 133 |
+
def get(self, key):
|
| 134 |
+
if key not in self.times:
|
| 135 |
+
return 0
|
| 136 |
+
|
| 137 |
+
return sum(self.times[key]) / len(self.times[key])
|
| 138 |
+
|
| 139 |
+
def print(self, units="s"):
|
| 140 |
+
for key in self.times:
|
| 141 |
+
average = self.get(key)
|
| 142 |
+
if units == "s":
|
| 143 |
+
pass
|
| 144 |
+
elif units == "ms":
|
| 145 |
+
average *= 1000
|
| 146 |
+
elif units == "us":
|
| 147 |
+
average *= 1000000
|
| 148 |
+
elif units == "ns":
|
| 149 |
+
average *= 1000000000
|
| 150 |
+
else:
|
| 151 |
+
raise ValueError(f"Invalid units: {units}")
|
| 152 |
+
print(f"{key}: {average:.3f}{units}")
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
profiler = Profiler()
|
| 156 |
+
|
| 157 |
+
|
| 158 |
+
### Turn flags on/off ###
|
| 159 |
+
def enable_memory_reports():
|
| 160 |
+
"""
|
| 161 |
+
Enables generating reports of memory allocation statistics in .reports/tt_metal dir
|
| 162 |
+
"""
|
| 163 |
+
return ttnn.device.EnableMemoryReports()
|
| 164 |
+
|
| 165 |
+
|
| 166 |
+
def disable_memory_reports():
|
| 167 |
+
"""
|
| 168 |
+
Disables generating reports of memory allocation statistics
|
| 169 |
+
"""
|
| 170 |
+
return ttnn.device.DisableMemoryReports()
|
| 171 |
+
|
| 172 |
+
|
| 173 |
+
### Tensor conversion ###
|
| 174 |
+
def torch2tt_tensor(
|
| 175 |
+
py_tensor: torch.Tensor,
|
| 176 |
+
tt_device,
|
| 177 |
+
tt_layout=ttnn.TILE_LAYOUT,
|
| 178 |
+
tt_memory_config=ttnn.MemoryConfig(ttnn.TensorMemoryLayout.INTERLEAVED),
|
| 179 |
+
tt_dtype=ttnn.bfloat16,
|
| 180 |
+
):
|
| 181 |
+
size = list(py_tensor.size())
|
| 182 |
+
|
| 183 |
+
while len(size) < 4:
|
| 184 |
+
size.insert(0, 1)
|
| 185 |
+
|
| 186 |
+
tt_tensor = ttnn.Tensor(py_tensor.reshape(size), tt_dtype)
|
| 187 |
+
tt_tensor = tt_tensor.to(tt_layout)
|
| 188 |
+
|
| 189 |
+
if tt_device is not None:
|
| 190 |
+
tt_tensor = tt_tensor.to(tt_device, tt_memory_config)
|
| 191 |
+
else:
|
| 192 |
+
tt_tensor = tt_tensor.cpu()
|
| 193 |
+
|
| 194 |
+
return tt_tensor
|
| 195 |
+
|
| 196 |
+
|
| 197 |
+
def tt_tensors_to_torch_tensors(
|
| 198 |
+
tt_tensors_device: ttnn.Tensor, mesh_device: Union[ttnn.MeshDevice, ttnn.Device], concat_dim: int = 0
|
| 199 |
+
):
|
| 200 |
+
# Convert tensors to interleaved
|
| 201 |
+
if tt_tensors_device.is_sharded():
|
| 202 |
+
tt_tensors_device = ttnn.sharded_to_interleaved(tt_tensors_device)
|
| 203 |
+
|
| 204 |
+
# Convert tensors to RM layout
|
| 205 |
+
if tt_tensors_device.layout == ttnn.TILE_LAYOUT:
|
| 206 |
+
# Convert to bfloat16 to ensure untilize works
|
| 207 |
+
if tt_tensors_device.dtype != ttnn.bfloat16:
|
| 208 |
+
tt_tensors_device = ttnn.clone(
|
| 209 |
+
tt_tensors_device, dtype=ttnn.bfloat16, memory_config=ttnn.DRAM_MEMORY_CONFIG
|
| 210 |
+
)
|
| 211 |
+
# Untilize using singlecore since multicore version runs out of l1 memory (Issue #9022)
|
| 212 |
+
tt_tensors_device = ttnn.untilize(tt_tensors_device, use_multicore=False)
|
| 213 |
+
|
| 214 |
+
return torch.cat([t.to_torch() for t in ttnn.get_device_tensors(tt_tensors_device.cpu())], dim=concat_dim)
|
| 215 |
+
|
| 216 |
+
|
| 217 |
+
def tt2torch_tensor(tt_tensor):
|
| 218 |
+
tt_output = tt_tensor.cpu()
|
| 219 |
+
if tt_output.get_layout() != ttnn.ROW_MAJOR_LAYOUT:
|
| 220 |
+
tt_output = tt_output.to(ttnn.ROW_MAJOR_LAYOUT)
|
| 221 |
+
return tt_output.to_torch()
|
| 222 |
+
|
| 223 |
+
|
| 224 |
+
def tt_to_torch_tensor(tt_tensor):
|
| 225 |
+
tt_output = tt_tensor.cpu().to(ttnn.ROW_MAJOR_LAYOUT)
|
| 226 |
+
return tt_output.to_torch()
|
| 227 |
+
|
| 228 |
+
|
| 229 |
+
def torch_to_tt_tensor_rm(py_tensor, device, shape=None, put_on_device=True):
|
| 230 |
+
if shape is None:
|
| 231 |
+
shape = list(py_tensor.size())
|
| 232 |
+
while len(shape) < 4:
|
| 233 |
+
shape.insert(0, 1)
|
| 234 |
+
|
| 235 |
+
tt_tensor = ttnn.Tensor(py_tensor.reshape(shape), ttnn.bfloat16)
|
| 236 |
+
if put_on_device:
|
| 237 |
+
tt_tensor = tt_tensor.to(device)
|
| 238 |
+
return tt_tensor
|
| 239 |
+
|
| 240 |
+
|
| 241 |
+
def torch_to_tt_tensor(py_tensor, device):
|
| 242 |
+
shape = list(py_tensor.size())
|
| 243 |
+
while len(shape) < 4:
|
| 244 |
+
shape.insert(0, 1)
|
| 245 |
+
|
| 246 |
+
tt_tensor = (
|
| 247 |
+
ttnn.Tensor(py_tensor.reshape(shape), ttnn.bfloat16)
|
| 248 |
+
.to(
|
| 249 |
+
ttnn.TILE_LAYOUT
|
| 250 |
+
) # change memory layout of TT Tensor to TILE (as operation that will use it expects TILE layout)
|
| 251 |
+
.to(device) # move TT Tensor from host to TT accelerator device (device is of type ttnn.device.Device)
|
| 252 |
+
)
|
| 253 |
+
|
| 254 |
+
return tt_tensor
|
| 255 |
+
|
| 256 |
+
|
| 257 |
+
def unpad_from_zero(x, desired_shape):
|
| 258 |
+
if x.padded_shape[-1] == desired_shape[-1] and x.padded_shape[-2] == desired_shape[-2]:
|
| 259 |
+
x = tt2torch_tensor(x)
|
| 260 |
+
else:
|
| 261 |
+
x = x.cpu()
|
| 262 |
+
if x.get_layout() != ttnn.ROW_MAJOR_LAYOUT:
|
| 263 |
+
x = x.to(ttnn.ROW_MAJOR_LAYOUT)
|
| 264 |
+
x = x.unpad(
|
| 265 |
+
(0, 0, 0, 0),
|
| 266 |
+
(
|
| 267 |
+
desired_shape[0],
|
| 268 |
+
desired_shape[1],
|
| 269 |
+
desired_shape[2],
|
| 270 |
+
desired_shape[3],
|
| 271 |
+
),
|
| 272 |
+
)
|
| 273 |
+
|
| 274 |
+
x = x.to_torch()
|
| 275 |
+
return x
|
| 276 |
+
|
| 277 |
+
|
| 278 |
+
def pad_activation(x):
|
| 279 |
+
"""
|
| 280 |
+
This function pads an activation with 0s as a pre-preprocessing step to tilization.
|
| 281 |
+
|
| 282 |
+
In the 2d case, it pads a vector to the right with 0s, and in the 2+d case,
|
| 283 |
+
it pads the bottom and right corners of the last two dimensions.
|
| 284 |
+
|
| 285 |
+
:param x: Input PyTorch Tensor
|
| 286 |
+
:type x: class:`torch.Tensor`
|
| 287 |
+
|
| 288 |
+
WARNING: This function should eventually be retired in favour of padding on device
|
| 289 |
+
"""
|
| 290 |
+
nearest_32 = _nearest_32
|
| 291 |
+
|
| 292 |
+
assert isinstance(x, torch.Tensor), "Input to this function must be an instance of torch.Tensor"
|
| 293 |
+
assert len(x.shape) >= 1 and len(x.shape) <= 4, "Only tensors with dimension 1-4 supported"
|
| 294 |
+
if len(x.shape) == 1: # (num_features,)
|
| 295 |
+
padded_tensor = torch.zeros(1, 1, 32, nearest_32(x.shape[0]))
|
| 296 |
+
padded_tensor[:, 0, 0, : x.shape[0]] = x
|
| 297 |
+
elif len(x.shape) == 2: # (batch, num features)
|
| 298 |
+
padded_tensor = torch.zeros(x.shape[0], 1, 32, nearest_32(x.shape[1]))
|
| 299 |
+
padded_tensor[:, 0, 0, : x.shape[1]] = x
|
| 300 |
+
elif len(x.shape) == 3: # (batch, num features y, num features x)
|
| 301 |
+
padded_tensor = torch.zeros(x.shape[0], 1, nearest_32(x.shape[-2]), nearest_32(x.shape[-1]))
|
| 302 |
+
padded_tensor[..., 0, : x.shape[-2], : x.shape[-1]] = x
|
| 303 |
+
else: # (batch, num channels, num features y, num features x)
|
| 304 |
+
padded_tensor = torch.zeros(*x.shape[:-2], nearest_32(x.shape[-2]), nearest_32(x.shape[-1]))
|
| 305 |
+
padded_tensor[..., : x.shape[-2], : x.shape[-1]] = x
|
| 306 |
+
return padded_tensor
|
| 307 |
+
|
| 308 |
+
|
| 309 |
+
def pad_weight(x):
|
| 310 |
+
"""
|
| 311 |
+
This function pads a weight/bias with 0s as a pre-preprocessing step to tilization.
|
| 312 |
+
|
| 313 |
+
tt_tensor = ttnn.Tensor(
|
| 314 |
+
py_tensor.reshape(shape), ttnn.bfloat16
|
| 315 |
+
In the 2d case, it pads a vector to the right with 0s, and in the 2+d case,
|
| 316 |
+
it pads the bottom and right corners of the last two dimensions.
|
| 317 |
+
|
| 318 |
+
:param x: Input PyTorch Tensor
|
| 319 |
+
:type x: class:`torch.Tensor`
|
| 320 |
+
|
| 321 |
+
WARNING: This function should eventually be retired in favour of padding on device
|
| 322 |
+
"""
|
| 323 |
+
nearest_32 = _nearest_32
|
| 324 |
+
|
| 325 |
+
assert isinstance(x, torch.Tensor), "Input to this function must be an instance of torch.Tensor"
|
| 326 |
+
assert len(x.shape) >= 1 and len(x.shape) <= 4, "Only tensors with dimension 1-4 supported"
|
| 327 |
+
|
| 328 |
+
if len(x.shape) == 1: # (num_features,)
|
| 329 |
+
padded_tensor = torch.zeros(1, 1, 32, nearest_32(x.shape[0]))
|
| 330 |
+
padded_tensor[:, 0, 0, : x.shape[0]] = x
|
| 331 |
+
elif len(x.shape) == 2: # (r_features, c_features)
|
| 332 |
+
padded_tensor = torch.zeros(1, 1, nearest_32(x.shape[0]), nearest_32(x.shape[1]))
|
| 333 |
+
padded_tensor[:, 0, : x.shape[0], : x.shape[1]] = x
|
| 334 |
+
else:
|
| 335 |
+
padded_tensor = torch.zeros(*x.shape[:-2], nearest_32(x.shape[-2]), nearest_32(x.shape[-1]))
|
| 336 |
+
padded_tensor[..., : x.shape[-2], : x.shape[-1]] = x
|
| 337 |
+
|
| 338 |
+
return padded_tensor
|
| 339 |
+
|
| 340 |
+
|
| 341 |
+
def convert_weights_2d_matrix(weights, w_shape):
|
| 342 |
+
"""
|
| 343 |
+
:param weights: Input PyTorch Tensor
|
| 344 |
+
:type weights: class:`torch.Tensor`
|
| 345 |
+
"""
|
| 346 |
+
ret_shape = [1, 1, w_shape[0], w_shape[1] * w_shape[2] * w_shape[3]]
|
| 347 |
+
if isinstance(weights, torch.Tensor):
|
| 348 |
+
ret = torch.zeros(np.prod(ret_shape))
|
| 349 |
+
else:
|
| 350 |
+
ret = np.zeros(np.prod(ret_shape))
|
| 351 |
+
idx = 0
|
| 352 |
+
for k in range(w_shape[0]):
|
| 353 |
+
for r in range(w_shape[2]):
|
| 354 |
+
for s in range(w_shape[3]):
|
| 355 |
+
for c in range(w_shape[1]):
|
| 356 |
+
ret[idx] = weights[k][c][r][s]
|
| 357 |
+
idx += 1
|
| 358 |
+
assert idx == np.prod(ret_shape)
|
| 359 |
+
return ret.reshape(ret_shape).transpose(2, 3)
|
| 360 |
+
|
| 361 |
+
|
| 362 |
+
def convert_act_2d_matrix(activation, kernel_y, kernel_x, stride_y, stride_x, pad_y, pad_x):
|
| 363 |
+
"""
|
| 364 |
+
:param activation: Input PyTorch Tensor
|
| 365 |
+
:type activation: class:`torch.Tensor`
|
| 366 |
+
"""
|
| 367 |
+
N = activation.shape[0]
|
| 368 |
+
C = activation.shape[1]
|
| 369 |
+
H = activation.shape[2]
|
| 370 |
+
W = activation.shape[3]
|
| 371 |
+
|
| 372 |
+
OH = (int)((H - kernel_y + 2 * pad_y) // stride_y) + 1
|
| 373 |
+
OW = ((W - kernel_x + 2 * pad_x) // stride_x) + 1
|
| 374 |
+
nrows = OH * OW
|
| 375 |
+
ncols = C * kernel_x * kernel_y
|
| 376 |
+
ret_shape = [1, N, nrows, ncols]
|
| 377 |
+
if isinstance(activation, torch.Tensor):
|
| 378 |
+
ret = torch.zeros(np.prod(ret_shape))
|
| 379 |
+
else:
|
| 380 |
+
ret = np.zeros(np.prod(ret_shape))
|
| 381 |
+
idx = 0
|
| 382 |
+
for n in range(N):
|
| 383 |
+
for h in range(-1 * pad_y, H + pad_y - kernel_y + 1, stride_y):
|
| 384 |
+
for w in range(-1 * pad_x, W + pad_x - kernel_x + 1, stride_x):
|
| 385 |
+
for r in range(kernel_y):
|
| 386 |
+
for s in range(kernel_x):
|
| 387 |
+
for c in range(C):
|
| 388 |
+
h_offs = h + r
|
| 389 |
+
w_offs = w + s
|
| 390 |
+
pad = h_offs < 0 or h_offs >= H or w_offs < 0 or w_offs >= W
|
| 391 |
+
ret[idx] = 0 if pad else activation[n][c][h_offs][w_offs]
|
| 392 |
+
idx += 1
|
| 393 |
+
assert idx == np.prod(ret_shape)
|
| 394 |
+
return ret.reshape(ret_shape)
|
| 395 |
+
|
| 396 |
+
|
| 397 |
+
### Tilizing / Untilizing ###
|
| 398 |
+
@deprecated("PyTorch data is handled automatically in tensor infra. This function does nothing now:")
|
| 399 |
+
def tilize(x):
|
| 400 |
+
return x
|
| 401 |
+
|
| 402 |
+
|
| 403 |
+
@deprecated("PyTorch data is handled automatically in tensor infra. This function does nothing now:")
|
| 404 |
+
def tilize_to_list(x):
|
| 405 |
+
"""
|
| 406 |
+
Returns a flattened list of the tensor
|
| 407 |
+
"""
|
| 408 |
+
return tilize(x).reshape(-1).tolist()
|
| 409 |
+
|
| 410 |
+
|
| 411 |
+
@deprecated("PyTorch data is handled automatically in tensor infra. This function does nothing now:")
|
| 412 |
+
def untilize(x):
|
| 413 |
+
return x
|
| 414 |
+
|
| 415 |
+
|
| 416 |
+
### Measuring accuracy and other metrics ###
|
| 417 |
+
def is_close(a, b, rtol=1e-2, atol=1e-2, max_mag=2.0, max_mag_fraction=0.02):
|
| 418 |
+
"""
|
| 419 |
+
A variant of np.isclose with logging.
|
| 420 |
+
"""
|
| 421 |
+
absdiff = (a - b).abs()
|
| 422 |
+
reldiff1 = (a.abs() / b.abs()) - 1.0
|
| 423 |
+
reldiff2 = (a.abs() + 1.0) / (b.abs() + 1.0) - 1.0 # in case b.abs() is 0
|
| 424 |
+
reldiff_or = torch.logical_or(reldiff1.abs() < rtol, reldiff2.abs() < rtol)
|
| 425 |
+
max_mag_ok = absdiff < max_mag * max_mag_fraction
|
| 426 |
+
|
| 427 |
+
or_abs_rel = torch.logical_or(absdiff < atol, reldiff_or)
|
| 428 |
+
or_abs_rel = torch.logical_or(or_abs_rel, max_mag_ok)
|
| 429 |
+
debug_index = or_abs_rel.to(torch.int32).argmin().item()
|
| 430 |
+
|
| 431 |
+
if not or_abs_rel.reshape(-1)[debug_index]:
|
| 432 |
+
logger.info(f"isclose mismatch at index={debug_index}")
|
| 433 |
+
logger.info(a.reshape(-1)[debug_index])
|
| 434 |
+
logger.info(b.reshape(-1)[debug_index])
|
| 435 |
+
logger.info(f"reldiff1={reldiff1.reshape(-1)[debug_index]}")
|
| 436 |
+
logger.info(f"reldiff2={reldiff2.reshape(-1)[debug_index]}")
|
| 437 |
+
logger.info(f"absdiff={absdiff.reshape(-1)[debug_index]}")
|
| 438 |
+
|
| 439 |
+
HT = a.shape[-2] // 32
|
| 440 |
+
WT = a.shape[-1] // 32
|
| 441 |
+
hwt = debug_index // 1024
|
| 442 |
+
wt = hwt % WT
|
| 443 |
+
ht = hwt // WT
|
| 444 |
+
h = (debug_index % 1024) // 32
|
| 445 |
+
w = (debug_index % 1024) % 32
|
| 446 |
+
|
| 447 |
+
logger.info(f"**** at {debug_index} --- HTWT={ht} {wt} HW={h} {w}")
|
| 448 |
+
|
| 449 |
+
return torch.all(or_abs_rel)
|
| 450 |
+
|
| 451 |
+
|
| 452 |
+
def _comp_nonfinite(golden, calculated):
|
| 453 |
+
"""
|
| 454 |
+
Returns True if tensors contain the same non-finite values (nan, inf, -inf) at the same positions. Also returns True if all elements are finite.
|
| 455 |
+
Returns False if non-finite values differ between both tensors.
|
| 456 |
+
"""
|
| 457 |
+
|
| 458 |
+
# torch.equal(['nan'], ['nan']] => False
|
| 459 |
+
# For this reason, we check for nan and inf separately
|
| 460 |
+
if torch.not_equal(torch.isnan(golden), torch.isnan(calculated)).any():
|
| 461 |
+
return False
|
| 462 |
+
|
| 463 |
+
golden_inf_mask = torch.isinf(golden)
|
| 464 |
+
calculated_inf_mask = torch.isinf(calculated)
|
| 465 |
+
|
| 466 |
+
if torch.not_equal(golden_inf_mask, calculated_inf_mask).any():
|
| 467 |
+
return False
|
| 468 |
+
|
| 469 |
+
golden_inf = golden[golden_inf_mask]
|
| 470 |
+
calculated_inf = calculated[calculated_inf_mask]
|
| 471 |
+
return torch.equal(golden_inf, calculated_inf)
|
| 472 |
+
|
| 473 |
+
|
| 474 |
+
def comp_allclose(golden, calculated, rtol=1e-05, atol=1e-08):
|
| 475 |
+
if golden.dtype != calculated.dtype:
|
| 476 |
+
calculated = calculated.type(golden.dtype)
|
| 477 |
+
|
| 478 |
+
atol_delta = torch.max(torch.abs(golden - calculated)).item()
|
| 479 |
+
rtol_delta = torch.max(torch.abs(golden - calculated) / torch.abs(calculated)).item()
|
| 480 |
+
return (
|
| 481 |
+
torch.allclose(golden, calculated, rtol, atol, True),
|
| 482 |
+
f"Max ATOL Delta: {atol_delta}, Max RTOL Delta: {rtol_delta}",
|
| 483 |
+
)
|
| 484 |
+
|
| 485 |
+
|
| 486 |
+
def comp_pcc(golden, calculated, pcc=0.99, rtol=1e-05, atol=1e-04):
|
| 487 |
+
golden = torch.Tensor(golden)
|
| 488 |
+
calculated = torch.Tensor(calculated)
|
| 489 |
+
|
| 490 |
+
if golden.dtype != calculated.dtype:
|
| 491 |
+
calculated = calculated.type(golden.dtype)
|
| 492 |
+
|
| 493 |
+
if torch.all(torch.isnan(golden)) and torch.all(torch.isnan(calculated)):
|
| 494 |
+
logger.warning("Both tensors are 'nan'")
|
| 495 |
+
return True, 1.0
|
| 496 |
+
|
| 497 |
+
if torch.all(torch.isnan(golden)) or torch.all(torch.isnan(calculated)):
|
| 498 |
+
logger.error("One tensor is all nan, the other is not.")
|
| 499 |
+
return False, 0.0
|
| 500 |
+
|
| 501 |
+
# Test if either is completely zero — but a zero tensor is also a constant tensor,
|
| 502 |
+
# so fall back to allclose instead of a hard 0.0: zero-vs-small-constant may be
|
| 503 |
+
# within the caller's tolerances.
|
| 504 |
+
if torch.any(golden.bool()) != torch.any(calculated.bool()):
|
| 505 |
+
logger.warning("One tensor is all zero. PCC undefined; falling back to allclose.")
|
| 506 |
+
result = torch.allclose(golden, calculated, rtol=rtol, atol=atol)
|
| 507 |
+
return result, float(result)
|
| 508 |
+
|
| 509 |
+
golden = torch.squeeze(golden).flatten()
|
| 510 |
+
calculated = torch.squeeze(calculated).flatten()
|
| 511 |
+
|
| 512 |
+
# For now, mask all infs and nans (to zero) so that we check the rest... TODO
|
| 513 |
+
# Skip this for integer types which don't have NaN/Inf values.
|
| 514 |
+
if golden.dtype.is_floating_point:
|
| 515 |
+
# FP8 doesn't support isfinite/nan_to_num and bfloat16 products lose precision,
|
| 516 |
+
# so correlate these in float32.
|
| 517 |
+
if golden.dtype in (torch.float8_e4m3fn, torch.float8_e5m2, torch.bfloat16):
|
| 518 |
+
golden = golden.to(torch.float32)
|
| 519 |
+
calculated = calculated.to(torch.float32)
|
| 520 |
+
|
| 521 |
+
# Zero out NaN/Inf, preserving the historical PCC values. nan_to_num allocates a
|
| 522 |
+
# full-size copy of each tensor, so only do it when invalid values are actually
|
| 523 |
+
# present; on the common all-finite path the tensors stay as views and no copy is
|
| 524 |
+
# made (this short-circuit is what keeps peak memory near 1x of one input).
|
| 525 |
+
if not bool((torch.isfinite(golden) & torch.isfinite(calculated)).all()):
|
| 526 |
+
golden = torch.nan_to_num(golden, nan=0.0, posinf=0.0, neginf=0.0)
|
| 527 |
+
calculated = torch.nan_to_num(calculated, nan=0.0, posinf=0.0, neginf=0.0)
|
| 528 |
+
|
| 529 |
+
if torch.equal(golden, calculated):
|
| 530 |
+
return True, 1.0
|
| 531 |
+
|
| 532 |
+
# Integer tensors must be correlated in floating point (centering/products would
|
| 533 |
+
# otherwise truncate/overflow). float32 keeps the working set small.
|
| 534 |
+
if not golden.dtype.is_floating_point:
|
| 535 |
+
golden = golden.to(torch.float32)
|
| 536 |
+
calculated = calculated.to(torch.float32)
|
| 537 |
+
|
| 538 |
+
# Pearson r with float64 *accumulation* (dtype= on the reductions) over the float32
|
| 539 |
+
# data: no float64 copy of either tensor is materialized, so peak memory stays near
|
| 540 |
+
# 1x of one input on large tensors while matching a full-float64 correlation to
|
| 541 |
+
# |Δ|<1e-9 across the high-PCC (>=0.999) range.
|
| 542 |
+
n = golden.numel()
|
| 543 |
+
g_centered = golden - (golden.sum(dtype=torch.float64) / n).to(golden.dtype)
|
| 544 |
+
c_centered = calculated - (calculated.sum(dtype=torch.float64) / n).to(calculated.dtype)
|
| 545 |
+
cov = (g_centered * c_centered).sum(dtype=torch.float64)
|
| 546 |
+
g_sq_sum = g_centered.pow(2).sum(dtype=torch.float64)
|
| 547 |
+
c_sq_sum = c_centered.pow(2).sum(dtype=torch.float64)
|
| 548 |
+
denom = torch.sqrt(g_sq_sum * c_sq_sum)
|
| 549 |
+
# pow/sum stay in float32 before the reduction; large-magnitude tensors (e.g. ldexp)
|
| 550 |
+
# can overflow to inf here even though float64 accumulation would be finite.
|
| 551 |
+
if not math.isfinite(denom.item()) or not math.isfinite(cov.item()):
|
| 552 |
+
g_centered64 = g_centered.to(torch.float64)
|
| 553 |
+
c_centered64 = c_centered.to(torch.float64)
|
| 554 |
+
cov = (g_centered64 * c_centered64).sum()
|
| 555 |
+
denom = torch.sqrt(g_centered64.pow(2).sum() * c_centered64.pow(2).sum())
|
| 556 |
+
cal_pcc = (cov / denom).item()
|
| 557 |
+
|
| 558 |
+
# Zero variance -> denom == 0 -> cal_pcc is nan: PCC is undefined for constant tensors.
|
| 559 |
+
# Fall back to allclose rather than returning a misleading 1.0.
|
| 560 |
+
if math.isnan(cal_pcc):
|
| 561 |
+
logger.warning("PCC is NaN (zero variance / constant tensor). Falling back to allclose check.")
|
| 562 |
+
result = torch.allclose(golden, calculated, rtol=rtol, atol=atol)
|
| 563 |
+
return result, float(result)
|
| 564 |
+
|
| 565 |
+
return cal_pcc >= pcc, cal_pcc
|
| 566 |
+
|
| 567 |
+
|
| 568 |
+
def ulp(x: Union[ttnn.Tensor, torch.Tensor]) -> Union[ttnn.Tensor, torch.Tensor]:
|
| 569 |
+
"Return Unit of Least Precision for each element of a given tensor"
|
| 570 |
+
|
| 571 |
+
received_ttnn_input = False
|
| 572 |
+
if isinstance(x, ttnn.Tensor):
|
| 573 |
+
x = ttnn.to_torch(x)
|
| 574 |
+
received_ttnn_input = True
|
| 575 |
+
|
| 576 |
+
# Notes:
|
| 577 |
+
# - This should be identical to the definition of ULP by Goldberg
|
| 578 |
+
# "What every computer scientist should know about floating-point arithmetic"
|
| 579 |
+
# https://docs.oracle.com/cd/E19957-01/806-3568/ncg_goldberg.html
|
| 580 |
+
# - We use torch.abs(x) to ensure symmetry ULP(-x) == ULP(x)
|
| 581 |
+
# - For x powers of 2, x + ULP(x) is not closest number but second closest (previous number is 2x closer)
|
| 582 |
+
# However, this avoids rounding-to-nearest-tie-to-even issues on addition (i.e. x + ULP(x) != x)
|
| 583 |
+
abs_x = torch.abs(x)
|
| 584 |
+
next = torch.nextafter(
|
| 585 |
+
abs_x, torch.tensor(math.inf, dtype=x.dtype)
|
| 586 |
+
) # 1 ULP ~ Difference between two consecutive floating point numbers
|
| 587 |
+
ulp_value = next - abs_x
|
| 588 |
+
|
| 589 |
+
# Special case: if abs_x == torch.finfo(x.dtype).max, then next == math.inf, which leads to ULP(x) == inf rather than finite number
|
| 590 |
+
# We fix this problem by manually calculating ULP at max value, and masking tensor when input == max
|
| 591 |
+
dtype_max = torch.finfo(x.dtype).max
|
| 592 |
+
max_epsilon = dtype_max - torch.nextafter(
|
| 593 |
+
torch.tensor(dtype_max, dtype=x.dtype), torch.tensor(-math.inf, dtype=x.dtype)
|
| 594 |
+
)
|
| 595 |
+
ulp_value = torch.where(abs_x == dtype_max, max_epsilon, ulp_value)
|
| 596 |
+
|
| 597 |
+
if received_ttnn_input: # Ensures that type(input) == type(output)
|
| 598 |
+
ulp_value = ttnn.from_torch(ulp_value)
|
| 599 |
+
|
| 600 |
+
return ulp_value
|
| 601 |
+
|
| 602 |
+
|
| 603 |
+
def comp_ulp(golden, calculated, ulp_threshold, allow_nonfinite=False):
|
| 604 |
+
"""
|
| 605 |
+
Compute absolute error between two tensors in Units of Least Precision (ULP)
|
| 606 |
+
"""
|
| 607 |
+
|
| 608 |
+
# If both tensors are empty, then we can return True
|
| 609 |
+
if torch.numel(golden) == 0 and torch.numel(calculated) == 0:
|
| 610 |
+
return True, "Both tensors are empty"
|
| 611 |
+
|
| 612 |
+
if not allow_nonfinite and not torch.all(torch.isfinite(calculated)):
|
| 613 |
+
return False, "Calculated tensor contains non-finite values"
|
| 614 |
+
|
| 615 |
+
if not _comp_nonfinite(golden, calculated):
|
| 616 |
+
return False, "Tensors are not finite at the same positions"
|
| 617 |
+
# nonfinite elements can interfere with ULP error calculation
|
| 618 |
+
# To avoid this, replace nan, +inf, -inf with 0
|
| 619 |
+
# (we have already checked that both tensors have the same nonfinite elements)
|
| 620 |
+
mask_finite = ~torch.isfinite(golden)
|
| 621 |
+
golden = golden.clone()
|
| 622 |
+
calculated = calculated.clone()
|
| 623 |
+
golden[mask_finite] = 0
|
| 624 |
+
calculated[mask_finite] = 0
|
| 625 |
+
|
| 626 |
+
# ULP is measured according to the golden tensor
|
| 627 |
+
# In most cases, data type of golden tensor should be the same as calculated tensor.
|
| 628 |
+
# However, in some cases, we may want to measure < 1 ULP differences, which requires golden tensor
|
| 629 |
+
# to have higher precision than calculated tensor.
|
| 630 |
+
# If we passed golden tensor to ulp() as is, we would get ULP of higher precision.
|
| 631 |
+
# e.g. ulp of float32 rather bfloat16 calculation, which would give us a wrong value.
|
| 632 |
+
ulp_value = ulp(golden.type(calculated.dtype))
|
| 633 |
+
|
| 634 |
+
if golden.dtype != calculated.dtype: # Note: assumes that golden has higher precision than calculated tensor
|
| 635 |
+
calculated = calculated.type(golden.dtype)
|
| 636 |
+
ulp_value = ulp_value.type(golden.dtype) # Convert ULP to higher precision (for sub-1 ULP measurements)
|
| 637 |
+
|
| 638 |
+
ulp_tensor = torch.abs(calculated - golden) / ulp_value
|
| 639 |
+
ulp_delta = torch.max(ulp_tensor)
|
| 640 |
+
within_threshold = ulp_delta <= ulp_threshold
|
| 641 |
+
message = f"Max ULP Delta: {ulp_delta}"
|
| 642 |
+
if not within_threshold:
|
| 643 |
+
ulp_index = torch.argmax(ulp_tensor)
|
| 644 |
+
ulp_index_tuple = tuple(int(idx) for idx in torch.unravel_index(ulp_index, golden.shape))
|
| 645 |
+
message += (
|
| 646 |
+
f" @ {list(ulp_index_tuple)} = "
|
| 647 |
+
f"|calculated {calculated[ulp_index_tuple]} - golden {golden[ulp_index_tuple]}| "
|
| 648 |
+
f"/ ULP(golden) {ulp_value[ulp_index_tuple]}"
|
| 649 |
+
)
|
| 650 |
+
return (within_threshold, message)
|
| 651 |
+
|
| 652 |
+
|
| 653 |
+
def calculate_detailed_ulp_stats(expected, actual):
|
| 654 |
+
"""
|
| 655 |
+
Calculate detailed ULP statistics for analysis.
|
| 656 |
+
|
| 657 |
+
Returns:
|
| 658 |
+
dict: Dictionary with ULP statistics including max, mean, std, and percentiles
|
| 659 |
+
"""
|
| 660 |
+
if isinstance(actual, ttnn.Tensor):
|
| 661 |
+
actual = ttnn.to_torch(actual)
|
| 662 |
+
if isinstance(expected, ttnn.Tensor):
|
| 663 |
+
expected = ttnn.to_torch(expected)
|
| 664 |
+
|
| 665 |
+
# Convert to bfloat16 if not already
|
| 666 |
+
expected = expected.to(torch.bfloat16)
|
| 667 |
+
actual = actual.to(torch.bfloat16)
|
| 668 |
+
|
| 669 |
+
# Handle special cases
|
| 670 |
+
if torch.allclose(expected, actual, rtol=0, atol=0, equal_nan=True):
|
| 671 |
+
return {
|
| 672 |
+
"max_ulp": 0.0,
|
| 673 |
+
"mean_ulp": 0.0,
|
| 674 |
+
"median_ulp": 0.0,
|
| 675 |
+
"std_ulp": 0.0,
|
| 676 |
+
"p95_ulp": 0.0,
|
| 677 |
+
"p99_ulp": 0.0,
|
| 678 |
+
"perfect_matches": 1.0,
|
| 679 |
+
}
|
| 680 |
+
|
| 681 |
+
# Convert bfloat16 to uint16 representation for bit manipulation
|
| 682 |
+
expected_bits = expected.view(torch.int16).to(torch.int32)
|
| 683 |
+
actual_bits = actual.view(torch.int16).to(torch.int32)
|
| 684 |
+
|
| 685 |
+
# Handle sign differences
|
| 686 |
+
expected_sign = expected_bits < 0
|
| 687 |
+
actual_sign = actual_bits < 0
|
| 688 |
+
same_sign = expected_sign == actual_sign
|
| 689 |
+
|
| 690 |
+
# Calculate ULP differences
|
| 691 |
+
expected_abs_bits = torch.where(expected_sign, -expected_bits, expected_bits)
|
| 692 |
+
actual_abs_bits = torch.where(actual_sign, -actual_bits, actual_bits)
|
| 693 |
+
|
| 694 |
+
ulp_diff = torch.where(same_sign, torch.abs(expected_bits - actual_bits), expected_abs_bits + actual_abs_bits)
|
| 695 |
+
|
| 696 |
+
# Handle non-finite values
|
| 697 |
+
expected_finite = torch.isfinite(expected)
|
| 698 |
+
actual_finite = torch.isfinite(actual)
|
| 699 |
+
both_finite = expected_finite & actual_finite
|
| 700 |
+
|
| 701 |
+
ulp_diff = torch.where(both_finite, ulp_diff, torch.tensor(float("inf")))
|
| 702 |
+
|
| 703 |
+
# Handle same non-finite values
|
| 704 |
+
both_nan = torch.isnan(expected) & torch.isnan(actual)
|
| 705 |
+
both_posinf = torch.isposinf(expected) & torch.isposinf(actual)
|
| 706 |
+
both_neginf = torch.isneginf(expected) & torch.isneginf(actual)
|
| 707 |
+
same_nonfinite = both_nan | both_posinf | both_neginf
|
| 708 |
+
|
| 709 |
+
ulp_diff = torch.where(same_nonfinite, torch.tensor(0.0), ulp_diff)
|
| 710 |
+
|
| 711 |
+
# Calculate statistics only on finite ULP differences
|
| 712 |
+
finite_ulp = ulp_diff[torch.isfinite(ulp_diff)]
|
| 713 |
+
|
| 714 |
+
if len(finite_ulp) == 0:
|
| 715 |
+
return {
|
| 716 |
+
"max_ulp": float("inf"),
|
| 717 |
+
"mean_ulp": float("inf"),
|
| 718 |
+
"median_ulp": float("inf"),
|
| 719 |
+
"std_ulp": float("inf"),
|
| 720 |
+
"p95_ulp": float("inf"),
|
| 721 |
+
"p99_ulp": float("inf"),
|
| 722 |
+
"perfect_matches": 0.0,
|
| 723 |
+
}
|
| 724 |
+
|
| 725 |
+
finite_ulp_float = finite_ulp.float()
|
| 726 |
+
perfect_matches = (finite_ulp == 0).float().mean().item()
|
| 727 |
+
|
| 728 |
+
return {
|
| 729 |
+
"max_ulp": torch.max(finite_ulp).item(),
|
| 730 |
+
"mean_ulp": torch.mean(finite_ulp_float).item(),
|
| 731 |
+
"median_ulp": torch.median(finite_ulp_float).item(),
|
| 732 |
+
"std_ulp": torch.std(finite_ulp_float).item(),
|
| 733 |
+
"p95_ulp": torch.quantile(finite_ulp_float, 0.95).item(),
|
| 734 |
+
"p99_ulp": torch.quantile(finite_ulp_float, 0.99).item(),
|
| 735 |
+
"perfect_matches": perfect_matches,
|
| 736 |
+
}
|
| 737 |
+
|
| 738 |
+
|
| 739 |
+
def comp_allclose_and_pcc(golden, calculated, rtol=1e-05, atol=1e-08, pcc=0.99):
|
| 740 |
+
# 0-volume tensors are special because they don't have elements, so we can't compute PCC, etc.
|
| 741 |
+
# If one of the tensors is a 0-volume tensor, simply call torch.equal to check if they are equal
|
| 742 |
+
# (i.e. that both are 0-volume tensors and they have equal shapes).
|
| 743 |
+
if golden.numel() == 0 or calculated.numel() == 0:
|
| 744 |
+
return torch.equal(golden, calculated), f"{golden} != {calculated}"
|
| 745 |
+
|
| 746 |
+
if golden.dtype != calculated.dtype:
|
| 747 |
+
calculated = calculated.type(golden.dtype)
|
| 748 |
+
|
| 749 |
+
passing = True
|
| 750 |
+
output = ""
|
| 751 |
+
passing_allclose, output_allclose = comp_allclose(golden, calculated, rtol, atol)
|
| 752 |
+
passing &= passing_allclose
|
| 753 |
+
output += output_allclose
|
| 754 |
+
if torch.numel(golden) != 1:
|
| 755 |
+
passing_pcc, output_pcc = comp_pcc(golden, calculated, pcc, rtol=rtol, atol=atol)
|
| 756 |
+
passing &= passing_pcc
|
| 757 |
+
output += f", pcc={output_pcc}"
|
| 758 |
+
|
| 759 |
+
return passing, output
|
| 760 |
+
|
| 761 |
+
|
| 762 |
+
def comp_equal(golden, calculated):
|
| 763 |
+
if golden.dtype != calculated.dtype:
|
| 764 |
+
calculated = calculated.type(golden.dtype)
|
| 765 |
+
|
| 766 |
+
# If either tensor is zero-volume, broadcasting can still yield an empty delta and
|
| 767 |
+
# crash torch.max(); defer entirely to torch.equal (False on shape mismatch).
|
| 768 |
+
if golden.numel() == 0 or calculated.numel() == 0:
|
| 769 |
+
return torch.equal(golden, calculated), f"{golden} != {calculated}"
|
| 770 |
+
|
| 771 |
+
atol_delta = torch.max(torch.abs(golden - calculated)).item()
|
| 772 |
+
rtol_delta = torch.max(torch.abs(golden - calculated) / torch.abs(calculated)).item()
|
| 773 |
+
return (
|
| 774 |
+
torch.equal(golden, calculated),
|
| 775 |
+
f"Max ATOL Delta: {atol_delta}, Max RTOL Delta: {rtol_delta}",
|
| 776 |
+
)
|
| 777 |
+
|
| 778 |
+
|
| 779 |
+
def get_oom_of_float(float_lst):
|
| 780 |
+
"""
|
| 781 |
+
Given a list of floats, returns a list of the order or magnitudes
|
| 782 |
+
of the floats. Useful when you want to make sure that even if your
|
| 783 |
+
tt outputs don't match pytorch all that well, they are at least
|
| 784 |
+
on the same order of magnitude
|
| 785 |
+
"""
|
| 786 |
+
ooms = []
|
| 787 |
+
for el in float_lst:
|
| 788 |
+
str_el = str(el)
|
| 789 |
+
if "e" in str_el:
|
| 790 |
+
oom = int(str_el.split("e")[1])
|
| 791 |
+
elif str_el[:2] == "0.":
|
| 792 |
+
str_el = str_el.split(".")[1]
|
| 793 |
+
|
| 794 |
+
oom = -1
|
| 795 |
+
for e in str_el:
|
| 796 |
+
if e != "0":
|
| 797 |
+
break
|
| 798 |
+
oom -= 1
|
| 799 |
+
else:
|
| 800 |
+
oom = len(str_el.split(".")[0])
|
| 801 |
+
|
| 802 |
+
ooms.append(oom)
|
| 803 |
+
|
| 804 |
+
return ooms
|
| 805 |
+
|
| 806 |
+
|
| 807 |
+
def print_diff_argmax(a, b, annotation=""):
|
| 808 |
+
"""
|
| 809 |
+
Prints out the value of both tensors at a point where the absolute difference is the largest.
|
| 810 |
+
"""
|
| 811 |
+
absdiff = (a - b).abs()
|
| 812 |
+
argmax = absdiff.argmax().item()
|
| 813 |
+
diff = absdiff.reshape(-1)[argmax]
|
| 814 |
+
rela = a.abs() / (torch.max(a.abs(), b.abs()))
|
| 815 |
+
relb = b.abs() / (torch.max(a.abs(), b.abs()))
|
| 816 |
+
HT = a.shape[-2] // 32
|
| 817 |
+
WT = a.shape[-1] // 32
|
| 818 |
+
hwt = argmax // 1024
|
| 819 |
+
wt = hwt % WT
|
| 820 |
+
ht = hwt // WT
|
| 821 |
+
h = (argmax % 1024) // 32
|
| 822 |
+
w = (argmax % 1024) % 32
|
| 823 |
+
print(
|
| 824 |
+
"Abs diff=",
|
| 825 |
+
diff,
|
| 826 |
+
" at ",
|
| 827 |
+
argmax,
|
| 828 |
+
" --- ",
|
| 829 |
+
annotation,
|
| 830 |
+
"HTWT=",
|
| 831 |
+
ht,
|
| 832 |
+
wt,
|
| 833 |
+
"HW=",
|
| 834 |
+
h,
|
| 835 |
+
w,
|
| 836 |
+
)
|
| 837 |
+
print(" (a=", a.reshape(-1)[argmax].item(), ")")
|
| 838 |
+
print(" (b=", b.reshape(-1)[argmax].item(), ")")
|
| 839 |
+
print(" Rel a=", rela.reshape(-1)[argmax], " at ", argmax)
|
| 840 |
+
print(" Rel b=", relb.reshape(-1)[argmax], " at ", argmax)
|
| 841 |
+
return diff.item()
|
| 842 |
+
|
| 843 |
+
|
| 844 |
+
def print_diff_tt_pyt(a, b, annotation=""):
|
| 845 |
+
# first convert a pytorch tensor argument b to tt
|
| 846 |
+
padded_b = pad_weight(b)
|
| 847 |
+
pyt_a = tt2torch(a) # untilizes also
|
| 848 |
+
return print_diff_argmax(pyt_a, padded_b, annotation)
|
| 849 |
+
|
| 850 |
+
|
| 851 |
+
def ttP(x, count=4, offset=0, stride=1):
|
| 852 |
+
if type(x) == torch.Tensor:
|
| 853 |
+
t1 = x.reshape(-1)
|
| 854 |
+
else:
|
| 855 |
+
tt_out = x.cpu()
|
| 856 |
+
torch_out = untilize(tt_out.to_torch())
|
| 857 |
+
t1 = torch_out.reshape(-1)
|
| 858 |
+
print("Tensor vals: (", end="")
|
| 859 |
+
for j in range(offset, offset + count * stride, stride):
|
| 860 |
+
print(t1[j].item(), " ", end="")
|
| 861 |
+
print(")")
|
| 862 |
+
|
| 863 |
+
|
| 864 |
+
### Conv related helpers ###
|
| 865 |
+
def read_conv_act_into_mm_act_block(
|
| 866 |
+
conv_act,
|
| 867 |
+
act_address_map_index,
|
| 868 |
+
address_map,
|
| 869 |
+
address_map_this_block_size,
|
| 870 |
+
act_block_h,
|
| 871 |
+
act_block_w,
|
| 872 |
+
):
|
| 873 |
+
mm_act_block_shape = [1, 1, act_block_h * 32, act_block_w * 32]
|
| 874 |
+
mm_act_block_size = act_block_h * act_block_w * 1024
|
| 875 |
+
mm_act_block = torch.zeros(mm_act_block_size, dtype=torch.bfloat16).float()
|
| 876 |
+
for i in range(0, address_map_this_block_size, 4):
|
| 877 |
+
src_address = address_map[act_address_map_index]
|
| 878 |
+
dst_address = address_map[act_address_map_index + 1]
|
| 879 |
+
read_size = address_map[act_address_map_index + 2]
|
| 880 |
+
pad = address_map[act_address_map_index + 3]
|
| 881 |
+
for s in range(read_size):
|
| 882 |
+
assert dst_address + s < mm_act_block_size
|
| 883 |
+
if pad:
|
| 884 |
+
mm_act_block[dst_address + s] = 0
|
| 885 |
+
else:
|
| 886 |
+
assert src_address + s < len(conv_act)
|
| 887 |
+
mm_act_block[dst_address + s] = conv_act[src_address + s]
|
| 888 |
+
act_address_map_index += 4
|
| 889 |
+
return (mm_act_block.reshape(mm_act_block_shape), act_address_map_index)
|
| 890 |
+
|
| 891 |
+
|
| 892 |
+
def read_conv_weight_into_mm_weight_block(
|
| 893 |
+
conv_weight,
|
| 894 |
+
weight_address_map_index,
|
| 895 |
+
weight_address_map,
|
| 896 |
+
weight_address_map_this_block_size,
|
| 897 |
+
weight_block_h,
|
| 898 |
+
weight_block_w,
|
| 899 |
+
):
|
| 900 |
+
mm_weight_block_shape = [1, 1, weight_block_h * 32, weight_block_w * 32]
|
| 901 |
+
mm_weight_block_size = weight_block_h * weight_block_w * 1024
|
| 902 |
+
mm_weight_block = torch.zeros(mm_weight_block_size, dtype=torch.bfloat16).float()
|
| 903 |
+
for i in range(0, weight_address_map_this_block_size, 4):
|
| 904 |
+
src_address = weight_address_map[weight_address_map_index]
|
| 905 |
+
dst_address = weight_address_map[weight_address_map_index + 1]
|
| 906 |
+
read_size = weight_address_map[weight_address_map_index + 2]
|
| 907 |
+
pad = weight_address_map[weight_address_map_index + 3]
|
| 908 |
+
for s in range(read_size):
|
| 909 |
+
assert dst_address + s < mm_weight_block_size
|
| 910 |
+
if pad:
|
| 911 |
+
mm_weight_block[dst_address + s] = 0
|
| 912 |
+
else:
|
| 913 |
+
assert src_address + s < len(conv_weight)
|
| 914 |
+
mm_weight_block[dst_address + s] = conv_weight[src_address + s]
|
| 915 |
+
weight_address_map_index += 4
|
| 916 |
+
return (mm_weight_block.reshape(mm_weight_block_shape), weight_address_map_index)
|
| 917 |
+
|
| 918 |
+
|
| 919 |
+
def blocked_mm_with_conv_act(
|
| 920 |
+
conv_act,
|
| 921 |
+
mm_weight,
|
| 922 |
+
act_address_map,
|
| 923 |
+
weight_address_map,
|
| 924 |
+
num_blocks_act_h,
|
| 925 |
+
num_blocks_act_w,
|
| 926 |
+
num_blocks_weight_w,
|
| 927 |
+
act_block_h,
|
| 928 |
+
act_block_w,
|
| 929 |
+
weight_block_w,
|
| 930 |
+
):
|
| 931 |
+
# act refers to conv activation tensor
|
| 932 |
+
# weight refers to conv weight tensor
|
| 933 |
+
mm_output_shape = [
|
| 934 |
+
1,
|
| 935 |
+
1,
|
| 936 |
+
num_blocks_act_h * act_block_h * 32,
|
| 937 |
+
num_blocks_weight_w * weight_block_w * 32,
|
| 938 |
+
]
|
| 939 |
+
ret = torch.zeros(mm_output_shape, dtype=torch.bfloat16).float()
|
| 940 |
+
mm_output_block_shape = [1, 1, act_block_h * 32, weight_block_w * 32]
|
| 941 |
+
act_address_map_index = 0
|
| 942 |
+
weight_address_map_index = 0
|
| 943 |
+
weight_block_h = act_block_w
|
| 944 |
+
num_groups = act_address_map[act_address_map_index]
|
| 945 |
+
assert num_groups == num_blocks_act_h * num_blocks_act_w * num_blocks_weight_w
|
| 946 |
+
weight_num_groups = act_address_map[weight_address_map_index]
|
| 947 |
+
assert weight_num_groups == num_groups
|
| 948 |
+
act_address_map_index += 1
|
| 949 |
+
weight_address_map_index += 1
|
| 950 |
+
for block_act_h in range(num_blocks_act_h):
|
| 951 |
+
# Reset weight (weight) to the starting tile in this column
|
| 952 |
+
for block_weight_w in range(num_blocks_weight_w):
|
| 953 |
+
output_block = torch.zeros(mm_output_block_shape, dtype=torch.bfloat16).float()
|
| 954 |
+
for block_act_w in range(num_blocks_act_w):
|
| 955 |
+
address_map_this_block_size = act_address_map[act_address_map_index]
|
| 956 |
+
act_address_map_index += 1
|
| 957 |
+
weight_address_map_this_block_size = weight_address_map[weight_address_map_index]
|
| 958 |
+
weight_address_map_index += 1
|
| 959 |
+
(mm_act_block, act_address_map_index) = read_conv_act_into_mm_act_block(
|
| 960 |
+
conv_act,
|
| 961 |
+
act_address_map_index,
|
| 962 |
+
act_address_map,
|
| 963 |
+
address_map_this_block_size,
|
| 964 |
+
act_block_h,
|
| 965 |
+
act_block_w,
|
| 966 |
+
)
|
| 967 |
+
(
|
| 968 |
+
mm_weight_block,
|
| 969 |
+
weight_address_map_index,
|
| 970 |
+
) = read_conv_weight_into_mm_weight_block(
|
| 971 |
+
mm_weight,
|
| 972 |
+
weight_address_map_index,
|
| 973 |
+
weight_address_map,
|
| 974 |
+
weight_address_map_this_block_size,
|
| 975 |
+
weight_block_h,
|
| 976 |
+
weight_block_w,
|
| 977 |
+
)
|
| 978 |
+
# Untilize weight block (this CPU reference does matmul on untilized blocks)
|
| 979 |
+
mm_weight_block = untilize(mm_weight_block)
|
| 980 |
+
for out_h_block in range(act_block_h * 32):
|
| 981 |
+
for out_w_block in range(weight_block_w * 32):
|
| 982 |
+
output_block[0][0][out_h_block][out_w_block] += torch.dot(
|
| 983 |
+
mm_act_block[0, 0, out_h_block, :].reshape(-1),
|
| 984 |
+
mm_weight_block[0, 0, :, out_w_block].reshape(-1),
|
| 985 |
+
)
|
| 986 |
+
start_oh = block_act_h * act_block_h * 32
|
| 987 |
+
start_ow = block_weight_w * weight_block_w * 32
|
| 988 |
+
end_oh = start_oh + (act_block_h * 32)
|
| 989 |
+
end_ow = start_ow + (weight_block_w * 32)
|
| 990 |
+
ret[0, 0, start_oh:end_oh, start_ow:end_ow] = output_block
|
| 991 |
+
|
| 992 |
+
return ret
|
| 993 |
+
|
| 994 |
+
|
| 995 |
+
def is_conv_supported_on_device(conv_params):
|
| 996 |
+
K, C, R, S, U, V, P_H, P_W, dilation, groups = [conv_params[i] for i in range(10)]
|
| 997 |
+
|
| 998 |
+
if K % 32 != 0 or dilation != 1 or groups != 1:
|
| 999 |
+
logger.warning("DOES NOT HAVE SUPPORT FOR Conv with following parameters -")
|
| 1000 |
+
logger.warning(
|
| 1001 |
+
"K="
|
| 1002 |
+
+ str(K)
|
| 1003 |
+
+ " C="
|
| 1004 |
+
+ str(C)
|
| 1005 |
+
+ " R="
|
| 1006 |
+
+ str(R)
|
| 1007 |
+
+ " S="
|
| 1008 |
+
+ str(S)
|
| 1009 |
+
+ " U="
|
| 1010 |
+
+ str(U)
|
| 1011 |
+
+ " V="
|
| 1012 |
+
+ str(V)
|
| 1013 |
+
+ " PH="
|
| 1014 |
+
+ str(P_H)
|
| 1015 |
+
+ " PW="
|
| 1016 |
+
+ str(P_W)
|
| 1017 |
+
+ " dilation="
|
| 1018 |
+
+ str(dilation)
|
| 1019 |
+
+ " groups="
|
| 1020 |
+
+ str(groups)
|
| 1021 |
+
)
|
| 1022 |
+
return False
|
| 1023 |
+
|
| 1024 |
+
return True
|
| 1025 |
+
|
| 1026 |
+
|
| 1027 |
+
def is_x2_harvested(device):
|
| 1028 |
+
grid = device.compute_with_storage_grid_size()
|
| 1029 |
+
return device.arch() == Arch.WORMHOLE_B0 and (grid.x, grid.y) == (8, 7)
|
| 1030 |
+
|
| 1031 |
+
|
| 1032 |
+
def is_single_chip():
|
| 1033 |
+
return ttnn.GetNumAvailableDevices() == 1
|
| 1034 |
+
|
| 1035 |
+
|
| 1036 |
+
def is_quasar():
|
| 1037 |
+
ARCH_NAME = ttnn.get_arch_name()
|
| 1038 |
+
return "quasar" in ARCH_NAME
|
| 1039 |
+
|
| 1040 |
+
|
| 1041 |
+
def is_blackhole():
|
| 1042 |
+
ARCH_NAME = ttnn.get_arch_name()
|
| 1043 |
+
return "blackhole" in ARCH_NAME
|
| 1044 |
+
|
| 1045 |
+
|
| 1046 |
+
def is_wormhole_b0():
|
| 1047 |
+
ARCH_NAME = ttnn.get_arch_name()
|
| 1048 |
+
return "wormhole_b0" in ARCH_NAME
|
| 1049 |
+
|
| 1050 |
+
|
| 1051 |
+
def is_watcher_enabled():
|
| 1052 |
+
watcher = os.environ.get("TT_METAL_WATCHER")
|
| 1053 |
+
lightweight_asserts = os.environ.get("TT_METAL_LIGHTWEIGHT_KERNEL_ASSERTS")
|
| 1054 |
+
return (watcher is not None and watcher != "") or lightweight_asserts == "1"
|
| 1055 |
+
|
| 1056 |
+
|
| 1057 |
+
def is_llk_assert_enabled():
|
| 1058 |
+
llk_assert = os.environ.get("TT_METAL_LLK_ASSERTS")
|
| 1059 |
+
return llk_assert == "1"
|
| 1060 |
+
|
| 1061 |
+
|
| 1062 |
+
def is_n300():
|
| 1063 |
+
return os.environ.get("MESH_DEVICE", "N150") == "N300"
|
| 1064 |
+
|
| 1065 |
+
|
| 1066 |
+
def is_slow_dispatch():
|
| 1067 |
+
return os.environ.get("TT_METAL_SLOW_DISPATCH_MODE") == "1"
|
| 1068 |
+
|
| 1069 |
+
|
| 1070 |
+
def ti_skip(condition, reason="Invalid test parameters"):
|
| 1071 |
+
import pytest
|
| 1072 |
+
|
| 1073 |
+
return pytest.mark.skipif(condition, reason="Skipping unsupported case: " + reason)
|
| 1074 |
+
|
| 1075 |
+
|
| 1076 |
+
def skip_for_blackhole(reason_str="not a blackhole test"):
|
| 1077 |
+
return ti_skip(is_blackhole(), reason=reason_str)
|
| 1078 |
+
|
| 1079 |
+
|
| 1080 |
+
def skip_for_wormhole_b0(reason_str="not a wormhole test"):
|
| 1081 |
+
return ti_skip(is_wormhole_b0(), reason=reason_str)
|
| 1082 |
+
|
| 1083 |
+
|
| 1084 |
+
def skip_with_watcher(reason_str="Test is not passing with watcher enabled"):
|
| 1085 |
+
return ti_skip(is_watcher_enabled(), reason=reason_str)
|
| 1086 |
+
|
| 1087 |
+
|
| 1088 |
+
def skip_with_llk_assert(reason_str="Test is not passing with LLK asserts enabled"):
|
| 1089 |
+
return ti_skip(is_llk_assert_enabled(), reason=reason_str)
|
| 1090 |
+
|
| 1091 |
+
|
| 1092 |
+
def run_for_blackhole(reason_str="only runs for Blackhole"):
|
| 1093 |
+
return ti_skip(not is_blackhole(), reason=reason_str)
|
| 1094 |
+
|
| 1095 |
+
|
| 1096 |
+
def run_for_wormhole_b0(reason_str="only runs for Wormhole B0"):
|
| 1097 |
+
return ti_skip(not is_wormhole_b0(), reason=reason_str)
|
| 1098 |
+
|
| 1099 |
+
|
| 1100 |
+
def run_for_wormhole_b0_or_blackhole(reason_str="only runs for Wormhole B0 or Blackhole"):
|
| 1101 |
+
return ti_skip(not (is_wormhole_b0() or is_blackhole()), reason=reason_str)
|
| 1102 |
+
|
| 1103 |
+
|
| 1104 |
+
def run_for_n_dev(n, reason_str="Test is not meant for this number of devices"):
|
| 1105 |
+
return ti_skip(ttnn.get_num_devices() != n, reason=reason_str)
|
| 1106 |
+
|
| 1107 |
+
|
| 1108 |
+
def skip_for_n_dev(n, reason_str="Test is not meant for this number of devices"):
|
| 1109 |
+
return ti_skip(ttnn.get_num_devices() == n, reason=reason_str)
|
| 1110 |
+
|
| 1111 |
+
|
| 1112 |
+
def skip_for_n_or_less_dev(n, reason_str="Test is not meant for this number of devices"):
|
| 1113 |
+
return ti_skip(ttnn.get_num_devices() <= n, reason=reason_str)
|
| 1114 |
+
|
| 1115 |
+
|
| 1116 |
+
def skip_for_slow_dispatch(reason_str="not working for slow dispatch"):
|
| 1117 |
+
return ti_skip(is_slow_dispatch(), reason=reason_str)
|
| 1118 |
+
|
| 1119 |
+
|
| 1120 |
+
def ttl_complex_2_torch_complex(tt_tensor):
|
| 1121 |
+
torch_tensor = tt2torch_tensor(tt_tensor)
|
| 1122 |
+
|
| 1123 |
+
# extract real and imag parts of the complex tensor
|
| 1124 |
+
real = torch_tensor[:, :, :, : torch_tensor.shape[-1] // 2].to(torch.bfloat16).to(torch.float)
|
| 1125 |
+
imag = torch_tensor[:, :, :, torch_tensor.shape[-1] // 2 :].to(torch.bfloat16).to(torch.float)
|
| 1126 |
+
|
| 1127 |
+
# create torch complex tensor
|
| 1128 |
+
result = torch.complex(real, imag)
|
| 1129 |
+
return result
|
| 1130 |
+
|
| 1131 |
+
|
| 1132 |
+
def pad_and_fold_conv_filters_for_unity_stride(filter_pyt_nchw_tensor, stride_h, stride_w, align_c=4):
|
| 1133 |
+
assert stride_h == stride_w
|
| 1134 |
+
assert filter_pyt_nchw_tensor.shape[2] == filter_pyt_nchw_tensor.shape[3]
|
| 1135 |
+
assert isinstance(align_c, int) and align_c > 0
|
| 1136 |
+
# Fold activation for unity stride
|
| 1137 |
+
# Pad channel size to align_c. This keeps L1 read addresses aligned; extra channels become
|
| 1138 |
+
# zero-valued weights that contribute nothing to the convolution. align_c=4 is the WH/BH default
|
| 1139 |
+
# (16B alignment for bf16 gives C a multiple of 4 with a tiled conv reader). Quasar's row-major
|
| 1140 |
+
# fold needs align_c=8 (bf16 row-major shard width must be a multiple of 8) so the first conv
|
| 1141 |
+
# folds to groups*8 input channels and consumes the aligned output without per-group padding strip.
|
| 1142 |
+
C = _nearest_y(filter_pyt_nchw_tensor.shape[1], align_c)
|
| 1143 |
+
# Pad filter to nearest stride
|
| 1144 |
+
Padded_filter_height = _nearest_y(filter_pyt_nchw_tensor.shape[2], stride_h)
|
| 1145 |
+
Padded_filter_width = _nearest_y(filter_pyt_nchw_tensor.shape[3], stride_w)
|
| 1146 |
+
filter_pyt_padded = torch.nn.functional.pad(
|
| 1147 |
+
filter_pyt_nchw_tensor,
|
| 1148 |
+
(
|
| 1149 |
+
0,
|
| 1150 |
+
Padded_filter_width - filter_pyt_nchw_tensor.shape[3],
|
| 1151 |
+
0,
|
| 1152 |
+
Padded_filter_height - filter_pyt_nchw_tensor.shape[2],
|
| 1153 |
+
0,
|
| 1154 |
+
C - filter_pyt_nchw_tensor.shape[1],
|
| 1155 |
+
),
|
| 1156 |
+
)
|
| 1157 |
+
# Fold filter for unity stride.
|
| 1158 |
+
filter_pyt_padded_folded = torch.zeros(
|
| 1159 |
+
[
|
| 1160 |
+
filter_pyt_padded.shape[0],
|
| 1161 |
+
C * stride_h * stride_w,
|
| 1162 |
+
(int)(filter_pyt_padded.shape[2] / stride_h),
|
| 1163 |
+
(int)(filter_pyt_padded.shape[3] / stride_w),
|
| 1164 |
+
]
|
| 1165 |
+
)
|
| 1166 |
+
for h in range(0, filter_pyt_padded.shape[2], stride_h):
|
| 1167 |
+
for w in range(0, filter_pyt_padded.shape[3], stride_w):
|
| 1168 |
+
folded_h = (int)(h / stride_h)
|
| 1169 |
+
folded_w = (int)(w / stride_w)
|
| 1170 |
+
for i in range(4):
|
| 1171 |
+
start_c = i * C
|
| 1172 |
+
filter_pyt_padded_folded[:, start_c : start_c + C, folded_h, folded_w] = filter_pyt_padded[
|
| 1173 |
+
:, :, h + (int)(i / stride_w), w + (int)(i % stride_w)
|
| 1174 |
+
]
|
| 1175 |
+
return filter_pyt_padded_folded
|
| 1176 |
+
|
| 1177 |
+
|
| 1178 |
+
# produces a tensor where each element in a page is the page number
|
| 1179 |
+
# this tensor is easy to debug and visualize
|
| 1180 |
+
def get_debug_tensor(num_pages_width, num_pages_height, dtype, page_width=32, page_height=32):
|
| 1181 |
+
torch_tensor = None
|
| 1182 |
+
for row_idx in range(0, int(num_pages_height)):
|
| 1183 |
+
tile_row = None
|
| 1184 |
+
for col_idx in range(0, int(num_pages_width)):
|
| 1185 |
+
tile_idx = col_idx + num_pages_width * row_idx
|
| 1186 |
+
tile = torch.full((1, 1, page_width, page_height), tile_idx + 1, dtype=dtype)
|
| 1187 |
+
if tile_row == None:
|
| 1188 |
+
tile_row = tile
|
| 1189 |
+
else:
|
| 1190 |
+
tile_row = torch.cat((tile_row, tile), 3)
|
| 1191 |
+
if torch_tensor == None:
|
| 1192 |
+
torch_tensor = tile_row
|
| 1193 |
+
else:
|
| 1194 |
+
torch_tensor = torch.cat((torch_tensor, tile_row), 2)
|
| 1195 |
+
|
| 1196 |
+
return torch_tensor
|
| 1197 |
+
|
| 1198 |
+
|
| 1199 |
+
# ── transformers 5.x Cache API compatibility ────────────────────────────────
|
| 1200 |
+
# transformers 5.x removed the legacy Cache API: DynamicCache no longer exposes
|
| 1201 |
+
# from_legacy_cache / to_legacy_cache / key_cache / value_cache (per-layer KV now
|
| 1202 |
+
# lives at cache.layers[i].keys/.values). These helpers work on both 4.x and 5.x.
|
| 1203 |
+
def hf_cache_layer_kv(cache, layer_idx):
|
| 1204 |
+
"""Return (key, value) tensors for a layer of a transformers Cache.
|
| 1205 |
+
|
| 1206 |
+
Handles the legacy tuple-of-tuples past_key_values, transformers <5 Cache
|
| 1207 |
+
(key_cache/value_cache), and transformers >=5 Cache (layers[i].keys/.values).
|
| 1208 |
+
"""
|
| 1209 |
+
if isinstance(cache, (tuple, list)): # legacy tuple-of-tuples past_key_values
|
| 1210 |
+
return cache[layer_idx][0], cache[layer_idx][1]
|
| 1211 |
+
if hasattr(cache, "key_cache"): # transformers < 5.x Cache
|
| 1212 |
+
return cache.key_cache[layer_idx], cache.value_cache[layer_idx]
|
| 1213 |
+
layer = cache.layers[layer_idx] # transformers >= 5.x Cache
|
| 1214 |
+
return layer.keys, layer.values
|
| 1215 |
+
|
| 1216 |
+
|
| 1217 |
+
def hf_cache_to_legacy(cache):
|
| 1218 |
+
"""Export a transformers Cache to the legacy tuple-of-(key, value) format."""
|
| 1219 |
+
if hasattr(cache, "to_legacy_cache"): # transformers < 5.x
|
| 1220 |
+
return cache.to_legacy_cache()
|
| 1221 |
+
return tuple((layer.keys, layer.values) for layer in cache.layers) # transformers >= 5.x
|
| 1222 |
+
|
| 1223 |
+
|
| 1224 |
+
def hf_dynamic_cache_from_legacy(layer_kvs):
|
| 1225 |
+
"""Build a transformers DynamicCache from per-layer (key, value) tuples."""
|
| 1226 |
+
from transformers import DynamicCache
|
| 1227 |
+
|
| 1228 |
+
layer_kvs = tuple(layer_kvs)
|
| 1229 |
+
if hasattr(DynamicCache, "from_legacy_cache"): # transformers < 5.x
|
| 1230 |
+
return DynamicCache.from_legacy_cache(layer_kvs)
|
| 1231 |
+
return DynamicCache(layer_kvs) # transformers >= 5.x
|
| 1232 |
+
|
| 1233 |
+
|
| 1234 |
+
def hf_cache_num_layers(cache):
|
| 1235 |
+
"""Number of populated layers in a transformers Cache (version-tolerant)."""
|
| 1236 |
+
return len(cache.key_cache) if hasattr(cache, "key_cache") else len(cache.layers)
|
| 1237 |
+
|
| 1238 |
+
|
| 1239 |
+
def hf_empty_encoder_decoder_cache():
|
| 1240 |
+
"""Create an empty transformers EncoderDecoderCache (version-tolerant)."""
|
| 1241 |
+
from transformers import DynamicCache, EncoderDecoderCache
|
| 1242 |
+
|
| 1243 |
+
if hasattr(EncoderDecoderCache, "from_legacy_cache"): # transformers < 5.x
|
| 1244 |
+
return EncoderDecoderCache.from_legacy_cache(None)
|
| 1245 |
+
return EncoderDecoderCache(DynamicCache(), DynamicCache()) # transformers >= 5.x
|
| 1246 |
+
|
| 1247 |
+
|
| 1248 |
+
def copy_to_buffer(src: "ttnn.Tensor", dst: "ttnn.Tensor", target_dtype) -> None:
|
| 1249 |
+
"""Convert ``src`` to ``dst``'s layout/dtype/shape/memcfg and write it into
|
| 1250 |
+
``dst``. ``dst``'s device buffer is preserved (no reallocation) so any
|
| 1251 |
+
captured trace and the DRAM prefetcher's recorded buffer addresses remain
|
| 1252 |
+
valid. The final ``ttnn.to_memory_config`` with ``output_tensor=dst`` both
|
| 1253 |
+
reshards to ``dst``'s memory config and copies into ``dst``'s buffer.
|
| 1254 |
+
"""
|
| 1255 |
+
converted = src
|
| 1256 |
+
|
| 1257 |
+
if converted.layout != dst.layout:
|
| 1258 |
+
converted = ttnn.to_layout(converted, layout=dst.layout)
|
| 1259 |
+
|
| 1260 |
+
if converted.dtype != target_dtype:
|
| 1261 |
+
converted = ttnn.typecast(converted, dtype=target_dtype)
|
| 1262 |
+
|
| 1263 |
+
if tuple(converted.shape) != tuple(dst.shape):
|
| 1264 |
+
converted = ttnn.reshape(converted, list(dst.shape))
|
| 1265 |
+
|
| 1266 |
+
ttnn.to_memory_config(converted, dst.memory_config(), output_tensor=dst)
|
code/models/experimental/gr00t/__init__.py
ADDED
|
File without changes
|
code/models/experimental/gr00t/reference/__init__.py
ADDED
|
@@ -0,0 +1,4 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
|
| 4 |
+
"""CPU torch reference implementations of the GR00T N1.5 / N1.6 / N1.7 components (populated by later tasks)."""
|
code/models/experimental/gr00t/reference/action_head.py
ADDED
|
@@ -0,0 +1,1093 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
|
| 4 |
+
"""CPU fp32 torch reference of the GR00T N1.5 / N1.6 / N1.7 action head (VL adapter, encoders, DiT, decoder).
|
| 5 |
+
|
| 6 |
+
The modules are organised the way the future device modules are (``01-architecture-synthesis.md`` §2.1 / §2.3):
|
| 7 |
+
|
| 8 |
+
* :class:`VLAdapter` ``vlln`` LayerNorm + 0 / 4 :class:`VLSelfAttentionBlock` -- once per inference (§1.4).
|
| 9 |
+
* :class:`EmbodimentLinear` one slot ``e`` of ``CategorySpecificLinear``: ``y = x @ W[e] + b[e]`` with ``W[e]`` in
|
| 10 |
+
``[in, out]`` orientation -- no transpose (``weight-loader-spec.md`` §4.7, arch-n15 §3.1).
|
| 11 |
+
* :class:`EmbodimentMLP` state encoder / action decoder (``layer2(relu(layer1(x)))``, §1.6).
|
| 12 |
+
* :class:`ActionEncoder` ``W1`` -> ``cat[a, tau]`` -> ``W2`` -> swish -> ``W3`` with the 1536-d sinusoid of the
|
| 13 |
+
integer bucket (arch-n15 §3.3, arch-n16 §7.2); the position rows are added by the head.
|
| 14 |
+
* :class:`TimestepEncoder` diffusers ``Timesteps(256, flip_sin_to_cos, shift 1)`` -> Linear -> SiLU -> Linear (§1.5).
|
| 15 |
+
* :class:`DiTBlock` AdaLN (``norm1.linear.chunk(2) = (scale, shift)``, attention branch only, ungated) ->
|
| 16 |
+
cross / self attention (32 x 48) -> plain non-affine LN -> FF 6144 GELU-tanh (§1.5, C6).
|
| 17 |
+
* :class:`DiTOutputHead` ``LN(eps 1e-6) * (1 + scale) + shift`` with ``proj_out_1.chunk(2) = (shift, scale)`` --
|
| 18 |
+
the opposite order to the blocks -- then ``proj_out_2`` (§1.5).
|
| 19 |
+
* :class:`DiT` the interleaved stack with the cross-attention key-set selector (``all`` for N1.5;
|
| 20 |
+
``idx % 4 == 0`` -> non-image, ``idx % 4 == 2`` -> image for N1.6 / N1.7; arch-n16 §7.4,
|
| 21 |
+
arch-n17 §3.3) in the reference *mask* form and in the *gather + hoisted K/V* form.
|
| 22 |
+
* :class:`ActionHead` everything above plus position rows, N1.5 future tokens, the decoder and the tap plumbing.
|
| 23 |
+
|
| 24 |
+
Weights are read from the RAW checkpoint keys through :class:`~models.experimental.gr00t.common.checkpoint.LazyCheckpoint`
|
| 25 |
+
(``nn.Linear`` layout ``[out, in]`` consumed with ``F.linear``; embodiment slots ``[in, out]`` consumed with ``@``), upcast
|
| 26 |
+
bf16 -> fp32 exactly. Every ``action_head.*`` key of the checkpoint must be consumed, and every shape is checked against
|
| 27 |
+
:mod:`~models.experimental.gr00t.common.configs`; nothing falls back silently.
|
| 28 |
+
|
| 29 |
+
Optional head padding 48 -> 64 (``static-shape-plan`` D5, ``weight-loader-spec.md`` §4.6) is available through
|
| 30 |
+
:meth:`DiT.set_head_dim_pad`; the softmax scale stays the *logical* ``48 ** -0.5`` and is always passed explicitly.
|
| 31 |
+
|
| 32 |
+
No ``ttnn`` import anywhere in this module.
|
| 33 |
+
"""
|
| 34 |
+
|
| 35 |
+
from __future__ import annotations
|
| 36 |
+
|
| 37 |
+
import math
|
| 38 |
+
from dataclasses import dataclass
|
| 39 |
+
from typing import Dict, List, Optional, Sequence, Set, Tuple
|
| 40 |
+
|
| 41 |
+
import torch
|
| 42 |
+
import torch.nn.functional as F
|
| 43 |
+
from torch import Tensor, nn
|
| 44 |
+
|
| 45 |
+
from models.experimental.gr00t.common.checkpoint import LazyCheckpoint
|
| 46 |
+
from models.experimental.gr00t.common.configs import DiTConfig, EncoderConfig, GR00TConfig, VLAdapterConfig, get_config
|
| 47 |
+
|
| 48 |
+
# "mask" = reference form (K/V over all S tokens + boolean key mask); "gather" = K/V over the selected tokens only.
|
| 49 |
+
CrossForm = str
|
| 50 |
+
CROSS_FORMS: Tuple[str, ...] = ("mask", "gather")
|
| 51 |
+
KEY_SUBSETS: Tuple[str, ...] = ("all", "text", "image")
|
| 52 |
+
|
| 53 |
+
|
| 54 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 55 |
+
# Functional pieces
|
| 56 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
def gelu_tanh(x: Tensor) -> Tensor:
|
| 60 |
+
"""diffusers ``FeedForward(activation_fn="gelu-approximate")`` = ``F.gelu(approximate="tanh")`` (arch-n17 §3.3)."""
|
| 61 |
+
return F.gelu(x, approximate="tanh")
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def swish(x: Tensor) -> Tensor:
|
| 65 |
+
"""``swish(x) = x * sigmoid(x)`` of the action encoder (arch-n15 §3.3)."""
|
| 66 |
+
return x * torch.sigmoid(x)
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
def sinusoidal_tau_encoding(t_bucket: int, dim: int = 1536, max_period: float = 10000.0) -> Tensor:
|
| 70 |
+
"""1536-d sinusoid of the integer timestep bucket fed to the action encoder (arch-n15 §3.3, arch-n16 §7.2).
|
| 71 |
+
|
| 72 |
+
``half = dim // 2``; ``exponent_i = -i * ln(max_period) / half``; ``enc = [sin(t * exp(exponent)), cos(...)]``
|
| 73 |
+
(sin first) -- computed in fp32 exactly like ``SinusoidalPositionalEncoding.forward``. This is *not* the DiT
|
| 74 |
+
timestep projection (:func:`timestep_projection`), which has 256 channels, a ``half - 1`` divisor and cos first.
|
| 75 |
+
"""
|
| 76 |
+
if dim % 2 != 0:
|
| 77 |
+
raise ValueError(f"tau dim must be even, got {dim}")
|
| 78 |
+
half = dim // 2
|
| 79 |
+
log_scale = torch.log(torch.tensor(float(max_period), dtype=torch.float32)) / half
|
| 80 |
+
exponent = -torch.arange(half, dtype=torch.float32) * log_scale
|
| 81 |
+
freqs = torch.tensor(float(t_bucket), dtype=torch.float32) * torch.exp(exponent)
|
| 82 |
+
return torch.cat([torch.sin(freqs), torch.cos(freqs)])
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
def timestep_projection(
|
| 86 |
+
t_bucket: int,
|
| 87 |
+
dim: int = 256,
|
| 88 |
+
flip_sin_to_cos: bool = True,
|
| 89 |
+
downscale_freq_shift: int = 1,
|
| 90 |
+
max_period: float = 10000.0,
|
| 91 |
+
) -> Tensor:
|
| 92 |
+
"""diffusers ``get_timestep_embedding`` as used by ``Timesteps(256, flip_sin_to_cos=True, downscale_freq_shift=1)``
|
| 93 |
+
(weight-loader-spec.md §4.6): ``e = t * exp(-ln(max_period) * arange(half) / (half - shift))``; ``[sin e, cos e]``
|
| 94 |
+
flipped to ``[cos e, sin e]``. Returns ``[1, dim]`` fp32. Sanity: ``t = 0`` -> first 128 entries 1.0, rest 0.0.
|
| 95 |
+
"""
|
| 96 |
+
half = dim // 2
|
| 97 |
+
exponent = -math.log(max_period) * torch.arange(0, half, dtype=torch.float32)
|
| 98 |
+
exponent = exponent / (half - downscale_freq_shift)
|
| 99 |
+
emb = torch.exp(exponent)
|
| 100 |
+
emb = torch.tensor([float(t_bucket)], dtype=torch.float32)[:, None] * emb[None, :]
|
| 101 |
+
emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=-1)
|
| 102 |
+
if flip_sin_to_cos:
|
| 103 |
+
emb = torch.cat([emb[:, half:], emb[:, :half]], dim=-1)
|
| 104 |
+
return emb
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
def _check_shape(name: str, t: Tensor, shape: Sequence[int]) -> None:
|
| 108 |
+
if tuple(t.shape) != tuple(shape):
|
| 109 |
+
raise ValueError(f"{name}: expected shape {tuple(shape)}, got {tuple(t.shape)}")
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
def _fp32(t: Tensor) -> Tensor:
|
| 113 |
+
if not t.is_floating_point():
|
| 114 |
+
raise TypeError(f"expected a floating tensor, got {t.dtype}")
|
| 115 |
+
return t.to(torch.float32)
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 119 |
+
# Leaf modules
|
| 120 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
class Linear(nn.Module):
|
| 124 |
+
"""``nn.Linear`` in the raw checkpoint layout: ``weight [out, in]``, ``bias [out]``; ``y = F.linear(x, W, b)``."""
|
| 125 |
+
|
| 126 |
+
def __init__(self, weight: Tensor, bias: Tensor):
|
| 127 |
+
super().__init__()
|
| 128 |
+
if weight.ndim != 2 or bias.ndim != 1 or bias.shape[0] != weight.shape[0]:
|
| 129 |
+
raise ValueError(f"Linear: weight {tuple(weight.shape)} / bias {tuple(bias.shape)} mismatch")
|
| 130 |
+
self.register_buffer("weight", _fp32(weight).contiguous())
|
| 131 |
+
self.register_buffer("bias", _fp32(bias).contiguous())
|
| 132 |
+
|
| 133 |
+
@property
|
| 134 |
+
def in_features(self) -> int:
|
| 135 |
+
return int(self.weight.shape[1])
|
| 136 |
+
|
| 137 |
+
@property
|
| 138 |
+
def out_features(self) -> int:
|
| 139 |
+
return int(self.weight.shape[0])
|
| 140 |
+
|
| 141 |
+
@classmethod
|
| 142 |
+
def from_checkpoint(cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], shape: Tuple[int, int]) -> "Linear":
|
| 143 |
+
wk, bk = prefix + ".weight", prefix + ".bias"
|
| 144 |
+
w = ck.get(wk, torch.float32)
|
| 145 |
+
b = ck.get(bk, torch.float32)
|
| 146 |
+
_check_shape(wk, w, shape)
|
| 147 |
+
_check_shape(bk, b, (shape[0],))
|
| 148 |
+
consumed.update((wk, bk))
|
| 149 |
+
return cls(w, b)
|
| 150 |
+
|
| 151 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 152 |
+
return F.linear(x, self.weight, self.bias)
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
class LayerNorm(nn.Module):
|
| 156 |
+
"""LayerNorm over the last dim; affine (``vlln``, VL-SA norms) or plain (DiT ``norm1`` inner LN, ``norm3``, ``norm_out``)."""
|
| 157 |
+
|
| 158 |
+
def __init__(self, dim: int, eps: float, weight: Optional[Tensor] = None, bias: Optional[Tensor] = None):
|
| 159 |
+
super().__init__()
|
| 160 |
+
self.dim = dim
|
| 161 |
+
self.eps = eps
|
| 162 |
+
if (weight is None) != (bias is None):
|
| 163 |
+
raise ValueError("LayerNorm: weight and bias must both be given or both be absent")
|
| 164 |
+
if weight is not None:
|
| 165 |
+
_check_shape("LayerNorm.weight", weight, (dim,))
|
| 166 |
+
_check_shape("LayerNorm.bias", bias, (dim,))
|
| 167 |
+
self.register_buffer("weight", _fp32(weight).contiguous())
|
| 168 |
+
self.register_buffer("bias", _fp32(bias).contiguous())
|
| 169 |
+
else:
|
| 170 |
+
self.weight = None
|
| 171 |
+
self.bias = None
|
| 172 |
+
|
| 173 |
+
@property
|
| 174 |
+
def affine(self) -> bool:
|
| 175 |
+
return self.weight is not None
|
| 176 |
+
|
| 177 |
+
@classmethod
|
| 178 |
+
def from_checkpoint(cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], dim: int, eps: float) -> "LayerNorm":
|
| 179 |
+
wk, bk = prefix + ".weight", prefix + ".bias"
|
| 180 |
+
w = ck.get(wk, torch.float32)
|
| 181 |
+
b = ck.get(bk, torch.float32)
|
| 182 |
+
consumed.update((wk, bk))
|
| 183 |
+
return cls(dim, eps, w, b)
|
| 184 |
+
|
| 185 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 186 |
+
if x.shape[-1] != self.dim:
|
| 187 |
+
raise ValueError(f"LayerNorm({self.dim}): got last dim {x.shape[-1]}")
|
| 188 |
+
return F.layer_norm(x, (self.dim,), self.weight, self.bias, self.eps)
|
| 189 |
+
|
| 190 |
+
|
| 191 |
+
class EmbodimentLinear(nn.Module):
|
| 192 |
+
"""One embodiment slot of ``CategorySpecificLinear`` (``flow_matching_action_head.py:30-42``,
|
| 193 |
+
``embodiment_conditioned_mlp.py:59-79``): ``W[e] [in, out]``, ``b[e] [out]``; ``y = x @ W[e] + b[e]``.
|
| 194 |
+
|
| 195 |
+
The slot is read with ``LazyCheckpoint.slot`` so only ``1/32`` of the ``[32, in, out]`` tensor is touched
|
| 196 |
+
(weight-loader-spec.md §1.2 / §4.7). The orientation is ``[in, out]`` -- **not** transposed (§4.7, VERIFIED).
|
| 197 |
+
"""
|
| 198 |
+
|
| 199 |
+
def __init__(self, W: Tensor, b: Tensor, embodiment_id: int):
|
| 200 |
+
super().__init__()
|
| 201 |
+
if W.ndim != 2 or b.ndim != 1 or b.shape[0] != W.shape[1]:
|
| 202 |
+
raise ValueError(f"EmbodimentLinear: W {tuple(W.shape)} / b {tuple(b.shape)} mismatch")
|
| 203 |
+
self.embodiment_id = int(embodiment_id)
|
| 204 |
+
self.register_buffer("W", _fp32(W).contiguous())
|
| 205 |
+
self.register_buffer("b", _fp32(b).contiguous())
|
| 206 |
+
|
| 207 |
+
@property
|
| 208 |
+
def in_features(self) -> int:
|
| 209 |
+
return int(self.W.shape[0])
|
| 210 |
+
|
| 211 |
+
@property
|
| 212 |
+
def out_features(self) -> int:
|
| 213 |
+
return int(self.W.shape[1])
|
| 214 |
+
|
| 215 |
+
@classmethod
|
| 216 |
+
def from_checkpoint(
|
| 217 |
+
cls,
|
| 218 |
+
ck: LazyCheckpoint,
|
| 219 |
+
prefix: str,
|
| 220 |
+
embodiment_id: int,
|
| 221 |
+
consumed: Set[str],
|
| 222 |
+
shape: Tuple[int, int],
|
| 223 |
+
max_num_embodiments: int,
|
| 224 |
+
) -> "EmbodimentLinear":
|
| 225 |
+
wk, bk = prefix + ".W", prefix + ".b"
|
| 226 |
+
_check_shape(wk, torch.empty(ck.shape(wk)), (max_num_embodiments,) + tuple(shape))
|
| 227 |
+
_check_shape(bk, torch.empty(ck.shape(bk)), (max_num_embodiments, shape[1]))
|
| 228 |
+
W = ck.slot(wk, embodiment_id, torch.float32)
|
| 229 |
+
b = ck.slot(bk, embodiment_id, torch.float32)
|
| 230 |
+
consumed.update((wk, bk))
|
| 231 |
+
return cls(W, b, embodiment_id)
|
| 232 |
+
|
| 233 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 234 |
+
if x.shape[-1] != self.in_features:
|
| 235 |
+
raise ValueError(f"EmbodimentLinear: input width {x.shape[-1]} != {self.in_features}")
|
| 236 |
+
return x @ self.W + self.b
|
| 237 |
+
|
| 238 |
+
|
| 239 |
+
class EmbodimentMLP(nn.Module):
|
| 240 |
+
"""``CategorySpecificMLP`` slot: ``layer2(relu(layer1(x)))`` (state encoder, action decoder; synthesis §1.6)."""
|
| 241 |
+
|
| 242 |
+
def __init__(self, layer1: EmbodimentLinear, layer2: EmbodimentLinear):
|
| 243 |
+
super().__init__()
|
| 244 |
+
if layer1.out_features != layer2.in_features:
|
| 245 |
+
raise ValueError("EmbodimentMLP: layer widths do not chain")
|
| 246 |
+
self.layer1 = layer1
|
| 247 |
+
self.layer2 = layer2
|
| 248 |
+
|
| 249 |
+
@classmethod
|
| 250 |
+
def from_checkpoint(
|
| 251 |
+
cls,
|
| 252 |
+
ck: LazyCheckpoint,
|
| 253 |
+
prefix: str,
|
| 254 |
+
embodiment_id: int,
|
| 255 |
+
consumed: Set[str],
|
| 256 |
+
dims: Tuple[int, int, int],
|
| 257 |
+
max_num_embodiments: int,
|
| 258 |
+
) -> "EmbodimentMLP":
|
| 259 |
+
l1 = EmbodimentLinear.from_checkpoint(
|
| 260 |
+
ck, prefix + "layer1", embodiment_id, consumed, dims[:2], max_num_embodiments
|
| 261 |
+
)
|
| 262 |
+
l2 = EmbodimentLinear.from_checkpoint(
|
| 263 |
+
ck, prefix + "layer2", embodiment_id, consumed, dims[1:], max_num_embodiments
|
| 264 |
+
)
|
| 265 |
+
return cls(l1, l2)
|
| 266 |
+
|
| 267 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 268 |
+
return self.layer2(F.relu(self.layer1(x)))
|
| 269 |
+
|
| 270 |
+
|
| 271 |
+
class ActionEncoder(nn.Module):
|
| 272 |
+
"""``MultiEmbodimentActionEncoder`` slot (arch-n15 §3.3, arch-n16 §7.2, arch-n17 §3.1)::
|
| 273 |
+
|
| 274 |
+
a = actions @ W1 + b1 # [B, H, D_action] -> [B, H, 1536]
|
| 275 |
+
tau = sinusoid_1536(t_bucket) # fp32, broadcast over H (sin first)
|
| 276 |
+
h = swish(cat[a, tau] @ W2 + b2) # [B, H, 3072] -> [B, H, 1536]
|
| 277 |
+
out = h @ W3 + b3 # [B, H, 1536] (BEFORE the position-embedding add)
|
| 278 |
+
"""
|
| 279 |
+
|
| 280 |
+
def __init__(
|
| 281 |
+
self, W1: EmbodimentLinear, W2: EmbodimentLinear, W3: EmbodimentLinear, tau_dim: int, tau_max_period: float
|
| 282 |
+
):
|
| 283 |
+
super().__init__()
|
| 284 |
+
if W2.in_features != W1.out_features + tau_dim or W3.in_features != W2.out_features:
|
| 285 |
+
raise ValueError("ActionEncoder: W1/W2/W3 widths do not chain")
|
| 286 |
+
self.W1, self.W2, self.W3 = W1, W2, W3
|
| 287 |
+
self.tau_dim = tau_dim
|
| 288 |
+
self.tau_max_period = tau_max_period
|
| 289 |
+
|
| 290 |
+
@classmethod
|
| 291 |
+
def from_checkpoint(
|
| 292 |
+
cls, ck: LazyCheckpoint, prefix: str, embodiment_id: int, consumed: Set[str], enc: EncoderConfig
|
| 293 |
+
) -> "ActionEncoder":
|
| 294 |
+
e, n = embodiment_id, enc.max_num_embodiments
|
| 295 |
+
W1 = EmbodimentLinear.from_checkpoint(ck, prefix + "W1", e, consumed, enc.action_encoder_w1, n)
|
| 296 |
+
W2 = EmbodimentLinear.from_checkpoint(ck, prefix + "W2", e, consumed, enc.action_encoder_w2, n)
|
| 297 |
+
W3 = EmbodimentLinear.from_checkpoint(ck, prefix + "W3", e, consumed, enc.action_encoder_w3, n)
|
| 298 |
+
if enc.tau_order != ("sin", "cos"):
|
| 299 |
+
raise ValueError(f"unsupported tau order {enc.tau_order}")
|
| 300 |
+
return cls(W1, W2, W3, enc.tau_dim, enc.tau_max_period)
|
| 301 |
+
|
| 302 |
+
def tau(self, t_bucket: int) -> Tensor:
|
| 303 |
+
return sinusoidal_tau_encoding(t_bucket, self.tau_dim, self.tau_max_period)
|
| 304 |
+
|
| 305 |
+
def forward(self, actions: Tensor, t_bucket: int) -> Tensor:
|
| 306 |
+
if actions.ndim != 3:
|
| 307 |
+
raise ValueError(f"actions must be [B, H, D], got {tuple(actions.shape)}")
|
| 308 |
+
a = self.W1(actions)
|
| 309 |
+
tau = self.tau(t_bucket).to(a.dtype)[None, None, :].expand(a.shape[0], a.shape[1], -1)
|
| 310 |
+
h = swish(self.W2(torch.cat([a, tau], dim=-1)))
|
| 311 |
+
return self.W3(h)
|
| 312 |
+
|
| 313 |
+
|
| 314 |
+
class FeedForward(nn.Module):
|
| 315 |
+
"""diffusers ``FeedForward``: ``net.0.proj`` Linear -> GELU(tanh) -> ``net.2`` Linear (VL-SA 8192, DiT 6144)."""
|
| 316 |
+
|
| 317 |
+
def __init__(self, proj: Linear, out: Linear):
|
| 318 |
+
super().__init__()
|
| 319 |
+
if proj.out_features != out.in_features or proj.in_features != out.out_features:
|
| 320 |
+
raise ValueError("FeedForward: widths do not chain")
|
| 321 |
+
self.proj = proj
|
| 322 |
+
self.out = out
|
| 323 |
+
|
| 324 |
+
@classmethod
|
| 325 |
+
def from_checkpoint(
|
| 326 |
+
cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], dim: int, inner: int
|
| 327 |
+
) -> "FeedForward":
|
| 328 |
+
proj = Linear.from_checkpoint(ck, prefix + "net.0.proj", consumed, (inner, dim))
|
| 329 |
+
out = Linear.from_checkpoint(ck, prefix + "net.2", consumed, (dim, inner))
|
| 330 |
+
return cls(proj, out)
|
| 331 |
+
|
| 332 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 333 |
+
return self.out(gelu_tanh(self.proj(x)))
|
| 334 |
+
|
| 335 |
+
|
| 336 |
+
class MultiHeadAttention(nn.Module):
|
| 337 |
+
"""diffusers ``Attention`` + ``AttnProcessor2_0`` in fp32: ``to_q/to_k/to_v`` (+bias) -> heads -> SDPA -> ``to_out.0``.
|
| 338 |
+
|
| 339 |
+
``head_dim`` is the *logical* head width (48 for the DiT, 64 for VL-SA) and fixes the softmax scale
|
| 340 |
+
``head_dim ** -0.5``. :meth:`set_head_dim_pad` re-lays the weights per head to a wider storage width
|
| 341 |
+
(48 -> 64, weight-loader-spec.md §4.6 rows to_q/to_k/to_v/to_out) while the scale stays the logical one
|
| 342 |
+
(static-shape-plan D5); zero-padded key dims contribute nothing to the logits and zero V columns meet zero
|
| 343 |
+
``to_out`` columns, so the result is unchanged up to fp32 rounding.
|
| 344 |
+
|
| 345 |
+
The K/V side is exposed separately (:meth:`project_kv`, :meth:`attend`) so that the DiT cross blocks can hoist
|
| 346 |
+
their K/V out of the denoising loop (arch-n15 §3.6, arch-n17 §3.3).
|
| 347 |
+
"""
|
| 348 |
+
|
| 349 |
+
def __init__(self, to_q: Linear, to_k: Linear, to_v: Linear, to_out: Linear, n_heads: int, head_dim: int):
|
| 350 |
+
super().__init__()
|
| 351 |
+
inner = n_heads * head_dim
|
| 352 |
+
for name, lin in (("to_q", to_q), ("to_k", to_k), ("to_v", to_v)):
|
| 353 |
+
if lin.out_features != inner:
|
| 354 |
+
raise ValueError(f"{name}: out {lin.out_features} != heads*head_dim {inner}")
|
| 355 |
+
if to_out.in_features != inner:
|
| 356 |
+
raise ValueError(f"to_out: in {to_out.in_features} != {inner}")
|
| 357 |
+
if to_k.in_features != to_v.in_features:
|
| 358 |
+
raise ValueError("to_k / to_v input widths differ")
|
| 359 |
+
self.to_q, self.to_k, self.to_v, self.to_out = to_q, to_k, to_v, to_out
|
| 360 |
+
self.n_heads = n_heads
|
| 361 |
+
self.head_dim = head_dim # logical
|
| 362 |
+
self.head_dim_pad = head_dim # storage width of each head in the buffers
|
| 363 |
+
self.scale = float(head_dim) ** -0.5
|
| 364 |
+
|
| 365 |
+
@property
|
| 366 |
+
def kv_dim(self) -> int:
|
| 367 |
+
return self.to_k.in_features
|
| 368 |
+
|
| 369 |
+
@classmethod
|
| 370 |
+
def from_checkpoint(
|
| 371 |
+
cls,
|
| 372 |
+
ck: LazyCheckpoint,
|
| 373 |
+
prefix: str,
|
| 374 |
+
consumed: Set[str],
|
| 375 |
+
query_dim: int,
|
| 376 |
+
kv_dim: int,
|
| 377 |
+
n_heads: int,
|
| 378 |
+
head_dim: int,
|
| 379 |
+
) -> "MultiHeadAttention":
|
| 380 |
+
inner = n_heads * head_dim
|
| 381 |
+
to_q = Linear.from_checkpoint(ck, prefix + "to_q", consumed, (inner, query_dim))
|
| 382 |
+
to_k = Linear.from_checkpoint(ck, prefix + "to_k", consumed, (inner, kv_dim))
|
| 383 |
+
to_v = Linear.from_checkpoint(ck, prefix + "to_v", consumed, (inner, kv_dim))
|
| 384 |
+
to_out = Linear.from_checkpoint(ck, prefix + "to_out.0", consumed, (query_dim, inner))
|
| 385 |
+
return cls(to_q, to_k, to_v, to_out, n_heads, head_dim)
|
| 386 |
+
|
| 387 |
+
# ------------------------------------------------------------------ head padding (weight-loader §4.6)
|
| 388 |
+
def set_head_dim_pad(self, pad: int) -> None:
|
| 389 |
+
"""Re-lay q/k/v out-axis and to_out in-axis per head to ``pad`` columns (zero filled); reversible."""
|
| 390 |
+
if pad < self.head_dim:
|
| 391 |
+
raise ValueError(f"head_dim_pad {pad} < logical head_dim {self.head_dim}")
|
| 392 |
+
cur = self.head_dim_pad
|
| 393 |
+
if pad == cur:
|
| 394 |
+
return
|
| 395 |
+
extra = pad - self.head_dim
|
| 396 |
+
for lin in (self.to_q, self.to_k, self.to_v):
|
| 397 |
+
w = lin.weight.reshape(self.n_heads, cur, lin.in_features)[:, : self.head_dim]
|
| 398 |
+
b = lin.bias.reshape(self.n_heads, cur)[:, : self.head_dim]
|
| 399 |
+
lin.weight = F.pad(w, (0, 0, 0, extra)).reshape(self.n_heads * pad, lin.in_features).contiguous()
|
| 400 |
+
lin.bias = F.pad(b, (0, extra)).reshape(self.n_heads * pad).contiguous()
|
| 401 |
+
wo = self.to_out.weight.reshape(self.to_out.out_features, self.n_heads, cur)[:, :, : self.head_dim]
|
| 402 |
+
self.to_out.weight = F.pad(wo, (0, extra)).reshape(self.to_out.out_features, self.n_heads * pad).contiguous()
|
| 403 |
+
self.head_dim_pad = pad
|
| 404 |
+
|
| 405 |
+
# ------------------------------------------------------------------ pieces
|
| 406 |
+
def _heads(self, x: Tensor) -> Tensor:
|
| 407 |
+
b, n, _ = x.shape
|
| 408 |
+
return x.view(b, n, self.n_heads, self.head_dim_pad).transpose(1, 2)
|
| 409 |
+
|
| 410 |
+
def project_q(self, x: Tensor) -> Tensor:
|
| 411 |
+
return self._heads(self.to_q(x))
|
| 412 |
+
|
| 413 |
+
def project_kv(self, kv: Tensor) -> Tuple[Tensor, Tensor]:
|
| 414 |
+
"""``(K, V)`` as ``[B, heads, L, head_dim_pad]`` from the key/value source rows."""
|
| 415 |
+
if kv.shape[-1] != self.kv_dim:
|
| 416 |
+
raise ValueError(f"key/value source width {kv.shape[-1]} != {self.kv_dim}")
|
| 417 |
+
return self._heads(self.to_k(kv)), self._heads(self.to_v(kv))
|
| 418 |
+
|
| 419 |
+
def attend(self, q: Tensor, k: Tensor, v: Tensor, key_mask: Optional[Tensor] = None) -> Tensor:
|
| 420 |
+
"""SDPA with the explicit logical scale; ``key_mask`` is a bool ``[B, L]`` (True = attend) or None."""
|
| 421 |
+
attn_mask = None
|
| 422 |
+
if key_mask is not None:
|
| 423 |
+
if key_mask.dtype != torch.bool or key_mask.ndim != 2 or key_mask.shape[-1] != k.shape[-2]:
|
| 424 |
+
raise ValueError(
|
| 425 |
+
f"key_mask must be bool [B, L={k.shape[-2]}], got {key_mask.dtype} {tuple(key_mask.shape)}"
|
| 426 |
+
)
|
| 427 |
+
if not bool(key_mask.any(dim=-1).all()):
|
| 428 |
+
raise ValueError("key_mask masks out every key of some row")
|
| 429 |
+
attn_mask = key_mask[:, None, None, :]
|
| 430 |
+
out = F.scaled_dot_product_attention(
|
| 431 |
+
q, k, v, attn_mask=attn_mask, dropout_p=0.0, is_causal=False, scale=self.scale
|
| 432 |
+
)
|
| 433 |
+
b, _, m, _ = out.shape
|
| 434 |
+
return self.to_out(out.transpose(1, 2).reshape(b, m, self.n_heads * self.head_dim_pad))
|
| 435 |
+
|
| 436 |
+
def forward(self, x: Tensor, kv: Optional[Tensor] = None, key_mask: Optional[Tensor] = None) -> Tensor:
|
| 437 |
+
"""Self attention when ``kv`` is None, cross attention on ``kv`` otherwise."""
|
| 438 |
+
q = self.project_q(x)
|
| 439 |
+
k, v = self.project_kv(x if kv is None else kv)
|
| 440 |
+
return self.attend(q, k, v, key_mask)
|
| 441 |
+
|
| 442 |
+
|
| 443 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 444 |
+
# VL adapter (vlln + VL self-attention)
|
| 445 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 446 |
+
|
| 447 |
+
|
| 448 |
+
class VLSelfAttentionBlock(nn.Module):
|
| 449 |
+
"""``BasicTransformerBlock(norm_type="layer_norm")`` of the VL self-attention transformer (arch-n15 §3.5,
|
| 450 |
+
arch-n17 §3.2): ``x += attn1(LN1(x))``; ``x += ff(LN3(x))``; LN affine eps 1e-5; 32 x 64 heads; FF 8192; no mask."""
|
| 451 |
+
|
| 452 |
+
def __init__(self, norm1: LayerNorm, attn: MultiHeadAttention, norm3: LayerNorm, ff: FeedForward):
|
| 453 |
+
super().__init__()
|
| 454 |
+
self.norm1, self.attn, self.norm3, self.ff = norm1, attn, norm3, ff
|
| 455 |
+
|
| 456 |
+
@classmethod
|
| 457 |
+
def from_checkpoint(
|
| 458 |
+
cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], cfg: VLAdapterConfig
|
| 459 |
+
) -> "VLSelfAttentionBlock":
|
| 460 |
+
norm1 = LayerNorm.from_checkpoint(ck, prefix + "norm1", consumed, cfg.dim, cfg.ln_eps)
|
| 461 |
+
attn = MultiHeadAttention.from_checkpoint(
|
| 462 |
+
ck, prefix + "attn1.", consumed, cfg.dim, cfg.dim, cfg.n_heads, cfg.head_dim
|
| 463 |
+
)
|
| 464 |
+
norm3 = LayerNorm.from_checkpoint(ck, prefix + "norm3", consumed, cfg.dim, cfg.ln_eps)
|
| 465 |
+
ff = FeedForward.from_checkpoint(ck, prefix + "ff.", consumed, cfg.dim, cfg.ff_dim)
|
| 466 |
+
return cls(norm1, attn, norm3, ff)
|
| 467 |
+
|
| 468 |
+
def forward(self, x: Tensor) -> Tensor:
|
| 469 |
+
x = x + self.attn(self.norm1(x))
|
| 470 |
+
return x + self.ff(self.norm3(x))
|
| 471 |
+
|
| 472 |
+
|
| 473 |
+
class VLAdapter(nn.Module):
|
| 474 |
+
"""``vlln`` LayerNorm(2048, eps 1e-5, affine) followed by 0 (N1.6) or 4 (N1.5 / N1.7) VL self-attention blocks
|
| 475 |
+
(synthesis §1.4). Runs once per inference; its output is the DiT ``encoder_hidden_states``."""
|
| 476 |
+
|
| 477 |
+
def __init__(self, vlln: LayerNorm, blocks: Sequence[VLSelfAttentionBlock]):
|
| 478 |
+
super().__init__()
|
| 479 |
+
self.vlln = vlln
|
| 480 |
+
self.blocks = nn.ModuleList(blocks)
|
| 481 |
+
|
| 482 |
+
@classmethod
|
| 483 |
+
def from_checkpoint(cls, ck: LazyCheckpoint, cfg: GR00TConfig, consumed: Set[str]) -> "VLAdapter":
|
| 484 |
+
vla = cfg.vl_adapter
|
| 485 |
+
vlln = LayerNorm.from_checkpoint(ck, cfg.checkpoint.vlln_prefix.rstrip("."), consumed, vla.dim, vla.vlln_eps)
|
| 486 |
+
blocks: List[VLSelfAttentionBlock] = []
|
| 487 |
+
prefix = cfg.checkpoint.vl_self_attention_prefix
|
| 488 |
+
if vla.n_blocks > 0:
|
| 489 |
+
if prefix is None:
|
| 490 |
+
raise ValueError(f"{cfg.version}: {vla.n_blocks} VL-SA blocks configured but no checkpoint prefix")
|
| 491 |
+
for i in range(vla.n_blocks):
|
| 492 |
+
blocks.append(
|
| 493 |
+
VLSelfAttentionBlock.from_checkpoint(ck, f"{prefix}transformer_blocks.{i}.", consumed, vla)
|
| 494 |
+
)
|
| 495 |
+
elif prefix is not None:
|
| 496 |
+
raise ValueError(f"{cfg.version}: VL-SA prefix configured but n_blocks == 0")
|
| 497 |
+
return cls(vlln, blocks)
|
| 498 |
+
|
| 499 |
+
def forward(self, backbone_features: Tensor, taps: Optional[Dict[str, Tensor]] = None) -> Tensor:
|
| 500 |
+
if backbone_features.ndim != 3 or backbone_features.shape[-1] != self.vlln.dim:
|
| 501 |
+
raise ValueError(f"backbone_features must be [B, S, {self.vlln.dim}], got {tuple(backbone_features.shape)}")
|
| 502 |
+
x = self.vlln(backbone_features)
|
| 503 |
+
if taps is not None:
|
| 504 |
+
taps["vlln_out"] = x
|
| 505 |
+
for i, blk in enumerate(self.blocks):
|
| 506 |
+
x = blk(x)
|
| 507 |
+
if taps is not None:
|
| 508 |
+
taps[f"vlsa_block{i}_out"] = x
|
| 509 |
+
if taps is not None:
|
| 510 |
+
if len(self.blocks) > 0:
|
| 511 |
+
taps["vl_self_attention_out"] = x
|
| 512 |
+
taps["dit_encoder_hidden_states"] = x
|
| 513 |
+
return x
|
| 514 |
+
|
| 515 |
+
|
| 516 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 517 |
+
# DiT
|
| 518 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 519 |
+
|
| 520 |
+
|
| 521 |
+
class TimestepEncoder(nn.Module):
|
| 522 |
+
"""``TimestepEncoder`` (cross_attention_dit.py:31-41 / dit.py:61-71): ``Timesteps(256, flip, shift 1)`` ->
|
| 523 |
+
``linear_1`` (256 -> 1536) -> SiLU -> ``linear_2`` (1536 -> 1536) -> ``temb [1, 1536]`` shared by every block."""
|
| 524 |
+
|
| 525 |
+
def __init__(self, linear_1: Linear, linear_2: Linear, cfg: DiTConfig):
|
| 526 |
+
super().__init__()
|
| 527 |
+
self.linear_1, self.linear_2 = linear_1, linear_2
|
| 528 |
+
self.embed_dim = cfg.timestep_embed_dim
|
| 529 |
+
self.flip_sin_to_cos = cfg.timestep_flip_sin_to_cos
|
| 530 |
+
self.downscale_freq_shift = cfg.timestep_downscale_freq_shift
|
| 531 |
+
self.max_period = cfg.timestep_max_period
|
| 532 |
+
|
| 533 |
+
@classmethod
|
| 534 |
+
def from_checkpoint(cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], cfg: DiTConfig) -> "TimestepEncoder":
|
| 535 |
+
l1 = Linear.from_checkpoint(
|
| 536 |
+
ck, prefix + "linear_1", consumed, (cfg.timestep_mlp_hidden, cfg.timestep_embed_dim)
|
| 537 |
+
)
|
| 538 |
+
l2 = Linear.from_checkpoint(ck, prefix + "linear_2", consumed, (cfg.width, cfg.timestep_mlp_hidden))
|
| 539 |
+
return cls(l1, l2, cfg)
|
| 540 |
+
|
| 541 |
+
def projection(self, t_bucket: int) -> Tensor:
|
| 542 |
+
return timestep_projection(
|
| 543 |
+
t_bucket, self.embed_dim, self.flip_sin_to_cos, self.downscale_freq_shift, self.max_period
|
| 544 |
+
)
|
| 545 |
+
|
| 546 |
+
def forward(self, t_bucket: int) -> Tensor:
|
| 547 |
+
return self.linear_2(F.silu(self.linear_1(self.projection(t_bucket))))
|
| 548 |
+
|
| 549 |
+
|
| 550 |
+
class AdaLayerNorm(nn.Module):
|
| 551 |
+
"""``AdaLayerNorm`` (cross_attention_dit.py:44-67 / dit.py:74-97): ``scale, shift = linear(silu(temb)).chunk(2)``
|
| 552 |
+
-- **scale first** -- and ``LN(x, eps 1e-5, no affine) * (1 + scale) + shift`` (critique C6; weight-loader §4.6
|
| 553 |
+
VERIFIED: swapped order -> PCC 0.61). :meth:`modulation` returns ``(1 + scale, shift)`` so that a precomputed
|
| 554 |
+
table and the live path execute the same arithmetic."""
|
| 555 |
+
|
| 556 |
+
def __init__(self, linear: Linear, dim: int, eps: float):
|
| 557 |
+
super().__init__()
|
| 558 |
+
if linear.out_features != 2 * dim or linear.in_features != dim:
|
| 559 |
+
raise ValueError(f"AdaLayerNorm: linear {linear.out_features}x{linear.in_features} != {2 * dim}x{dim}")
|
| 560 |
+
self.linear = linear
|
| 561 |
+
self.norm = LayerNorm(dim, eps)
|
| 562 |
+
|
| 563 |
+
def modulation(self, temb: Tensor) -> Tuple[Tensor, Tensor]:
|
| 564 |
+
scale, shift = self.linear(F.silu(temb)).chunk(2, dim=-1)
|
| 565 |
+
return 1.0 + scale, shift
|
| 566 |
+
|
| 567 |
+
def forward(self, x: Tensor, one_plus_scale: Tensor, shift: Tensor) -> Tensor:
|
| 568 |
+
return self.norm(x) * one_plus_scale[:, None, :] + shift[:, None, :]
|
| 569 |
+
|
| 570 |
+
|
| 571 |
+
class DiTBlock(nn.Module):
|
| 572 |
+
"""``BasicTransformerBlock(norm_type="ada_norm")`` (synthesis §1.5)::
|
| 573 |
+
|
| 574 |
+
h = AdaLN(x, temb) # attention branch only, ungated
|
| 575 |
+
x = x + attn1(h, kv = vl_embs if cross else h) # 32 x 48, scale 48^-0.5, bias everywhere
|
| 576 |
+
x = x + ff(LN(x, eps 1e-5, no affine)) # norm3 has no weights in any checkpoint (synthesis §3 N8)
|
| 577 |
+
|
| 578 |
+
``key_subset`` names the cross-attention key set (``DiTConfig.cross_key_subset``): ``all`` (N1.5), ``text``
|
| 579 |
+
(non-image tokens, ``idx % 4 == 0``) or ``image`` (``idx % 4 == 2``); ``None`` for self-attention blocks.
|
| 580 |
+
"""
|
| 581 |
+
|
| 582 |
+
def __init__(
|
| 583 |
+
self,
|
| 584 |
+
index: int,
|
| 585 |
+
norm1: AdaLayerNorm,
|
| 586 |
+
attn: MultiHeadAttention,
|
| 587 |
+
ff: FeedForward,
|
| 588 |
+
norm3_eps: float,
|
| 589 |
+
key_subset: Optional[str],
|
| 590 |
+
):
|
| 591 |
+
super().__init__()
|
| 592 |
+
self.index = index
|
| 593 |
+
self.norm1, self.attn, self.ff = norm1, attn, ff
|
| 594 |
+
self.norm3 = LayerNorm(attn.to_q.in_features, norm3_eps)
|
| 595 |
+
if key_subset is not None and key_subset not in KEY_SUBSETS:
|
| 596 |
+
raise ValueError(f"block {index}: unknown key subset {key_subset!r}")
|
| 597 |
+
self.key_subset = key_subset
|
| 598 |
+
|
| 599 |
+
@property
|
| 600 |
+
def is_cross(self) -> bool:
|
| 601 |
+
return self.key_subset is not None
|
| 602 |
+
|
| 603 |
+
@classmethod
|
| 604 |
+
def from_checkpoint(
|
| 605 |
+
cls, ck: LazyCheckpoint, prefix: str, index: int, consumed: Set[str], cfg: DiTConfig
|
| 606 |
+
) -> "DiTBlock":
|
| 607 |
+
is_cross = index % 2 == 0 # cross_block_parity == "even"
|
| 608 |
+
key_subset = cfg.cross_key_subset(index) if is_cross else None
|
| 609 |
+
kv_dim = cfg.cross_attention_dim if is_cross else cfg.width
|
| 610 |
+
norm1 = AdaLayerNorm(
|
| 611 |
+
Linear.from_checkpoint(ck, prefix + "norm1.linear", consumed, (2 * cfg.width, cfg.width)),
|
| 612 |
+
cfg.width,
|
| 613 |
+
cfg.adaln_ln_eps,
|
| 614 |
+
)
|
| 615 |
+
attn = MultiHeadAttention.from_checkpoint(
|
| 616 |
+
ck, prefix + "attn1.", consumed, cfg.width, kv_dim, cfg.n_heads, cfg.head_dim
|
| 617 |
+
)
|
| 618 |
+
ff = FeedForward.from_checkpoint(ck, prefix + "ff.", consumed, cfg.width, cfg.ff_dim)
|
| 619 |
+
return cls(index, norm1, attn, ff, cfg.norm3_eps, key_subset)
|
| 620 |
+
|
| 621 |
+
def forward(
|
| 622 |
+
self,
|
| 623 |
+
x: Tensor,
|
| 624 |
+
one_plus_scale: Tensor,
|
| 625 |
+
shift: Tensor,
|
| 626 |
+
kv: Optional[Tensor] = None,
|
| 627 |
+
key_mask: Optional[Tensor] = None,
|
| 628 |
+
hoisted_kv: Optional[Tuple[Tensor, Tensor]] = None,
|
| 629 |
+
) -> Tensor:
|
| 630 |
+
h = self.norm1(x, one_plus_scale, shift)
|
| 631 |
+
if self.is_cross:
|
| 632 |
+
q = self.attn.project_q(h)
|
| 633 |
+
if hoisted_kv is not None:
|
| 634 |
+
if kv is not None or key_mask is not None:
|
| 635 |
+
raise ValueError(f"block {self.index}: pass either hoisted K/V or (kv, key_mask), not both")
|
| 636 |
+
a = self.attn.attend(q, hoisted_kv[0], hoisted_kv[1], None)
|
| 637 |
+
else:
|
| 638 |
+
if kv is None:
|
| 639 |
+
raise ValueError(f"block {self.index}: cross-attention block needs kv or hoisted_kv")
|
| 640 |
+
k, v = self.attn.project_kv(kv)
|
| 641 |
+
a = self.attn.attend(q, k, v, key_mask)
|
| 642 |
+
else:
|
| 643 |
+
if kv is not None or key_mask is not None or hoisted_kv is not None:
|
| 644 |
+
raise ValueError(f"block {self.index}: self-attention block takes no key/value source")
|
| 645 |
+
a = self.attn(h)
|
| 646 |
+
x = x + a
|
| 647 |
+
return x + self.ff(self.norm3(x))
|
| 648 |
+
|
| 649 |
+
|
| 650 |
+
class DiTOutputHead(nn.Module):
|
| 651 |
+
"""Output block (cross_attention_dit.py:299-306 / dit.py:407-414): ``shift, scale = proj_out_1(silu(temb)).chunk(2)``
|
| 652 |
+
-- **shift first**, the opposite order to the blocks -- ``LN(x, eps 1e-6, no affine) * (1 + scale) + shift`` ->
|
| 653 |
+
``proj_out_2`` (1536 -> 1024)."""
|
| 654 |
+
|
| 655 |
+
def __init__(self, proj_out_1: Linear, proj_out_2: Linear, dim: int, eps: float):
|
| 656 |
+
super().__init__()
|
| 657 |
+
if proj_out_1.out_features != 2 * dim or proj_out_2.in_features != dim:
|
| 658 |
+
raise ValueError("DiTOutputHead: projection widths mismatch")
|
| 659 |
+
self.proj_out_1, self.proj_out_2 = proj_out_1, proj_out_2
|
| 660 |
+
self.norm_out = LayerNorm(dim, eps)
|
| 661 |
+
|
| 662 |
+
@classmethod
|
| 663 |
+
def from_checkpoint(cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], cfg: DiTConfig) -> "DiTOutputHead":
|
| 664 |
+
p1 = Linear.from_checkpoint(ck, prefix + "proj_out_1", consumed, (2 * cfg.width, cfg.width))
|
| 665 |
+
p2 = Linear.from_checkpoint(ck, prefix + "proj_out_2", consumed, (cfg.out_dim, cfg.width))
|
| 666 |
+
return cls(p1, p2, cfg.width, cfg.out_norm_eps)
|
| 667 |
+
|
| 668 |
+
def modulation(self, temb: Tensor) -> Tuple[Tensor, Tensor]:
|
| 669 |
+
"""``(1 + scale, shift)`` of the output head (chunk order shift, scale)."""
|
| 670 |
+
shift, scale = self.proj_out_1(F.silu(temb)).chunk(2, dim=-1)
|
| 671 |
+
return 1.0 + scale, shift
|
| 672 |
+
|
| 673 |
+
def forward(self, x: Tensor, one_plus_scale: Tensor, shift: Tensor) -> Tensor:
|
| 674 |
+
return self.proj_out_2(self.norm_out(x) * one_plus_scale[:, None, :] + shift[:, None, :])
|
| 675 |
+
|
| 676 |
+
|
| 677 |
+
@dataclass(frozen=True)
|
| 678 |
+
class StepModulation:
|
| 679 |
+
"""Every timestep-dependent vector of one denoising step (weight-loader-spec.md §4.6 'precompute'): ``temb``
|
| 680 |
+
``[1, 1536]``, per block ``(1 + scale, shift)`` and the output head ``(1 + scale, shift)``, all ``[1, 1536]``."""
|
| 681 |
+
|
| 682 |
+
bucket: int
|
| 683 |
+
temb: Tensor
|
| 684 |
+
block_one_plus_scale: Tuple[Tensor, ...]
|
| 685 |
+
block_shift: Tuple[Tensor, ...]
|
| 686 |
+
head_one_plus_scale: Tensor
|
| 687 |
+
head_shift: Tensor
|
| 688 |
+
|
| 689 |
+
@property
|
| 690 |
+
def n_blocks(self) -> int:
|
| 691 |
+
return len(self.block_one_plus_scale)
|
| 692 |
+
|
| 693 |
+
|
| 694 |
+
def select_keys(
|
| 695 |
+
subset: str, image_mask: Optional[Tensor], backbone_attention_mask: Optional[Tensor], seq_len: int
|
| 696 |
+
) -> Optional[Tensor]:
|
| 697 |
+
"""Boolean key mask ``[B, S]`` of a cross-attention key subset (arch-n16 §7.4, arch-n17 §3.3):
|
| 698 |
+
``text`` -> ``~image_mask & backbone_attention_mask``; ``image`` -> ``image_mask & backbone_attention_mask``;
|
| 699 |
+
``all`` -> None (N1.5 applies no key mask, ``VLAdapterConfig.masked`` is False)."""
|
| 700 |
+
if subset == "all":
|
| 701 |
+
return None
|
| 702 |
+
if image_mask is None or backbone_attention_mask is None:
|
| 703 |
+
raise ValueError(f"key subset {subset!r} needs image_mask and backbone_attention_mask")
|
| 704 |
+
for name, m in (("image_mask", image_mask), ("backbone_attention_mask", backbone_attention_mask)):
|
| 705 |
+
if m.dtype != torch.bool:
|
| 706 |
+
raise TypeError(f"{name} must be bool, got {m.dtype}")
|
| 707 |
+
if m.ndim != 2 or m.shape[-1] != seq_len:
|
| 708 |
+
raise ValueError(f"{name} must be [B, S={seq_len}], got {tuple(m.shape)}")
|
| 709 |
+
if subset == "text":
|
| 710 |
+
return (~image_mask) & backbone_attention_mask
|
| 711 |
+
if subset == "image":
|
| 712 |
+
return image_mask & backbone_attention_mask
|
| 713 |
+
raise ValueError(f"unknown key subset {subset!r}")
|
| 714 |
+
|
| 715 |
+
|
| 716 |
+
class DiT(nn.Module):
|
| 717 |
+
"""``cross_attention_dit.DiT`` (N1.5) / ``dit.AlternateVLDiT`` (N1.6, N1.7) in fp32 (synthesis §1.5).
|
| 718 |
+
|
| 719 |
+
``forward`` supports three interchangeable cross-attention forms:
|
| 720 |
+
|
| 721 |
+
* ``cross_form="mask"`` -- reference: K/V from all ``S`` VL tokens + boolean key mask (N1.5: no mask);
|
| 722 |
+
* ``cross_form="gather"`` -- K/V from the gathered key subset only (no mask);
|
| 723 |
+
* ``cross_kv=...`` -- hoisted K/V from :meth:`hoist_cross_kv` (gather form computed once per inference).
|
| 724 |
+
|
| 725 |
+
and an optional precomputed :class:`StepModulation` (``modulation=``) in place of the live timestep encoder.
|
| 726 |
+
"""
|
| 727 |
+
|
| 728 |
+
def __init__(
|
| 729 |
+
self, cfg: DiTConfig, timestep_encoder: TimestepEncoder, blocks: Sequence[DiTBlock], out: DiTOutputHead
|
| 730 |
+
):
|
| 731 |
+
super().__init__()
|
| 732 |
+
if len(blocks) != cfg.n_blocks:
|
| 733 |
+
raise ValueError(f"DiT: {len(blocks)} blocks != {cfg.n_blocks}")
|
| 734 |
+
self.cfg = cfg
|
| 735 |
+
self.timestep_encoder = timestep_encoder
|
| 736 |
+
self.blocks = nn.ModuleList(blocks)
|
| 737 |
+
self.out = out
|
| 738 |
+
|
| 739 |
+
@classmethod
|
| 740 |
+
def from_checkpoint(cls, ck: LazyCheckpoint, prefix: str, consumed: Set[str], cfg: DiTConfig) -> "DiT":
|
| 741 |
+
te = TimestepEncoder.from_checkpoint(ck, prefix + "timestep_encoder.timestep_embedder.", consumed, cfg)
|
| 742 |
+
blocks = [
|
| 743 |
+
DiTBlock.from_checkpoint(ck, f"{prefix}transformer_blocks.{i}.", i, consumed, cfg)
|
| 744 |
+
for i in range(cfg.n_blocks)
|
| 745 |
+
]
|
| 746 |
+
out = DiTOutputHead.from_checkpoint(ck, prefix, consumed, cfg)
|
| 747 |
+
return cls(cfg, te, blocks, out)
|
| 748 |
+
|
| 749 |
+
# ------------------------------------------------------------------ head padding
|
| 750 |
+
@property
|
| 751 |
+
def head_dim_pad(self) -> int:
|
| 752 |
+
return self.blocks[0].attn.head_dim_pad
|
| 753 |
+
|
| 754 |
+
def set_head_dim_pad(self, pad: int) -> None:
|
| 755 |
+
"""Pad (or un-pad) every block's attention heads to ``pad`` columns; the scale stays ``48 ** -0.5``."""
|
| 756 |
+
for blk in self.blocks:
|
| 757 |
+
blk.attn.set_head_dim_pad(pad)
|
| 758 |
+
|
| 759 |
+
# ------------------------------------------------------------------ timestep-dependent vectors
|
| 760 |
+
def modulation(self, t_bucket: int) -> StepModulation:
|
| 761 |
+
"""Live path: ``temb`` and every ``(1 + scale, shift)`` of one bucket."""
|
| 762 |
+
temb = self.timestep_encoder(t_bucket)
|
| 763 |
+
ops, shs = [], []
|
| 764 |
+
for blk in self.blocks:
|
| 765 |
+
o, s = blk.norm1.modulation(temb)
|
| 766 |
+
ops.append(o)
|
| 767 |
+
shs.append(s)
|
| 768 |
+
ho, hs = self.out.modulation(temb)
|
| 769 |
+
return StepModulation(int(t_bucket), temb, tuple(ops), tuple(shs), ho, hs)
|
| 770 |
+
|
| 771 |
+
# ------------------------------------------------------------------ cross-attention key sets
|
| 772 |
+
def key_indices(
|
| 773 |
+
self, subset: str, image_mask: Optional[Tensor], backbone_attention_mask: Optional[Tensor], seq_len: int
|
| 774 |
+
) -> Optional[Tensor]:
|
| 775 |
+
"""Gather indices of ``subset`` (batch 1) or None for ``all``."""
|
| 776 |
+
mask = select_keys(subset, image_mask, backbone_attention_mask, seq_len)
|
| 777 |
+
if mask is None:
|
| 778 |
+
return None
|
| 779 |
+
if mask.shape[0] != 1:
|
| 780 |
+
raise ValueError("gather form is defined for batch 1")
|
| 781 |
+
idx = mask[0].nonzero(as_tuple=False).flatten()
|
| 782 |
+
if idx.numel() == 0:
|
| 783 |
+
raise ValueError(f"key subset {subset!r} selects no token")
|
| 784 |
+
return idx
|
| 785 |
+
|
| 786 |
+
def hoist_cross_kv(
|
| 787 |
+
self, vl_embs: Tensor, image_mask: Optional[Tensor], backbone_attention_mask: Optional[Tensor]
|
| 788 |
+
) -> Dict[int, Tuple[Tensor, Tensor]]:
|
| 789 |
+
"""K/V of every cross block over its gathered key subset -- computed once per inference and reused by the 4
|
| 790 |
+
denoising steps (arch-n15 §3.6; static-shape-plan §6.2 'hoisted K/V buffers')."""
|
| 791 |
+
seq_len = vl_embs.shape[1]
|
| 792 |
+
gathered: Dict[str, Tensor] = {}
|
| 793 |
+
out: Dict[int, Tuple[Tensor, Tensor]] = {}
|
| 794 |
+
for blk in self.blocks:
|
| 795 |
+
if not blk.is_cross:
|
| 796 |
+
continue
|
| 797 |
+
if blk.key_subset not in gathered:
|
| 798 |
+
idx = self.key_indices(blk.key_subset, image_mask, backbone_attention_mask, seq_len)
|
| 799 |
+
gathered[blk.key_subset] = vl_embs if idx is None else vl_embs[:, idx]
|
| 800 |
+
out[blk.index] = blk.attn.project_kv(gathered[blk.key_subset])
|
| 801 |
+
return out
|
| 802 |
+
|
| 803 |
+
# ------------------------------------------------------------------ forward
|
| 804 |
+
def forward(
|
| 805 |
+
self,
|
| 806 |
+
sa_embs: Tensor,
|
| 807 |
+
vl_embs: Tensor,
|
| 808 |
+
t_bucket: int,
|
| 809 |
+
image_mask: Optional[Tensor] = None,
|
| 810 |
+
backbone_attention_mask: Optional[Tensor] = None,
|
| 811 |
+
*,
|
| 812 |
+
modulation: Optional[StepModulation] = None,
|
| 813 |
+
cross_form: CrossForm = "mask",
|
| 814 |
+
cross_kv: Optional[Dict[int, Tuple[Tensor, Tensor]]] = None,
|
| 815 |
+
taps: Optional[Dict[str, Tensor]] = None,
|
| 816 |
+
tap_suffix: str = "",
|
| 817 |
+
) -> Tensor:
|
| 818 |
+
cfg = self.cfg
|
| 819 |
+
_check_shape("sa_embs", sa_embs, (1, cfg.n_query_tokens, cfg.width))
|
| 820 |
+
if vl_embs.ndim != 3 or vl_embs.shape[0] != 1 or vl_embs.shape[-1] != cfg.cross_attention_dim:
|
| 821 |
+
raise ValueError(f"vl_embs must be [1, S, {cfg.cross_attention_dim}], got {tuple(vl_embs.shape)}")
|
| 822 |
+
if cross_form not in CROSS_FORMS:
|
| 823 |
+
raise ValueError(f"cross_form must be one of {CROSS_FORMS}, got {cross_form!r}")
|
| 824 |
+
seq_len = vl_embs.shape[1]
|
| 825 |
+
|
| 826 |
+
mod = self.modulation(t_bucket) if modulation is None else modulation
|
| 827 |
+
if mod.bucket != int(t_bucket) or mod.n_blocks != cfg.n_blocks:
|
| 828 |
+
raise ValueError(
|
| 829 |
+
f"modulation is for bucket {mod.bucket} / {mod.n_blocks} blocks, need {t_bucket} / {cfg.n_blocks}"
|
| 830 |
+
)
|
| 831 |
+
if taps is not None:
|
| 832 |
+
taps["temb" + tap_suffix] = mod.temb
|
| 833 |
+
|
| 834 |
+
masks: Dict[str, Optional[Tensor]] = {}
|
| 835 |
+
gathered: Dict[str, Tensor] = {}
|
| 836 |
+
x = sa_embs.contiguous()
|
| 837 |
+
for i, blk in enumerate(self.blocks):
|
| 838 |
+
ops, sh = mod.block_one_plus_scale[i], mod.block_shift[i]
|
| 839 |
+
if not blk.is_cross:
|
| 840 |
+
x = blk(x, ops, sh)
|
| 841 |
+
elif cross_kv is not None:
|
| 842 |
+
if blk.index not in cross_kv:
|
| 843 |
+
raise KeyError(f"cross_kv has no entry for block {blk.index}")
|
| 844 |
+
x = blk(x, ops, sh, hoisted_kv=cross_kv[blk.index])
|
| 845 |
+
elif cross_form == "mask":
|
| 846 |
+
if blk.key_subset not in masks:
|
| 847 |
+
masks[blk.key_subset] = select_keys(blk.key_subset, image_mask, backbone_attention_mask, seq_len)
|
| 848 |
+
x = blk(x, ops, sh, kv=vl_embs, key_mask=masks[blk.key_subset])
|
| 849 |
+
else: # gather
|
| 850 |
+
if blk.key_subset not in gathered:
|
| 851 |
+
idx = self.key_indices(blk.key_subset, image_mask, backbone_attention_mask, seq_len)
|
| 852 |
+
gathered[blk.key_subset] = vl_embs if idx is None else vl_embs[:, idx]
|
| 853 |
+
x = blk(x, ops, sh, kv=gathered[blk.key_subset], key_mask=None)
|
| 854 |
+
if taps is not None:
|
| 855 |
+
taps[f"dit_block{i}_out" + tap_suffix] = x
|
| 856 |
+
if taps is not None:
|
| 857 |
+
taps["dit_block_last_out" + tap_suffix] = x
|
| 858 |
+
y = self.out(x, mod.head_one_plus_scale, mod.head_shift)
|
| 859 |
+
if taps is not None:
|
| 860 |
+
taps["dit_out" + tap_suffix] = y
|
| 861 |
+
return y
|
| 862 |
+
|
| 863 |
+
|
| 864 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 865 |
+
# Action head
|
| 866 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 867 |
+
|
| 868 |
+
|
| 869 |
+
@dataclass
|
| 870 |
+
class Conditioning:
|
| 871 |
+
"""Per-inference constants of the denoising loop (everything that does not depend on the step)."""
|
| 872 |
+
|
| 873 |
+
vl_embs: Tensor # [1, S, 2048] = DiT encoder_hidden_states
|
| 874 |
+
state_features: Tensor # [1, 1, 1536]
|
| 875 |
+
image_mask: Optional[Tensor] # bool [1, S] (N1.6 / N1.7)
|
| 876 |
+
backbone_attention_mask: Optional[Tensor] # bool [1, S]
|
| 877 |
+
cross_kv: Optional[Dict[int, Tuple[Tensor, Tensor]]] = None # hoisted K/V per cross block (gather form)
|
| 878 |
+
|
| 879 |
+
|
| 880 |
+
class ActionHead(nn.Module):
|
| 881 |
+
"""The complete GR00T action head for one embodiment slot (synthesis §1.4-1.6).
|
| 882 |
+
|
| 883 |
+
Public API::
|
| 884 |
+
|
| 885 |
+
head = ActionHead.from_checkpoint("n17", embodiment_id=24)
|
| 886 |
+
cond = head.prepare(backbone_features, state, embodiment_id, image_mask, backbone_attention_mask, taps=taps)
|
| 887 |
+
v = head.denoise_step(actions, t_bucket, cond, taps=taps, tap_suffix="[k=0]") # velocity [1, H, D]
|
| 888 |
+
|
| 889 |
+
``prepare`` runs the VL adapter and the state encoder once; ``denoise_step`` runs action encoder -> ``sa_embs``
|
| 890 |
+
-> DiT -> decoder -> velocity rows ``-H:``. The sampler (:mod:`.sampler`) drives the 4 Euler steps.
|
| 891 |
+
"""
|
| 892 |
+
|
| 893 |
+
def __init__(
|
| 894 |
+
self,
|
| 895 |
+
cfg: GR00TConfig,
|
| 896 |
+
embodiment_id: int,
|
| 897 |
+
vl_adapter: VLAdapter,
|
| 898 |
+
state_encoder: EmbodimentMLP,
|
| 899 |
+
action_encoder: ActionEncoder,
|
| 900 |
+
position_embedding: Tensor,
|
| 901 |
+
future_tokens: Optional[Tensor],
|
| 902 |
+
dit: DiT,
|
| 903 |
+
action_decoder: EmbodimentMLP,
|
| 904 |
+
):
|
| 905 |
+
super().__init__()
|
| 906 |
+
enc = cfg.encoders
|
| 907 |
+
self.cfg = cfg
|
| 908 |
+
self.version = cfg.version
|
| 909 |
+
self.embodiment_id = int(embodiment_id)
|
| 910 |
+
self.vl_adapter = vl_adapter
|
| 911 |
+
self.state_encoder = state_encoder
|
| 912 |
+
self.action_encoder = action_encoder
|
| 913 |
+
_check_shape("position_embedding", position_embedding, (enc.action_horizon, enc.input_embedding_dim))
|
| 914 |
+
self.register_buffer("position_embedding", _fp32(position_embedding).contiguous())
|
| 915 |
+
if cfg.dit.n_future_tokens > 0:
|
| 916 |
+
if future_tokens is None:
|
| 917 |
+
raise ValueError(f"{cfg.version}: {cfg.dit.n_future_tokens} future tokens expected")
|
| 918 |
+
_check_shape("future_tokens", future_tokens, (cfg.dit.n_future_tokens, enc.input_embedding_dim))
|
| 919 |
+
self.register_buffer("future_tokens", _fp32(future_tokens).contiguous())
|
| 920 |
+
else:
|
| 921 |
+
if future_tokens is not None:
|
| 922 |
+
raise ValueError(f"{cfg.version}: unexpected future tokens")
|
| 923 |
+
self.future_tokens = None
|
| 924 |
+
self.dit = dit
|
| 925 |
+
self.action_decoder = action_decoder
|
| 926 |
+
if 1 + cfg.dit.n_future_tokens + enc.action_horizon != cfg.dit.n_query_tokens:
|
| 927 |
+
raise ValueError("query-token bookkeeping is inconsistent")
|
| 928 |
+
|
| 929 |
+
# ------------------------------------------------------------------ loading
|
| 930 |
+
@classmethod
|
| 931 |
+
def from_checkpoint(cls, version: str, embodiment_id: int, ck: Optional[LazyCheckpoint] = None) -> "ActionHead":
|
| 932 |
+
"""Build the head for ``embodiment_id`` from the raw checkpoint keys; every ``action_head.*`` key is consumed."""
|
| 933 |
+
cfg = get_config(version)
|
| 934 |
+
if ck is None:
|
| 935 |
+
ck = LazyCheckpoint(version)
|
| 936 |
+
enc = cfg.encoders
|
| 937 |
+
if not 0 <= embodiment_id < enc.max_num_embodiments:
|
| 938 |
+
raise IndexError(f"embodiment_id {embodiment_id} out of range [0, {enc.max_num_embodiments})")
|
| 939 |
+
consumed: Set[str] = set()
|
| 940 |
+
ah = cfg.checkpoint.action_head_prefix
|
| 941 |
+
p_state, p_action, p_decoder = cfg.checkpoint.embodiment_prefixes
|
| 942 |
+
n = enc.max_num_embodiments
|
| 943 |
+
|
| 944 |
+
vl_adapter = VLAdapter.from_checkpoint(ck, cfg, consumed)
|
| 945 |
+
state_encoder = EmbodimentMLP.from_checkpoint(ck, p_state, embodiment_id, consumed, enc.state_encoder_dims, n)
|
| 946 |
+
action_encoder = ActionEncoder.from_checkpoint(ck, p_action, embodiment_id, consumed, enc)
|
| 947 |
+
action_decoder = EmbodimentMLP.from_checkpoint(
|
| 948 |
+
ck, p_decoder, embodiment_id, consumed, enc.action_decoder_dims, n
|
| 949 |
+
)
|
| 950 |
+
|
| 951 |
+
pos_key = ah + "position_embedding.weight"
|
| 952 |
+
_check_shape(pos_key, torch.empty(ck.shape(pos_key)), (enc.position_embedding_rows, enc.input_embedding_dim))
|
| 953 |
+
position_embedding = ck.rows(pos_key, 0, enc.action_horizon, torch.float32)
|
| 954 |
+
consumed.add(pos_key)
|
| 955 |
+
|
| 956 |
+
future_tokens = None
|
| 957 |
+
ft_key = ah + "future_tokens.weight"
|
| 958 |
+
if cfg.dit.n_future_tokens > 0:
|
| 959 |
+
future_tokens = ck.get(ft_key, torch.float32)
|
| 960 |
+
consumed.add(ft_key)
|
| 961 |
+
|
| 962 |
+
dit = DiT.from_checkpoint(ck, cfg.checkpoint.dit_prefix, consumed, cfg.dit)
|
| 963 |
+
|
| 964 |
+
unconsumed = sorted(set(ck.list_by_prefix(ah)) - consumed)
|
| 965 |
+
if unconsumed:
|
| 966 |
+
raise ValueError(f"{version}: {len(unconsumed)} action_head keys not consumed, e.g. {unconsumed[:5]}")
|
| 967 |
+
return cls(
|
| 968 |
+
cfg,
|
| 969 |
+
embodiment_id,
|
| 970 |
+
vl_adapter,
|
| 971 |
+
state_encoder,
|
| 972 |
+
action_encoder,
|
| 973 |
+
position_embedding,
|
| 974 |
+
future_tokens,
|
| 975 |
+
dit,
|
| 976 |
+
action_decoder,
|
| 977 |
+
)
|
| 978 |
+
|
| 979 |
+
# ------------------------------------------------------------------ once per inference
|
| 980 |
+
def _check_embodiment(self, embodiment_id) -> None:
|
| 981 |
+
e = int(embodiment_id.reshape(-1)[0]) if isinstance(embodiment_id, Tensor) else int(embodiment_id)
|
| 982 |
+
if isinstance(embodiment_id, Tensor) and embodiment_id.numel() != 1:
|
| 983 |
+
raise ValueError("batch 1: embodiment_id must have one element")
|
| 984 |
+
if e != self.embodiment_id:
|
| 985 |
+
raise ValueError(f"head was built for embodiment slot {self.embodiment_id}, got {e}")
|
| 986 |
+
|
| 987 |
+
def encode_state(self, state: Tensor) -> Tensor:
|
| 988 |
+
"""``state [1, 1, max_state_dim]`` (N1.7: ``[B, T_hist, D].view(B, 1, -1)``) -> ``state_features [1, 1, 1536]``."""
|
| 989 |
+
enc = self.cfg.encoders
|
| 990 |
+
if state.ndim != 3 or state.shape[0] != 1:
|
| 991 |
+
raise ValueError(f"state must be [1, T, D], got {tuple(state.shape)}")
|
| 992 |
+
state = state.reshape(1, 1, -1)
|
| 993 |
+
_check_shape("state (flattened)", state, (1, 1, enc.max_state_dim))
|
| 994 |
+
return self.state_encoder(_fp32(state))
|
| 995 |
+
|
| 996 |
+
@torch.no_grad()
|
| 997 |
+
def prepare(
|
| 998 |
+
self,
|
| 999 |
+
backbone_features: Tensor,
|
| 1000 |
+
state: Tensor,
|
| 1001 |
+
embodiment_id,
|
| 1002 |
+
image_mask: Optional[Tensor] = None,
|
| 1003 |
+
backbone_attention_mask: Optional[Tensor] = None,
|
| 1004 |
+
*,
|
| 1005 |
+
hoist_cross_kv: bool = False,
|
| 1006 |
+
taps: Optional[Dict[str, Tensor]] = None,
|
| 1007 |
+
) -> Conditioning:
|
| 1008 |
+
"""VL adapter + state encoder (+ optional hoisted cross K/V). Masks are converted to bool (N1.5 stores int64)."""
|
| 1009 |
+
self._check_embodiment(embodiment_id)
|
| 1010 |
+
bf = _fp32(backbone_features)
|
| 1011 |
+
if image_mask is not None:
|
| 1012 |
+
image_mask = image_mask.to(torch.bool)
|
| 1013 |
+
if backbone_attention_mask is not None:
|
| 1014 |
+
backbone_attention_mask = backbone_attention_mask.to(torch.bool)
|
| 1015 |
+
if self.cfg.dit.cross_key_set != "all" and (image_mask is None or backbone_attention_mask is None):
|
| 1016 |
+
raise ValueError(f"{self.version}: image_mask and backbone_attention_mask are required")
|
| 1017 |
+
vl_embs = self.vl_adapter(bf, taps)
|
| 1018 |
+
state_features = self.encode_state(state)
|
| 1019 |
+
if taps is not None:
|
| 1020 |
+
taps["state_features"] = state_features
|
| 1021 |
+
taps["position_embedding"] = self.position_embedding
|
| 1022 |
+
cross_kv = self.dit.hoist_cross_kv(vl_embs, image_mask, backbone_attention_mask) if hoist_cross_kv else None
|
| 1023 |
+
return Conditioning(vl_embs, state_features, image_mask, backbone_attention_mask, cross_kv)
|
| 1024 |
+
|
| 1025 |
+
# ------------------------------------------------------------------ per denoising step
|
| 1026 |
+
def build_sa_embs(
|
| 1027 |
+
self,
|
| 1028 |
+
actions: Tensor,
|
| 1029 |
+
t_bucket: int,
|
| 1030 |
+
state_features: Tensor,
|
| 1031 |
+
taps: Optional[Dict[str, Tensor]] = None,
|
| 1032 |
+
tap_suffix: str = "",
|
| 1033 |
+
) -> Tensor:
|
| 1034 |
+
"""``cat(state_features, [future_tokens], action_encoder(actions, t) + pos[0:H])`` -> ``[1, T_q, 1536]``."""
|
| 1035 |
+
enc = self.cfg.encoders
|
| 1036 |
+
_check_shape("actions", actions, (1, enc.action_horizon, enc.max_action_dim))
|
| 1037 |
+
_check_shape("state_features", state_features, (1, 1, enc.input_embedding_dim))
|
| 1038 |
+
a = self.action_encoder(_fp32(actions), t_bucket)
|
| 1039 |
+
if taps is not None:
|
| 1040 |
+
taps["action_encoder_out" + tap_suffix] = a
|
| 1041 |
+
a = a + self.position_embedding[None]
|
| 1042 |
+
parts = [state_features]
|
| 1043 |
+
if self.future_tokens is not None:
|
| 1044 |
+
parts.append(self.future_tokens[None])
|
| 1045 |
+
parts.append(a)
|
| 1046 |
+
sa = torch.cat(parts, dim=1)
|
| 1047 |
+
if taps is not None:
|
| 1048 |
+
taps["sa_embs" + tap_suffix] = sa
|
| 1049 |
+
return sa
|
| 1050 |
+
|
| 1051 |
+
def decode(self, dit_out: Tensor, taps: Optional[Dict[str, Tensor]] = None, tap_suffix: str = "") -> Tensor:
|
| 1052 |
+
"""Action decoder on all query rows; the velocity is the last ``H`` rows (synthesis §1.6)."""
|
| 1053 |
+
pred = self.action_decoder(dit_out)
|
| 1054 |
+
if taps is not None:
|
| 1055 |
+
taps["action_decoder_out" + tap_suffix] = pred
|
| 1056 |
+
v = pred[:, -self.cfg.encoders.action_horizon :]
|
| 1057 |
+
if taps is not None:
|
| 1058 |
+
taps["pred_velocity" + tap_suffix] = v
|
| 1059 |
+
return v
|
| 1060 |
+
|
| 1061 |
+
@torch.no_grad()
|
| 1062 |
+
def denoise_step(
|
| 1063 |
+
self,
|
| 1064 |
+
actions: Tensor,
|
| 1065 |
+
t_bucket: int,
|
| 1066 |
+
cond: Conditioning,
|
| 1067 |
+
*,
|
| 1068 |
+
modulation: Optional[StepModulation] = None,
|
| 1069 |
+
cross_form: CrossForm = "mask",
|
| 1070 |
+
taps: Optional[Dict[str, Tensor]] = None,
|
| 1071 |
+
tap_suffix: str = "",
|
| 1072 |
+
) -> Tensor:
|
| 1073 |
+
"""One evaluation of the velocity field ``v(actions, t_bucket)`` -> ``[1, H, max_action_dim]``."""
|
| 1074 |
+
if taps is not None:
|
| 1075 |
+
taps["noisy_actions_in" + tap_suffix] = _fp32(actions)
|
| 1076 |
+
taps["timestep" + tap_suffix] = torch.tensor([int(t_bucket)], dtype=torch.int64)
|
| 1077 |
+
sa = self.build_sa_embs(actions, t_bucket, cond.state_features, taps, tap_suffix)
|
| 1078 |
+
y = self.dit(
|
| 1079 |
+
sa,
|
| 1080 |
+
cond.vl_embs,
|
| 1081 |
+
t_bucket,
|
| 1082 |
+
cond.image_mask,
|
| 1083 |
+
cond.backbone_attention_mask,
|
| 1084 |
+
modulation=modulation,
|
| 1085 |
+
cross_form=cross_form,
|
| 1086 |
+
cross_kv=cond.cross_kv,
|
| 1087 |
+
taps=taps,
|
| 1088 |
+
tap_suffix=tap_suffix,
|
| 1089 |
+
)
|
| 1090 |
+
return self.decode(y, taps, tap_suffix)
|
| 1091 |
+
|
| 1092 |
+
def __repr__(self) -> str: # keep the module tree out of pytest output
|
| 1093 |
+
return f"ActionHead({self.version}, embodiment={self.embodiment_id}, dit_blocks={self.cfg.dit.n_blocks}, head_dim_pad={self.dit.head_dim_pad})"
|
code/models/experimental/gr00t/reference/model.py
ADDED
|
@@ -0,0 +1,524 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
|
| 4 |
+
"""End-to-end fp32 CPU reference of GR00T N1.5 / N1.6 / N1.7: raw observation -> physical actions.
|
| 5 |
+
|
| 6 |
+
:class:`Gr00tReference` glues the host pipeline and the torch reference modules together exactly the way the device
|
| 7 |
+
model will (``01-architecture-synthesis.md`` §1.7-1.8 dataflow)::
|
| 8 |
+
|
| 9 |
+
Observation --encode--> ModelInputs --backbone--> features [S, 2048] --action head + sampler--> x_4 --decode--> actions
|
| 10 |
+
(common.preprocessing / prompts) (reference.backbone) (reference.action_head / sampler) (common.normalization)
|
| 11 |
+
|
| 12 |
+
* **encode**: :func:`common.preprocessing.encode` (images -> pixel values, prompt -> ids, state -> normalised
|
| 13 |
+
vector, static slot layout + RoPE tables; ``foundation-f2-host.md`` §2).
|
| 14 |
+
* **backbone**: :class:`reference.backbone.Backbone` on the *unpadded* sequence (batch 1, pure causal mask, the
|
| 15 |
+
golden case). The RoPE tables / mRoPE ids of the padded host layout are gathered at the real-token slots
|
| 16 |
+
(``ModelInputs.slots.slot_of_token``), so the host tables are the ones exercised, not the backbone's own builder.
|
| 17 |
+
* **action head + sampler**: :class:`reference.action_head.ActionHead` (one embodiment slot) driven by
|
| 18 |
+
:class:`reference.sampler.FlowMatchingSampler` (4 Euler steps, ``SamplerConfig``; the fp32 Euler convention by
|
| 19 |
+
default, the official bf16 conventions on request -- ``golden-tap-map-and-thresholds.md`` §2.1).
|
| 20 |
+
* **decode**: :func:`common.normalization.decode` (per-group min-max un-normalisation; N1.6 / N1.7 RELATIVE keys are
|
| 21 |
+
composed with the raw observation state; ``foundation-f2-host.md`` §3).
|
| 22 |
+
|
| 23 |
+
Noise: the reference policies draw ``randn`` after a fixed seed on every call (N1.5 ``manual_seed(0)``,
|
| 24 |
+
``flow_matching_action_head.py:364-368``; N1.6 / N1.7 seed 42, ``golden/n16/README.md`` §"initial_noise",
|
| 25 |
+
``golden/n17/README.md`` §"Determinism / seed"). :meth:`Gr00tReference.make_noise` mirrors that with a CPU
|
| 26 |
+
``torch.Generator`` (the CPU stream differs from the CUDA stream of the goldens, so tests inject the golden noise).
|
| 27 |
+
|
| 28 |
+
Everything is fp32, CPU, deterministic, batch 1; no ``ttnn`` import.
|
| 29 |
+
"""
|
| 30 |
+
|
| 31 |
+
from __future__ import annotations
|
| 32 |
+
|
| 33 |
+
import time
|
| 34 |
+
from dataclasses import dataclass, field
|
| 35 |
+
from pathlib import Path
|
| 36 |
+
from typing import Any, Dict, Mapping, Optional, Tuple, Union
|
| 37 |
+
|
| 38 |
+
import torch
|
| 39 |
+
from torch import Tensor
|
| 40 |
+
|
| 41 |
+
from models.experimental.gr00t.common import normalization
|
| 42 |
+
from models.experimental.gr00t.common.checkpoint import LazyCheckpoint
|
| 43 |
+
from models.experimental.gr00t.common.configs import GR00T_VERSIONS, GR00TConfig, get_config
|
| 44 |
+
from models.experimental.gr00t.common.golden import GoldenSet
|
| 45 |
+
from models.experimental.gr00t.common.normalization import EmbodimentSpec, get_embodiment_spec
|
| 46 |
+
from models.experimental.gr00t.common.preprocessing import ModelInputs, Observation, encode, load_golden_observation
|
| 47 |
+
from models.experimental.gr00t.reference.action_head import ActionHead, CrossForm
|
| 48 |
+
from models.experimental.gr00t.reference.backbone import Backbone, BackboneInputs
|
| 49 |
+
from models.experimental.gr00t.reference.sampler import EULER_DTYPES, AdaLNTables, FlowMatchingSampler
|
| 50 |
+
|
| 51 |
+
# Seed the reference policies use for the flow-matching noise (module docstring). CPU generator here.
|
| 52 |
+
DEFAULT_NOISE_SEED: Mapping[str, int] = {"n15": 0, "n16": 42, "n17": 42}
|
| 53 |
+
|
| 54 |
+
STAGES: Tuple[str, ...] = ("encode", "backbone", "head_prepare", "sampler", "decode", "total")
|
| 55 |
+
|
| 56 |
+
|
| 57 |
+
@dataclass
|
| 58 |
+
class ReferenceOutput:
|
| 59 |
+
"""Everything one inference produced (``actions`` is ``None`` when no observation was decoded)."""
|
| 60 |
+
|
| 61 |
+
version: str
|
| 62 |
+
inputs: ModelInputs
|
| 63 |
+
noise: Tensor # [1, H, max_action_dim] fp32, the x_0 actually integrated
|
| 64 |
+
backbone_features: Tensor # [1, S, 2048] fp32
|
| 65 |
+
action_pred_normalized: Tensor # [1, H, max_action_dim] fp32 (x_4)
|
| 66 |
+
actions: Optional[Dict[str, Tensor]] # {group: [1, H, D] fp32 physical actions}
|
| 67 |
+
taps: Dict[str, Tensor] = field(default_factory=dict)
|
| 68 |
+
timing: Dict[str, float] = field(default_factory=dict) # seconds per stage (STAGES)
|
| 69 |
+
|
| 70 |
+
@property
|
| 71 |
+
def seq_len(self) -> int:
|
| 72 |
+
return int(self.inputs.seq_len)
|
| 73 |
+
|
| 74 |
+
def valid_actions(self, spec: EmbodimentSpec) -> Tensor:
|
| 75 |
+
"""``action_pred_normalized[:, :H, :D_real]`` -- the trained region (golden-tap-map §3.1 'valid slices')."""
|
| 76 |
+
return self.action_pred_normalized[:, : spec.action_horizon, : spec.action_dim]
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
class Gr00tReference:
|
| 80 |
+
"""fp32 CPU reference policy for one (version, embodiment) pair.
|
| 81 |
+
|
| 82 |
+
::
|
| 83 |
+
|
| 84 |
+
ref = Gr00tReference("n17") # DROID slot 24, ~11 GB fp32 resident, ~1 s to build
|
| 85 |
+
actions = ref.get_action(observation, seed=42) # {'eef_9d': [1, 40, 9], 'gripper_position': ..., ...}
|
| 86 |
+
out = ref.infer(observation, noise=golden_noise, return_taps=True) # full result incl. taps and timing
|
| 87 |
+
out = ref.forward_from_inputs(model_inputs, noise) # from pre-encoded inputs (tests)
|
| 88 |
+
|
| 89 |
+
``device`` / ``dtype`` are part of the signature for symmetry with the device model but only ``"cpu"`` /
|
| 90 |
+
``torch.float32`` are implemented (the reference modules hold fp32 CPU buffers); anything else raises.
|
| 91 |
+
"""
|
| 92 |
+
|
| 93 |
+
def __init__(
|
| 94 |
+
self,
|
| 95 |
+
version: str,
|
| 96 |
+
embodiment: Optional[str] = None,
|
| 97 |
+
device: Union[str, torch.device] = "cpu",
|
| 98 |
+
dtype: torch.dtype = torch.float32,
|
| 99 |
+
*,
|
| 100 |
+
checkpoint: Optional[LazyCheckpoint] = None,
|
| 101 |
+
euler_dtype: str = "fp32",
|
| 102 |
+
cross_form: CrossForm = "mask",
|
| 103 |
+
hoist_cross_kv: bool = False,
|
| 104 |
+
precompute_adaln: bool = False,
|
| 105 |
+
):
|
| 106 |
+
if version not in GR00T_VERSIONS:
|
| 107 |
+
raise KeyError(f"unknown GR00T version {version!r}; expected one of {GR00T_VERSIONS}")
|
| 108 |
+
if torch.device(device).type != "cpu":
|
| 109 |
+
raise NotImplementedError(f"Gr00tReference runs on CPU only (got device={device!r})")
|
| 110 |
+
if dtype != torch.float32:
|
| 111 |
+
raise NotImplementedError(f"Gr00tReference is fp32 only (got dtype={dtype}); bf16 belongs to the tt/ model")
|
| 112 |
+
if euler_dtype not in EULER_DTYPES:
|
| 113 |
+
raise ValueError(f"euler_dtype must be one of {EULER_DTYPES}, got {euler_dtype!r}")
|
| 114 |
+
self.cfg: GR00TConfig = get_config(version)
|
| 115 |
+
self.version = version
|
| 116 |
+
self.device = torch.device(device)
|
| 117 |
+
self.dtype = dtype
|
| 118 |
+
self.euler_dtype = euler_dtype
|
| 119 |
+
self.cross_form: CrossForm = cross_form
|
| 120 |
+
self.hoist_cross_kv = hoist_cross_kv
|
| 121 |
+
|
| 122 |
+
tag = embodiment if embodiment is not None else self.cfg.canonical_embodiment
|
| 123 |
+
self.spec: EmbodimentSpec = get_embodiment_spec(version, tag)
|
| 124 |
+
self.embodiment_tag = tag
|
| 125 |
+
self.embodiment_id = int(self.spec.embodiment_id)
|
| 126 |
+
if self.embodiment_id != self.cfg.embodiment_id(tag):
|
| 127 |
+
raise ValueError(
|
| 128 |
+
f"{version}/{tag}: embodiment id {self.embodiment_id} (processor files) != {self.cfg.embodiment_id(tag)} (configs)"
|
| 129 |
+
)
|
| 130 |
+
|
| 131 |
+
t0 = time.perf_counter()
|
| 132 |
+
self.ck = checkpoint if checkpoint is not None else LazyCheckpoint(version)
|
| 133 |
+
self.backbone = Backbone(version, self.ck)
|
| 134 |
+
t1 = time.perf_counter()
|
| 135 |
+
self.head = ActionHead.from_checkpoint(version, self.embodiment_id, self.ck)
|
| 136 |
+
self.sampler = FlowMatchingSampler(self.head)
|
| 137 |
+
self.adaln_tables: Optional[AdaLNTables] = self.sampler.precompute_adaln() if precompute_adaln else None
|
| 138 |
+
t2 = time.perf_counter()
|
| 139 |
+
self.load_timing = {"backbone_s": t1 - t0, "head_s": t2 - t1, "total_s": t2 - t0}
|
| 140 |
+
|
| 141 |
+
# ------------------------------------------------------------------ host side
|
| 142 |
+
@property
|
| 143 |
+
def noise_shape(self) -> Tuple[int, int, int]:
|
| 144 |
+
return tuple(self.cfg.sampler.noise_shape) # type: ignore[return-value]
|
| 145 |
+
|
| 146 |
+
def make_noise(self, seed: Optional[int] = None) -> Tensor:
|
| 147 |
+
"""``randn(noise_shape)`` from a CPU generator seeded with ``seed`` (default: the version's reference seed)."""
|
| 148 |
+
s = int(DEFAULT_NOISE_SEED[self.version] if seed is None else seed)
|
| 149 |
+
g = torch.Generator(device="cpu").manual_seed(s)
|
| 150 |
+
return torch.randn(self.noise_shape, generator=g, dtype=torch.float32)
|
| 151 |
+
|
| 152 |
+
def _resolve_noise(self, noise: Optional[Tensor], seed: Optional[int]) -> Tensor:
|
| 153 |
+
if noise is not None:
|
| 154 |
+
if seed is not None:
|
| 155 |
+
raise ValueError("pass either noise or seed, not both")
|
| 156 |
+
if not isinstance(noise, Tensor):
|
| 157 |
+
raise TypeError(f"noise must be a torch.Tensor, got {type(noise).__name__}")
|
| 158 |
+
if tuple(noise.shape) != self.noise_shape:
|
| 159 |
+
raise ValueError(f"noise must have shape {self.noise_shape}, got {tuple(noise.shape)}")
|
| 160 |
+
if not noise.is_floating_point():
|
| 161 |
+
raise TypeError(f"noise must be floating point, got {noise.dtype}")
|
| 162 |
+
return noise.detach().to("cpu", torch.float32)
|
| 163 |
+
return self.make_noise(seed)
|
| 164 |
+
|
| 165 |
+
def encode(self, observation: Observation) -> ModelInputs:
|
| 166 |
+
""":func:`common.preprocessing.encode` for this model's embodiment (the observation's tag must agree)."""
|
| 167 |
+
if observation.embodiment_tag != self.embodiment_tag:
|
| 168 |
+
raise ValueError(
|
| 169 |
+
f"model is built for embodiment {self.embodiment_tag!r} (slot {self.embodiment_id}); "
|
| 170 |
+
f"observation carries {observation.embodiment_tag!r}"
|
| 171 |
+
)
|
| 172 |
+
return encode(self.version, observation, embodiment=self.embodiment_tag)
|
| 173 |
+
|
| 174 |
+
def backbone_inputs(self, mi: ModelInputs) -> BackboneInputs:
|
| 175 |
+
"""Unpadded :class:`BackboneInputs` from the padded host layout of ``mi``.
|
| 176 |
+
|
| 177 |
+
The host tables live in the static ``S_pad`` layout (``static-shape-plan.md`` §4.3-4.4); real token ``i`` sits
|
| 178 |
+
at ``slot_of_token[i]``, so ``rope_cos[0, slot_of_token]`` is the ``[S, 128]`` table of the reference sequence
|
| 179 |
+
(N1.6 text-slot padding keeps position ``i`` for token ``i``, so this is the ``arange`` table; N1.7's mRoPE ids
|
| 180 |
+
are the golden ``llm_position_ids`` for the first ``S`` tokens, ``foundation-f2-host.md`` §2).
|
| 181 |
+
"""
|
| 182 |
+
if mi.version != self.version:
|
| 183 |
+
raise ValueError(f"inputs are for {mi.version}, model is {self.version}")
|
| 184 |
+
if int(mi.embodiment_id.reshape(-1)[0]) != self.embodiment_id:
|
| 185 |
+
raise ValueError(
|
| 186 |
+
f"inputs carry embodiment slot {int(mi.embodiment_id.reshape(-1)[0])}, model {self.embodiment_id}"
|
| 187 |
+
)
|
| 188 |
+
if mi.input_ids.shape != (1, mi.seq_len) or mi.attention_mask.shape != (1, mi.seq_len):
|
| 189 |
+
raise ValueError(f"input_ids / attention_mask must be [1, S={mi.seq_len}]")
|
| 190 |
+
if not bool((mi.attention_mask != 0).all()):
|
| 191 |
+
raise ValueError("the reference backbone runs the unpadded B=1 sequence; attention_mask must be all ones")
|
| 192 |
+
slot = mi.slots.slot_of_token
|
| 193 |
+
if tuple(slot.shape) != (mi.seq_len,):
|
| 194 |
+
raise ValueError(f"slot_of_token must be [S], got {tuple(slot.shape)}")
|
| 195 |
+
rope_cos = mi.rope_cos[0][slot]
|
| 196 |
+
rope_sin = mi.rope_sin[0][slot]
|
| 197 |
+
position_ids = None
|
| 198 |
+
if self.version == "n17":
|
| 199 |
+
if mi.position_ids.ndim != 3 or mi.position_ids.shape[:2] != (3, 1):
|
| 200 |
+
raise ValueError(f"N1.7 position_ids must be [3, 1, S_pad], got {tuple(mi.position_ids.shape)}")
|
| 201 |
+
position_ids = mi.position_ids[:, 0, :][:, slot]
|
| 202 |
+
return self.backbone.prepare_inputs(
|
| 203 |
+
mi.input_ids[0],
|
| 204 |
+
mi.pixel_values,
|
| 205 |
+
image_grid_thw=mi.image_grid_thw,
|
| 206 |
+
rope_cos=rope_cos,
|
| 207 |
+
rope_sin=rope_sin,
|
| 208 |
+
position_ids=position_ids,
|
| 209 |
+
)
|
| 210 |
+
|
| 211 |
+
# ------------------------------------------------------------------ model
|
| 212 |
+
@torch.no_grad()
|
| 213 |
+
def forward_from_inputs(
|
| 214 |
+
self,
|
| 215 |
+
inputs: ModelInputs,
|
| 216 |
+
noise: Optional[Tensor] = None,
|
| 217 |
+
seed: Optional[int] = None,
|
| 218 |
+
return_taps: bool = False,
|
| 219 |
+
*,
|
| 220 |
+
euler_dtype: Optional[str] = None,
|
| 221 |
+
) -> ReferenceOutput:
|
| 222 |
+
"""Backbone + action head + sampler on pre-encoded inputs -> normalised action chunk (no decode).
|
| 223 |
+
|
| 224 |
+
``taps`` (when ``return_taps``) merges the backbone taps (``vit_*``, ``projector_*``, ``llm_*``,
|
| 225 |
+
``backbone_features``), the head taps (``vlln_out`` ... ``action_pred_normalized``, per-step ``[k=<step>]``)
|
| 226 |
+
and the host tensors ``initial_noise``, ``image_mask``, ``backbone_attention_mask``, ``llm_rotary_cos/sin``,
|
| 227 |
+
``llm_position_ids`` (N1.7) under the golden tap names of ``golden-tap-map-and-thresholds.md`` §2.
|
| 228 |
+
"""
|
| 229 |
+
ed = self.euler_dtype if euler_dtype is None else euler_dtype
|
| 230 |
+
if ed not in EULER_DTYPES:
|
| 231 |
+
raise ValueError(f"euler_dtype must be one of {EULER_DTYPES}, got {ed!r}")
|
| 232 |
+
x0 = self._resolve_noise(noise, seed)
|
| 233 |
+
timing: Dict[str, float] = {}
|
| 234 |
+
|
| 235 |
+
t0 = time.perf_counter()
|
| 236 |
+
bi = self.backbone_inputs(inputs)
|
| 237 |
+
if return_taps:
|
| 238 |
+
features, taps = self.backbone(bi, return_taps=True)
|
| 239 |
+
else:
|
| 240 |
+
features, taps = self.backbone(bi), {}
|
| 241 |
+
t1 = time.perf_counter()
|
| 242 |
+
timing["backbone"] = t1 - t0
|
| 243 |
+
|
| 244 |
+
features_b = features[None] # [1, S, 2048]
|
| 245 |
+
image_mask = bi.image_mask[None]
|
| 246 |
+
attn_mask = inputs.attention_mask.to(torch.bool)
|
| 247 |
+
head_taps: Optional[Dict[str, Tensor]] = taps if return_taps else None
|
| 248 |
+
cond = self.head.prepare(
|
| 249 |
+
features_b,
|
| 250 |
+
inputs.state,
|
| 251 |
+
inputs.embodiment_id,
|
| 252 |
+
image_mask,
|
| 253 |
+
attn_mask,
|
| 254 |
+
hoist_cross_kv=self.hoist_cross_kv,
|
| 255 |
+
taps=head_taps,
|
| 256 |
+
)
|
| 257 |
+
t2 = time.perf_counter()
|
| 258 |
+
timing["head_prepare"] = t2 - t1
|
| 259 |
+
x = self.sampler.sample(
|
| 260 |
+
x0, cond, tables=self.adaln_tables, cross_form=self.cross_form, euler_dtype=ed, taps=head_taps
|
| 261 |
+
)
|
| 262 |
+
t3 = time.perf_counter()
|
| 263 |
+
timing["sampler"] = t3 - t2
|
| 264 |
+
if return_taps:
|
| 265 |
+
taps["initial_noise"] = x0
|
| 266 |
+
taps["image_mask"] = image_mask
|
| 267 |
+
taps["backbone_attention_mask"] = attn_mask
|
| 268 |
+
taps["llm_rotary_cos"] = bi.rope_cos
|
| 269 |
+
taps["llm_rotary_sin"] = bi.rope_sin
|
| 270 |
+
if bi.position_ids is not None:
|
| 271 |
+
taps["llm_position_ids"] = bi.position_ids
|
| 272 |
+
if tuple(x.shape) != self.noise_shape:
|
| 273 |
+
raise AssertionError(f"sampler returned {tuple(x.shape)}, expected {self.noise_shape}")
|
| 274 |
+
return ReferenceOutput(
|
| 275 |
+
version=self.version,
|
| 276 |
+
inputs=inputs,
|
| 277 |
+
noise=x0,
|
| 278 |
+
backbone_features=features_b,
|
| 279 |
+
action_pred_normalized=x,
|
| 280 |
+
actions=None,
|
| 281 |
+
taps=taps,
|
| 282 |
+
timing=timing,
|
| 283 |
+
)
|
| 284 |
+
|
| 285 |
+
def decode(self, action_pred_normalized: Tensor, observation: Observation) -> Dict[str, Tensor]:
|
| 286 |
+
""":func:`common.normalization.decode` with this model's embodiment (the observation supplies the reference
|
| 287 |
+
state of RELATIVE keys)."""
|
| 288 |
+
if observation.embodiment_tag != self.embodiment_tag:
|
| 289 |
+
raise ValueError(f"observation embodiment {observation.embodiment_tag!r} != model {self.embodiment_tag!r}")
|
| 290 |
+
return normalization.decode(self.version, action_pred_normalized, observation, embodiment=self.embodiment_tag)
|
| 291 |
+
|
| 292 |
+
@torch.no_grad()
|
| 293 |
+
def infer(
|
| 294 |
+
self,
|
| 295 |
+
observation: Observation,
|
| 296 |
+
noise: Optional[Tensor] = None,
|
| 297 |
+
seed: Optional[int] = None,
|
| 298 |
+
return_taps: bool = False,
|
| 299 |
+
*,
|
| 300 |
+
euler_dtype: Optional[str] = None,
|
| 301 |
+
) -> ReferenceOutput:
|
| 302 |
+
"""encode -> forward -> decode; the full :class:`ReferenceOutput` with per-stage timing."""
|
| 303 |
+
t0 = time.perf_counter()
|
| 304 |
+
mi = self.encode(observation)
|
| 305 |
+
t1 = time.perf_counter()
|
| 306 |
+
out = self.forward_from_inputs(mi, noise=noise, seed=seed, return_taps=return_taps, euler_dtype=euler_dtype)
|
| 307 |
+
t2 = time.perf_counter()
|
| 308 |
+
out.actions = self.decode(out.action_pred_normalized, observation)
|
| 309 |
+
t3 = time.perf_counter()
|
| 310 |
+
out.timing["encode"] = t1 - t0
|
| 311 |
+
out.timing["decode"] = t3 - t2
|
| 312 |
+
out.timing["total"] = t3 - t0
|
| 313 |
+
return out
|
| 314 |
+
|
| 315 |
+
def get_action(
|
| 316 |
+
self, observation: Observation, noise: Optional[Tensor] = None, seed: Optional[int] = None
|
| 317 |
+
) -> Dict[str, Tensor]:
|
| 318 |
+
"""Raw observation -> ``{action key: physical action [1, H, D] fp32}`` (the policy API).
|
| 319 |
+
|
| 320 |
+
``noise`` overrides the flow-matching x_0 (shape ``SamplerConfig.noise_shape``); otherwise it is drawn from a
|
| 321 |
+
CPU generator seeded with ``seed`` (default ``DEFAULT_NOISE_SEED[version]``). Same seed -> bit-identical output.
|
| 322 |
+
"""
|
| 323 |
+
return self.infer(observation, noise=noise, seed=seed).actions # type: ignore[return-value]
|
| 324 |
+
|
| 325 |
+
__call__ = get_action
|
| 326 |
+
|
| 327 |
+
def __repr__(self) -> str:
|
| 328 |
+
return (
|
| 329 |
+
f"Gr00tReference({self.version}, embodiment={self.embodiment_tag!r} (slot {self.embodiment_id}), "
|
| 330 |
+
f"euler_dtype={self.euler_dtype!r}, cross_form={self.cross_form!r})"
|
| 331 |
+
)
|
| 332 |
+
|
| 333 |
+
|
| 334 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 335 |
+
# Golden-sample plumbing shared by the tests and the CLI
|
| 336 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 337 |
+
|
| 338 |
+
|
| 339 |
+
def golden_obs_dir(gs: GoldenSet) -> Path:
|
| 340 |
+
"""``obs/`` directory next to the fp32 run of a golden sample (``golden/n15/obs``, ``golden/n16/fp32_math/obs``,
|
| 341 |
+
``golden/n17/droid_fp32_sdpa/obs``, and the multi-sample equivalents)."""
|
| 342 |
+
d = gs.path("input_ids").parent.parent / "obs"
|
| 343 |
+
if not d.is_dir():
|
| 344 |
+
raise FileNotFoundError(f"{gs.version}/{gs.sample}: no obs/ directory at {d}")
|
| 345 |
+
return d
|
| 346 |
+
|
| 347 |
+
|
| 348 |
+
def load_golden_sample(version: str, sample: Optional[str] = None) -> Tuple[GoldenSet, Observation]:
|
| 349 |
+
"""``(GoldenSet, raw Observation)`` of a golden sample (``None`` / ``"canonical"``, an N1.7 extra, or a multi name)."""
|
| 350 |
+
gs = GoldenSet(version, sample)
|
| 351 |
+
obs = load_golden_observation(version, golden_obs_dir(gs))
|
| 352 |
+
return gs, obs
|
| 353 |
+
|
| 354 |
+
|
| 355 |
+
def golden_sample_from_path(path: Union[str, Path]) -> Tuple[str, str]:
|
| 356 |
+
"""Map a golden directory (``golden/n17``, ``golden/n17/g1_synthetic_fp32_sdpa``, ``golden/n15_multi/t3_s20_seed1``,
|
| 357 |
+
``golden/n16_multi/t2_s50_fp32_sdpa``) to ``(version, sample name)``."""
|
| 358 |
+
p = Path(path).expanduser().resolve()
|
| 359 |
+
parts = p.parts
|
| 360 |
+
for i, part in enumerate(parts):
|
| 361 |
+
if part in GR00T_VERSIONS:
|
| 362 |
+
version = part
|
| 363 |
+
rest = parts[i + 1 :]
|
| 364 |
+
if not rest:
|
| 365 |
+
return version, "canonical"
|
| 366 |
+
if version == "n17" and len(rest) == 1:
|
| 367 |
+
name = rest[0]
|
| 368 |
+
for suffix in ("_fp32_sdpa", "_bf16_fa2"):
|
| 369 |
+
if name.endswith(suffix):
|
| 370 |
+
name = name[: -len(suffix)]
|
| 371 |
+
if name == "droid":
|
| 372 |
+
return version, "canonical"
|
| 373 |
+
return version, name
|
| 374 |
+
raise ValueError(f"{p}: not a golden sample directory")
|
| 375 |
+
if part.endswith("_multi") and part[: -len("_multi")] in GR00T_VERSIONS:
|
| 376 |
+
version = part[: -len("_multi")]
|
| 377 |
+
rest = parts[i + 1 :]
|
| 378 |
+
if not rest:
|
| 379 |
+
raise ValueError(f"{p}: name the sample under {part}/")
|
| 380 |
+
name = rest[0]
|
| 381 |
+
if version == "n16":
|
| 382 |
+
for suffix in ("_fp32_sdpa", "_bf16_fa2"):
|
| 383 |
+
if name.endswith(suffix):
|
| 384 |
+
name = name[: -len(suffix)]
|
| 385 |
+
return version, name
|
| 386 |
+
raise ValueError(f"{p}: no GR00T version component in the path")
|
| 387 |
+
|
| 388 |
+
|
| 389 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 390 |
+
# Golden tap mapping (shared by tests/reference/test_e2e_vs_golden.py and run_reference.py)
|
| 391 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 392 |
+
|
| 393 |
+
|
| 394 |
+
# golden input tap -> key of ModelInputs.golden_inputs()
|
| 395 |
+
GOLDEN_INPUT_KEYS: Dict[str, Dict[str, str]] = {
|
| 396 |
+
"n15": {
|
| 397 |
+
"input_ids": "eagle_input_ids",
|
| 398 |
+
"attention_mask": "eagle_attention_mask",
|
| 399 |
+
"pixel_values": "eagle_pixel_values",
|
| 400 |
+
"image_geometry": "eagle_image_sizes",
|
| 401 |
+
"state": "state",
|
| 402 |
+
"embodiment_id": "embodiment_id",
|
| 403 |
+
},
|
| 404 |
+
"n16": {
|
| 405 |
+
"input_ids": "input_ids",
|
| 406 |
+
"attention_mask": "attention_mask",
|
| 407 |
+
"pixel_values": "pixel_values.0",
|
| 408 |
+
"image_geometry": "image_sizes",
|
| 409 |
+
"state": "state",
|
| 410 |
+
"embodiment_id": "embodiment_id",
|
| 411 |
+
},
|
| 412 |
+
"n17": {
|
| 413 |
+
"input_ids": "input_ids",
|
| 414 |
+
"attention_mask": "attention_mask",
|
| 415 |
+
"pixel_values": "pixel_values",
|
| 416 |
+
"image_geometry": "image_grid_thw",
|
| 417 |
+
"state": "state",
|
| 418 |
+
"embodiment_id": "embodiment_id",
|
| 419 |
+
},
|
| 420 |
+
}
|
| 421 |
+
|
| 422 |
+
|
| 423 |
+
N16_WINDOWED_TAPS: Tuple[str, ...] = ("vit_embeddings", "vit_block_first", "vit_block_last")
|
| 424 |
+
|
| 425 |
+
|
| 426 |
+
def n16_reverse_mapping(gs: GoldenSet) -> torch.Tensor:
|
| 427 |
+
p = gs.path("input_ids").parent / "vision_reverse_mapping.pt"
|
| 428 |
+
if not p.is_file():
|
| 429 |
+
raise FileNotFoundError(p)
|
| 430 |
+
rm = torch.load(p, map_location="cpu", weights_only=True)
|
| 431 |
+
if rm.ndim != 1 or rm.dtype != torch.int64:
|
| 432 |
+
raise ValueError(f"vision_reverse_mapping must be a 1-D int64 index, got {tuple(rm.shape)} {rm.dtype}")
|
| 433 |
+
return rm
|
| 434 |
+
|
| 435 |
+
|
| 436 |
+
def n16_windowed_to_raster(gs: GoldenSet, ref: torch.Tensor) -> torch.Tensor:
|
| 437 |
+
"""N1.6 vision goldens are stored in Eagle window order: ``golden[0][reverse_mapping]`` is raster order
|
| 438 |
+
(foundation-f3a §3), i.e. the order of the reference's ``vit_*`` taps."""
|
| 439 |
+
if ref.ndim != 3 or ref.shape[0] != 1:
|
| 440 |
+
raise ValueError(f"windowed vision golden must be [1, P, C], got {tuple(ref.shape)}")
|
| 441 |
+
return ref[0][n16_reverse_mapping(gs)][None]
|
| 442 |
+
|
| 443 |
+
|
| 444 |
+
def n16_raster_to_windowed(gs: GoldenSet, got: torch.Tensor) -> torch.Tensor:
|
| 445 |
+
"""Inverse of :func:`n16_windowed_to_raster` (for the official gate, which loads the windowed golden)."""
|
| 446 |
+
if got.ndim != 3 or got.shape[0] != 1:
|
| 447 |
+
raise ValueError(f"raster vision tensor must be [1, P, C], got {tuple(got.shape)}")
|
| 448 |
+
w = torch.empty_like(got)
|
| 449 |
+
w[0][n16_reverse_mapping(gs)] = got[0]
|
| 450 |
+
return w
|
| 451 |
+
|
| 452 |
+
|
| 453 |
+
def reference_tap_tensor(out: ReferenceOutput, gs: GoldenSet, tap: str, kw: Dict[str, Any]) -> Optional[torch.Tensor]:
|
| 454 |
+
"""The reference's counterpart of golden ``tap`` (``None`` when the reference has no such tensor)."""
|
| 455 |
+
v = gs.version
|
| 456 |
+
cfg = get_config(v)
|
| 457 |
+
taps = out.taps
|
| 458 |
+
if tap in GOLDEN_INPUT_KEYS[v]:
|
| 459 |
+
return out.inputs.golden_inputs()[GOLDEN_INPUT_KEYS[v][tap]]
|
| 460 |
+
if tap == "vit_embeddings":
|
| 461 |
+
return taps["vit_patch_embed"] if v == "n17" else taps["vit_embeddings"] # N1.7 golden is PRE pos-add
|
| 462 |
+
if tap == "vit_block_first":
|
| 463 |
+
return taps["vit_block_0"]
|
| 464 |
+
if tap == "vit_block_last":
|
| 465 |
+
return taps[f"vit_block_{cfg.vision.n_layers - 1}"]
|
| 466 |
+
if tap == "vit_post_ln":
|
| 467 |
+
return taps.get("vit_post_ln")
|
| 468 |
+
if tap == "vit_deepstack_mergers":
|
| 469 |
+
return taps[f"vit_deepstack_{kw['deepstack']}"]
|
| 470 |
+
if tap == "llm_layer_first":
|
| 471 |
+
return taps["llm_layer_0"]
|
| 472 |
+
if tap == "llm_layer_last":
|
| 473 |
+
return taps[f"llm_layer_{cfg.llm.n_layers_executed - 1}"]
|
| 474 |
+
if tap == "action_pred_valid":
|
| 475 |
+
h, d = gs.valid_hd
|
| 476 |
+
return out.action_pred_normalized[:, :h, :d]
|
| 477 |
+
if tap == "unnormalized_actions":
|
| 478 |
+
if out.actions is None:
|
| 479 |
+
raise ValueError("decode() was not run")
|
| 480 |
+
return out.actions[kw["group"]]
|
| 481 |
+
if "step" in kw:
|
| 482 |
+
return taps.get(f"{tap}[k={kw['step']}]")
|
| 483 |
+
return taps.get(tap) # projector_out, llm_*, backbone_*, image_mask, vlln_out, ..., action_pred_normalized
|
| 484 |
+
|
| 485 |
+
|
| 486 |
+
def golden_tap_tensor(gs: GoldenSet, tap: str, kw: Dict[str, Any]) -> torch.Tensor:
|
| 487 |
+
ref = gs.load(tap, **kw)
|
| 488 |
+
if gs.version == "n16" and tap in N16_WINDOWED_TAPS:
|
| 489 |
+
ref = n16_windowed_to_raster(gs, ref)
|
| 490 |
+
return ref
|
| 491 |
+
|
| 492 |
+
|
| 493 |
+
def reconcile_shape(got: torch.Tensor, ref: torch.Tensor) -> torch.Tensor:
|
| 494 |
+
"""The reference drops the batch axis (``[S, C]`` vs golden ``[1, S, C]``; ``[3, S]`` vs ``[3, 1, S]``): reshape
|
| 495 |
+
when the element counts agree, raise otherwise."""
|
| 496 |
+
if tuple(got.shape) == tuple(ref.shape):
|
| 497 |
+
return got
|
| 498 |
+
if got.numel() == ref.numel():
|
| 499 |
+
return got.reshape(ref.shape)
|
| 500 |
+
raise ValueError(f"shape {tuple(got.shape)} vs golden {tuple(ref.shape)}")
|
| 501 |
+
|
| 502 |
+
|
| 503 |
+
def summarize_timing(timing: Mapping[str, float]) -> str:
|
| 504 |
+
return " ".join(f"{k}={timing[k] * 1e3:.1f}ms" for k in STAGES if k in timing)
|
| 505 |
+
|
| 506 |
+
|
| 507 |
+
__all__ = [
|
| 508 |
+
"DEFAULT_NOISE_SEED",
|
| 509 |
+
"GOLDEN_INPUT_KEYS",
|
| 510 |
+
"N16_WINDOWED_TAPS",
|
| 511 |
+
"STAGES",
|
| 512 |
+
"Gr00tReference",
|
| 513 |
+
"ReferenceOutput",
|
| 514 |
+
"golden_obs_dir",
|
| 515 |
+
"golden_sample_from_path",
|
| 516 |
+
"golden_tap_tensor",
|
| 517 |
+
"load_golden_sample",
|
| 518 |
+
"n16_raster_to_windowed",
|
| 519 |
+
"n16_reverse_mapping",
|
| 520 |
+
"n16_windowed_to_raster",
|
| 521 |
+
"reconcile_shape",
|
| 522 |
+
"reference_tap_tensor",
|
| 523 |
+
"summarize_timing",
|
| 524 |
+
]
|
code/models/experimental/gr00t/reference/qwen3vl_vision.py
ADDED
|
@@ -0,0 +1,381 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
|
| 4 |
+
"""Qwen3-VL vision tower of GR00T N1.7 (``Qwen3VLVisionModel`` of Cosmos-Reason2-2B) in plain fp32 torch.
|
| 5 |
+
|
| 6 |
+
Executable specification for the N1.7-only device tower (``01-architecture-synthesis.md`` §1.1 / §2.1 "Qwen3-VL vision
|
| 7 |
+
block"; arch-n17 §2.2; ``host-layout-helpers-validation.md`` §2):
|
| 8 |
+
|
| 9 |
+
* patch embedding ``Conv3d(3 -> 1024, (2, 16, 16))`` == ``Linear(1536 -> 1024)`` on the processor's ``(c, t, ph, pw)``
|
| 10 |
+
rows (no column permutation, ``host-layout`` §2.3); rows arrive in **merge-window order**
|
| 11 |
+
``(grid_t, gh/2, gw/2, mh, mw)``;
|
| 12 |
+
* learned ``pos_embed [2304, 1024]`` (48 x 48) bilinearly 4-tap interpolated to each image's ``(h, w)`` grid and permuted
|
| 13 |
+
to the same merge-window order, added once before block 0 (HF ``fast_pos_embed_interpolate``); the golden tap
|
| 14 |
+
``vis_patch_embed_out`` is taken **before** this add;
|
| 15 |
+
* 2-D RoPE theta 1e4, 16 frequencies per axis from full-resolution ``(row, col)`` patch coordinates, rotate-half layout
|
| 16 |
+
``cos/sin [P, 64]``, applied in fp32 to q and k in **every** block (HF ``rot_pos_emb`` / ``apply_rotary_pos_emb_vision``);
|
| 17 |
+
* 24 blocks ``x += attn(LN1 x); x += mlp(LN2 x)``: fused ``qkv Linear(1024 -> 3072)`` + bias split as
|
| 18 |
+
``reshape(P, 3, 16, 64)``, ``proj``, scale ``64**-0.5``, bidirectional attention **per image** (``cu_seqlens``);
|
| 19 |
+
``linear_fc1 1024 -> 4096`` GELU-tanh ``linear_fc2``; LN eps 1e-6 affine;
|
| 20 |
+
* deepstack mergers after blocks 5 / 11 / 17 (post-concat LN(4096)) and the final ``merger`` (pre-concat LN(1024)),
|
| 21 |
+
each ``-> Linear(4096 -> 4096) -> GELU(erf) -> Linear(4096 -> 2048)``, grouping 4 consecutive rows.
|
| 22 |
+
|
| 23 |
+
Host tables (``vision_pos_embeds``, ``vision_rope_tables``, ``vision_cu_seqlens``) are pure functions of ``grid_thw``;
|
| 24 |
+
they are DEDUPE CANDIDATES with ``common/preprocessing.py``. No ``ttnn`` import.
|
| 25 |
+
"""
|
| 26 |
+
|
| 27 |
+
from __future__ import annotations
|
| 28 |
+
|
| 29 |
+
from typing import Callable, Dict, List, Optional, Sequence, Tuple
|
| 30 |
+
|
| 31 |
+
import torch
|
| 32 |
+
import torch.nn.functional as F
|
| 33 |
+
|
| 34 |
+
from models.experimental.gr00t.reference.projectors import MergeMLPProjector, merge_consecutive_rows
|
| 35 |
+
from models.experimental.gr00t.reference.qwen3 import apply_rope, rope_inv_freq
|
| 36 |
+
from models.experimental.gr00t.reference.siglip import full_attention, gelu_tanh, layer_norm
|
| 37 |
+
|
| 38 |
+
WeightGetter = Callable[[str], torch.Tensor]
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 42 |
+
# Host tables (functions of grid_thw only)
|
| 43 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 44 |
+
|
| 45 |
+
|
| 46 |
+
def _check_grid(grid_thw: torch.Tensor) -> None:
|
| 47 |
+
if grid_thw.ndim != 2 or grid_thw.shape[1] != 3:
|
| 48 |
+
raise ValueError(f"grid_thw must be [n_img, 3] (t, h, w), got {tuple(grid_thw.shape)}")
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def vision_pos_embeds(
|
| 52 |
+
pos_table: torch.Tensor, grid_thw: torch.Tensor, num_grid_per_side: int = 48, spatial_merge_size: int = 2
|
| 53 |
+
) -> torch.Tensor:
|
| 54 |
+
"""``[sum(t*h*w), D]`` position rows in merge-window order -- pure-torch copy of HF ``fast_pos_embed_interpolate``
|
| 55 |
+
(``modeling_qwen3_vl.py:642-701``; ``host-layout`` §2.4: taps ``linspace(0, 47, h)`` / ``linspace(0, 47, w)``,
|
| 56 |
+
floor/ceil corners clipped to 47, bilinear weights, then ``view(t, h/2, 2, w/2, 2, D).permute(0, 1, 3, 2, 4, 5)``).
|
| 57 |
+
"""
|
| 58 |
+
_check_grid(grid_thw)
|
| 59 |
+
if pos_table.ndim != 2 or pos_table.shape[0] != num_grid_per_side**2:
|
| 60 |
+
raise ValueError(f"pos table {tuple(pos_table.shape)} is not {num_grid_per_side}^2 rows")
|
| 61 |
+
m = spatial_merge_size
|
| 62 |
+
out: List[torch.Tensor] = []
|
| 63 |
+
for t, h, w in grid_thw.tolist():
|
| 64 |
+
t, h, w = int(t), int(h), int(w)
|
| 65 |
+
if h % m or w % m:
|
| 66 |
+
raise ValueError(f"grid ({h}, {w}) not divisible by the merge size {m}")
|
| 67 |
+
h_idx = torch.linspace(0, num_grid_per_side - 1, h)
|
| 68 |
+
w_idx = torch.linspace(0, num_grid_per_side - 1, w)
|
| 69 |
+
h_floor = h_idx.int()
|
| 70 |
+
w_floor = w_idx.int()
|
| 71 |
+
h_ceil = (h_floor + 1).clip(max=num_grid_per_side - 1)
|
| 72 |
+
w_ceil = (w_floor + 1).clip(max=num_grid_per_side - 1)
|
| 73 |
+
dh = h_idx - h_floor
|
| 74 |
+
dw = w_idx - w_floor
|
| 75 |
+
base_h = (h_floor * num_grid_per_side).long()
|
| 76 |
+
base_h_ceil = (h_ceil * num_grid_per_side).long()
|
| 77 |
+
corners = [
|
| 78 |
+
(base_h[:, None] + w_floor.long()[None, :]).flatten(),
|
| 79 |
+
(base_h[:, None] + w_ceil.long()[None, :]).flatten(),
|
| 80 |
+
(base_h_ceil[:, None] + w_floor.long()[None, :]).flatten(),
|
| 81 |
+
(base_h_ceil[:, None] + w_ceil.long()[None, :]).flatten(),
|
| 82 |
+
]
|
| 83 |
+
weights = [
|
| 84 |
+
((1 - dh)[:, None] * (1 - dw)[None, :]).flatten(),
|
| 85 |
+
((1 - dh)[:, None] * dw[None, :]).flatten(),
|
| 86 |
+
(dh[:, None] * (1 - dw)[None, :]).flatten(),
|
| 87 |
+
(dh[:, None] * dw[None, :]).flatten(),
|
| 88 |
+
]
|
| 89 |
+
pe = pos_table[corners[0]] * weights[0][:, None]
|
| 90 |
+
for c, wt in zip(corners[1:], weights[1:]):
|
| 91 |
+
pe = pe + pos_table[c] * wt[:, None]
|
| 92 |
+
pe = pe.repeat(t, 1)
|
| 93 |
+
pe = pe.view(t, h // m, m, w // m, m, -1).permute(0, 1, 3, 2, 4, 5).reshape(t * h * w, -1)
|
| 94 |
+
out.append(pe)
|
| 95 |
+
return torch.cat(out, dim=0)
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
def vision_rope_position_ids(grid_thw: torch.Tensor, spatial_merge_size: int = 2) -> torch.Tensor:
|
| 99 |
+
"""``[P, 2]`` full-resolution ``(row, col)`` patch coordinates in merge-window order (HF ``rot_pos_emb``,
|
| 100 |
+
``modeling_qwen3_vl.py:603-640``)."""
|
| 101 |
+
_check_grid(grid_thw)
|
| 102 |
+
m = spatial_merge_size
|
| 103 |
+
out: List[torch.Tensor] = []
|
| 104 |
+
for t, h, w in grid_thw.tolist():
|
| 105 |
+
t, h, w = int(t), int(h), int(w)
|
| 106 |
+
rows = torch.arange(h).view(h // m, m, 1, 1).expand(h // m, m, w // m, m).permute(0, 2, 1, 3).reshape(-1)
|
| 107 |
+
cols = torch.arange(w).view(1, 1, w // m, m).expand(h // m, m, w // m, m).permute(0, 2, 1, 3).reshape(-1)
|
| 108 |
+
out.append(torch.stack((rows, cols), dim=-1).repeat(t, 1))
|
| 109 |
+
return torch.cat(out, dim=0)
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
def vision_rope_tables(
|
| 113 |
+
grid_thw: torch.Tensor, head_dim: int = 64, spatial_merge_size: int = 2, theta: float = 10000.0
|
| 114 |
+
) -> Tuple[torch.Tensor, torch.Tensor]:
|
| 115 |
+
"""``cos, sin [P, head_dim]``: ``emb[0:16] = row * inv_freq``, ``emb[16:32] = col * inv_freq`` (16 frequencies of
|
| 116 |
+
``Qwen3VLVisionRotaryEmbedding(dim=32)``), duplicated to 64 (rotate-half layout); ``host-layout`` §2.5."""
|
| 117 |
+
pos = vision_rope_position_ids(grid_thw, spatial_merge_size)
|
| 118 |
+
inv = rope_inv_freq(head_dim // 2, theta) # 16 frequencies (dim = head_dim/2 = 32 -> 16)
|
| 119 |
+
freqs = (pos.float()[:, :, None] * inv[None, None, :]).flatten(1) # [P, 32] = (row freqs | col freqs)
|
| 120 |
+
emb = torch.cat((freqs, freqs), dim=-1)
|
| 121 |
+
return emb.cos(), emb.sin()
|
| 122 |
+
|
| 123 |
+
|
| 124 |
+
def vision_cu_seqlens(grid_thw: torch.Tensor) -> List[int]:
|
| 125 |
+
"""Attention segment boundaries ``[0, n_1, n_1 + n_2, …]``: one segment per frame per image (HF
|
| 126 |
+
``repeat_interleave(h*w, t).cumsum``)."""
|
| 127 |
+
_check_grid(grid_thw)
|
| 128 |
+
bounds = [0]
|
| 129 |
+
for t, h, w in grid_thw.tolist():
|
| 130 |
+
for _ in range(int(t)):
|
| 131 |
+
bounds.append(bounds[-1] + int(h) * int(w))
|
| 132 |
+
return bounds
|
| 133 |
+
|
| 134 |
+
|
| 135 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 136 |
+
# Modules
|
| 137 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 138 |
+
|
| 139 |
+
|
| 140 |
+
class Qwen3VLPatchEmbed:
|
| 141 |
+
"""``Linear(1536 -> 1024)`` + bias on ``(c, t, ph, pw)`` rows (``Conv3d`` kernel flattened by ``reshape``)."""
|
| 142 |
+
|
| 143 |
+
def __init__(self, weight: torch.Tensor, bias: torch.Tensor):
|
| 144 |
+
if weight.ndim == 5:
|
| 145 |
+
weight = weight.reshape(weight.shape[0], -1).contiguous() # (c, t, ph, pw) column order, no permutation
|
| 146 |
+
if weight.ndim != 2 or bias.shape != (weight.shape[0],):
|
| 147 |
+
raise ValueError(f"patch weight/bias {tuple(weight.shape)} / {tuple(bias.shape)}")
|
| 148 |
+
self.weight, self.bias = weight, bias
|
| 149 |
+
self.in_features, self.hidden = weight.shape[1], weight.shape[0]
|
| 150 |
+
|
| 151 |
+
def forward(self, pixel_values: torch.Tensor) -> torch.Tensor:
|
| 152 |
+
"""``[P, 1536] -> [P, 1024]`` (the golden ``vis_patch_embed_out``, before the pos-embed add)."""
|
| 153 |
+
if pixel_values.ndim != 2 or pixel_values.shape[1] != self.in_features:
|
| 154 |
+
raise ValueError(f"pixel_values must be [P, {self.in_features}], got {tuple(pixel_values.shape)}")
|
| 155 |
+
return F.linear(pixel_values, self.weight, self.bias)
|
| 156 |
+
|
| 157 |
+
__call__ = forward
|
| 158 |
+
|
| 159 |
+
|
| 160 |
+
class Qwen3VLVisionAttention:
|
| 161 |
+
"""Fused-qkv bidirectional attention 16 x 64 with 2-D RoPE (fp32) and per-image segments."""
|
| 162 |
+
|
| 163 |
+
def __init__(
|
| 164 |
+
self, w_qkv: torch.Tensor, b_qkv: torch.Tensor, w_proj: torch.Tensor, b_proj: torch.Tensor, n_heads: int
|
| 165 |
+
):
|
| 166 |
+
hidden = w_qkv.shape[1]
|
| 167 |
+
if tuple(w_qkv.shape) != (3 * hidden, hidden) or b_qkv.shape != (3 * hidden,):
|
| 168 |
+
raise ValueError(f"fused qkv {tuple(w_qkv.shape)} / {tuple(b_qkv.shape)} != (3*{hidden}, {hidden})")
|
| 169 |
+
if tuple(w_proj.shape) != (hidden, hidden) or b_proj.shape != (hidden,):
|
| 170 |
+
raise ValueError(f"proj {tuple(w_proj.shape)} / {tuple(b_proj.shape)}")
|
| 171 |
+
if hidden % n_heads:
|
| 172 |
+
raise ValueError(f"hidden {hidden} not divisible by {n_heads} heads")
|
| 173 |
+
self.w_qkv, self.b_qkv, self.w_proj, self.b_proj = w_qkv, b_qkv, w_proj, b_proj
|
| 174 |
+
self.n_heads = n_heads
|
| 175 |
+
self.head_dim = hidden // n_heads
|
| 176 |
+
self.scale = self.head_dim**-0.5
|
| 177 |
+
|
| 178 |
+
def forward(self, x: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor, cu_seqlens: Sequence[int]) -> torch.Tensor:
|
| 179 |
+
"""``x [P, C]``, ``cos/sin [P, head_dim]`` -> ``[P, C]``."""
|
| 180 |
+
p = x.shape[0]
|
| 181 |
+
h, d = self.n_heads, self.head_dim
|
| 182 |
+
q, k, v = F.linear(x, self.w_qkv, self.b_qkv).reshape(p, 3, h, d).permute(1, 2, 0, 3) # each [H, P, d]
|
| 183 |
+
q = apply_rope(q.float(), cos, sin)
|
| 184 |
+
k = apply_rope(k.float(), cos, sin)
|
| 185 |
+
if cu_seqlens[0] != 0 or cu_seqlens[-1] != p:
|
| 186 |
+
raise ValueError(f"cu_seqlens {list(cu_seqlens)} do not cover {p} patches")
|
| 187 |
+
outs = []
|
| 188 |
+
for a, b in zip(cu_seqlens[:-1], cu_seqlens[1:]):
|
| 189 |
+
outs.append(full_attention(q[:, a:b], k[:, a:b], v[:, a:b], self.scale))
|
| 190 |
+
o = torch.cat(outs, dim=1).transpose(0, 1).reshape(p, h * d)
|
| 191 |
+
return F.linear(o, self.w_proj, self.b_proj)
|
| 192 |
+
|
| 193 |
+
__call__ = forward
|
| 194 |
+
|
| 195 |
+
|
| 196 |
+
class Qwen3VLVisionBlock:
|
| 197 |
+
"""``x += attn(LN1 x); x += fc2(gelu_tanh(fc1(LN2 x)))`` (``Qwen3VLVisionBlock``, LN eps 1e-6)."""
|
| 198 |
+
|
| 199 |
+
def __init__(
|
| 200 |
+
self,
|
| 201 |
+
ln1_w: torch.Tensor,
|
| 202 |
+
ln1_b: torch.Tensor,
|
| 203 |
+
attn: Qwen3VLVisionAttention,
|
| 204 |
+
ln2_w: torch.Tensor,
|
| 205 |
+
ln2_b: torch.Tensor,
|
| 206 |
+
fc1_w: torch.Tensor,
|
| 207 |
+
fc1_b: torch.Tensor,
|
| 208 |
+
fc2_w: torch.Tensor,
|
| 209 |
+
fc2_b: torch.Tensor,
|
| 210 |
+
eps: float,
|
| 211 |
+
):
|
| 212 |
+
self.ln1_w, self.ln1_b, self.attn = ln1_w, ln1_b, attn
|
| 213 |
+
self.ln2_w, self.ln2_b = ln2_w, ln2_b
|
| 214 |
+
self.fc1_w, self.fc1_b, self.fc2_w, self.fc2_b = fc1_w, fc1_b, fc2_w, fc2_b
|
| 215 |
+
self.eps = eps
|
| 216 |
+
|
| 217 |
+
def forward(
|
| 218 |
+
self,
|
| 219 |
+
x: torch.Tensor,
|
| 220 |
+
cos: torch.Tensor,
|
| 221 |
+
sin: torch.Tensor,
|
| 222 |
+
cu_seqlens: Sequence[int],
|
| 223 |
+
return_taps: bool = False,
|
| 224 |
+
) -> Tuple[torch.Tensor, Dict[str, torch.Tensor]]:
|
| 225 |
+
h = layer_norm(x, self.ln1_w, self.ln1_b, self.eps)
|
| 226 |
+
a = self.attn(h, cos, sin, cu_seqlens)
|
| 227 |
+
x = x + a
|
| 228 |
+
h2 = layer_norm(x, self.ln2_w, self.ln2_b, self.eps)
|
| 229 |
+
m = F.linear(gelu_tanh(F.linear(h2, self.fc1_w, self.fc1_b)), self.fc2_w, self.fc2_b)
|
| 230 |
+
x = x + m
|
| 231 |
+
taps = {"ln1": h, "attn": a, "ln2": h2, "mlp": m} if return_taps else {}
|
| 232 |
+
return x, taps
|
| 233 |
+
|
| 234 |
+
__call__ = forward
|
| 235 |
+
|
| 236 |
+
|
| 237 |
+
class Qwen3VLVisionEncoder:
|
| 238 |
+
"""Patch embed + pos add -> 24 blocks (2-D RoPE, per-image attention) -> deepstack mergers + final merger."""
|
| 239 |
+
|
| 240 |
+
def __init__(
|
| 241 |
+
self,
|
| 242 |
+
patch_embed: Qwen3VLPatchEmbed,
|
| 243 |
+
pos_table: torch.Tensor,
|
| 244 |
+
blocks: Sequence[Qwen3VLVisionBlock],
|
| 245 |
+
merger: MergeMLPProjector,
|
| 246 |
+
deepstack_mergers: Sequence[MergeMLPProjector],
|
| 247 |
+
deepstack_layers: Sequence[int],
|
| 248 |
+
num_grid_per_side: int = 48,
|
| 249 |
+
spatial_merge_size: int = 2,
|
| 250 |
+
rope_theta: float = 10000.0,
|
| 251 |
+
):
|
| 252 |
+
if len(deepstack_mergers) != len(deepstack_layers):
|
| 253 |
+
raise ValueError(f"{len(deepstack_mergers)} deepstack mergers for layers {tuple(deepstack_layers)}")
|
| 254 |
+
if merger.ln_position != "pre_concat" or any(m.ln_position != "post_concat" for m in deepstack_mergers):
|
| 255 |
+
raise ValueError("Qwen3-VL: final merger is pre-concat LN(1024), deepstack mergers post-concat LN(4096)")
|
| 256 |
+
self.patch_embed = patch_embed
|
| 257 |
+
self.pos_table = pos_table
|
| 258 |
+
self.blocks: List[Qwen3VLVisionBlock] = list(blocks)
|
| 259 |
+
self.merger = merger
|
| 260 |
+
self.deepstack_mergers: List[MergeMLPProjector] = list(deepstack_mergers)
|
| 261 |
+
self.deepstack_layers = tuple(deepstack_layers)
|
| 262 |
+
self.num_grid_per_side = num_grid_per_side
|
| 263 |
+
self.spatial_merge_size = spatial_merge_size
|
| 264 |
+
self.rope_theta = rope_theta
|
| 265 |
+
self.hidden = patch_embed.hidden
|
| 266 |
+
self.head_dim = blocks[0].attn.head_dim
|
| 267 |
+
|
| 268 |
+
@property
|
| 269 |
+
def n_layers(self) -> int:
|
| 270 |
+
return len(self.blocks)
|
| 271 |
+
|
| 272 |
+
def host_tables(self, grid_thw: torch.Tensor) -> Tuple[torch.Tensor, torch.Tensor, torch.Tensor, List[int]]:
|
| 273 |
+
"""``(pos_embeds [P, D], cos [P, hd], sin [P, hd], cu_seqlens)`` -- everything the device needs per layout."""
|
| 274 |
+
pos = vision_pos_embeds(self.pos_table, grid_thw, self.num_grid_per_side, self.spatial_merge_size)
|
| 275 |
+
cos, sin = vision_rope_tables(grid_thw, self.head_dim, self.spatial_merge_size, self.rope_theta)
|
| 276 |
+
return pos, cos, sin, vision_cu_seqlens(grid_thw)
|
| 277 |
+
|
| 278 |
+
def forward(
|
| 279 |
+
self,
|
| 280 |
+
pixel_values: torch.Tensor,
|
| 281 |
+
grid_thw: torch.Tensor,
|
| 282 |
+
return_taps: bool = False,
|
| 283 |
+
detail_blocks: Sequence[int] = (0,),
|
| 284 |
+
) -> Tuple[torch.Tensor, List[torch.Tensor], Dict[str, torch.Tensor]]:
|
| 285 |
+
"""``pixel_values [P, 1536]`` + ``grid_thw [n_img, 3]`` -> ``(image_embeds [P/4, 2048], deepstack [3 x [P/4, 2048]],
|
| 286 |
+
taps)``. Taps: ``patch_embed`` (pre-pos), ``embeddings`` (post-pos), ``block_{i}``, ``block_{i}_{ln1,attn,ln2,mlp}``
|
| 287 |
+
for ``detail_blocks``, ``deepstack_{d}``, ``merger``."""
|
| 288 |
+
pos, cos, sin, cu = self.host_tables(grid_thw)
|
| 289 |
+
lin = self.patch_embed(pixel_values)
|
| 290 |
+
if lin.shape[0] != pos.shape[0]:
|
| 291 |
+
raise ValueError(f"{lin.shape[0]} patch rows but grid_thw implies {pos.shape[0]}")
|
| 292 |
+
x = lin + pos
|
| 293 |
+
taps: Dict[str, torch.Tensor] = {}
|
| 294 |
+
if return_taps:
|
| 295 |
+
taps["patch_embed"] = lin
|
| 296 |
+
taps["embeddings"] = x
|
| 297 |
+
deepstack: List[torch.Tensor] = []
|
| 298 |
+
for i, blk in enumerate(self.blocks):
|
| 299 |
+
x, bt = blk(x, cos, sin, cu, return_taps and i in detail_blocks)
|
| 300 |
+
if return_taps:
|
| 301 |
+
taps[f"block_{i}"] = x
|
| 302 |
+
for k, v in bt.items():
|
| 303 |
+
taps[f"block_{i}_{k}"] = v
|
| 304 |
+
if i in self.deepstack_layers:
|
| 305 |
+
d = self.deepstack_layers.index(i)
|
| 306 |
+
feat, _ = self.deepstack_mergers[d](x, merge_consecutive_rows)
|
| 307 |
+
deepstack.append(feat)
|
| 308 |
+
if return_taps:
|
| 309 |
+
taps[f"deepstack_{d}"] = feat
|
| 310 |
+
out, _ = self.merger(x, merge_consecutive_rows)
|
| 311 |
+
if return_taps:
|
| 312 |
+
taps["merger"] = out
|
| 313 |
+
return out, deepstack, taps
|
| 314 |
+
|
| 315 |
+
__call__ = forward
|
| 316 |
+
|
| 317 |
+
@classmethod
|
| 318 |
+
def from_getter(
|
| 319 |
+
cls,
|
| 320 |
+
w: WeightGetter,
|
| 321 |
+
n_layers: int,
|
| 322 |
+
n_heads: int,
|
| 323 |
+
ln_eps: float,
|
| 324 |
+
merger_ln_eps: float,
|
| 325 |
+
deepstack_layers: Sequence[int],
|
| 326 |
+
num_grid_per_side: int = 48,
|
| 327 |
+
spatial_merge_size: int = 2,
|
| 328 |
+
rope_theta: float = 10000.0,
|
| 329 |
+
) -> "Qwen3VLVisionEncoder":
|
| 330 |
+
"""Build from canonical keys under ``visual.`` (``patch_embed.proj.*``, ``pos_embed.weight``, ``blocks.N.*``,
|
| 331 |
+
``merger.*``, ``deepstack_merger_list.k.*``; ``weight-loader-spec.md`` §2.3 / §4.2 N1.7)."""
|
| 332 |
+
patch = Qwen3VLPatchEmbed(w("patch_embed.proj.weight"), w("patch_embed.proj.bias"))
|
| 333 |
+
blocks = []
|
| 334 |
+
for i in range(n_layers):
|
| 335 |
+
p = f"blocks.{i}."
|
| 336 |
+
attn = Qwen3VLVisionAttention(
|
| 337 |
+
w(p + "attn.qkv.weight"),
|
| 338 |
+
w(p + "attn.qkv.bias"),
|
| 339 |
+
w(p + "attn.proj.weight"),
|
| 340 |
+
w(p + "attn.proj.bias"),
|
| 341 |
+
n_heads,
|
| 342 |
+
)
|
| 343 |
+
blocks.append(
|
| 344 |
+
Qwen3VLVisionBlock(
|
| 345 |
+
w(p + "norm1.weight"),
|
| 346 |
+
w(p + "norm1.bias"),
|
| 347 |
+
attn,
|
| 348 |
+
w(p + "norm2.weight"),
|
| 349 |
+
w(p + "norm2.bias"),
|
| 350 |
+
w(p + "mlp.linear_fc1.weight"),
|
| 351 |
+
w(p + "mlp.linear_fc1.bias"),
|
| 352 |
+
w(p + "mlp.linear_fc2.weight"),
|
| 353 |
+
w(p + "mlp.linear_fc2.bias"),
|
| 354 |
+
ln_eps,
|
| 355 |
+
)
|
| 356 |
+
)
|
| 357 |
+
merger = MergeMLPProjector.from_getter(
|
| 358 |
+
w, "merger.norm.", "merger.linear_fc1.", "merger.linear_fc2.", merger_ln_eps, "pre_concat"
|
| 359 |
+
)
|
| 360 |
+
deep = [
|
| 361 |
+
MergeMLPProjector.from_getter(
|
| 362 |
+
w,
|
| 363 |
+
f"deepstack_merger_list.{d}.norm.",
|
| 364 |
+
f"deepstack_merger_list.{d}.linear_fc1.",
|
| 365 |
+
f"deepstack_merger_list.{d}.linear_fc2.",
|
| 366 |
+
merger_ln_eps,
|
| 367 |
+
"post_concat",
|
| 368 |
+
)
|
| 369 |
+
for d in range(len(deepstack_layers))
|
| 370 |
+
]
|
| 371 |
+
return cls(
|
| 372 |
+
patch,
|
| 373 |
+
w("pos_embed.weight"),
|
| 374 |
+
blocks,
|
| 375 |
+
merger,
|
| 376 |
+
deep,
|
| 377 |
+
deepstack_layers,
|
| 378 |
+
num_grid_per_side,
|
| 379 |
+
spatial_merge_size,
|
| 380 |
+
rope_theta,
|
| 381 |
+
)
|
code/models/experimental/gr00t/reference/sampler.py
ADDED
|
@@ -0,0 +1,239 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
|
| 4 |
+
"""Flow-matching Euler sampler of the GR00T action head (synthesis §1.6; arch-n15 §3.7, arch-n16 §7.6, arch-n17 §3.4).
|
| 5 |
+
|
| 6 |
+
::
|
| 7 |
+
|
| 8 |
+
x_0 = noise # [1, H, max_action_dim], supplied by the caller (all dims noisy)
|
| 9 |
+
for k in 0..3: bucket_k = int(k / 4 * 1000) # 0, 250, 500, 750
|
| 10 |
+
v_k = head(x_k, bucket_k) # velocity = decoder rows -H:
|
| 11 |
+
x_{k+1} = x_k + 0.25 * v_k
|
| 12 |
+
return x_4 # normalised action chunk
|
| 13 |
+
|
| 14 |
+
Two device-oriented decompositions are available and asserted equal to the live path by the tests:
|
| 15 |
+
|
| 16 |
+
* :func:`precompute_adaln_tables` -- every timestep-dependent vector (``temb``, per-block ``(1 + scale, shift)``, output
|
| 17 |
+
head ``(1 + scale, shift)``) for the 4 fixed buckets, computed from the raw ``norm1.linear`` / ``proj_out_1`` /
|
| 18 |
+
timestep-encoder weights (weight-loader-spec.md §4.6 'precompute'); ``FlowMatchingSampler.sample(tables=...)`` runs
|
| 19 |
+
the DiT with them instead of the live timestep encoder.
|
| 20 |
+
* ``hoist_cross_kv=True`` -- cross-attention K/V of the 8 / 16 cross blocks computed once from the gathered key subset
|
| 21 |
+
and reused for the 4 steps (arch-n15 §3.6).
|
| 22 |
+
|
| 23 |
+
Euler dtype conventions (golden-tap-map-and-thresholds.md §2.1, ``SamplerConfig.euler_dtype``):
|
| 24 |
+
|
| 25 |
+
* ``"fp32"`` -- the fp32 goldens: everything fp32 (default here).
|
| 26 |
+
* ``"fp32_actions_bf16_velocity"`` -- N1.5 official autocast path: actions stay fp32, ``0.25 * bf16(v)`` added.
|
| 27 |
+
* ``"bf16"`` -- N1.6 / N1.7 official path: ``bf16(bf16(x) + 0.25 * bf16(v))``.
|
| 28 |
+
"""
|
| 29 |
+
|
| 30 |
+
from __future__ import annotations
|
| 31 |
+
|
| 32 |
+
from dataclasses import dataclass
|
| 33 |
+
from typing import Dict, Optional, Sequence, Tuple
|
| 34 |
+
|
| 35 |
+
import torch
|
| 36 |
+
import torch.nn.functional as F
|
| 37 |
+
from torch import Tensor
|
| 38 |
+
|
| 39 |
+
from models.experimental.gr00t.common.configs import SamplerConfig
|
| 40 |
+
from models.experimental.gr00t.reference.action_head import ActionHead, Conditioning, CrossForm, DiT, StepModulation
|
| 41 |
+
|
| 42 |
+
EULER_DTYPES: Tuple[str, ...] = ("fp32", "fp32_actions_bf16_velocity", "bf16")
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 46 |
+
# Precomputed AdaLN tables
|
| 47 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
@dataclass(frozen=True)
|
| 51 |
+
class AdaLNTables:
|
| 52 |
+
"""``(1 + scale, shift)`` of every DiT block and of the output head, plus ``temb``, for each sampler bucket.
|
| 53 |
+
|
| 54 |
+
``steps[i]`` is the :class:`StepModulation` of ``buckets[i]``; :meth:`as_tensor` packs the modulation vectors into
|
| 55 |
+
one ``[n_steps, 2 * n_blocks + 2, 1536]`` table (row order: block0 one_plus_scale, block0 shift, block1 ..., head
|
| 56 |
+
one_plus_scale, head shift) -- the layout a device port would upload (weight-loader §4.6 'layout options').
|
| 57 |
+
"""
|
| 58 |
+
|
| 59 |
+
buckets: Tuple[int, ...]
|
| 60 |
+
steps: Tuple[StepModulation, ...]
|
| 61 |
+
|
| 62 |
+
def step(self, k: int) -> StepModulation:
|
| 63 |
+
return self.steps[k]
|
| 64 |
+
|
| 65 |
+
def for_bucket(self, bucket: int) -> StepModulation:
|
| 66 |
+
for s in self.steps:
|
| 67 |
+
if s.bucket == bucket:
|
| 68 |
+
return s
|
| 69 |
+
raise KeyError(f"no precomputed modulation for bucket {bucket}; have {self.buckets}")
|
| 70 |
+
|
| 71 |
+
@property
|
| 72 |
+
def n_blocks(self) -> int:
|
| 73 |
+
return self.steps[0].n_blocks
|
| 74 |
+
|
| 75 |
+
@property
|
| 76 |
+
def n_vectors(self) -> int:
|
| 77 |
+
"""Modulation vectors stored (excluding ``temb``): ``n_steps * (2 * n_blocks + 2)`` = 136 (N1.5) / 264 (N1.6, N1.7)."""
|
| 78 |
+
return len(self.steps) * (2 * self.n_blocks + 2)
|
| 79 |
+
|
| 80 |
+
def as_tensor(self) -> Tensor:
|
| 81 |
+
rows = []
|
| 82 |
+
for s in self.steps:
|
| 83 |
+
vecs = []
|
| 84 |
+
for o, sh in zip(s.block_one_plus_scale, s.block_shift):
|
| 85 |
+
vecs += [o, sh]
|
| 86 |
+
vecs += [s.head_one_plus_scale, s.head_shift]
|
| 87 |
+
rows.append(torch.cat(vecs, dim=0))
|
| 88 |
+
return torch.stack(rows, dim=0)
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
def precompute_adaln_tables(dit: DiT, buckets: Sequence[int] = (0, 250, 500, 750)) -> AdaLNTables:
|
| 92 |
+
"""Host-side precompute of weight-loader-spec.md §4.6 from the raw weights (independent of ``DiT.modulation``)::
|
| 93 |
+
|
| 94 |
+
proj = [cos e, sin e], e = t * exp(-ln(1e4) * arange(128) / 127)
|
| 95 |
+
temb = W2 @ silu(W1 @ proj + b1) + b2
|
| 96 |
+
s = silu(temb)
|
| 97 |
+
block: scale, shift = (Wn @ s + bn).chunk(2) -> (1 + scale, shift) (scale FIRST)
|
| 98 |
+
head: shift, scale = (Wp @ s + bp).chunk(2) -> (1 + scale, shift) (shift FIRST)
|
| 99 |
+
"""
|
| 100 |
+
steps = []
|
| 101 |
+
te = dit.timestep_encoder
|
| 102 |
+
for b in buckets:
|
| 103 |
+
proj = te.projection(int(b))
|
| 104 |
+
temb = F.linear(
|
| 105 |
+
F.silu(F.linear(proj, te.linear_1.weight, te.linear_1.bias)), te.linear_2.weight, te.linear_2.bias
|
| 106 |
+
)
|
| 107 |
+
s = F.silu(temb)
|
| 108 |
+
ops, shs = [], []
|
| 109 |
+
for blk in dit.blocks:
|
| 110 |
+
scale, shift = F.linear(s, blk.norm1.linear.weight, blk.norm1.linear.bias).chunk(2, dim=-1)
|
| 111 |
+
ops.append(1.0 + scale)
|
| 112 |
+
shs.append(shift)
|
| 113 |
+
h_shift, h_scale = F.linear(s, dit.out.proj_out_1.weight, dit.out.proj_out_1.bias).chunk(2, dim=-1)
|
| 114 |
+
steps.append(StepModulation(int(b), temb, tuple(ops), tuple(shs), 1.0 + h_scale, h_shift))
|
| 115 |
+
return AdaLNTables(tuple(int(b) for b in buckets), tuple(steps))
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 119 |
+
# Euler update
|
| 120 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
def euler_update(actions: Tensor, velocity: Tensor, dt: float, euler_dtype: str = "fp32") -> Tensor:
|
| 124 |
+
"""``x + dt * v`` under one of the three reference dtype conventions (golden-tap-map §2.1 'Euler update dtype').
|
| 125 |
+
|
| 126 |
+
Returns fp32 in every mode (the bf16 modes return bf16-representable values)."""
|
| 127 |
+
if tuple(actions.shape) != tuple(velocity.shape):
|
| 128 |
+
raise ValueError(f"actions {tuple(actions.shape)} vs velocity {tuple(velocity.shape)}")
|
| 129 |
+
if euler_dtype == "fp32":
|
| 130 |
+
return actions.to(torch.float32) + dt * velocity.to(torch.float32)
|
| 131 |
+
if euler_dtype == "fp32_actions_bf16_velocity":
|
| 132 |
+
# autocast: the decoder output is bf16, `dt * v` stays bf16 (dt = 0.25 is exact), fp32 + bf16 -> fp32
|
| 133 |
+
return actions.to(torch.float32) + (dt * velocity.to(torch.bfloat16)).to(torch.float32)
|
| 134 |
+
if euler_dtype == "bf16":
|
| 135 |
+
v = velocity.to(torch.bfloat16)
|
| 136 |
+
return (actions.to(torch.bfloat16) + dt * v).to(torch.float32)
|
| 137 |
+
raise ValueError(f"euler_dtype must be one of {EULER_DTYPES}, got {euler_dtype!r}")
|
| 138 |
+
|
| 139 |
+
|
| 140 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 141 |
+
# Sampler
|
| 142 |
+
# --------------------------------------------------------------------------------------------------------------------
|
| 143 |
+
|
| 144 |
+
|
| 145 |
+
class FlowMatchingSampler:
|
| 146 |
+
"""4-step Euler flow matching over an :class:`ActionHead` (``SamplerConfig`` of the version)."""
|
| 147 |
+
|
| 148 |
+
def __init__(self, head: ActionHead, cfg: Optional[SamplerConfig] = None):
|
| 149 |
+
self.head = head
|
| 150 |
+
self.cfg = cfg if cfg is not None else head.cfg.sampler
|
| 151 |
+
if self.cfg.timestep_buckets != tuple(
|
| 152 |
+
self.cfg.timestep_bucket(k) for k in range(self.cfg.num_inference_timesteps)
|
| 153 |
+
):
|
| 154 |
+
raise ValueError("SamplerConfig buckets are inconsistent with int(k / N * buckets)")
|
| 155 |
+
if abs(self.cfg.dt - 1.0 / self.cfg.num_inference_timesteps) > 1e-12:
|
| 156 |
+
raise ValueError("SamplerConfig.dt != 1 / num_inference_timesteps")
|
| 157 |
+
|
| 158 |
+
@property
|
| 159 |
+
def buckets(self) -> Tuple[int, ...]:
|
| 160 |
+
return self.cfg.timestep_buckets
|
| 161 |
+
|
| 162 |
+
def precompute_adaln(self) -> AdaLNTables:
|
| 163 |
+
return precompute_adaln_tables(self.head.dit, self.buckets)
|
| 164 |
+
|
| 165 |
+
@torch.no_grad()
|
| 166 |
+
def sample(
|
| 167 |
+
self,
|
| 168 |
+
noise: Tensor,
|
| 169 |
+
cond: Conditioning,
|
| 170 |
+
*,
|
| 171 |
+
tables: Optional[AdaLNTables] = None,
|
| 172 |
+
cross_form: CrossForm = "mask",
|
| 173 |
+
euler_dtype: str = "fp32",
|
| 174 |
+
taps: Optional[Dict[str, Tensor]] = None,
|
| 175 |
+
) -> Tensor:
|
| 176 |
+
"""Integrate from ``noise`` (``[1, H, max_action_dim]``) to the normalised action chunk.
|
| 177 |
+
|
| 178 |
+
``taps`` (optional dict) receives every per-step tap under the golden key convention ``"<tap>[k=<step>]"``
|
| 179 |
+
(``noisy_actions_in``, ``timestep``, ``action_encoder_out``, ``sa_embs``, ``temb``, ``dit_block{i}_out``,
|
| 180 |
+
``dit_block_last_out``, ``dit_out``, ``action_decoder_out``, ``pred_velocity``, ``actions_out``) and the final
|
| 181 |
+
``action_pred_normalized``.
|
| 182 |
+
"""
|
| 183 |
+
if euler_dtype not in EULER_DTYPES:
|
| 184 |
+
raise ValueError(f"euler_dtype must be one of {EULER_DTYPES}, got {euler_dtype!r}")
|
| 185 |
+
if tuple(noise.shape) != self.cfg.noise_shape:
|
| 186 |
+
raise ValueError(f"noise must be {self.cfg.noise_shape}, got {tuple(noise.shape)}")
|
| 187 |
+
x = noise.to(torch.float32)
|
| 188 |
+
if euler_dtype == "bf16":
|
| 189 |
+
x = x.to(torch.bfloat16).to(torch.float32) # the official path feeds bf16(noise) (golden-tap-map §1)
|
| 190 |
+
for k in range(self.cfg.num_inference_timesteps):
|
| 191 |
+
bucket = self.cfg.timestep_bucket(k)
|
| 192 |
+
suffix = f"[k={k}]"
|
| 193 |
+
mod = tables.for_bucket(bucket) if tables is not None else None
|
| 194 |
+
v = self.head.denoise_step(
|
| 195 |
+
x, bucket, cond, modulation=mod, cross_form=cross_form, taps=taps, tap_suffix=suffix
|
| 196 |
+
)
|
| 197 |
+
x = euler_update(x, v, self.cfg.dt, euler_dtype)
|
| 198 |
+
if taps is not None:
|
| 199 |
+
taps["actions_out" + suffix] = x
|
| 200 |
+
if taps is not None:
|
| 201 |
+
taps["action_pred_normalized"] = x
|
| 202 |
+
return x
|
| 203 |
+
|
| 204 |
+
@torch.no_grad()
|
| 205 |
+
def run(
|
| 206 |
+
self,
|
| 207 |
+
backbone_features: Tensor,
|
| 208 |
+
state: Tensor,
|
| 209 |
+
embodiment_id,
|
| 210 |
+
noise: Tensor,
|
| 211 |
+
image_mask: Optional[Tensor] = None,
|
| 212 |
+
backbone_attention_mask: Optional[Tensor] = None,
|
| 213 |
+
*,
|
| 214 |
+
hoist_cross_kv: bool = False,
|
| 215 |
+
tables: Optional[AdaLNTables] = None,
|
| 216 |
+
cross_form: CrossForm = "mask",
|
| 217 |
+
euler_dtype: str = "fp32",
|
| 218 |
+
return_taps: bool = False,
|
| 219 |
+
) -> Tuple[Tensor, Dict[str, Tensor]]:
|
| 220 |
+
"""``prepare`` + ``sample``; returns ``(action_pred_normalized, taps)`` (``taps`` empty unless requested)."""
|
| 221 |
+
taps: Dict[str, Tensor] = {}
|
| 222 |
+
cond = self.head.prepare(
|
| 223 |
+
backbone_features,
|
| 224 |
+
state,
|
| 225 |
+
embodiment_id,
|
| 226 |
+
image_mask,
|
| 227 |
+
backbone_attention_mask,
|
| 228 |
+
hoist_cross_kv=hoist_cross_kv,
|
| 229 |
+
taps=taps if return_taps else None,
|
| 230 |
+
)
|
| 231 |
+
x = self.sample(
|
| 232 |
+
noise,
|
| 233 |
+
cond,
|
| 234 |
+
tables=tables,
|
| 235 |
+
cross_form=cross_form,
|
| 236 |
+
euler_dtype=euler_dtype,
|
| 237 |
+
taps=taps if return_taps else None,
|
| 238 |
+
)
|
| 239 |
+
return x, taps
|
code/models/experimental/gr00t/tests/__init__.py
ADDED
|
@@ -0,0 +1,2 @@
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
code/scripts/bench_http.py
ADDED
|
@@ -0,0 +1,127 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
# SPDX-FileCopyrightText: © 2026 Tenstorrent USA, Inc.
|
| 3 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 4 |
+
"""HTTP latency of a running GR00T policy server: POST the shipped demo observation N times and report medians.
|
| 5 |
+
|
| 6 |
+
Standard library only. The numbers are the server's own ``timing_ms`` fields (``device`` = the four Metal trace
|
| 7 |
+
replays incl. input upload and the action readback; ``total`` = the whole ``/predict`` handler) plus the client's
|
| 8 |
+
wall-clock per request on the same host (adds JSON encode/decode and HTTP framing).
|
| 9 |
+
|
| 10 |
+
python scripts/bench_http.py --url http://127.0.0.1:20000 [--reps 50] [--warmup 10] [--out bench.json]
|
| 11 |
+
"""
|
| 12 |
+
|
| 13 |
+
from __future__ import annotations
|
| 14 |
+
|
| 15 |
+
import argparse
|
| 16 |
+
import base64
|
| 17 |
+
import json
|
| 18 |
+
import statistics
|
| 19 |
+
import sys
|
| 20 |
+
import time
|
| 21 |
+
import urllib.request
|
| 22 |
+
from pathlib import Path
|
| 23 |
+
from typing import Any, Dict, List
|
| 24 |
+
|
| 25 |
+
HERE = Path(__file__).resolve().parent
|
| 26 |
+
DEMO_ROOT = HERE.parent / "gr00t_p150" / "demo"
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
def load_request(demo_dir: Path, use_noise: bool) -> Dict[str, Any]:
|
| 30 |
+
with open(demo_dir / "observation.json") as fh:
|
| 31 |
+
obs = json.load(fh)
|
| 32 |
+
images = {
|
| 33 |
+
cam: [base64.b64encode((demo_dir / f).read_bytes()).decode("ascii") for f in files]
|
| 34 |
+
for cam, files in obs["cameras"].items()
|
| 35 |
+
}
|
| 36 |
+
req: Dict[str, Any] = {
|
| 37 |
+
"images": images,
|
| 38 |
+
"state": obs["state"],
|
| 39 |
+
"instruction": obs["instruction"],
|
| 40 |
+
"embodiment": obs["embodiment"],
|
| 41 |
+
"state_dtype": obs["state_dtype"],
|
| 42 |
+
}
|
| 43 |
+
if use_noise:
|
| 44 |
+
with open(demo_dir / "noise.json") as fh:
|
| 45 |
+
req["noise"] = json.load(fh)["data"]
|
| 46 |
+
return req
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
def post(url: str, payload: bytes, timeout: float = 120.0) -> Dict[str, Any]:
|
| 50 |
+
r = urllib.request.Request(url, data=payload, headers={"Content-Type": "application/json"}, method="POST")
|
| 51 |
+
with urllib.request.urlopen(r, timeout=timeout) as resp:
|
| 52 |
+
if resp.status != 200:
|
| 53 |
+
raise RuntimeError(f"HTTP {resp.status}")
|
| 54 |
+
return json.loads(resp.read().decode())
|
| 55 |
+
|
| 56 |
+
|
| 57 |
+
def pct(xs: List[float], q: float) -> float:
|
| 58 |
+
ys = sorted(xs)
|
| 59 |
+
k = max(0, min(len(ys) - 1, int(round(q * (len(ys) - 1)))))
|
| 60 |
+
return ys[k]
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
def main() -> int:
|
| 64 |
+
ap = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
|
| 65 |
+
ap.add_argument("--url", default="http://127.0.0.1:20000")
|
| 66 |
+
ap.add_argument("--reps", type=int, default=50)
|
| 67 |
+
ap.add_argument("--warmup", type=int, default=10)
|
| 68 |
+
ap.add_argument("--version", default=None, choices=["n15", "n16"], help="default: what /info reports")
|
| 69 |
+
ap.add_argument("--demo-dir", type=Path, default=None)
|
| 70 |
+
ap.add_argument(
|
| 71 |
+
"--seed-path", action="store_true", help="use the server's default seed instead of the golden noise"
|
| 72 |
+
)
|
| 73 |
+
ap.add_argument("--out", type=Path, default=None)
|
| 74 |
+
args = ap.parse_args()
|
| 75 |
+
url = args.url.rstrip("/")
|
| 76 |
+
|
| 77 |
+
with urllib.request.urlopen(f"{url}/info", timeout=30) as resp:
|
| 78 |
+
info = json.loads(resp.read().decode())
|
| 79 |
+
version = args.version or info.get("version")
|
| 80 |
+
demo_dir = args.demo_dir or (DEMO_ROOT / str(version))
|
| 81 |
+
payload = json.dumps(load_request(demo_dir, use_noise=not args.seed_path)).encode()
|
| 82 |
+
|
| 83 |
+
for _ in range(args.warmup):
|
| 84 |
+
post(f"{url}/predict", payload)
|
| 85 |
+
keys = ("decode", "encode", "device", "decode_actions", "total")
|
| 86 |
+
series: Dict[str, List[float]] = {k: [] for k in keys}
|
| 87 |
+
wall: List[float] = []
|
| 88 |
+
for _ in range(args.reps):
|
| 89 |
+
t0 = time.perf_counter()
|
| 90 |
+
r = post(f"{url}/predict", payload)
|
| 91 |
+
wall.append((time.perf_counter() - t0) * 1000.0)
|
| 92 |
+
for k in keys:
|
| 93 |
+
series[k].append(float(r["timing_ms"][k]))
|
| 94 |
+
summary: Dict[str, Any] = {
|
| 95 |
+
"url": url,
|
| 96 |
+
"model": info.get("name"),
|
| 97 |
+
"version": version,
|
| 98 |
+
"reps": args.reps,
|
| 99 |
+
"warmup": args.warmup,
|
| 100 |
+
"payload_bytes": len(payload),
|
| 101 |
+
"request": "demo observation" + (" + server default seed" if args.seed_path else " + golden noise"),
|
| 102 |
+
"timing_ms": {
|
| 103 |
+
k: {"median": statistics.median(v), "p90": pct(v, 0.9), "min": min(v), "max": max(v)}
|
| 104 |
+
for k, v in series.items()
|
| 105 |
+
},
|
| 106 |
+
"client_wall_ms": {
|
| 107 |
+
"median": statistics.median(wall),
|
| 108 |
+
"p90": pct(wall, 0.9),
|
| 109 |
+
"min": min(wall),
|
| 110 |
+
"max": max(wall),
|
| 111 |
+
},
|
| 112 |
+
"warmup_latency_ms": info.get("warmup_latency_ms"),
|
| 113 |
+
}
|
| 114 |
+
if args.out:
|
| 115 |
+
args.out.write_text(json.dumps(summary, indent=1))
|
| 116 |
+
t = summary["timing_ms"]
|
| 117 |
+
print(
|
| 118 |
+
f"{info.get('name')} {version}: n={args.reps} device median {t['device']['median']:.2f} ms (p90 {t['device']['p90']:.2f}) "
|
| 119 |
+
f"total median {t['total']['median']:.2f} ms (p90 {t['total']['p90']:.2f}) "
|
| 120 |
+
f"[decode {t['decode']['median']:.2f} encode {t['encode']['median']:.2f} decode_actions {t['decode_actions']['median']:.2f}] "
|
| 121 |
+
f"client wall median {summary['client_wall_ms']['median']:.1f} ms (p90 {summary['client_wall_ms']['p90']:.1f})"
|
| 122 |
+
)
|
| 123 |
+
return 0
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
if __name__ == "__main__":
|
| 127 |
+
sys.exit(main())
|
code/scripts/download_weights.sh
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env bash
|
| 2 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 3 |
+
# Fetch the pinned nvidia/GR00T-N1.5-3B snapshot the GR00T-N1.5-3B-p150 package serves, into the HF cache
|
| 4 |
+
# (`tt-model serve` does this automatically; this script is for host runs / offline hosts).
|
| 5 |
+
# The weights are NVIDIA's (NVIDIA License, non-commercial use) -- read LICENSE in the snapshot before use.
|
| 6 |
+
#
|
| 7 |
+
# bash scripts/download_weights.sh # -> ~/.cache/huggingface/hub/models--nvidia--GR00T-N1.5-3B/snapshots/869830fc.../
|
| 8 |
+
# HF_HOME=/some/dir bash scripts/download_weights.sh # another hub cache (the server reads HF_HUB_CACHE / HF_HOME / ~/.cache/huggingface)
|
| 9 |
+
set -euo pipefail
|
| 10 |
+
REPO=nvidia/GR00T-N1.5-3B
|
| 11 |
+
REVISION=869830fc749c35f34771aa5209f923ac57e4564e
|
| 12 |
+
PY=${PYTHON:-python3}
|
| 13 |
+
"$PY" - "$REPO" "$REVISION" <<'PY'
|
| 14 |
+
import sys
|
| 15 |
+
from huggingface_hub import snapshot_download
|
| 16 |
+
|
| 17 |
+
repo, revision = sys.argv[1], sys.argv[2]
|
| 18 |
+
patterns = ["model-*.safetensors", "model.safetensors.index.json", "config.json", "experiment_cfg/metadata.json", "LICENSE"]
|
| 19 |
+
path = snapshot_download(repo_id=repo, revision=revision, allow_patterns=patterns)
|
| 20 |
+
print(f"{repo} @ {revision}\n -> {path}")
|
| 21 |
+
PY
|
image/blobs/sha256/0b8bee58599dd50ebcc83819b473ea1eb586d722ee381103cbef6f32a1e1c780
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"7b14b5cfd31bdadda5d107644c6d4efdae9384a0386f40d03255eed4ce6c802d","parent":"19231fda800e2539c6e4cfd611e94b121ced3a710ae534efd4540cda9975f19a","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/1d1bc46ff8841de85f975ecd5e1203308bc2d6faf331d4aa9427d032f4fcc935
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"12d7cd873a75dd244c2f4c5376f0d6229f3d2c7f6270529efb2ec48c2b4081ef","parent":"5fb45e015e46e543747edd8c207913a9958ec718389d215335ae76c9e4e5ae37","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac
ADDED
|
Binary file (4.61 kB). View file
|
|
|
image/blobs/sha256/370bb95b39281a3ded169a86bb7972b898b349503342e491db98470ce5b1af87
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"0b2d0a5af285ce86b6328abd3d09c8d698930ebed015cb00934c6cf8d5f81a49","parent":"8239f5f3bd9364f3693079f7feb5552c0d2076ca9c7ff66c247bdf4a982bcf0b","created":"2026-09-15T00:28:43.990879611+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"config":{"Hostname":"","Domainname":"","User":"tt","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":["PATH=/opt/tt-venv/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin","VENV=/opt/tt-venv","VIRTUAL_ENV=/opt/tt-venv","TT_METAL_RUNTIME_ROOT=/opt/tt-metal","TT_METAL_HOME=/opt/tt-metal","PYTHONPATH=/opt/tt-metal","LD_LIBRARY_PATH=/opt/tt-metal/build/lib:/opt/openmpi-v5.0.7-ulfm/lib","EXTRA_MODELS_DIR=","TT_VLLM_BUILTIN_MODELS=","TT_MODEL_KIND=tt-dit-server","HF_HOME=/hf","TT_METAL_CACHE=/cache","HOME=/home/tt","USER=tt","LOGNAME=tt"],"Cmd":["/usr/local/bin/serve-default.sh"],"ArgsEscaped":true,"Image":"","Volumes":null,"WorkingDir":"/home/tt/work","Entrypoint":["/usr/local/bin/entrypoint.sh"],"OnBuild":null,"Labels":{"org.opencontainers.image.revision":"668c290757550588d0ce46b180c344a462a2aaf5","org.opencontainers.image.version":"22.04","org.tenstorrent.tt-model":"gr00t-n1.5-3b-p150","org.tenstorrent.tt-model.arch":"blackhole","org.tenstorrent.tt-model.kind":"tt-dit-server","org.tenstorrent.tt-model.plugin":"","org.tenstorrent.tt-model.profiles":"default","org.tenstorrent.tt-model.repo":"changh95/GR00T-N1.5-3B-p150","org.tenstorrent.tt-model.tt-metal":"v0.79.0-dev20260914-1-g668c290757","org.tenstorrent.tt-model.weights":"nvidia/GR00T-N1.5-3B"}},"architecture":"amd64","os":"linux"}
|
image/blobs/sha256/3ac026cc87fbebb2f96c2cffe83a97e3c0593da7fd6dd97bbdbd84f934ab0751
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"81ded9a441b8b3eb72ecaf63ca8fc877b095eff468cffb70c172e1b43bf79f82","parent":"91c1d01879c35e53047eb2b7f5e2ed76b29667e4892c58a8b719492e8c885e06","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/443501bd3b7afce579bf743eeedd64809886653c29a9d7125614e8451cd61a7b
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"architecture":"amd64","config":{"User":"tt","Env":["PATH=/opt/tt-venv/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin","VENV=/opt/tt-venv","VIRTUAL_ENV=/opt/tt-venv","TT_METAL_RUNTIME_ROOT=/opt/tt-metal","TT_METAL_HOME=/opt/tt-metal","PYTHONPATH=/opt/tt-metal","LD_LIBRARY_PATH=/opt/tt-metal/build/lib:/opt/openmpi-v5.0.7-ulfm/lib","EXTRA_MODELS_DIR=","TT_VLLM_BUILTIN_MODELS=","TT_MODEL_KIND=tt-dit-server","HF_HOME=/hf","TT_METAL_CACHE=/cache","HOME=/home/tt","USER=tt","LOGNAME=tt"],"Entrypoint":["/usr/local/bin/entrypoint.sh"],"Cmd":["/usr/local/bin/serve-default.sh"],"WorkingDir":"/home/tt/work","Labels":{"org.opencontainers.image.revision":"668c290757550588d0ce46b180c344a462a2aaf5","org.opencontainers.image.version":"22.04","org.tenstorrent.tt-model":"gr00t-n1.5-3b-p150","org.tenstorrent.tt-model.arch":"blackhole","org.tenstorrent.tt-model.kind":"tt-dit-server","org.tenstorrent.tt-model.plugin":"","org.tenstorrent.tt-model.profiles":"default","org.tenstorrent.tt-model.repo":"changh95/GR00T-N1.5-3B-p150","org.tenstorrent.tt-model.tt-metal":"v0.79.0-dev20260914-1-g668c290757","org.tenstorrent.tt-model.weights":"nvidia/GR00T-N1.5-3B"},"ArgsEscaped":true},"created":"2026-09-15T00:28:43.990879611+09:00","history":[{"created":"2026-09-03T12:14:51.139348462Z","created_by":"/bin/sh -c #(nop) ARG RELEASE","empty_layer":true},{"created":"2026-09-03T12:14:51.170427469Z","created_by":"/bin/sh -c #(nop) ARG LAUNCHPAD_BUILD_ARCH","empty_layer":true},{"created":"2026-09-03T12:14:51.200307479Z","created_by":"/bin/sh -c #(nop) LABEL org.opencontainers.image.version=22.04","empty_layer":true},{"created":"2026-09-03T12:14:53.528689977Z","created_by":"/bin/sh -c #(nop) ADD file:81c01921c5f642ac2fcbfae682e489e8e64b347467d9fa1587707e310e64d790 in / "},{"created":"2026-09-03T12:14:54.045714841Z","created_by":"/bin/sh -c #(nop) CMD [\"/bin/bash\"]","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG OMPI_DIR=/opt/openmpi-v5.0.7-ulfm","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG EXTRA_MODELS_DIR=","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG TT_MODEL_KIND","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_NAME","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_REPO","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_WEIGHTS","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_ARCH","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_PROFILES","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_TT_METAL_SHA","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_TT_METAL_DESCRIBE","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"ARG MODEL_PLUGIN_SHA","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:17:44.55093893+09:00","created_by":"RUN |11 OMPI_DIR=/opt/openmpi-v5.0.7-ulfm EXTRA_MODELS_DIR= TT_MODEL_KIND=tt-dit-server MODEL_NAME=gr00t-n1.5-3b-p150 MODEL_REPO=changh95/GR00T-N1.5-3B-p150 MODEL_WEIGHTS=nvidia/GR00T-N1.5-3B MODEL_ARCH=blackhole MODEL_PROFILES=default MODEL_TT_METAL_SHA=668c290757550588d0ce46b180c344a462a2aaf5 MODEL_TT_METAL_DESCRIBE=v0.79.0-dev20260914-1-g668c290757 MODEL_PLUGIN_SHA= /bin/sh -c apt-get update \u0026\u0026 apt-get install -y --no-install-recommends libhwloc15 libnuma1 libatomic1 libudev1 libcap2 zlib1g libmpc3 libmpfr6 libgmp10 libzstd1 libevent-core-2.1-7 libevent-pthreads-2.1-7 libgl1 libsndfile1 ca-certificates \u0026\u0026 apt-get clean \u0026\u0026 rm -rf /var/lib/apt/lists/* # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:17:45.103027718+09:00","created_by":"RUN |11 OMPI_DIR=/opt/openmpi-v5.0.7-ulfm EXTRA_MODELS_DIR= TT_MODEL_KIND=tt-dit-server MODEL_NAME=gr00t-n1.5-3b-p150 MODEL_REPO=changh95/GR00T-N1.5-3B-p150 MODEL_WEIGHTS=nvidia/GR00T-N1.5-3B MODEL_ARCH=blackhole MODEL_PROFILES=default MODEL_TT_METAL_SHA=668c290757550588d0ce46b180c344a462a2aaf5 MODEL_TT_METAL_DESCRIBE=v0.79.0-dev20260914-1-g668c290757 MODEL_PLUGIN_SHA= /bin/sh -c existing=\"$(getent passwd 1000 | cut -d: -f1)\" \u0026\u0026 if [ -n \"$existing\" ]; then userdel -r \"$existing\" 2\u003e/dev/null || userdel \"$existing\"; fi \u0026\u0026 useradd --uid 1000 --create-home --home-dir /home/tt --shell /bin/bash tt \u0026\u0026 mkdir -p /home/tt/work/logs /cache /opt/tt-metal \u0026\u0026 chown -R tt:tt /home/tt /cache /opt/tt-metal \u0026\u0026 chmod 1777 /home/tt /home/tt/work /home/tt/work/logs /cache # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:26:50.12099139+09:00","created_by":"COPY /opt/openmpi-v5.0.7-ulfm /opt/openmpi-v5.0.7-ulfm # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:26:56.859028587+09:00","created_by":"COPY /opt/tenstorrent /opt/tenstorrent # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:26:57.871714714+09:00","created_by":"COPY /usr/local/share/uv /usr/local/share/uv # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:01.173123316+09:00","created_by":"COPY /opt/tt-venv /opt/tt-venv # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:01.349280216+09:00","created_by":"COPY /opt/vllm /opt/vllm # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:06.182311758+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/runtime /opt/tt-metal/runtime # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:10.459270679+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/build_Release /opt/tt-metal/build_Release # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:14.890865208+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/build /opt/tt-metal/build # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:22.091999446+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/tt_metal /opt/tt-metal/tt_metal # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:25.597581517+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/ttnn /opt/tt-metal/ttnn # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:26.78141524+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/tools /opt/tt-metal/tools # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:27.818810081+09:00","created_by":"COPY --chown=tt:tt /opt/tt-metal/setup.py /opt/tt-metal/pyproject.toml /opt/tt-metal/ # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:29.056067419+09:00","created_by":"COPY --chown=tt:tt code/ /opt/tt-metal/ # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:29.869952207+09:00","created_by":"COPY entrypoint.sh /usr/local/bin/entrypoint.sh # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"COPY --chmod=0755 serve-default.sh /usr/local/bin/serve-default.sh # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV VENV=/opt/tt-venv","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV VIRTUAL_ENV=/opt/tt-venv","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV PATH=/opt/tt-venv/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV TT_METAL_RUNTIME_ROOT=/opt/tt-metal","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV TT_METAL_HOME=/opt/tt-metal","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV PYTHONPATH=/opt/tt-metal","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV LD_LIBRARY_PATH=/opt/tt-metal/build/lib:/opt/openmpi-v5.0.7-ulfm/lib","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV EXTRA_MODELS_DIR=","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ARG TT_VLLM_BUILTIN_MODELS=","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV TT_VLLM_BUILTIN_MODELS=","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV TT_MODEL_KIND=tt-dit-server","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV HF_HOME=/hf","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV TT_METAL_CACHE=/cache","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV HOME=/home/tt","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV USER=tt","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"ENV LOGNAME=tt","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:30.701160452+09:00","created_by":"USER tt","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:27:31.7325366+09:00","created_by":"WORKDIR /home/tt/work","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:27:32.54518317+09:00","created_by":"COPY verify.sh /ctx/verify.sh # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:28:40.774081382+09:00","created_by":"RUN |12 OMPI_DIR=/opt/openmpi-v5.0.7-ulfm EXTRA_MODELS_DIR= TT_MODEL_KIND=tt-dit-server MODEL_NAME=gr00t-n1.5-3b-p150 MODEL_REPO=changh95/GR00T-N1.5-3B-p150 MODEL_WEIGHTS=nvidia/GR00T-N1.5-3B MODEL_ARCH=blackhole MODEL_PROFILES=default MODEL_TT_METAL_SHA=668c290757550588d0ce46b180c344a462a2aaf5 MODEL_TT_METAL_DESCRIBE=v0.79.0-dev20260914-1-g668c290757 MODEL_PLUGIN_SHA= TT_VLLM_BUILTIN_MODELS= /bin/sh -c bash /ctx/verify.sh # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:28:40.774081382+09:00","created_by":"USER root","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:28:43.990879611+09:00","created_by":"RUN |12 OMPI_DIR=/opt/openmpi-v5.0.7-ulfm EXTRA_MODELS_DIR= TT_MODEL_KIND=tt-dit-server MODEL_NAME=gr00t-n1.5-3b-p150 MODEL_REPO=changh95/GR00T-N1.5-3B-p150 MODEL_WEIGHTS=nvidia/GR00T-N1.5-3B MODEL_ARCH=blackhole MODEL_PROFILES=default MODEL_TT_METAL_SHA=668c290757550588d0ce46b180c344a462a2aaf5 MODEL_TT_METAL_DESCRIBE=v0.79.0-dev20260914-1-g668c290757 MODEL_PLUGIN_SHA= TT_VLLM_BUILTIN_MODELS= /bin/sh -c chmod -R a+rwX /home/tt # buildkit","comment":"buildkit.dockerfile.v0"},{"created":"2026-09-15T00:28:43.990879611+09:00","created_by":"USER tt","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:28:43.990879611+09:00","created_by":"LABEL org.tenstorrent.tt-model=gr00t-n1.5-3b-p150 org.tenstorrent.tt-model.repo=changh95/GR00T-N1.5-3B-p150 org.tenstorrent.tt-model.weights=nvidia/GR00T-N1.5-3B org.tenstorrent.tt-model.arch=blackhole org.tenstorrent.tt-model.kind=tt-dit-server org.tenstorrent.tt-model.profiles=default org.opencontainers.image.revision=668c290757550588d0ce46b180c344a462a2aaf5 org.tenstorrent.tt-model.tt-metal=v0.79.0-dev20260914-1-g668c290757 org.tenstorrent.tt-model.plugin=","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:28:43.990879611+09:00","created_by":"ENTRYPOINT [\"/usr/local/bin/entrypoint.sh\"]","comment":"buildkit.dockerfile.v0","empty_layer":true},{"created":"2026-09-15T00:28:43.990879611+09:00","created_by":"CMD [\"/usr/local/bin/serve-default.sh\"]","comment":"buildkit.dockerfile.v0","empty_layer":true}],"os":"linux","rootfs":{"type":"layers","diff_ids":["sha256:ea16cace89338c84eb6bcb91a7efdfcae6838fff359efe951858227436486c34","sha256:51823e2af991bff33ffec20f249ee6bdb4314e7b9cbdf91000f1d4f4a71e0012","sha256:ae776143cc7af24f72a82ba98ae76acb15de31e0367d51325d34a2c0ae9774b1","sha256:5a589f1aa835965af711da5a5217b53178226a35f12d46b268f651f27f50ab66","sha256:20cad74cf2e0718048ce7cad5032e4837d231af0ead9812353883170b27a8c89","sha256:8b5207d0ea018af069c35032458560c4f7228bdbd7be56f83c2c8d38720c48ad","sha256:96d36b6a923d9a423d4d024e1d8b2865ba17630ff6c943b8b5399135262a392c","sha256:bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed","sha256:a94f59fd3b1e98f96650b4d704cd34b87a23cf6663284a9e7450054eb6655b1e","sha256:d30f4ffbfa0e22bdd84b1f348824e7ac9852f52aad62567398dc32bc64b833f6","sha256:61e58277f929e3e211f0f965b1ed7e676f7cb507da697ebfaaeb031d50881155","sha256:ab1563d57f53302f322fde8a9eca85f76b8df4c53f5e5475747ef187aae66cfd","sha256:5de3eb86f710f06651b3ea02c107f8a5eb867c64f9d11c430af796102fcfe6f9","sha256:45d79cfe2597546eebcbb17d2d8fed625efbed07554b30ee8f2220ae6b74a6e9","sha256:ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8","sha256:e72991f8dede710d8265ab8a49bd37bddfd9b4958934fa6f69e7f15c3c904c49","sha256:2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac","sha256:9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623","sha256:5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef","sha256:cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c","sha256:1746b32b74db4426d73b785ed8574fea5e421dee1d36bc62b81613901dd15a1e","sha256:4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c"]}}
|
image/blobs/sha256/4568a8cf3754ec6555dfd72c99498a8a6d81c756cb843f869c32db42000f4f07
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"1ac9704e2f8a4d5d29fa88659ad705d2f16158f8312222b98570272754200b1c","parent":"6b74c1ea99d52673ac6ef692bd3c5873d2de286a0fcc425753fdb131eb99aa72","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c
ADDED
|
Binary file (39.9 kB). View file
|
|
|
image/blobs/sha256/514ee738d1ef907136a924293b5033e43461f7b14c90428f3fdaf082d4bca600
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"19231fda800e2539c6e4cfd611e94b121ced3a710ae534efd4540cda9975f19a","parent":"2936fcd1226666b3c2513e2825f14e5a99c3ff4fc9dd24ac8741571d6c1fecf6","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/5628e13ce208b83d793af15fa41c28d1702e7a43e27c8c72944442d01e959a71
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"e618d643825753f4550a54eacfd500e6e7652078cf4168c9ef3f869701db7fc5","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/5f1f271cd6c23c85e2bbe2b1601abb2143184d033d1e93853029f959402b64c3
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"17be60e495073261a8d023e6447bf638526af346e74fc420cbb2bfb54d996833","parent":"6ecf5ff235091d534b1398dc7b8a249889b15a958fb4788a3c109c4b350dd8d2","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef
ADDED
|
Binary file (1.02 kB). View file
|
|
|
image/blobs/sha256/60d99486d4e943a3a234fd3001d031f22c99fa65f933b048f3bc272051148d81
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"f0c5ef0e38047417380a9c2efe4dab8455a6bb182f3308c79c98664a50bac4c0","parent":"17be60e495073261a8d023e6447bf638526af346e74fc420cbb2bfb54d996833","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/6c3dd1840f3cb732d89c764a387e4742bffa52990892993301bc49819ef39be5
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"8239f5f3bd9364f3693079f7feb5552c0d2076ca9c7ff66c247bdf4a982bcf0b","parent":"1238be44de2e9550ca38cfe414ec5326953ed54dc9ae503f3cba1025dab6a2c5","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/746d6df035900c8d4ad4ad98c30b5cd4050eb272fb1ef5d19d0330c27a38f18e
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"91c1d01879c35e53047eb2b7f5e2ed76b29667e4892c58a8b719492e8c885e06","parent":"2da341b5a7879df7bf157e6bb65cd528dfbd1bcf928107a2c9511c5c1b3cdaf7","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/75df73761a6599a1f76198e180ea6ea4845564fd787cdb1a85bb96fc9490e4e2
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"a14eec88ef93717bfe2b45846415b064324e5996669e7e7f3e1707632801c805","parent":"1ac9704e2f8a4d5d29fa88659ad705d2f16158f8312222b98570272754200b1c","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/7da1668187b2357115d5ede196f3848c315c32695c103c2991fe8d09bcea1fb5
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"5fb45e015e46e543747edd8c207913a9958ec718389d215335ae76c9e4e5ae37","parent":"7b14b5cfd31bdadda5d107644c6d4efdae9384a0386f40d03255eed4ce6c802d","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/8836ac07b9ab1d87c8f9759bcc86240cb196a2de00ed7efbd06d8b91b25cd4d9
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"2da341b5a7879df7bf157e6bb65cd528dfbd1bcf928107a2c9511c5c1b3cdaf7","parent":"14ed07f3336ada962a82269352e617a0bf348e6f425b7533c44244530a1187b0","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/8b2c5066cae93333c326dc28469add1060522ce7553473cc67a464531afd31e9
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"2936fcd1226666b3c2513e2825f14e5a99c3ff4fc9dd24ac8741571d6c1fecf6","parent":"1031dddc9543787c54ae3956c460ec749c1a3e798c8f05b25c3e8455de1ed974","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/92387b8093f65f78b3f65ac14f4c1fface25891d185815c29ca124a9cacb5a9e
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"1031dddc9543787c54ae3956c460ec749c1a3e798c8f05b25c3e8455de1ed974","parent":"5a10e48ae8d8ff84ab16cfca7e66bfb43764d2d85c829945921d4af55f5dc3cd","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/95a774a140ea0bdf3c88f347e5a26834bef4d22301cd5300cc925c9cd0a728dd
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"5a10e48ae8d8ff84ab16cfca7e66bfb43764d2d85c829945921d4af55f5dc3cd","parent":"f0c5ef0e38047417380a9c2efe4dab8455a6bb182f3308c79c98664a50bac4c0","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623
ADDED
|
Binary file (5.12 kB). View file
|
|
|
image/blobs/sha256/a2491fe22925746efefa576db546cd62a39b33b9378a7205bb119d6f5a2d06b4
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"6ecf5ff235091d534b1398dc7b8a249889b15a958fb4788a3c109c4b350dd8d2","parent":"e618d643825753f4550a54eacfd500e6e7652078cf4168c9ef3f869701db7fc5","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed
ADDED
|
Binary file (2.05 kB). View file
|
|
|
image/blobs/sha256/ceda6a792461a030c40385b7e455fcfd3b56ab238855e2af19f623ff962e325a
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"schemaVersion":2,"mediaType":"application/vnd.oci.image.manifest.v1+json","config":{"mediaType":"application/vnd.oci.image.config.v1+json","digest":"sha256:443501bd3b7afce579bf743eeedd64809886653c29a9d7125614e8451cd61a7b","size":14429},"layers":[{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:ea16cace89338c84eb6bcb91a7efdfcae6838fff359efe951858227436486c34","size":80641024},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:51823e2af991bff33ffec20f249ee6bdb4314e7b9cbdf91000f1d4f4a71e0012","size":204086784},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:ae776143cc7af24f72a82ba98ae76acb15de31e0367d51325d34a2c0ae9774b1","size":352256},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:5a589f1aa835965af711da5a5217b53178226a35f12d46b268f651f27f50ab66","size":33464832},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:20cad74cf2e0718048ce7cad5032e4837d231af0ead9812353883170b27a8c89","size":454126592},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:8b5207d0ea018af069c35032458560c4f7228bdbd7be56f83c2c8d38720c48ad","size":187652608},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:96d36b6a923d9a423d4d024e1d8b2865ba17630ff6c943b8b5399135262a392c","size":1245465600},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed","size":2048},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:a94f59fd3b1e98f96650b4d704cd34b87a23cf6663284a9e7450054eb6655b1e","size":454626304},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:d30f4ffbfa0e22bdd84b1f348824e7ac9852f52aad62567398dc32bc64b833f6","size":136048640},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:61e58277f929e3e211f0f965b1ed7e676f7cb507da697ebfaaeb031d50881155","size":136048640},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:ab1563d57f53302f322fde8a9eca85f76b8df4c53f5e5475747ef187aae66cfd","size":195663360},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:5de3eb86f710f06651b3ea02c107f8a5eb867c64f9d11c430af796102fcfe6f9","size":69021184},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:45d79cfe2597546eebcbb17d2d8fed625efbed07554b30ee8f2220ae6b74a6e9","size":5885952},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8","size":23040},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:e72991f8dede710d8265ab8a49bd37bddfd9b4958934fa6f69e7f15c3c904c49","size":10117632},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac","size":4608},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623","size":5120},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef","size":1024},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c","size":6144},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:1746b32b74db4426d73b785ed8574fea5e421dee1d36bc62b81613901dd15a1e","size":1684480},{"mediaType":"application/vnd.oci.image.layer.v1.tar","digest":"sha256:4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c","size":39936}]}
|
image/blobs/sha256/cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c
ADDED
|
Binary file (6.14 kB). View file
|
|
|
image/blobs/sha256/dfdf267c677095544bf7ac50b1a0f6678eb93662a45aeb30f77f976ac4ace6de
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"00f2159936b314d8fbbbd37a75ac10517a79e0da0c80bdb4b8b4b1a1cda406f1","parent":"12d7cd873a75dd244c2f4c5376f0d6229f3d2c7f6270529efb2ec48c2b4081ef","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/e0c4814cde1d85e88a2dd6121d00c886b5b04f8206434ec4a0e14aca6a8a1769
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"6b74c1ea99d52673ac6ef692bd3c5873d2de286a0fcc425753fdb131eb99aa72","parent":"81ded9a441b8b3eb72ecaf63ca8fc877b095eff468cffb70c172e1b43bf79f82","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/e13438a9103dc3ce3126a1a1711007fdf9c31bfabfeadeae010327901fc39b88
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"1238be44de2e9550ca38cfe414ec5326953ed54dc9ae503f3cba1025dab6a2c5","parent":"a14eec88ef93717bfe2b45846415b064324e5996669e7e7f3e1707632801c805","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/e8d4979d8340f3b13fb626dab5702018f87bd5b44295909f6fdd0c2734a7910f
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"id":"14ed07f3336ada962a82269352e617a0bf348e6f425b7533c44244530a1187b0","parent":"00f2159936b314d8fbbbd37a75ac10517a79e0da0c80bdb4b8b4b1a1cda406f1","created":"1970-01-01T09:00:00+09:00","container_config":{"Hostname":"","Domainname":"","User":"","AttachStdin":false,"AttachStdout":false,"AttachStderr":false,"Tty":false,"OpenStdin":false,"StdinOnce":false,"Env":null,"Cmd":null,"Image":"","Volumes":null,"WorkingDir":"","Entrypoint":null,"OnBuild":null,"Labels":null},"os":"linux"}
|
image/blobs/sha256/ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8
ADDED
|
Binary file (23 kB). View file
|
|
|
image/index.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"schemaVersion":2,"mediaType":"application/vnd.oci.image.index.v1+json","manifests":[{"mediaType":"application/vnd.oci.image.manifest.v1+json","digest":"sha256:ceda6a792461a030c40385b7e455fcfd3b56ab238855e2af19f623ff962e325a","size":3616,"annotations":{"io.containerd.image.name":"docker.io/tt-model/gr00t-n1.5-3b-p150:443501bd3b7a","org.opencontainers.image.ref.name":"443501bd3b7a"}}]}
|
image/manifest.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
[{"Config":"blobs/sha256/443501bd3b7afce579bf743eeedd64809886653c29a9d7125614e8451cd61a7b","RepoTags":["tt-model/gr00t-n1.5-3b-p150:443501bd3b7a"],"Layers":["blobs/sha256/ea16cace89338c84eb6bcb91a7efdfcae6838fff359efe951858227436486c34","blobs/sha256/51823e2af991bff33ffec20f249ee6bdb4314e7b9cbdf91000f1d4f4a71e0012","blobs/sha256/ae776143cc7af24f72a82ba98ae76acb15de31e0367d51325d34a2c0ae9774b1","blobs/sha256/5a589f1aa835965af711da5a5217b53178226a35f12d46b268f651f27f50ab66","blobs/sha256/20cad74cf2e0718048ce7cad5032e4837d231af0ead9812353883170b27a8c89","blobs/sha256/8b5207d0ea018af069c35032458560c4f7228bdbd7be56f83c2c8d38720c48ad","blobs/sha256/96d36b6a923d9a423d4d024e1d8b2865ba17630ff6c943b8b5399135262a392c","blobs/sha256/bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed","blobs/sha256/a94f59fd3b1e98f96650b4d704cd34b87a23cf6663284a9e7450054eb6655b1e","blobs/sha256/d30f4ffbfa0e22bdd84b1f348824e7ac9852f52aad62567398dc32bc64b833f6","blobs/sha256/61e58277f929e3e211f0f965b1ed7e676f7cb507da697ebfaaeb031d50881155","blobs/sha256/ab1563d57f53302f322fde8a9eca85f76b8df4c53f5e5475747ef187aae66cfd","blobs/sha256/5de3eb86f710f06651b3ea02c107f8a5eb867c64f9d11c430af796102fcfe6f9","blobs/sha256/45d79cfe2597546eebcbb17d2d8fed625efbed07554b30ee8f2220ae6b74a6e9","blobs/sha256/ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8","blobs/sha256/e72991f8dede710d8265ab8a49bd37bddfd9b4958934fa6f69e7f15c3c904c49","blobs/sha256/2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac","blobs/sha256/9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623","blobs/sha256/5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef","blobs/sha256/cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c","blobs/sha256/1746b32b74db4426d73b785ed8574fea5e421dee1d36bc62b81613901dd15a1e","blobs/sha256/4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c"],"LayerSources":{"sha256:1746b32b74db4426d73b785ed8574fea5e421dee1d36bc62b81613901dd15a1e":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":1684480,"digest":"sha256:1746b32b74db4426d73b785ed8574fea5e421dee1d36bc62b81613901dd15a1e"},"sha256:20cad74cf2e0718048ce7cad5032e4837d231af0ead9812353883170b27a8c89":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":454126592,"digest":"sha256:20cad74cf2e0718048ce7cad5032e4837d231af0ead9812353883170b27a8c89"},"sha256:2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":4608,"digest":"sha256:2368844ee84552082aa5dffa46d1d10eeb7ae2ca19b2b8a7dfeda01bd0569dac"},"sha256:45d79cfe2597546eebcbb17d2d8fed625efbed07554b30ee8f2220ae6b74a6e9":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":5885952,"digest":"sha256:45d79cfe2597546eebcbb17d2d8fed625efbed07554b30ee8f2220ae6b74a6e9"},"sha256:4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":39936,"digest":"sha256:4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c"},"sha256:51823e2af991bff33ffec20f249ee6bdb4314e7b9cbdf91000f1d4f4a71e0012":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":204086784,"digest":"sha256:51823e2af991bff33ffec20f249ee6bdb4314e7b9cbdf91000f1d4f4a71e0012"},"sha256:5a589f1aa835965af711da5a5217b53178226a35f12d46b268f651f27f50ab66":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":33464832,"digest":"sha256:5a589f1aa835965af711da5a5217b53178226a35f12d46b268f651f27f50ab66"},"sha256:5de3eb86f710f06651b3ea02c107f8a5eb867c64f9d11c430af796102fcfe6f9":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":69021184,"digest":"sha256:5de3eb86f710f06651b3ea02c107f8a5eb867c64f9d11c430af796102fcfe6f9"},"sha256:5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":1024,"digest":"sha256:5f70bf18a086007016e948b04aed3b82103a36bea41755b6cddfaf10ace3c6ef"},"sha256:61e58277f929e3e211f0f965b1ed7e676f7cb507da697ebfaaeb031d50881155":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":136048640,"digest":"sha256:61e58277f929e3e211f0f965b1ed7e676f7cb507da697ebfaaeb031d50881155"},"sha256:8b5207d0ea018af069c35032458560c4f7228bdbd7be56f83c2c8d38720c48ad":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":187652608,"digest":"sha256:8b5207d0ea018af069c35032458560c4f7228bdbd7be56f83c2c8d38720c48ad"},"sha256:96d36b6a923d9a423d4d024e1d8b2865ba17630ff6c943b8b5399135262a392c":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":1245465600,"digest":"sha256:96d36b6a923d9a423d4d024e1d8b2865ba17630ff6c943b8b5399135262a392c"},"sha256:9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":5120,"digest":"sha256:9800a286b1c10fea7a3d177d6a9c1972383e555aa42fddfa538286053c654623"},"sha256:a94f59fd3b1e98f96650b4d704cd34b87a23cf6663284a9e7450054eb6655b1e":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":454626304,"digest":"sha256:a94f59fd3b1e98f96650b4d704cd34b87a23cf6663284a9e7450054eb6655b1e"},"sha256:ab1563d57f53302f322fde8a9eca85f76b8df4c53f5e5475747ef187aae66cfd":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":195663360,"digest":"sha256:ab1563d57f53302f322fde8a9eca85f76b8df4c53f5e5475747ef187aae66cfd"},"sha256:ae776143cc7af24f72a82ba98ae76acb15de31e0367d51325d34a2c0ae9774b1":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":352256,"digest":"sha256:ae776143cc7af24f72a82ba98ae76acb15de31e0367d51325d34a2c0ae9774b1"},"sha256:bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":2048,"digest":"sha256:bfb33d6feff769cce24063505762c22c182208e1c678d9f5d5024e09736323ed"},"sha256:cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":6144,"digest":"sha256:cfcbdcb92afa4680baac457e629510a6e55667a2c45d208620d6dcdc94a44e9c"},"sha256:d30f4ffbfa0e22bdd84b1f348824e7ac9852f52aad62567398dc32bc64b833f6":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":136048640,"digest":"sha256:d30f4ffbfa0e22bdd84b1f348824e7ac9852f52aad62567398dc32bc64b833f6"},"sha256:e72991f8dede710d8265ab8a49bd37bddfd9b4958934fa6f69e7f15c3c904c49":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":10117632,"digest":"sha256:e72991f8dede710d8265ab8a49bd37bddfd9b4958934fa6f69e7f15c3c904c49"},"sha256:ea16cace89338c84eb6bcb91a7efdfcae6838fff359efe951858227436486c34":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":80641024,"digest":"sha256:ea16cace89338c84eb6bcb91a7efdfcae6838fff359efe951858227436486c34"},"sha256:ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8":{"mediaType":"application/vnd.oci.image.layer.v1.tar","size":23040,"digest":"sha256:ff89efbc286d449abab8814120c65f02fc6c051c498d955f18566cd0734a95d8"}}}]
|
image/oci-layout
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"imageLayoutVersion": "1.0.0"}
|
image/repositories
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"tt-model/gr00t-n1.5-3b-p150":{"443501bd3b7a":"4d0e7c32d9164b460304d93dc180502d9492beffb5914aaa43ab93d98c14f97c"}}
|
requirements.lock
ADDED
|
@@ -0,0 +1,87 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
annotated-doc==0.0.5
|
| 2 |
+
annotated-types==0.8.0
|
| 3 |
+
anyio==4.15.1
|
| 4 |
+
certifi==2026.7.22
|
| 5 |
+
cfgv==3.5.0
|
| 6 |
+
charset-normalizer==3.5.1
|
| 7 |
+
click==8.5.0
|
| 8 |
+
contourpy==1.3.3
|
| 9 |
+
cycler==0.12.1
|
| 10 |
+
distlib==0.4.3
|
| 11 |
+
distro==1.9.0
|
| 12 |
+
elastic-transport==9.4.2
|
| 13 |
+
elasticsearch==9.5.1
|
| 14 |
+
fastapi==0.141.1
|
| 15 |
+
filelock==3.32.6
|
| 16 |
+
fonttools==4.65.0
|
| 17 |
+
fsspec==2026.7.0
|
| 18 |
+
graphviz==0.21
|
| 19 |
+
h11==0.16.0
|
| 20 |
+
hf-xet==1.6.0
|
| 21 |
+
httpcore==1.0.9
|
| 22 |
+
httpx==0.28.1
|
| 23 |
+
huggingface_hub==1.31.0
|
| 24 |
+
identify==2.6.19
|
| 25 |
+
idna==3.19
|
| 26 |
+
iniconfig==2.3.0
|
| 27 |
+
Jinja2==3.1.6
|
| 28 |
+
kiwisolver==1.5.1
|
| 29 |
+
linkify-it-py==2.2.0
|
| 30 |
+
loguru==0.7.3
|
| 31 |
+
markdown-it-py==4.2.0
|
| 32 |
+
MarkupSafe==3.0.3
|
| 33 |
+
matplotlib==3.11.2
|
| 34 |
+
mdit-py-plugins==0.6.1
|
| 35 |
+
mdurl==0.1.2
|
| 36 |
+
ml_dtypes==0.5.4
|
| 37 |
+
mpmath==1.3.0
|
| 38 |
+
networkx==3.6.1
|
| 39 |
+
nodeenv==1.10.0
|
| 40 |
+
numpy==1.26.4
|
| 41 |
+
opencv-python-headless==4.8.1.78
|
| 42 |
+
packaging==26.3
|
| 43 |
+
pandas==3.0.5
|
| 44 |
+
pillow==12.3.0
|
| 45 |
+
platformdirs==4.11.8
|
| 46 |
+
pluggy==1.6.0
|
| 47 |
+
pre_commit==4.6.2
|
| 48 |
+
psutil==7.2.2
|
| 49 |
+
pydantic==2.13.5
|
| 50 |
+
pydantic_core==2.46.5
|
| 51 |
+
Pygments==2.21.0
|
| 52 |
+
pyluwen==0.9.0
|
| 53 |
+
pyparsing==3.3.2
|
| 54 |
+
pytest==9.1.1
|
| 55 |
+
python-dateutil==2.9.0.post0
|
| 56 |
+
python-discovery==1.6.0
|
| 57 |
+
PyYAML==6.0.3
|
| 58 |
+
regex==2026.9.10
|
| 59 |
+
requests==2.34.2
|
| 60 |
+
rich==15.0.0
|
| 61 |
+
safetensors==0.8.0
|
| 62 |
+
seaborn==0.13.2
|
| 63 |
+
setuptools==80.10.2
|
| 64 |
+
setuptools-scm==8.1.0
|
| 65 |
+
shellingham==1.5.4
|
| 66 |
+
six==1.17.0
|
| 67 |
+
sniffio==1.3.1
|
| 68 |
+
starlette==1.6.0
|
| 69 |
+
sympy==1.14.0
|
| 70 |
+
textual==8.2.8
|
| 71 |
+
tokenizers==0.22.2
|
| 72 |
+
tomli==2.4.1
|
| 73 |
+
torch==2.11.0+cpu
|
| 74 |
+
torchvision==0.26.0+cpu
|
| 75 |
+
tqdm==4.70.1
|
| 76 |
+
transformers==5.12.1
|
| 77 |
+
tt-smi==6.5.0
|
| 78 |
+
tt-tools-common==1.6.0
|
| 79 |
+
tt-umd==0.9.10
|
| 80 |
+
ttnn==0.65.2.dev10011
|
| 81 |
+
typer==0.27.2
|
| 82 |
+
typing-inspection==0.4.4
|
| 83 |
+
typing_extensions==4.16.0
|
| 84 |
+
urllib3==2.7.0
|
| 85 |
+
uvicorn==0.53.0
|
| 86 |
+
virtualenv==21.7.9
|
| 87 |
+
wheel==0.48.0
|
tt_kernel_manifest.json
ADDED
|
@@ -0,0 +1,138 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"schema_version": "5.1",
|
| 3 |
+
"name": "gr00t-n1.5-3b-p150",
|
| 4 |
+
"tt_metal_version": "0.65.2.dev10011",
|
| 5 |
+
"arch": "blackhole",
|
| 6 |
+
"device_count": 1,
|
| 7 |
+
"producer": {
|
| 8 |
+
"tt_kernel_version": "0.1.0",
|
| 9 |
+
"created_at": "2026-09-14T15:30:00.783347+00:00",
|
| 10 |
+
"hostname": "deepgadget"
|
| 11 |
+
},
|
| 12 |
+
"weights": {
|
| 13 |
+
"repo_id": "nvidia/GR00T-N1.5-3B",
|
| 14 |
+
"revision": "869830fc749c35f34771aa5209f923ac57e4564e",
|
| 15 |
+
"allow_patterns": [
|
| 16 |
+
"model-*.safetensors",
|
| 17 |
+
"model.safetensors.index.json",
|
| 18 |
+
"config.json",
|
| 19 |
+
"experiment_cfg/metadata.json",
|
| 20 |
+
"LICENSE"
|
| 21 |
+
],
|
| 22 |
+
"ignore_patterns": null,
|
| 23 |
+
"repo_type": "model"
|
| 24 |
+
},
|
| 25 |
+
"mesh": null,
|
| 26 |
+
"entrypoint": null,
|
| 27 |
+
"resources": null,
|
| 28 |
+
"capabilities": null,
|
| 29 |
+
"env": {},
|
| 30 |
+
"bundled": null,
|
| 31 |
+
"deps": null,
|
| 32 |
+
"container": {
|
| 33 |
+
"image": {
|
| 34 |
+
"registry": "hf",
|
| 35 |
+
"repository": "gr00t-n1.5-3b-p150",
|
| 36 |
+
"tag": "tt-model/gr00t-n1.5-3b-p150:443501bd3b7a",
|
| 37 |
+
"digest": "sha256:443501bd3b7afce579bf743eeedd64809886653c29a9d7125614e8451cd61a7b"
|
| 38 |
+
},
|
| 39 |
+
"kind": "tt-dit-server",
|
| 40 |
+
"runtime": {
|
| 41 |
+
"app": "gr00t_p150.server.app:app",
|
| 42 |
+
"mesh_shape_env": "TT_MESH_SHAPE",
|
| 43 |
+
"packages": [
|
| 44 |
+
"numpy>=1.24.4,<2",
|
| 45 |
+
"safetensors",
|
| 46 |
+
"huggingface_hub",
|
| 47 |
+
"transformers==5.12.1",
|
| 48 |
+
"opencv-python-headless==4.8.1.78",
|
| 49 |
+
"torchvision==0.26.0",
|
| 50 |
+
"pytest"
|
| 51 |
+
],
|
| 52 |
+
"lock": "requirements.lock"
|
| 53 |
+
},
|
| 54 |
+
"serve": {
|
| 55 |
+
"hardware": "p150",
|
| 56 |
+
"mesh_device": "P150",
|
| 57 |
+
"port": 20000,
|
| 58 |
+
"max_model_len": null,
|
| 59 |
+
"max_num_seqs": null,
|
| 60 |
+
"block_size": null,
|
| 61 |
+
"server_timeout": null,
|
| 62 |
+
"capabilities": null,
|
| 63 |
+
"additional_config": {},
|
| 64 |
+
"args": [],
|
| 65 |
+
"env": {
|
| 66 |
+
"TT_WEIGHTS_REVISION": "869830fc749c35f34771aa5209f923ac57e4564e",
|
| 67 |
+
"TT_METAL_VISIBLE_DEVICES": "0",
|
| 68 |
+
"TT_DEVICE_ID": "0",
|
| 69 |
+
"GR00T_VERSION": "n15",
|
| 70 |
+
"GR00T_EMBODIMENT": "gr1",
|
| 71 |
+
"GR00T_LAYOUT": "gr1",
|
| 72 |
+
"GR00T_POLICY": "mixed_dit",
|
| 73 |
+
"GR00T_TRACE_LAYOUT": "per_stage",
|
| 74 |
+
"GR00T_TOKENIZER_DIR_N15": "/opt/tt-metal/gr00t_p150/assets/tokenizer/n15",
|
| 75 |
+
"GR00T_PROJECT_ROOT": "/nonexistent",
|
| 76 |
+
"GR00T_GOLDEN_ROOT": "/nonexistent",
|
| 77 |
+
"GR00T_TT_CACHE": "/weight-cache/gr00t-tt",
|
| 78 |
+
"GR00T_WARMUP_RUNS": "3"
|
| 79 |
+
}
|
| 80 |
+
},
|
| 81 |
+
"serve_profiles": [
|
| 82 |
+
{
|
| 83 |
+
"hardware": null,
|
| 84 |
+
"mesh_device": null,
|
| 85 |
+
"port": null,
|
| 86 |
+
"max_model_len": null,
|
| 87 |
+
"max_num_seqs": null,
|
| 88 |
+
"block_size": null,
|
| 89 |
+
"server_timeout": null,
|
| 90 |
+
"capabilities": null,
|
| 91 |
+
"additional_config": {},
|
| 92 |
+
"args": [],
|
| 93 |
+
"env": {},
|
| 94 |
+
"name": "default",
|
| 95 |
+
"description": null
|
| 96 |
+
}
|
| 97 |
+
],
|
| 98 |
+
"default_profile": null,
|
| 99 |
+
"code_dir": "code",
|
| 100 |
+
"verify": [
|
| 101 |
+
"import gr00t_p150.server.app as a; assert a.app; import sys; assert 'ttnn' not in sys.modules, 'server import must be side-effect free'",
|
| 102 |
+
"import models.experimental.gr00t.tt.model as m; assert m.Gr00tTT",
|
| 103 |
+
"from models.experimental.gr00t.common import preprocessing, normalization, prompts, checkpoint, weights, configs; assert configs.HF_SNAPSHOT_SHAS['n15'] == '869830fc749c35f34771aa5209f923ac57e4564e'",
|
| 104 |
+
"import pytest, models.common.utility_functions; import models.tt_dit.utils.matmul as mm; assert mm.get_matmul_config",
|
| 105 |
+
"import models.demos.deepseek_v3_b1.unified_kernel_descriptor as u; assert u.UnifiedKernelDescriptor",
|
| 106 |
+
"import models.tt_dit.encoders.qwen3vl.vision_qwen3vl",
|
| 107 |
+
"import models.experimental.gr00t.tt.layers, models.experimental.gr00t.tt.qwen3vl_vision, models.experimental.gr00t.tt.megakernel.descriptors",
|
| 108 |
+
"import safetensors, huggingface_hub, cv2, numpy, PIL; assert int(numpy.__version__.split('.')[0]) < 2, numpy.__version__",
|
| 109 |
+
"import transformers; assert transformers.__version__ == '5.12.1', transformers.__version__",
|
| 110 |
+
"import torchvision; assert torchvision.__version__.startswith('0.26.0'), torchvision.__version__",
|
| 111 |
+
"from pathlib import Path; d = Path('/opt/tt-metal/gr00t_p150/assets/tokenizer/n15'); assert all((d / f).is_file() for f in ('vocab.json', 'merges.txt', 'tokenizer_config.json', 'special_tokens_map.json', 'added_tokens.json')), sorted(p.name for p in d.iterdir())",
|
| 112 |
+
"import os; os.environ['GR00T_TOKENIZER_DIR_N15'] = '/opt/tt-metal/gr00t_p150/assets/tokenizer/n15'; from models.experimental.gr00t.common.prompts import get_tokenizer; t = get_tokenizer('n15'); assert t.convert_tokens_to_ids('<IMG_CONTEXT>') == 151669",
|
| 113 |
+
"from pathlib import Path; assert Path('/opt/tt-metal/models/experimental/gr00t/common/golden_tap_map.json').is_file()",
|
| 114 |
+
"from pathlib import Path; assert Path('/opt/tt-metal/gr00t_p150/server/smoke_test.py').is_file() and Path('/opt/tt-metal/scripts/bench_http.py').is_file()",
|
| 115 |
+
"from pathlib import Path; d = Path('/opt/tt-metal/gr00t_p150/demo/n15'); assert all((d / f).is_file() for f in ('observation.json', 'noise.json', 'expected.json', 'frames/ego_view_t0.png')), sorted(str(p) for p in d.rglob('*'))",
|
| 116 |
+
"import ttnn; assert all(hasattr(ttnn, a) for a in ('begin_trace_capture', 'end_trace_capture', 'execute_trace', 'release_trace', 'copy_host_to_device_tensor', 'MinimalMatmulConfig'))",
|
| 117 |
+
"from gr00t_p150.server.app import parse_mesh_shape as p; assert p('1x1') == p('(1, 1)') == p('1,1') == (1, 1)"
|
| 118 |
+
],
|
| 119 |
+
"built": {
|
| 120 |
+
"image": "tt-model/gr00t-n1.5-3b-p150:443501bd3b7a",
|
| 121 |
+
"repo": "changh95/GR00T-N1.5-3B-p150",
|
| 122 |
+
"tt_model_version": "0.1.0",
|
| 123 |
+
"created_at": "2026-09-14T15:17:00+00:00",
|
| 124 |
+
"tt_metal": {
|
| 125 |
+
"sha": "668c290757550588d0ce46b180c344a462a2aaf5",
|
| 126 |
+
"describe": "v0.79.0-dev20260914-1-g668c290757",
|
| 127 |
+
"dirty": false,
|
| 128 |
+
"scm_version": "0.65.2.dev10011",
|
| 129 |
+
"mode": "local",
|
| 130 |
+
"remote": "https://github.com/tenstorrent/tt-metal.git",
|
| 131 |
+
"branch": "HEAD",
|
| 132 |
+
"pushed": true
|
| 133 |
+
},
|
| 134 |
+
"code_sha256": "a2771515bca98527e302292524e9c1d28db4941cec8eb276bc8c8344d14358e9",
|
| 135 |
+
"image_digest": "sha256:443501bd3b7afce579bf743eeedd64809886653c29a9d7125614e8451cd61a7b"
|
| 136 |
+
}
|
| 137 |
+
}
|
| 138 |
+
}
|