

Restore card metadata (license, pipeline_tag, base_model, tags) and upload tt-model authoring files
Browse filesREADME.md = the finished card (front matter: license other / nvidia-license / license_link, pipeline_tag robotics, base_model, descriptive tags + tt-model-catalog; quickstart paragraph simplified to the two bullets as in changh95/rf-detr-p150 and changh95/pi05-base-p150). Root files tt-model.yaml, SERVING.md, GPU_COMPARISON.md, LICENSE, LICENSE-NOTICE.md, requirements.lock and media/* from the staging dir; code/ and image/ untouched (as pushed by tt-model push).
- .gitattributes +1 -0
- GPU_COMPARISON.md +91 -0
- LICENSE +61 -0
- LICENSE-NOTICE.md +26 -0
- README.md +16 -2
- SERVING.md +229 -0
- media/demo_actions_vs_golden.png +3 -0
- media/demo_ego_view.png +0 -0
- media/demo_observation.json +46 -0
- tt-model.yaml +212 -0
.gitattributes
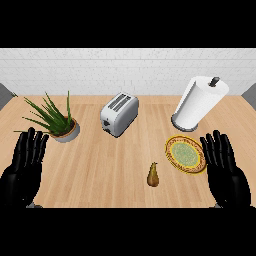
CHANGED
|
@@ -48,3 +48,4 @@ image/blobs/sha256/ea07a201af443d5a600b22c02de0009e907acab32e5b033ed8df86d0a0113
|
|
| 48 |
image/blobs/sha256/256e0cf0f7d85bbf0d3362be27dee0534059bc45011db9b5aad683550e991905 filter=lfs diff=lfs merge=lfs -text
|
| 49 |
image/blobs/sha256/58c2b8faf6877c94ecd1468ab1ad99d4c4c73fb376613d8517b659fc09309496 filter=lfs diff=lfs merge=lfs -text
|
| 50 |
image/blobs/sha256/6ef3d5458860fc96e862cfc6df467f80a4db334ebe6bae7da8f09fda2d1cd758 filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 48 |
image/blobs/sha256/256e0cf0f7d85bbf0d3362be27dee0534059bc45011db9b5aad683550e991905 filter=lfs diff=lfs merge=lfs -text
|
| 49 |
image/blobs/sha256/58c2b8faf6877c94ecd1468ab1ad99d4c4c73fb376613d8517b659fc09309496 filter=lfs diff=lfs merge=lfs -text
|
| 50 |
image/blobs/sha256/6ef3d5458860fc96e862cfc6df467f80a4db334ebe6bae7da8f09fda2d1cd758 filter=lfs diff=lfs merge=lfs -text
|
| 51 |
+
media/demo_actions_vs_golden.png filter=lfs diff=lfs merge=lfs -text
|
GPU_COMPARISON.md
ADDED
|
@@ -0,0 +1,91 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# GR00T-N1.6-3B-p150 — Blackhole p150a vs RTX 5090 (same host, same weights, same observation)
|
| 2 |
+
|
| 3 |
+
Facts only. The GPU rows were measured on the build host during the port's reference-environment study
|
| 4 |
+
(2026-09-14, `docs/research/ref-env-n16.md` §5 of the port project); the p150a rows are the port's own Stage-1
|
| 5 |
+
benchmark and the served numbers of this image. Nothing here was re-measured for this file; every number names its source.
|
| 6 |
+
|
| 7 |
+
## What was run
|
| 8 |
+
|
| 9 |
+
| | |
|
| 10 |
+
|---|---|
|
| 11 |
+
| Model (GPU) | NVIDIA's **unmodified** `Gr00tPolicy` from [Isaac-GR00T](https://github.com/NVIDIA/Isaac-GR00T) `n1.6.1-release` — Eagle-Block2A-2B-v2 backbone (SigLIP2 252² → 81 tokens, Qwen3-1.7B[:16]) + `AlternateVLDiT` action head, 4 Euler flow-matching steps — i.e. the network the p150a port is PCC-gated against |
|
| 12 |
+
| Weights | `nvidia/GR00T-N1.6-3B` @ `d0814e7ecb19202e7c8468b46098b0b7ef3a6d61` (= `tt-model.yaml` `weights.revision` = `serve.env.TT_WEIGHTS_REVISION`), from the HF cache |
|
| 13 |
+
| Observation | `demo_data/gr1.PickNPlace` episode 0, frame 0 (GR1: one 256×256 `ego_view_bg_crop_pad_res256_freq20` frame, 5 state groups 7/7/6/6/3, instruction "pick the pear from the counter and place it in the plate") — the same step shipped as `media/demo_observation.json` + `media/demo_ego_view.png` and used by the smoke test; batch 1 |
|
| 14 |
+
| GPU | NVIDIA GeForce RTX 5090 (sm_120), the same host as the p150a; GPU otherwise idle (`nvidia-smi` compute-app list recorded in every run manifest) |
|
| 15 |
+
| GPU software | Python 3.10.20, torch 2.7.1+cu128 (cuDNN 90701), transformers 4.51.3, flash_attn 2.7.4.post1 (sm_120 SASS, imports and runs natively), numpy 1.26.4 — the `uv.lock` of `Isaac-GR00T-n1.6` (`ref-env-n16.md` §1) |
|
| 16 |
+
| GPU loop | medians of **20 warm iterations** after warm-up, `torch.cuda.synchronize()` around each call, one process per configuration |
|
| 17 |
+
| GPU timing definitions | `e2e` = `policy.get_action` incl. ~2.5 ms of CPU preprocessing (albumentations, PIL resize, tokenisation) and the numpy decode; `backbone` and `action head` are the GPU sub-steps (`action head` = 4 DiT steps + encoders/decoder) |
|
| 18 |
+
| p150a (device) | one Blackhole p150a, tt-metal `668c2907575`, the port's `benchmarks/bench_e2e.py` (Stage-1: TTNN ops in four Metal traces, `mixed_dit` = bfp8_b DiT matmul weights / bf16 elsewhere, `per_stage` layout): 10 warm-up calls, then **50 calls** of `encode → upload (+sync) → 4 × execute_trace → one sync → D2H → decode`, host wall clock medians; a second 50-call pass with a sync after every trace gives the per-trace split — `code/models/experimental/gr00t/benchmarks/results/e2e_stage1_n16.json` |
|
| 19 |
+
| p150a (served) | this image, `POST /predict` on the demo observation, seed path, 50 requests after 5 warm-ups (`code/scripts/bench_http.py`), server-side `timing_ms` |
|
| 20 |
+
|
| 21 |
+
## Correctness reference (what "same output" means here)
|
| 22 |
+
|
| 23 |
+
The port is gated against the **fp32 CPU run** of NVIDIA's code (the golden). NVIDIA's own bf16 + flash-attention GPU path
|
| 24 |
+
sits at a measurable distance from that golden, which bounds what any bf16 implementation can be asked to reproduce
|
| 25 |
+
(`code/models/experimental/gr00t/common/golden_tap_map.json`, `thresholds.n16`):
|
| 26 |
+
|
| 27 |
+
| tensor | official bf16 GPU vs fp32 golden (PCC) | p150a Stage-1 vs fp32 golden (PCC) | gate |
|
| 28 |
+
|---|---:|---:|---:|
|
| 29 |
+
| `backbone_features` (LLM output, 116 tokens × 2048) | 0.99679 | 0.99878 | 0.9917 |
|
| 30 |
+
| `action_pred_valid` (16 steps × 29 action dims, normalised) | 0.99956 | 0.99921 | 0.998 |
|
| 31 |
+
| `unnormalized_actions` — `left_arm` / `right_arm` / `right_hand` | — | 0.99995 / 0.99991 / 0.99312 | 0.9999 / 0.9998 / 0.99 |
|
| 32 |
+
|
| 33 |
+
p150a values: `tests/tt/results/test_e2e_{untraced_taps_vs_golden,predict_actions_vs_golden}_n16_20260914-2324*.json`. Four
|
| 34 |
+
intermediate DiT taps of the p150a run miss their per-tap gates on the unused state-token row (`dit_out[k=1]` 0.999556 vs 0.99961,
|
| 35 |
+
`dit_out[k=2]` 0.999496 vs 0.99964, `action_decoder_out[k=1]` 0.999579 vs 0.9997, `action_decoder_out[k=2]` 0.999556 vs 0.99978);
|
| 36 |
+
every action tap passes — see the card's Caveats.
|
| 37 |
+
|
| 38 |
+
## GPU latency (RTX 5090, batch 1, medians of 20 iterations, ms)
|
| 39 |
+
|
| 40 |
+
| configuration | e2e `get_action` | data proc (CPU) | backbone (GPU) | action head = 4 DiT steps (GPU) |
|
| 41 |
+
|---|---:|---:|---:|---:|
|
| 42 |
+
| **official**: bf16 + flash-attn 2, deterministic algorithms OFF, `cudnn.benchmark` ON, eager PyTorch | **63.1** | 2.5 | 16.8 | 36.2 |
|
| 43 |
+
| **official + `torch.compile(DiT.forward, mode="max-autotune")`** (as `standalone_inference_script.py`; compile 41 s; inductor skipped some Triton mm configs on sm_120 "out of shared memory") | **33.1** | 2.4 | 17.1 | 13.5 |
|
| 44 |
+
| golden run `bf16_fa2` (deterministic algorithms ON, `CUBLAS_WORKSPACE_CONFIG=:4096:8`, `cudnn.benchmark` OFF) | 97.3 | 2.6 | 25.3 | 66.8 |
|
| 45 |
+
| golden run `bf16_sdpa` (same flags) | 93.2 | 2.9 | 23.6 | 66.9 |
|
| 46 |
+
| golden run `fp32_math` (same flags, fp32, math SDPA) | 114.5 | 2.6 | 32.8 | 80.4 |
|
| 47 |
+
|
| 48 |
+
The official rows reproduce NVIDIA's README table for the RTX 5090 (eager 58 ms, compiled 37 ms e2e; backbone 18 ms; action head
|
| 49 |
+
38 → 16 ms). The "golden" rows are the settings the fp32 goldens were dumped with; the deterministic mode costs ~35 ms
|
| 50 |
+
(`CUBLAS_WORKSPACE_CONFIG` roughly doubles the small-M DiT GEMMs — `docs/research/golden-multisample.md` §3) and is not a serving
|
| 51 |
+
configuration. The eager action head is dispatch-bound (128 DiT-block evaluations in 36 ms), which is why `torch.compile` gains 2.7×
|
| 52 |
+
on it — and the regime the port's Stage-2 persistent megakernel targets.
|
| 53 |
+
|
| 54 |
+
## p150a latency (batch 1, ms)
|
| 55 |
+
|
| 56 |
+
| row | median | p90 | source |
|
| 57 |
+
|---|---:|---:|---|
|
| 58 |
+
| `bench_e2e` end-to-end (host encode + upload + 4 traces + D2H + host decode) | **59.42** | 60.10 | `e2e_stage1_n16.json` `stages.e2e` |
|
| 59 |
+
| device = upload + traces + D2H | 57.20 | 57.67 | `stages.device` |
|
| 60 |
+
| 4 traces (one sync) | 53.27 | 53.29 | `stages.traces` |
|
| 61 |
+
| trace `vision` (SigLIP2 tower + unshuffle projector) | 11.49 | 11.50 | `stages.trace/vision` (split pass) |
|
| 62 |
+
| trace `llm` (Qwen3-1.7B[:16], S 116 → 128) | 9.50 | 9.52 | `stages.trace/llm` |
|
| 63 |
+
| trace `adapter` (VL-LN, K/V hoist, state encoder) | 1.98 | 1.99 | `stages.trace/adapter` |
|
| 64 |
+
| trace `denoise` (4 Euler steps × 32 DiT blocks + decoder) | 30.40 | 30.41 | `stages.trace/denoise` |
|
| 65 |
+
| upload / D2H / host encode / host decode | 3.79 / 0.09 / 1.99 / 0.17 | 4.31 / 0.11 / 2.28 / 0.21 | `stages.*` |
|
| 66 |
+
| served `timing_ms.device` (this image, 50 requests after 5 warm-ups, quiet host) | 56.8 | 57.3 | `bench_http.py` run of the container validation (round 1, `bench-n16-c1-20260915-014844.json`) |
|
| 67 |
+
| served `timing_ms.total` (handler wall incl. base64 + PNG decode) | 59.4 | 59.8 | same |
|
| 68 |
+
| served client wall (localhost, incl. HTTP + JSON) | 61.0 | 61.6 | same |
|
| 69 |
+
|
| 70 |
+
## Comparison with matching definitions
|
| 71 |
+
|
| 72 |
+
Ratio = GPU ms / p150a ms (> 1 means the p150a is faster).
|
| 73 |
+
|
| 74 |
+
| row | p150a | GPU | ratio |
|
| 75 |
+
|---|---:|---:|---:|
|
| 76 |
+
| end-to-end policy call: `bench_e2e` e2e 59.42 (encode + device + decode) vs `get_action` eager bf16 e2e 63.1 (data proc + backbone + head) | 59.42 | 63.1 | **1.06** (p150a faster) |
|
| 77 |
+
| same vs `get_action` with `torch.compile(DiT)` | 59.42 | 33.1 | **0.56** (GPU 1.80× faster) |
|
| 78 |
+
| model only: p150a device 57.20 (upload + traces + D2H) vs GPU backbone + head 53.0 (eager) | 57.20 | 53.0 | 0.93 (GPU 1.08× faster) |
|
| 79 |
+
| model only vs GPU compiled backbone + head 30.6 | 57.20 | 30.6 | 0.53 (GPU 1.87× faster) |
|
| 80 |
+
| denoise: p150a `denoise` trace 30.40 vs GPU action head 36.2 (eager) / 13.5 (compiled) | 30.40 | 36.2 / 13.5 | 1.19 / 0.44 |
|
| 81 |
+
| vision + LLM: p150a `vision` + `llm` traces 20.99 vs GPU backbone 16.8 | 20.99 | 16.8 | 0.80 (GPU 1.25× faster) |
|
| 82 |
+
|
| 83 |
+
Reading: against NVIDIA's eager bf16 path the Stage-1 p150a port is at parity end-to-end (1.06× faster); against the compiled
|
| 84 |
+
DiT the GPU is 1.8× faster, entirely in the denoise stage (30.4 vs 13.5 ms) — the p150a's four-step DiT is the part the
|
| 85 |
+
persistent megakernel (Stage 2, not in this image; weight streaming measured at 464 GB/s bf16 / 414 GB/s bfp8 in
|
| 86 |
+
`tests/tt/results/mk_k1_summary.md`) is meant to replace. The GPU's `data proc` (2.5 ms) and the p150a's `host encode` (2.0 ms) are the
|
| 87 |
+
same kind of host work; HTTP/JSON framing is excluded on both sides except in the "served client wall" row.
|
| 88 |
+
|
| 89 |
+
Not measured / not claimed: p150a power (no power or efficiency comparison); TensorRT or FP8 on the GPU; the compiled GPU path with
|
| 90 |
+
the p150a's exact host chain; N1.6's `gr1_long_text` layout. GPU numbers were not re-run for this card; they are copied with their
|
| 91 |
+
source lines from `ref-env-n16.md` §5 (which also records the machine state of each run).
|
LICENSE
ADDED
|
@@ -0,0 +1,61 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
NVIDIA License
|
| 2 |
+
1. Definitions
|
| 3 |
+
“Licensor” means any person or entity that distributes its Work.
|
| 4 |
+
“Work” means (a) the original work of authorship made available under this license,
|
| 5 |
+
which may include software, documentation, or other files, and (b) any additions to or
|
| 6 |
+
derivative works thereof that are made available under this license.
|
| 7 |
+
The terms “reproduce,” “reproduction,” “derivative works,” and “distribution” have the
|
| 8 |
+
meaning as provided under U.S. copyright law; provided, however, that for the purposes
|
| 9 |
+
of this license, derivative works shall not include works that remain separable from, or
|
| 10 |
+
merely link (or bind by name) to the interfaces of, the Work.
|
| 11 |
+
Works are “made available” under this license by including in or with the Work either (a)
|
| 12 |
+
a copyright notice referencing the applicability of this license to the Work, or (b) a copy
|
| 13 |
+
of this license.
|
| 14 |
+
2. License Grant
|
| 15 |
+
2.1 Copyright Grant. Subject to the terms and conditions of this license, each
|
| 16 |
+
Licensor grants to you a perpetual, worldwide, non-exclusive, royalty-free,
|
| 17 |
+
copyright license to use, reproduce, prepare derivative works of, publicly display,
|
| 18 |
+
publicly perform, sublicense and distribute its Work and any resulting derivative
|
| 19 |
+
works in any form.
|
| 20 |
+
3. Limitations
|
| 21 |
+
3.1 Redistribution. You may reproduce or distribute the Work only if (a) you do so
|
| 22 |
+
under this license, (b) you include a complete copy of this license with your
|
| 23 |
+
distribution, and (c) you retain without modification any copyright, patent,
|
| 24 |
+
trademark, or attribution notices that are present in the Work.
|
| 25 |
+
3.2 Derivative Works. You may specify that additional or different terms apply to
|
| 26 |
+
the use, reproduction, and distribution of your derivative works of the Work (“Your
|
| 27 |
+
Terms”) only if (a) Your Terms provide that the use limitation in Section 3.3
|
| 28 |
+
applies to your derivative works, and (b) you identify the specific derivative works
|
| 29 |
+
that are subject to Your Terms. Notwithstanding Your Terms, this license (including
|
| 30 |
+
the redistribution requirements in Section 3.1) will continue to apply to the Work
|
| 31 |
+
itself.
|
| 32 |
+
3.3 Use Limitation. The Work and any derivative works thereof only may be used
|
| 33 |
+
or intended for use non-commercially. Notwithstanding the foregoing, NVIDIA
|
| 34 |
+
Corporation and its affiliates may use the Work and any derivative works
|
| 35 |
+
commercially. As used herein, “non-commercially” means for research or
|
| 36 |
+
evaluation purposes only.
|
| 37 |
+
3.4 Patent Claims. If you bring or threaten to bring a patent claim against any
|
| 38 |
+
Licensor (including any claim, cross-claim or counterclaim in a lawsuit) to enforce
|
| 39 |
+
any patents that you allege are infringed by any Work, then your rights under this
|
| 40 |
+
license from such Licensor (including the grant in Section 2.1) will terminate
|
| 41 |
+
immediately.
|
| 42 |
+
3.5 Trademarks. This license does not grant any rights to use any Licensor’s or its
|
| 43 |
+
affiliates’ names, logos, or trademarks, except as necessary to reproduce the
|
| 44 |
+
notices described in this license.
|
| 45 |
+
3.6 Termination. If you violate any term of this license, then your rights under this
|
| 46 |
+
license (including the grant in Section 2.1) will terminate immediately.
|
| 47 |
+
4. Disclaimer of Warranty.
|
| 48 |
+
THE WORK IS PROVIDED “AS IS” WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND,
|
| 49 |
+
EITHER EXPRESS OR IMPLIED, INCLUDING WARRANTIES OR CONDITIONS OF
|
| 50 |
+
MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, TITLE OR NON-
|
| 51 |
+
INFRINGEMENT. YOU BEAR THE RISK OF UNDERTAKING ANY ACTIVITIES UNDER THIS
|
| 52 |
+
LICENSE.
|
| 53 |
+
5. Limitation of Liability.
|
| 54 |
+
EXCEPT AS PROHIBITED BY APPLICABLE LAW, IN NO EVENT AND UNDER NO LEGAL
|
| 55 |
+
THEORY, WHETHER IN TORT (INCLUDING NEGLIGENCE), CONTRACT, OR OTHERWISE
|
| 56 |
+
SHALL ANY LICENSOR BE LIABLE TO YOU FOR DAMAGES, INCLUDING ANY DIRECT,
|
| 57 |
+
INDIRECT, SPECIAL, INCIDENTAL, OR CONSEQUENTIAL DAMAGES ARISING OUT OF OR
|
| 58 |
+
RELATED TO THIS LICENSE, THE USE OR INABILITY TO USE THE WORK (INCLUDING BUT
|
| 59 |
+
NOT LIMITED TO LOSS OF GOODWILL, BUSINESS INTERRUPTION, LOST PROFITS OR
|
| 60 |
+
DATA, COMPUTER FAILURE OR MALFUNCTION, OR ANY OTHER DAMAGES OR LOSSES),
|
| 61 |
+
EVEN IF THE LICENSOR HAS BEEN ADVISED OF THE POSSIBILITY OF SUCH DAMAGES.
|
LICENSE-NOTICE.md
ADDED
|
@@ -0,0 +1,26 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Licence notice — `changh95/GR00T-N1.6-3B-p150`
|
| 2 |
+
|
| 3 |
+
This repository is a **tt-model container package**: a Docker image (`image/`), the code inside it (`code/`), a manifest
|
| 4 |
+
and a card. It contains **no model weights**. Four licences apply to what is here and to what the package fetches.
|
| 5 |
+
|
| 6 |
+
| component | where | licence |
|
| 7 |
+
|---|---|---|
|
| 8 |
+
| Model weights `nvidia/GR00T-N1.6-3B` @ `d0814e7ecb19202e7c8468b46098b0b7ef3a6d61` | **not in this repo** — `tt-model serve` / `scripts/download_weights.sh` fetch exactly the files listed in `tt-model.yaml` (`weights.allow_patterns`) into your Hugging Face cache | **NVIDIA License** (the `LICENSE` file of the weights repository; a verbatim copy is [`LICENSE`](LICENSE) in this repo). §3.3: use is limited to **non-commercial purposes** — research or evaluation only. §3.1: redistribution must carry the same licence and a complete copy of it. §3.2: derivative works must carry the same use limitation. This is **not** the NVIDIA Open Model License and **not** Apache-2.0. |
|
| 9 |
+
| Vendored tokenizer files `code/gr00t_p150/assets/tokenizer/n16/{vocab.json, merges.txt, tokenizer_config.json, special_tokens_map.json, added_tokens.json}` | in this repo and in the image (`/opt/tt-metal/gr00t_p150/assets/tokenizer/n16`) | copied from [NVIDIA/Isaac-GR00T](https://github.com/NVIDIA/Isaac-GR00T) tag `n1.6.1-release`, path `gr00t/model/modules/nvidia/Eagle-Block2A-2B-v2/`; that repository's `LICENSE` is the same **NVIDIA License** as the weights. The files are the Qwen2 BPE vocabulary + merges plus the Eagle special tokens (`<IMG_CONTEXT>` = 151669, `<img>` = 151670, `</img>` = 151671); they are not part of the weights repo, which is why they ship here. |
|
| 10 |
+
| Demo observation `media/demo_ego_view.png`, `media/demo_observation.json`, `code/gr00t_p150/demo/n16/` (frame, raw state, instruction, the reference initial noise and the fp32 / bf16 reference actions) | in this repo and in the image | one GR1 PickNPlace step from the Isaac-GR00T demo data (`demo_data`, distributed with the Isaac-GR00T repository); the reference actions were computed with NVIDIA's unmodified code on the pinned weights and are therefore derivative of the weights (NVIDIA License §3.2 applies to their use). |
|
| 11 |
+
| Port and serving code: `code/models/experimental/gr00t/` (the tt-nn port of GR00T N1.5 / N1.6 / N1.7: `common/`, `reference/`, `tt/` incl. `tt/megakernel/`, `tests/`, `benchmarks/`), `code/gr00t_p150/` (FastAPI server, schemas, smoke test, demo builder), `code/scripts/` | in this repo and in the image (`/opt/tt-metal/...`) | **Apache-2.0** (`SPDX-License-Identifier: Apache-2.0`, © 2026 Tenstorrent USA, Inc. in every source file). Because the port only runs the NVIDIA-licensed weights and is distributed together with the NVIDIA-licensed tokenizer files and reference actions, the package as a whole is offered under the NVIDIA License's non-commercial use limitation; the Apache-2.0 grant on the code itself is unaffected. |
|
| 12 |
+
| tt-metal / tt-nn: `code/models/common/utility_functions.py`, `code/models/tt_dit/**`, `code/models/demos/deepseek_v3_b1/unified_kernel_descriptor.py` and the whole tt-metal build inside the image (`/opt/tt-metal`, commit `668c290757550588d0ce46b180c344a462a2aaf5`) | in this repo (the three files) and in the image | **Apache-2.0** ([tenstorrent/tt-metal](https://github.com/tenstorrent/tt-metal/blob/main/LICENSE)). |
|
| 13 |
+
| Third-party Python packages inside the image (`requirements.lock`: torch 2.11.0+cpu, transformers 5.12.1, opencv-python-headless 4.8.1.78, numpy 1.26.4, fastapi, uvicorn, pydantic, pillow, safetensors, huggingface_hub, loguru, ...) and the Ubuntu 22.04 base | in the image | their respective licences (BSD-3 / Apache-2.0 / MIT / HPND; Ubuntu package licences). |
|
| 14 |
+
|
| 15 |
+
## Practical reading
|
| 16 |
+
|
| 17 |
+
- **You may** download the weights and run this package for research or evaluation. **You may not** use the weights, the
|
| 18 |
+
vendored tokenizer files, the reference actions, or the actions this server produces for a commercial purpose (NVIDIA
|
| 19 |
+
License §3.3), and you must keep the NVIDIA License with any copy you redistribute (§3.1).
|
| 20 |
+
- The Apache-2.0 code (`code/models/experimental/gr00t`, `code/gr00t_p150`, `code/scripts`) can be reused under Apache-2.0
|
| 21 |
+
on its own; running it against GR00T weights puts you back under the NVIDIA License.
|
| 22 |
+
- The upstream paper is the GR00T N1 report ([arXiv:2503.14734](https://arxiv.org/abs/2503.14734)); GR00T N1.6's own
|
| 23 |
+
page is https://research.nvidia.com/labs/gear/gr00t-n1_6/. The `arxiv:2504.15271` tag on the upstream model card is the
|
| 24 |
+
Eagle 2.5 backbone paper, not a GR00T paper.
|
| 25 |
+
- Hugging Face metadata of this repo: `license: other`, `license_name: nvidia-license`,
|
| 26 |
+
`license_link: https://huggingface.co/nvidia/GR00T-N1.6-3B/blob/main/LICENSE`, `base_model: nvidia/GR00T-N1.6-3B`.
|
README.md
CHANGED
|
@@ -4,8 +4,21 @@ tags:
|
|
| 4 |
- p150
|
| 5 |
- tt-dit-server
|
| 6 |
- tt-model-cache
|
| 7 |
-
- tt-model-catalog
|
| 8 |
- tt-model-container
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 9 |
---
|
| 10 |
|
| 11 |
# gr00t-n1.6-3b-p150
|
|
@@ -24,7 +37,8 @@ tt-model pull changh95/GR00T-N1.6-3B-p150 --with-weights
|
|
| 24 |
tt-model serve changh95/GR00T-N1.6-3B-p150
|
| 25 |
```
|
| 26 |
|
| 27 |
-
|
|
|
|
| 28 |
|
| 29 |
### Run with tt-cli
|
| 30 |
|
|
|
|
| 4 |
- p150
|
| 5 |
- tt-dit-server
|
| 6 |
- tt-model-cache
|
|
|
|
| 7 |
- tt-model-container
|
| 8 |
+
- tenstorrent
|
| 9 |
+
- ttnn
|
| 10 |
+
- tt-metal
|
| 11 |
+
- tt-nn
|
| 12 |
+
- robotics
|
| 13 |
+
- vla
|
| 14 |
+
- gr00t
|
| 15 |
+
- tt-model-catalog
|
| 16 |
+
pipeline_tag: robotics
|
| 17 |
+
license: other
|
| 18 |
+
license_name: nvidia-license
|
| 19 |
+
license_link: https://huggingface.co/nvidia/GR00T-N1.6-3B/blob/main/LICENSE
|
| 20 |
+
base_model:
|
| 21 |
+
- nvidia/GR00T-N1.6-3B
|
| 22 |
---
|
| 23 |
|
| 24 |
# gr00t-n1.6-3b-p150
|
|
|
|
| 37 |
tt-model serve changh95/GR00T-N1.6-3B-p150
|
| 38 |
```
|
| 39 |
|
| 40 |
+
- Weights [`nvidia/GR00T-N1.6-3B`](https://huggingface.co/nvidia/GR00T-N1.6-3B) at `d0814e7ecb19` (2 bf16 safetensors shards, 6.57 GB) go to your HF cache; the image does not contain them.
|
| 41 |
+
- Serves on port 20000 (or the next free port); ready when the log says `Application startup complete`.
|
| 42 |
|
| 43 |
### Run with tt-cli
|
| 44 |
|
SERVING.md
ADDED
|
@@ -0,0 +1,229 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Serving GR00T N1.6-3B (`nvidia/GR00T-N1.6-3B`) on Blackhole with tt-model-manager
|
| 2 |
+
|
| 3 |
+
This repo is a **tt-model container package source**: `tt-model.yaml` + the code under `code/`. `tt-model package
|
| 4 |
+
--container` builds the OCI image (tt-metal from source + the port + the HTTP stack), `tt-model serve` runs it against
|
| 5 |
+
the card, `tt-model push` publishes it here. The server is `code/gr00t_p150/server/app.py` (FastAPI, `kind:
|
| 6 |
+
tt-dit-server`); the device model is the tt-nn port `code/models/experimental/gr00t` (Stage-1 path: TTNN ops captured
|
| 7 |
+
in four Metal traces, DiT matmul weights bfp8_b, everything else bf16). Weights are a pinned pointer, never in the image.
|
| 8 |
+
|
| 9 |
+
| | |
|
| 10 |
+
|---|---|
|
| 11 |
+
| tt-metal | main `668c290757550588d0ce46b180c344a462a2aaf5` (`v0.79.0-dev20260914-1-g668c2907575`), built from source inside the image; torch pin 2.11.0 (+cpu in the image) |
|
| 12 |
+
| weights | `nvidia/GR00T-N1.6-3B` @ `d0814e7ecb19202e7c8468b46098b0b7ef3a6d61` — `model-0000{1,2}-of-00002.safetensors` (6,573,217,664 B), `model.safetensors.index.json`, `config.json`, `processor_config.json`, `statistics.json`, `embodiment_id.json`, `LICENSE` (NVIDIA License, non-commercial) |
|
| 13 |
+
| app | `gr00t_p150.server.app:app` (uvicorn `--lifespan on`; the lifespan resolves the snapshot, opens the device, builds `Gr00tTT`, captures the traces, runs `GR00T_WARMUP_RUNS` traced predictions and checks them against the shipped fp32 golden before READY) |
|
| 14 |
+
| device recipe | `models.experimental.gr00t.tt.device.open_gr00t_device(device_id, trace_region_size=64 MiB, l1_small_size=32768, num_command_queues=1)` — the port's validated parameters; asserts the 11×10 compute / 8×1 DRAM grid of a p150 |
|
| 15 |
+
| port source | `code/models/experimental/gr00t` = the frozen snapshot commit `5dc0517ee3bec090b7ead025001a343c2f63aa7b` (ref `gr00t-p150-snapshot`, parent = `668c2907575`) of the tt-metal working tree `models/experimental/gr00t`; `code/gr00t_p150` (server) and `code/scripts` were written for this release |
|
| 16 |
+
| only served configuration | version `n16`, embodiment `gr1` (slot 20), static layout `gr1` (1 camera × 81 image tokens, `L_max` 24 text tokens, LLM sequence padded to 128), `mixed_dit` dtype policy, `per_stage` trace layout, batch 1 |
|
| 17 |
+
|
| 18 |
+
Below, `$ROOT` = the tt-models tooling checkout (`/home/deepgadget/experiments/tt-models` on the build host: `tt-model` CLI in
|
| 19 |
+
`$ROOT/.venv/bin`, rootless Docker env in `$ROOT/bin/docker-env.sh`), `$TREE` = the tt-metal tree with the built `python_env`
|
| 20 |
+
(`/home/deepgadget/experiments/gr00t/tt-metal`), `$REPO` = this directory.
|
| 21 |
+
|
| 22 |
+
## Layout
|
| 23 |
+
|
| 24 |
+
```
|
| 25 |
+
tt-model.yaml authoring manifest (schema 5.1) -- the whole build/serve interface
|
| 26 |
+
tt_kernel_manifest.json GENERATED wire manifest: weights pointer, image tag/digest, runtime, serve, verify, built provenance
|
| 27 |
+
requirements.lock GENERATED `pip freeze` of the image venv (Python 3.12, torch 2.11.0+cpu, ttnn <scm>)
|
| 28 |
+
image/ GENERATED OCI layout of the image (~3 GB)
|
| 29 |
+
README.md the card (generated by `tt-model package` from card.description / card.quickstart; front matter restored after push)
|
| 30 |
+
SERVING.md, GPU_COMPARISON.md, LICENSE, LICENSE-NOTICE.md authored
|
| 31 |
+
media/demo_ego_view.png the GR1 PickNPlace demo frame (256x256), media/demo_observation.json the matching raw state + instruction
|
| 32 |
+
media/demo_actions_vs_golden.png served action chunk vs the fp32 reference, one panel per action dimension
|
| 33 |
+
code/models/experimental/gr00t/ the port: common/ (host preprocessing, prompts, normalisation, checkpoint, weight plan),
|
| 34 |
+
reference/ (fp32 torch reference), tt/ (device model, layers, traces, tt/megakernel/ Stage-2 work),
|
| 35 |
+
tests/ (CPU + device suites and their results JSONs), benchmarks/ (bench_e2e etc. + results)
|
| 36 |
+
code/models/common/utility_functions.py, code/models/tt_dit/{utils,layers,parallel,encoders/qwen3vl}/..., code/models/demos/deepseek_v3_b1/unified_kernel_descriptor.py
|
| 37 |
+
the tt-metal files the port imports from the tree other than itself (staged by tt-model from `source.code`)
|
| 38 |
+
code/gr00t_p150/ server/{app.py, schemas.py, smoke_test.py}, demo/n16/ (canonical demo observation + golden), assets/tokenizer/n16/ (vendored Qwen2 tokenizer)
|
| 39 |
+
code/scripts/ download_weights.sh (pinned snapshot -> HF cache), bench_http.py (HTTP latency, 50 requests)
|
| 40 |
+
```
|
| 41 |
+
|
| 42 |
+
In the image the code lands at `/opt/tt-metal/<path>` with `PYTHONPATH=/opt/tt-metal`, which is exactly the tree layout the port was
|
| 43 |
+
written for (`models.experimental.gr00t.*`, `models.tt_dit.*` absolute imports; `models` is a namespace package).
|
| 44 |
+
|
| 45 |
+
## 1. Run on the HOST (hardware validation, no Docker)
|
| 46 |
+
|
| 47 |
+
The tree venv `$TREE/python_env` (Python 3.10, torch 2.11.0+cpu, ttnn editable, transformers 5.12.1, opencv 4.8.1) has everything
|
| 48 |
+
except `fastapi` / `uvicorn`. Do not install into the tree venv; put the HTTP stack in a side directory and prepend it to `PYTHONPATH`.
|
| 49 |
+
`$REPO/code` must be FIRST on `PYTHONPATH` so `models.experimental.gr00t` resolves to the shipped snapshot (the tree's `models/` is still
|
| 50 |
+
needed for `models.tt_dit.*` on the host; in the image the staged `code/` is the only `models` tree).
|
| 51 |
+
|
| 52 |
+
```bash
|
| 53 |
+
export TREE=/home/deepgadget/experiments/gr00t/tt-metal
|
| 54 |
+
export PATH=$HOME/.local/bin:$PATH # uv
|
| 55 |
+
HTTP=/home/deepgadget/experiments/gr00t/publish/http-side # any writable dir outside the trees
|
| 56 |
+
uv pip install --python $TREE/python_env/bin/python --target $HTTP fastapi uvicorn "pydantic>=2"
|
| 57 |
+
|
| 58 |
+
cd $REPO
|
| 59 |
+
export PYTHONPATH=$PWD/code:$TREE:$TREE/ttnn:$TREE/tools:$HTTP
|
| 60 |
+
export TT_METAL_HOME=$TREE ARCH_NAME=blackhole
|
| 61 |
+
export TT_METAL_CACHE=$HOME/.cache/tt-metal-cache-gr00t # JIT kernels (7 GB warm on the build host)
|
| 62 |
+
export HF_MODEL=nvidia/GR00T-N1.6-3B
|
| 63 |
+
export TT_WEIGHTS_REVISION=d0814e7ecb19202e7c8468b46098b0b7ef3a6d61 # scripts/download_weights.sh puts it in ~/.cache/huggingface
|
| 64 |
+
export TT_MESH_SHAPE=1x1 TT_DEVICE_ID=0 TT_METAL_VISIBLE_DEVICES=0
|
| 65 |
+
export GR00T_VERSION=n16 GR00T_EMBODIMENT=gr1 GR00T_LAYOUT=gr1 GR00T_POLICY=mixed_dit GR00T_TRACE_LAYOUT=per_stage
|
| 66 |
+
export GR00T_TOKENIZER_DIR=$PWD/code/gr00t_p150/assets/tokenizer/n16
|
| 67 |
+
export GR00T_TT_CACHE=$HOME/.cache/gr00t-tt # host .pt plan tier + .tensorbin device tier (~8 GB for n16)
|
| 68 |
+
export GR00T_WARMUP_RUNS=3
|
| 69 |
+
|
| 70 |
+
# import check, no device (what the image's verify.sh does):
|
| 71 |
+
$TREE/python_env/bin/python -c "import gr00t_p150.server.app as a; assert a.app; print('ok')"
|
| 72 |
+
|
| 73 |
+
# serve (opens the device, loads the weights, captures the four traces, 3 warm-up predictions checked against the golden, then READY).
|
| 74 |
+
# The one Blackhole card of the build host is shared with other agents: run server + client + shutdown inside ONE lock hold.
|
| 75 |
+
DEVICE_LOCK_TIMEOUT=14400 /home/deepgadget/experiments/gr00t/bin/with-device.sh bash -c '
|
| 76 |
+
$TREE/python_env/bin/python -m uvicorn --host 127.0.0.1 --port 20016 --lifespan on gr00t_p150.server.app:app & UV=$!
|
| 77 |
+
python3 code/gr00t_p150/server/smoke_test.py --url http://127.0.0.1:20016 --wait 1800 --out /tmp/gr00t-n16-smoke.json; RC=$?
|
| 78 |
+
python3 code/scripts/bench_http.py --url http://127.0.0.1:20016 --n 50 --out /tmp/gr00t-n16-bench.json
|
| 79 |
+
kill -TERM $UV; wait $UV; exit $RC'
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
Boot log landmarks (they drive `tt-model serve`'s boot checklist): `Loading weights: nvidia/GR00T-N1.6-3B @ d0814e7e…` →
|
| 83 |
+
`Tokenizer files: …` → `Opening device 0 (trace_region_size=67108864, l1_small_size=32768)` → `Loading pipeline: Gr00tTT.from_pretrained(...)`
|
| 84 |
+
→ `Model built in N s (1037 tensors, 3775 MB on device, cache path warm|cold)` → `Warming up: capture per_stage traces on the n16 demo
|
| 85 |
+
observation, then 3 traced predict(s)` → `Warmup k/3: … ms` → `Warm-up fidelity vs golden fp32: actions PCC 0.9992…` → `Warmup complete (…)`
|
| 86 |
+
→ uvicorn `Application startup complete`. Startup failures raise and uvicorn exits non-zero (no CPU fallback); a warm-up PCC below
|
| 87 |
+
`GR00T_WARMUP_PCC_MIN` (0.999) fails the boot. Stop with SIGTERM / Ctrl-C: the lifespan releases the traces and device tensors and closes
|
| 88 |
+
the device (`Releasing traces and device tensors`, `Closing device`).
|
| 89 |
+
|
| 90 |
+
Expected smoke line on the demo observation (host, warm caches, `publish/logs/smoke_n16_snapshot_20260914-235724.log` of the build host):
|
| 91 |
+
|
| 92 |
+
```
|
| 93 |
+
PASS GR00T-N1.6-3B-p150 n16: PCC(actions)=0.999209 max|d|=0.0971 PCC(action_pred_valid)=0.999213 repeat_maxdiff=0.0e+00 seed_path_ok device_ms=57.14/57.03 total_ms=64.11/62.68 wall_ms=70 per_group[left_arm=0.99995/0.0176 right_arm=0.99991/0.0423 left_hand=0.80114/0.0589 right_hand=0.99312/0.0971 waist=0.77216/0.0170]
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
Host boot with warm `GR00T_TT_CACHE` + `TT_METAL_CACHE`: model built 0.6–8.5 s (page cache), capture 1.7–2.0 s, 5 warm-ups ~60 ms each,
|
| 97 |
+
READY after 5–13 s. Offline overrides: `GR00T_WEIGHTS_DIR=<dir with the seven snapshot files>` (shimmed into a private hub cache so the
|
| 98 |
+
port's `configs.snapshot_dir("n16")` resolves to it); `GR00T_TOKENIZER_DIR=<dir>`. Every variable is read in the lifespan, never at import.
|
| 99 |
+
|
| 100 |
+
## 2. Package, serve, push (Docker)
|
| 101 |
+
|
| 102 |
+
Rootless Docker on the build host needs `source $ROOT/bin/docker-env.sh` first (PATH + `DOCKER_HOST`; the bare `docker` is podman).
|
| 103 |
+
**Run every `tt-model` command from this directory**: `source.tt_metal` and `extra_code[].root: code` resolve against the process CWD.
|
| 104 |
+
`--out` points outside any git checkout because `stage()` deletes `<out>/gr00t-n1.6-3b-p150` before rebuilding.
|
| 105 |
+
|
| 106 |
+
```bash
|
| 107 |
+
source $ROOT/bin/docker-env.sh
|
| 108 |
+
cd $REPO
|
| 109 |
+
# offline validation (must print VALID)
|
| 110 |
+
$ROOT/.venv/bin/python -c "from tt_kernel.container_manifest import load_container_manifest as L; m = L('tt-model.yaml', check_sources=True); print('VALID', m.name, m.weights_ref)"
|
| 111 |
+
|
| 112 |
+
$ROOT/.venv/bin/tt-model package --container tt-model.yaml --out /home/deepgadget/experiments/gr00t/publish/build # ~2 h cold (tt-metal C++ build), runs verify.sh
|
| 113 |
+
# serve -> smoke -> bench -> stop inside ONE device-lock hold (the container keeps the card after `serve` returns)
|
| 114 |
+
DEVICE_LOCK_TIMEOUT=14400 /home/deepgadget/experiments/gr00t/bin/with-device.sh bash -c '
|
| 115 |
+
source $ROOT/bin/docker-env.sh
|
| 116 |
+
$ROOT/.venv/bin/tt-model serve /home/deepgadget/experiments/gr00t/publish/build/gr00t-n1.6-3b-p150/tt_kernel_manifest.json || exit 1
|
| 117 |
+
python3 code/gr00t_p150/server/smoke_test.py --url http://127.0.0.1:20000 --out /tmp/gr00t-n16-smoke.json
|
| 118 |
+
python3 code/scripts/bench_http.py --url http://127.0.0.1:20000 --n 50 --out /tmp/gr00t-n16-bench.json
|
| 119 |
+
$ROOT/.venv/bin/tt-model stop /home/deepgadget/experiments/gr00t/publish/build/gr00t-n1.6-3b-p150/tt_kernel_manifest.json' # org/name is a valid target only after pull/push
|
| 120 |
+
$ROOT/.venv/bin/tt-model push /home/deepgadget/experiments/gr00t/publish/build/gr00t-n1.6-3b-p150 --publish
|
| 121 |
+
```
|
| 122 |
+
|
| 123 |
+
`serve` pre-downloads the pinned files into `~/.cache/huggingface` (a metadata no-op when present), then
|
| 124 |
+
`docker run --user 0:0 --device /dev/tenstorrent --ipc host --mount /dev/hugepages-1G -v ~/.cache/huggingface:/hf
|
| 125 |
+
-v ~/.cache/tt-model/gr00t-n1.6-3b-p150/{cache,weights,tensors}:/{cache,weight-cache,tensor-cache} -p 20000:20000` with exactly
|
| 126 |
+
`HF_MODEL=nvidia/GR00T-N1.6-3B`, `MESH_DEVICE=P150`, `TT_MESH_SHAPE=1x1`, `HF_HOME=/hf`, `TT_METAL_CACHE=/cache`,
|
| 127 |
+
`TT_DIT_CACHE_DIR=/weight-cache`, `TT_CACHE_PATH=/tensor-cache` and the `serve.env` block of `tt-model.yaml`
|
| 128 |
+
(`TT_WEIGHTS_REVISION`, `GR00T_VERSION=n16`, `GR00T_TT_CACHE=/weight-cache/gr00t-tt`, `GR00T_TOKENIZER_DIR=/opt/tt-metal/gr00t_p150/assets/tokenizer/n16`, …),
|
| 129 |
+
and waits ≤ 1800 s for `Application startup complete`. Serves on 20000 or the next free port (printed). tt-cli users after the push:
|
| 130 |
+
`tt serve changh95/GR00T-N1.6-3B-p150` / `tt model stop changh95/GR00T-N1.6-3B-p150`.
|
| 131 |
+
|
| 132 |
+
Caches on the host (persist across boots): `~/.cache/tt-model/gr00t-n1.6-3b-p150/cache` (JIT kernels, `TT_METAL_CACHE`),
|
| 133 |
+
`~/.cache/tt-model/gr00t-n1.6-3b-p150/weights/gr00t-tt/n16/...` (the port's host plan tier + `.tensorbin` device tier, ~8 GB, written on
|
| 134 |
+
the first boot), weights in `~/.cache/huggingface/hub/models--nvidia--GR00T-N1.6-3B`.
|
| 135 |
+
|
| 136 |
+
Measured on the build host with this image (`docs/publish/build-n16.md` has every command and log):
|
| 137 |
+
|
| 138 |
+
| boot | wall from `docker run` to READY | notes |
|
| 139 |
+
|---|---:|---|
|
| 140 |
+
| first (cold: empty `/cache` and `/weight-cache`) | 137 s | checkpoint → device-layout plan + `.tensorbin` write, JIT of every kernel of the four traces, trace capture, 3 warm-ups (round-0 build `7e1e1380a5a5`, 2026-09-15 00:30 KST) |
|
| 141 |
+
| second (warm caches, 15 min later) | 13 s | `Model built in 1.2 s` (weight tier in the host page cache), capture 5.2 s (round-0 build) |
|
| 142 |
+
| third (warm caches, 1 h later, the shipped build `feb77048a2ed`) | 21 s | `Model built in 11.2 s` (the 7.9 GB weight tier re-read from disk), capture 4.6 s, 3 warm-ups 60.8 / 59.4 / 59.9 ms; smoke PASS, 50-request bench 56.8 / 59.4 ms, clean stop 2.1 s |
|
| 143 |
+
|
| 144 |
+
The shipped image (`feb77048a2ed`, fix round 1) differs from the round-0 build only in the server's `GET /info → license` text and in
|
| 145 |
+
`code/` shipping 8 instead of 2,009 `tests/tt/results` files; the tt-metal build, the port, the serve path and the JIT / weight caches are
|
| 146 |
+
identical, so the cold-boot figure was not re-measured. The served latency in the card is the round-1 run of the shipped image.
|
| 147 |
+
|
| 148 |
+
`push` makes `code/` and `image/` on the Hub exactly the staged trees and replaces `README.md` with the generated card (everything worth
|
| 149 |
+
keeping lives in `card.description` / `card.quickstart`); `tt-model.yaml`, `SERVING.md`, `GPU_COMPARISON.md`, `LICENSE`,
|
| 150 |
+
`LICENSE-NOTICE.md`, `media/` survive (re-uploaded after every push). The front matter (`license: other`, `license_name: nvidia-license`,
|
| 151 |
+
`license_link`, `pipeline_tag: robotics`, `base_model`, extra tags) is restored afterwards with `huggingface_hub.metadata_update`.
|
| 152 |
+
|
| 153 |
+
## 3. Request / response contract
|
| 154 |
+
|
| 155 |
+
| route | returns |
|
| 156 |
+
|---|---|
|
| 157 |
+
| `GET /health` | `{"status": "ok" \| "starting", "model": "GR00T-N1.6-3B-p150", "device": "blackhole:0"}` — 200 always; `ok` only after warm-up |
|
| 158 |
+
| `GET /info` | model / version / task / hardware / `stage` (`served: stage1-ttnn-traces` + megakernel note) / `weights` (repo, revision, snapshot dir actually loaded) / `source` (port snapshot commit, server version, tt-metal commit, ttnn version) / `inputs` (the full observation contract) / `outputs` / `noise.default_seed` (42) / `limits` / `device_facts` / `warmup_latency_ms` / `warmup_fidelity_vs_golden` / `license` |
|
| 159 |
+
| `GET /demo` | `{"request": <ready-to-post demo body>, "expected": <golden actions + gates>}` |
|
| 160 |
+
| `GET /v1/models` | OpenAI-shaped stub (`{"object": "list", "data": [{"id": "nvidia/GR00T-N1.6-3B", ...}]}`) so the tt-model ready card does not 404; this is not a chat API |
|
| 161 |
+
| `POST /predict` | one observation → one 16-step action chunk (below) |
|
| 162 |
+
|
| 163 |
+
`POST /predict` request (JSON; unknown fields → 422):
|
| 164 |
+
|
| 165 |
+
| field | type | meaning |
|
| 166 |
+
|---|---|---|
|
| 167 |
+
| `images` | `{camera key: base64 PNG/JPEG}` or `{camera key: [one frame]}` | exactly one camera, `ego_view_bg_crop_pad_res256_freq20`; any resolution with sides in [64, 4096]; the frame goes through the version's own eval chain (letterbox → 256 INTER_AREA → 0.95 centre crop → 256 → PIL bicubic 252 → Eagle3 normalisation), so no client-controlled shape reaches ttnn |
|
| 168 |
+
| `state` | `{group: [D floats]}` (or `[[D floats]]`) | raw physical joint state: `left_arm` 7, `right_arm` 7, `left_hand` 6, `right_hand` 6, `waist` 3; finite |
|
| 169 |
+
| `instruction` | str (aliases `language`, `prompt`) | task text, 1–2000 chars; ≤ 24 BPE tokens in this layout (longer → 400: `n_text exceeds L_max`); leading/trailing whitespace stripped |
|
| 170 |
+
| `embodiment` | str, optional | must be `gr1` |
|
| 171 |
+
| `seed` | int ≥ 0, optional | CPU-generator seed of the `[1, 50, 128]` flow-matching noise; default 42 (the deployed policy's seed) |
|
| 172 |
+
| `noise` | `[50, 128]` or `[1, 50, 128]` floats, optional | explicit initial noise (the smoke test sends the reference noise); exclusive with `seed` |
|
| 173 |
+
| `state_dtype` | `float32` \| `float64`, optional | default `float32` for N1.6 (the reference dataset's dtype) |
|
| 174 |
+
| `return_normalized` | bool, optional | also return `action_pred_normalized` (`[50, 128]` model-space chunk) and `action_pred_valid_hd` (`[16, 29]`) |
|
| 175 |
+
|
| 176 |
+
Response (200):
|
| 177 |
+
|
| 178 |
+
```json
|
| 179 |
+
{"actions": {"left_arm": [[7 floats] x 16], "right_arm": [...], "left_hand": [[6] x 16], "right_hand": [...], "waist": [[3] x 16]},
|
| 180 |
+
"action_horizon": 16, "action_keys": ["left_arm", "right_arm", "left_hand", "right_hand", "waist"], "action_dims": {"left_arm": 7, "right_arm": 7, "left_hand": 6, "right_hand": 6, "waist": 3},
|
| 181 |
+
"normalized": false, "embodiment": "gr1", "embodiment_id": 20, "version": "n16", "model": "GR00T-N1.6-3B-p150", "layout": "gr1",
|
| 182 |
+
"images": {"ego_view_bg_crop_pad_res256_freq20": {"frames": 1, "received_hw": [256, 256]}}, "seq_len": 116, "prompt_tokens": 12,
|
| 183 |
+
"state_dtype": "float32", "noise_source": "seed", "seed": 42,
|
| 184 |
+
"timing_ms": {"decode": 4.0, "encode": 2.8, "device": 57.1, "decode_actions": 0.2, "total": 64.1}}
|
| 185 |
+
```
|
| 186 |
+
|
| 187 |
+
`actions` are physical, un-normalised joint targets (float32 as decimal JSON): the arm and hand groups are the checkpoint's RELATIVE
|
| 188 |
+
outputs already composed onto the request's `state` (per-step min/max un-normalisation from `statistics.json` + the raw last state,
|
| 189 |
+
clipped), `waist` is ABSOLUTE — exactly `Gr00tPolicy.get_action` for the GR1 data config. `timing_ms`: `decode` = base64 + PNG decode +
|
| 190 |
+
validation, `encode` = the port's host preprocessing, `device` = `predict_normalized` (input writes, `execute_trace` × 4, one blocking
|
| 191 |
+
readback), `decode_actions` = un-normalisation, `total` = handler wall time. Errors: **400** (wrong/missing camera or state group, wrong
|
| 192 |
+
state width, non-finite state, undecodable image, frame outside [64, 4096], empty/too-long instruction, other embodiment, `seed` +
|
| 193 |
+
`noise` together, malformed noise), **422** (schema), **503** while starting, **500** `Type: text` on a device failure. Handlers are
|
| 194 |
+
synchronous and serialised on one lock; batch is 1.
|
| 195 |
+
|
| 196 |
+
## 4. Caveats
|
| 197 |
+
|
| 198 |
+
* **Stage-1 path.** TTNN ops in four Metal traces (`vision` 11.5 ms, `llm` 9.5, `adapter` 2.0, `denoise` 30.4 — `bench_e2e` medians,
|
| 199 |
+
`code/models/experimental/gr00t/benchmarks/results/e2e_stage1_n16.json`); DiT matmul weights bfp8_b, everything else bf16. The
|
| 200 |
+
persistent-megakernel denoise (Stage 2, `tt/megakernel/`, rung K1: 464 GB/s bf16 / 414 GB/s bfp8 weight streaming,
|
| 201 |
+
`tests/tt/results/mk_k1_summary.md`) is **not** integrated into `Gr00tTT` and not served.
|
| 202 |
+
* **N1.6 fidelity margin.** Final actions reproduce the fp32 golden at PCC 0.99921 on the normalised valid slice (the official bf16 GPU
|
| 203 |
+
path scores 0.99956 there; boot/smoke gate 0.999). Four intermediate DiT taps miss their per-tap gates on the state-token row 0 only
|
| 204 |
+
(`dit_out[k=1]` 0.999556 vs 0.99961, `dit_out[k=2]` 0.999496 vs 0.99964, `action_decoder_out[k=1]` 0.999579 vs 0.9997,
|
| 205 |
+
`action_decoder_out[k=2]` 0.999556 vs 0.99978; 52/56 gated rows pass (57/61 rows incl. the determinism row and the four xfail info rows) —
|
| 206 |
+
`tests/tt/results/test_e2e_untraced_taps_vs_golden_n16_20260914-232434.json`, `tests/tt/results/d2_summary.md` §3.2). Nothing downstream
|
| 207 |
+
reads row 0; every action tap passes.
|
| 208 |
+
* **One embodiment, one layout, one camera, batch 1.** `gr1` (GR1 arms + hands + waist), static layout `gr1` (81 image tokens, `L_max` 24,
|
| 209 |
+
`S_pad` 128). `GR00T_LAYOUT=gr1_long_text` (`L_max` 152, `S_pad` 256) exists in the port but was **not** device-validated. Other
|
| 210 |
+
embodiments need their own layout + validation.
|
| 211 |
+
* **Deterministic noise.** Actions are a deterministic function of (observation, seed | noise); the default seed 42 reproduces the
|
| 212 |
+
reference `initial_noise` bit-exactly (`demo/n16/noise.json: seed_equivalent`). Two identical requests return bit-identical chunks.
|
| 213 |
+
* **First boot is cold**: the checkpoint is converted to the device layout into `/weight-cache` (~8 GB) and every kernel is JIT-compiled
|
| 214 |
+
into `/cache`; both persist under `~/.cache/tt-model/gr00t-n1.6-3b-p150/`. Measured boot times: §2.
|
| 215 |
+
* **Python 3.12 image vs 3.10 host venv.** The image resolves the packages on 3.12 (`requirements.lock`); the host venv is 3.10. The
|
| 216 |
+
code is 3.10/3.12 compatible; the image is the authoritative validation (§2 numbers).
|
| 217 |
+
* **Vendored tokenizer** (`code/gr00t_p150/assets/tokenizer/n16`, NVIDIA License — see `LICENSE-NOTICE.md`): verified bit-exact against the
|
| 218 |
+
Isaac-GR00T checkout and the golden `input_ids`.
|
| 219 |
+
* `tt-model curl` / `GET /v1/models` are OpenAI-shaped and are not this API; use the routes above.
|
| 220 |
+
|
| 221 |
+
## 5. Where the numbers come from
|
| 222 |
+
|
| 223 |
+
Everything in the card is measured and shipped: `code/models/experimental/gr00t/benchmarks/results/e2e_stage1_n16.json` (Stage-1 latency,
|
| 224 |
+
50 calls, tt-metal `668c2907575`), `code/models/experimental/gr00t/tests/tt/results/test_e2e_{predict_actions_vs_golden,
|
| 225 |
+
traced_equals_untraced,untraced_taps_vs_golden}_n16_20260914-2324*.json` (fidelity, determinism, the four marginal taps),
|
| 226 |
+
`tests/tt/results/d2_summary.md` (device session D2), `tests/tt/results/mk_k1_summary.md` (megakernel K1), `code/gr00t_p150/demo/n16/expected.json`
|
| 227 |
+
(fp32 golden + official bf16 reference actions for the demo step). The RTX 5090 rows are in `GPU_COMPARISON.md`. The served numbers of this
|
| 228 |
+
image (`timing_ms` over 50 requests, cold / warm boot) were measured on the build host as described in §2 and recorded in
|
| 229 |
+
`docs/publish/build-n16.md` of the port project.
|
media/demo_actions_vs_golden.png
ADDED

|
Git LFS Details
|
media/demo_ego_view.png
ADDED
|
media/demo_observation.json
ADDED
|
@@ -0,0 +1,46 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"instruction": "pick the pear from the counter and place it in the plate",
|
| 3 |
+
"embodiment": "gr1",
|
| 4 |
+
"state_dtype": "float32",
|
| 5 |
+
"state": {
|
| 6 |
+
"left_arm": [
|
| 7 |
+
-0.011470829136669636,
|
| 8 |
+
0.12207967042922974,
|
| 9 |
+
0.0422939732670784,
|
| 10 |
+
-2.0999999046325684,
|
| 11 |
+
-0.014414452016353607,
|
| 12 |
+
-0.030135324224829674,
|
| 13 |
+
-0.0038438651245087385
|
| 14 |
+
],
|
| 15 |
+
"right_arm": [
|
| 16 |
+
0.00674682529643178,
|
| 17 |
+
-0.09052426367998123,
|
| 18 |
+
0.008140102960169315,
|
| 19 |
+
-2.0999999046325684,
|
| 20 |
+
-0.022280285134911537,
|
| 21 |
+
0.01403734926134348,
|
| 22 |
+
0.0010467972606420517
|
| 23 |
+
],
|
| 24 |
+
"left_hand": [
|
| 25 |
+
0.0006738778320141137,
|
| 26 |
+
0.000763183634262532,
|
| 27 |
+
0.0008477637893520296,
|
| 28 |
+
0.0006939115701243281,
|
| 29 |
+
0.0007511776639148593,
|
| 30 |
+
0.004858833272010088
|
| 31 |
+
],
|
| 32 |
+
"right_hand": [
|
| 33 |
+
0.0018731876043602824,
|
| 34 |
+
0.0021648642141371965,
|
| 35 |
+
0.0023829967249184847,
|
| 36 |
+
0.0018253575544804335,
|
| 37 |
+
0.021009067073464394,
|
| 38 |
+
0.01359221339225769
|
| 39 |
+
],
|
| 40 |
+
"waist": [
|
| 41 |
+
0.0,
|
| 42 |
+
0.0,
|
| 43 |
+
0.0
|
| 44 |
+
]
|
| 45 |
+
}
|
| 46 |
+
}
|
tt-model.yaml
ADDED
|
@@ -0,0 +1,212 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-License-Identifier: Apache-2.0
|
| 2 |
+
# tt-model-manager container manifest (schema 5.1) for NVIDIA Isaac GR00T N1.6-3B on Blackhole (Stage-1 TTNN trace path).
|
| 3 |
+
#
|
| 4 |
+
# Run EVERY tt-model command from this directory: `source.tt_metal` and `extra_code[].root: code` resolve against the
|
| 5 |
+
# process CWD, not against this file. `--out` must lie outside any git checkout (`package` deletes <out>/<name> first).
|
| 6 |
+
# On the build host rootless Docker needs `source /home/deepgadget/experiments/tt-models/bin/docker-env.sh` first.
|
| 7 |
+
#
|
| 8 |
+
# tt-model package --container tt-model.yaml --out /home/deepgadget/experiments/gr00t/publish/build # ~2 h cold, runs verify.sh
|
| 9 |
+
# tt-model serve /home/deepgadget/experiments/gr00t/publish/build/gr00t-n1.6-3b-p150/tt_kernel_manifest.json
|
| 10 |
+
# python code/gr00t_p150/server/smoke_test.py --url http://127.0.0.1:20000 # PASS/FAIL one-liner
|
| 11 |
+
# tt-model stop /home/deepgadget/experiments/gr00t/publish/build/gr00t-n1.6-3b-p150/tt_kernel_manifest.json # org/name works only after pull/push
|
| 12 |
+
# tt-model push /home/deepgadget/experiments/gr00t/publish/build/gr00t-n1.6-3b-p150 --publish
|
| 13 |
+
#
|
| 14 |
+
# The one Blackhole card of the build host is shared: `serve -> smoke -> stop` runs inside ONE bin/with-device.sh hold.
|
| 15 |
+
schema: "5.1"
|
| 16 |
+
|
| 17 |
+
repo: changh95/GR00T-N1.6-3B-p150
|
| 18 |
+
name: gr00t-n1.6-3b-p150
|
| 19 |
+
|
| 20 |
+
# A POINTER, pinned. `serve` pre-downloads exactly these files at this sha into the host HF cache (mounted at /hf);
|
| 21 |
+
# the server resolves the same snapshot with snapshot_download(revision=TT_WEIGHTS_REVISION) and asserts that the
|
| 22 |
+
# port's own common.configs.snapshot_dir("n16") points at it. The weights never enter the image.
|
| 23 |
+
weights:
|
| 24 |
+
repo: nvidia/GR00T-N1.6-3B
|
| 25 |
+
revision: d0814e7ecb19202e7c8468b46098b0b7ef3a6d61
|
| 26 |
+
allow_patterns:
|
| 27 |
+
- "model-*.safetensors" # 2 bf16 shards, 6,573,217,664 B
|
| 28 |
+
- model.safetensors.index.json # LazyCheckpoint needs it (common/checkpoint.py)
|
| 29 |
+
- config.json
|
| 30 |
+
- processor_config.json # modality configs (common/normalization.py)
|
| 31 |
+
- statistics.json # per-embodiment min/max statistics (common/normalization.py)
|
| 32 |
+
- embodiment_id.json # tag -> slot cross-check (common/normalization.py)
|
| 33 |
+
- LICENSE # NVIDIA License: keep it next to the weights it covers
|
| 34 |
+
|
| 35 |
+
kind: tt-dit-server
|
| 36 |
+
arch: blackhole
|
| 37 |
+
|
| 38 |
+
source:
|
| 39 |
+
# Clean shared clone of tt-metal main 668c2907575 (v0.79.0-dev20260914-1), the commit the port was validated on;
|
| 40 |
+
# git status is empty there, so the card records a clean tree. The image builds tt-metal from this source.
|
| 41 |
+
tt_metal: /home/deepgadget/experiments/gr00t/publish/tt-metal-668c2907575
|
| 42 |
+
# tt-metal-relative files the port imports from the tree OTHER than itself, with their import closure.
|
| 43 |
+
code:
|
| 44 |
+
- models/common/utility_functions.py # models.tt_dit.utils.matmul imports is_blackhole
|
| 45 |
+
- models/tt_dit/utils/matmul.py # tt/layers.py: MinimalMatmul config rows (lazy)
|
| 46 |
+
- models/tt_dit/utils/agmm_rules.py # lazy from matmul.py
|
| 47 |
+
- models/tt_dit/utils/mmrs_rules.py # lazy from matmul.py
|
| 48 |
+
- models/tt_dit/utils/tensor.py # layers/linear.py, layers/module.py, lora.py, parallel/manager.py
|
| 49 |
+
- models/tt_dit/utils/progress.py # layers/module.py
|
| 50 |
+
- models/tt_dit/utils/walltime.py # utils/progress.py
|
| 51 |
+
- models/tt_dit/utils/substate.py # layers/module.py
|
| 52 |
+
- models/tt_dit/layers/linear.py # encoders/qwen3vl/vision_qwen3vl.py (N1.7 tower; lazy, unused at run time here)
|
| 53 |
+
- models/tt_dit/layers/module.py
|
| 54 |
+
- models/tt_dit/layers/normalization.py
|
| 55 |
+
- models/tt_dit/layers/lora.py # imported at the bottom of layers/linear.py
|
| 56 |
+
- models/tt_dit/parallel/config.py
|
| 57 |
+
- models/tt_dit/parallel/manager.py
|
| 58 |
+
- models/tt_dit/encoders/qwen3vl/vision_qwen3vl.py # tt/qwen3vl_vision.py (lazy; N1.7 only)
|
| 59 |
+
- models/demos/deepseek_v3_b1/unified_kernel_descriptor.py # tt/megakernel/descriptors.py (lazy; Stage-2 work, not served)
|
| 60 |
+
# This repo's own code (lands at /opt/tt-metal/<path>; PYTHONPATH=/opt/tt-metal).
|
| 61 |
+
extra_code:
|
| 62 |
+
- root: code
|
| 63 |
+
paths:
|
| 64 |
+
- models # code/models/experimental/gr00t: the frozen snapshot of the port (tt-metal commit 5dc0517e, parent 668c2907575)
|
| 65 |
+
- gr00t_p150 # FastAPI server, schemas, smoke test, demo observation, vendored Qwen2 tokenizer files (n16)
|
| 66 |
+
- scripts # download_weights.sh, bench_http.py
|
| 67 |
+
ubuntu: "22.04"
|
| 68 |
+
python: "3.12"
|
| 69 |
+
|
| 70 |
+
runtime:
|
| 71 |
+
app: gr00t_p150.server.app:app
|
| 72 |
+
mesh_shape_env: TT_MESH_SHAPE
|
| 73 |
+
# On top of the kind defaults (fastapi, uvicorn, pydantic>=2, pillow), torch==2.11.0+cpu (auto-pinned from the tree's
|
| 74 |
+
# tt_metal/python_env/requirements-dev.txt) and ttnn's own deps. Every third-party module on the serve path, pinned
|
| 75 |
+
# where the tree pins it. Resolved on Python 3.12 with uv (dry-run 2026-09-15): numpy 1.26.4, transformers 5.12.1,
|
| 76 |
+
# opencv-python-headless 4.8.1.78, safetensors 0.8.0, huggingface_hub 1.31.0, loguru 0.7.3, torch 2.11.0+cpu.
|
| 77 |
+
# No torchvision: the N1.6 image chain is cv2 + PIL (torchvision is only on the N1.5 path).
|
| 78 |
+
packages:
|
| 79 |
+
- "numpy>=1.24.4,<2"
|
| 80 |
+
- safetensors # common/checkpoint.py (module level)
|
| 81 |
+
- huggingface_hub # server: snapshot_download(revision=..., local_files_only=True) first
|
| 82 |
+
- transformers==5.12.1 # common/prompts.get_tokenizer (AutoTokenizer, lazy); tree pin
|
| 83 |
+
- opencv-python-headless==4.8.1.78 # common/preprocessing.py imports cv2 at module level; tree pin (cp312 wheel exists)
|
| 84 |
+
- loguru # models/common/utility_functions.py (via models.tt_dit.utils.matmul)
|
| 85 |
+
|
| 86 |
+
serve:
|
| 87 |
+
port: 20000
|
| 88 |
+
hardware: p150
|
| 89 |
+
mesh_device: P150
|
| 90 |
+
env:
|
| 91 |
+
TT_WEIGHTS_REVISION: "d0814e7ecb19202e7c8468b46098b0b7ef3a6d61" # == weights.revision == configs.HF_SNAPSHOT_SHAS["n16"]
|
| 92 |
+
TT_METAL_VISIBLE_DEVICES: "0"
|
| 93 |
+
TT_DEVICE_ID: "0"
|
| 94 |
+
GR00T_VERSION: "n16" # the server code is shared with GR00T-N1.5-3B-p150 and never guesses
|
| 95 |
+
GR00T_EMBODIMENT: "gr1" # GR1 arms + hands + waist, embodiment slot 20; the only device-validated layout
|
| 96 |
+
GR00T_LAYOUT: "gr1" # static layout: 1 camera x 81 image tokens, L_max 24 text tokens, S_pad 128
|
| 97 |
+
GR00T_POLICY: "mixed_dit" # TTPolicy.dtype_policy: DiT matmul weights bfp8_b, everything else bf16 (validated Stage-1 default)
|
| 98 |
+
GR00T_TRACE_LAYOUT: "per_stage" # four Metal traces: vision / llm / adapter / denoise (the benchmarked layout)
|
| 99 |
+
GR00T_TOKENIZER_DIR: "/opt/tt-metal/gr00t_p150/assets/tokenizer/n16" # vendored Qwen2 tokenizer files (not in the weights repo)
|
| 100 |
+
GR00T_PROJECT_ROOT: "/nonexistent" # kill the dev-box default the port's prompts.py would otherwise fall back to
|
| 101 |
+
GR00T_GOLDEN_ROOT: "/nonexistent" # same for common/golden.py (tests only; defensive)
|
| 102 |
+
GR00T_TT_CACHE: "/weight-cache/gr00t-tt" # host .pt plan tier + .tensorbin device tier (~8 GB) -> ~/.cache/tt-model/gr00t-n1.6-3b-p150/weights
|
| 103 |
+
GR00T_WARMUP_RUNS: "3" # traced predict() calls after trace capture, before READY
|
| 104 |
+
GR00T_WARMUP_PCC_MIN: "0.999" # boot FAILS when the warm-up actions' PCC vs the shipped fp32 golden is below this
|
| 105 |
+
|
| 106 |
+
# Build-time assertions, run INSIDE the finished image as uid 1000, no device, no weights, no HF_MODEL.
|
| 107 |
+
verify:
|
| 108 |
+
- "import gr00t_p150.server.app as a; assert a.app"
|
| 109 |
+
- "import sys, gr00t_p150.server.app; assert 'ttnn' not in sys.modules and not any(m.startswith('models.experimental.gr00t') for m in sys.modules), 'the server module must import without side effects'"
|
| 110 |
+
- "import models.experimental.gr00t.tt.model as m; assert m.Gr00tTT"
|
| 111 |
+
- "from models.experimental.gr00t.common import configs, preprocessing, normalization, prompts, checkpoint, weights; assert configs.HF_SNAPSHOT_SHAS['n16'] == 'd0814e7ecb19202e7c8468b46098b0b7ef3a6d61' and configs.HF_REPOS['n16'] == 'nvidia/GR00T-N1.6-3B'"
|
| 112 |
+
- "import models.tt_dit.utils.matmul as mm; assert mm.get_matmul_config"
|
| 113 |
+
- "import models.demos.deepseek_v3_b1.unified_kernel_descriptor as u; assert u.UnifiedKernelDescriptor"
|
| 114 |
+
- "import safetensors, huggingface_hub, cv2, numpy, PIL, loguru; assert int(numpy.__version__.split('.')[0]) < 2, numpy.__version__; assert cv2.__version__ == '4.8.1', cv2.__version__"
|
| 115 |
+
- "import transformers; assert transformers.__version__ == '5.12.1', transformers.__version__"
|
| 116 |
+
- "from pathlib import Path; d = Path('/opt/tt-metal/gr00t_p150/assets/tokenizer/n16'); assert all((d / f).is_file() for f in ('vocab.json', 'merges.txt', 'tokenizer_config.json', 'special_tokens_map.json', 'added_tokens.json')), sorted(p.name for p in d.iterdir())"
|
| 117 |
+
- "import os; os.environ['GR00T_TOKENIZER_DIR_N16'] = '/opt/tt-metal/gr00t_p150/assets/tokenizer/n16'; from models.experimental.gr00t.common.prompts import get_tokenizer; t = get_tokenizer('n16'); assert t.convert_tokens_to_ids('<IMG_CONTEXT>') == 151669 and t.convert_tokens_to_ids('<img>') == 151670 and t.convert_tokens_to_ids('</img>') == 151671"
|
| 118 |
+
- "from pathlib import Path; d = Path('/opt/tt-metal/gr00t_p150/demo/n16'); assert all((d / f).is_file() for f in ('observation.json', 'noise.json', 'expected.json', 'frames/ego_view_bg_crop_pad_res256_freq20_t0.png')), sorted(str(p) for p in d.rglob('*'))"
|
| 119 |
+
- "from gr00t_p150.server.app import load_demo_request; import numpy as np; r = load_demo_request('n16'); assert set(r['images']) == {'ego_view_bg_crop_pad_res256_freq20'} and np.asarray(r['noise']).squeeze().shape == (50, 128)"
|
| 120 |
+
- "from pathlib import Path; assert Path('/opt/tt-metal/models/experimental/gr00t/common/golden_tap_map.json').is_file() and Path('/opt/tt-metal/models/experimental/gr00t/tests/tt/gates/gates_multi.json').is_file()"
|
| 121 |
+
- "from pathlib import Path; assert Path('/opt/tt-metal/gr00t_p150/server/smoke_test.py').is_file() and Path('/opt/tt-metal/scripts/bench_http.py').is_file() and Path('/opt/tt-metal/scripts/download_weights.sh').is_file()"
|
| 122 |
+
- "import ttnn; assert all(hasattr(ttnn, a) for a in ('begin_trace_capture', 'end_trace_capture', 'execute_trace', 'release_trace', 'copy_host_to_device_tensor', 'MinimalMatmulConfig'))"
|
| 123 |
+
- "from gr00t_p150.server.app import parse_mesh_shape as p; assert p('1x1') == p('(1, 1)') == p('1,1') == (1, 1)"
|
| 124 |
+
|
| 125 |
+
card:
|
| 126 |
+
description: >
|
| 127 |
+
NVIDIA Isaac GR00T N1.6 (3B vision-language-action policy: SigLIP2 ViT (252², 81 tokens per image) → 16-layer
|
| 128 |
+
Qwen3-1.7B backbone → 32-block alternating cross/self-attention AdaLN DiT, 4 Euler flow-matching steps) running on
|
| 129 |
+
one Tenstorrent Blackhole p150a via tt-nn: one camera frame + proprioceptive state + a task instruction in, a
|
| 130 |
+
16-step chunk of GR1 arm / hand / waist actions out. Stage-1 release: every op is a TTNN op replayed from four
|
| 131 |
+
Metal traces (DiT matmul weights bfp8, everything else bf16); the persistent-megakernel denoise is in progress and
|
| 132 |
+
is not in this image.
|
| 133 |
+
|
| 134 |
+
Weights: [nvidia/GR00T-N1.6-3B](https://huggingface.co/nvidia/GR00T-N1.6-3B) ·
|
| 135 |
+
Paper: [arXiv:2503.14734](https://arxiv.org/abs/2503.14734) (GR00T N1 report) ·
|
| 136 |
+
Project page: [research.nvidia.com/labs/gear/gr00t-n1_6](https://research.nvidia.com/labs/gear/gr00t-n1_6/) ·
|
| 137 |
+
Upstream code: [NVIDIA/Isaac-GR00T](https://github.com/NVIDIA/Isaac-GR00T) (`n1.6.1-release`) ·
|
| 138 |
+
Port: `code/models/experimental/gr00t` in this repo (tt-metal `models/experimental/gr00t`, snapshot `5dc0517e`) + `code/gr00t_p150` (server)
|
| 139 |
+
quickstart: |
|
| 140 |
+
### Run with tt-cli
|
| 141 |
+
|
| 142 |
+
```bash
|
| 143 |
+
tt serve changh95/GR00T-N1.6-3B-p150
|
| 144 |
+
python - <<'EOF'
|
| 145 |
+
import base64, json
|
| 146 |
+
obs = json.load(open("media/demo_observation.json")) # GR1 PickNPlace demo step: raw state + instruction
|
| 147 |
+
obs["images"] = {"ego_view_bg_crop_pad_res256_freq20": base64.b64encode(open("media/demo_ego_view.png", "rb").read()).decode()}
|
| 148 |
+
json.dump(obs, open("req.json", "w"))
|
| 149 |
+
EOF
|
| 150 |
+
curl -s localhost:20000/predict -H 'Content-Type: application/json' -d @req.json
|
| 151 |
+
tt model stop changh95/GR00T-N1.6-3B-p150
|
| 152 |
+
```
|
| 153 |
+
|
| 154 |
+
- `POST /predict`: `images` (`{camera key: base64 PNG/JPEG}` — exactly one camera, `ego_view_bg_crop_pad_res256_freq20`, for the GR1 embodiment; any size, letterboxed / cropped / resized to 252×252 server-side by the reference eval chain), `state` (`{group: [floats]}`: `left_arm` 7, `right_arm` 7, `left_hand` 6, `right_hand` 6, `waist` 3 — raw joint values), `instruction` (task text, ≤ 24 BPE tokens in this layout); optional `embodiment` (`gr1`, the only layout in this image), `seed` (initial flow-matching noise; default = the deployed policy's fixed seed 42 → deterministic), `noise` (explicit `[50, 128]` initial noise), `state_dtype` (`float32` default), `return_normalized`.
|
| 155 |
+
- `GET /health`, `GET /info` (full contract, device facts, warm-up fidelity), `GET /demo` (the shipped demo request + its golden actions).
|
| 156 |
+
|
| 157 |
+
### Response
|
| 158 |
+
|
| 159 |
+
```json
|
| 160 |
+
{"actions": {"left_arm": [[-0.0289, 0.1453, 0.0224, -2.1383, -0.0165, -0.0260, -0.0414], "... 16 steps × 7"],
|
| 161 |
+
"right_arm": [[-0.0024, -0.1502, 0.0280, -2.1461, -0.0091, 0.0132, 0.0044], "..."],
|
| 162 |
+
"left_hand": [[0.0097, -0.0177, 0.0041, 0.0078, 0.0539, 0.0281], "..."],
|
| 163 |
+
"right_hand": [[-0.2339, -0.2466, -0.2431, -0.2311, -0.2423, 0.3333], "..."],
|
| 164 |
+
"waist": [[-0.0010, -0.0060, 0.0008], "..."]},
|
| 165 |
+
"action_horizon": 16, "action_keys": ["left_arm", "right_arm", "left_hand", "right_hand", "waist"],
|
| 166 |
+
"action_dims": {"left_arm": 7, "right_arm": 7, "left_hand": 6, "right_hand": 6, "waist": 3},
|
| 167 |
+
"normalized": false, "embodiment": "gr1", "embodiment_id": 20, "version": "n16", "model": "GR00T-N1.6-3B-p150", "layout": "gr1",
|
| 168 |
+
"images": {"ego_view_bg_crop_pad_res256_freq20": {"frames": 1, "received_hw": [256, 256]}}, "seq_len": 116, "prompt_tokens": 12,
|
| 169 |
+
"state_dtype": "float32", "noise_source": "seed", "seed": 42,
|
| 170 |
+
"timing_ms": {"decode": 0.8, "encode": 1.5, "device": 56.5, "decode_actions": 0.1, "total": 58.9}}
|
| 171 |
+
```
|
| 172 |
+
|
| 173 |
+
- `actions` are **physical, un-normalised** joint targets, 16 steps × [7, 7, 6, 6, 3] dims, exactly what `Gr00tPolicy.get_action` returns for the GR1 data config: the arm and hand groups are the checkpoint's RELATIVE outputs already composed onto the request's `state` (per-step min/max un-normalisation + the raw last state, clipped), `waist` is absolute. `seq_len` is the LLM prompt length the request produced (116 for the demo; padded to 128 on device).
|
| 174 |
+
- `timing_ms`: `decode` = base64 + PNG decode + validation, `encode` = the port's host preprocessing (image chain, prompt + tokenizer, sin/cos state), `device` = input upload + the four trace replays + one blocking readback, `decode_actions` = un-normalisation, `total` = handler wall time.
|
| 175 |
+
|
| 176 |
+
### Demo
|
| 177 |
+
|
| 178 |
+
| Input (`media/demo_ego_view.png`, GR1 sim PickNPlace, 256×256) | Instruction |
|
| 179 |
+
|:---:|:---|
|
| 180 |
+
|  | `pick the pear from the counter and place it in the plate` |
|
| 181 |
+
|
| 182 |
+
Served action chunk vs the fp32 reference for this observation (same initial noise), one panel per action dimension: `media/demo_actions_vs_golden.png`.
|
| 183 |
+
|
| 184 |
+

|
| 185 |
+
|
| 186 |
+
### Accuracy and speed
|
| 187 |
+
|
| 188 |
+
| Metric | Value |
|
| 189 |
+
|---|---:|
|
| 190 |
+
| Action-chunk PCC vs the fp32 golden (official `Gr00tPolicy` code on CPU, same observation, same noise) | `left_arm` 0.99995 (gate 0.9999) · `right_arm` 0.99991 (0.9998) · `right_hand` 0.99312 (0.99); `left_hand` 0.801 and `waist` 0.772 reported-only (near-constant groups, golden range < 0.25 — max\|d\| 0.059 / 0.017 within tolerance); all 29 action dims concatenated **0.999209**, `action_pred_valid` 0.99921 (gate 0.998) |
|
| 191 |
+
| Intermediate taps vs golden (45 canonical taps, untraced, from pixels) | **52 of 56 gated rows pass; 4 marginal misses** (57 of 61 rows incl. the determinism row and the four xfail info rows), all on DiT state-token row 0 (which no action reads): `dit_out[k=1]` 0.999556 vs gate 0.99961, `dit_out[k=2]` 0.999496 vs 0.99964, `action_decoder_out[k=1]` 0.999579 vs 0.9997, `action_decoder_out[k=2]` 0.999556 vs 0.99978 (excluding row 0: 0.99984 / 0.99984 / 0.99991 / 0.99992). Root cause: bf16 HiFi2 SigLIP2 tower error propagation (`vit_block_last` 0.99276), not the DiT — `test_tt_action_head` passes on golden inputs |
|
| 192 |
+
| Traced == untraced, determinism, stale state | bit-identical (13/13 rows; 5 replays + 1 traced-after-untraced; A→B→A→B alternation passes) |
|
| 193 |
+
| Inference on p150a, `bench_e2e` (warm, batch 1, one 256² frame → 252², S 116→128, median of 50) | **59.4 ms end-to-end** (p90 60.1) = host encode 2.0 + upload 3.8 + 4 traces 53.3 (vision 11.5 · LLM 9.5 · adapter 2.0 · denoise 30.4) + D2H 0.1 + decode 0.2 |
|
| 194 |
+
| Served over HTTP from this image (container, warm, 50 requests after 5 warm-ups, seed path, quiet host) | **56.8 ms device** (p90 57.3, min 56.5, max 57.6) · **59.4 ms server-side total** incl. PNG decode (p90 59.8) · 61.0 ms client wall on localhost (p90 61.6) |
|
| 195 |
+
| Same policy on an RTX 5090 (same host, NVIDIA's unmodified code, eager PyTorch bf16 + flash-attn 2, batch 1) | `get_action` e2e 63.1 ms (backbone 16.8, action head 36.2) → **p150a 1.06× faster e2e**; with `torch.compile(DiT, max-autotune)` the GPU reaches 33.1 ms (head 13.5) → **GPU 1.8× faster** than this Stage-1 path; NVIDIA's published RTX 5090 numbers: eager 58 ms, compiled 37 ms |
|
| 196 |
+
|
| 197 |
+
### Caveats
|
| 198 |
+
|
| 199 |
+
- **Stage-1 path.** Vision / LLM / adapter / denoise are TTNN ops captured in four Metal traces; DiT block matmul weights are bfp8_b, everything else bf16 (`mixed_dit`). The persistent-megakernel denoise (Stage 2) is at rung K1 — weight streaming measured at 464 GB/s bf16 / 414 GB/s bfp8 over the full 32-block N1.6 weight set — and is **not** in this image.
|
| 200 |
+
- **N1.6 fidelity margin.** The served chunk reproduces the fp32 golden at PCC 0.99921 on the normalised valid slice (NVIDIA's own bf16 GPU run scores 0.99956 there), 2e-4 above the 0.999 boot / smoke gate; the four intermediate-tap misses above are disclosed verbatim. N1.5 (`changh95/GR00T-N1.5-3B-p150`) passes every tap.
|
| 201 |
+
- **One embodiment, one layout.** The image is built for GR1 (`gr1`, embodiment slot 20, one `ego_view_bg_crop_pad_res256_freq20` camera, instruction ≤ 24 BPE tokens → LLM sequence padded to 128); other embodiments / cameras / longer instructions are refused (400). Batch 1; requests are serialised on one lock.
|
| 202 |
+
- **Noise is seeded** (seed 42, as the deployed policy); pass `seed` or `noise` for a different draw. Outputs are the base checkpoint's actions for the GR1 sim data config — a real robot needs NVIDIA's post-training.
|
| 203 |
+
- Not an OpenAI-compatible API; `GET /v1/models` is a stub so the tt-model ready card does not 404.
|
| 204 |
+
- Validated on tt-metal main `668c2907575` (`v0.79.0-dev20260914-1`), single p150a only. First boot converts the checkpoint to device layout and compiles every kernel (137 s cold, see SERVING.md) into `~/.cache/tt-model/gr00t-n1.6-3b-p150/{weights,cache}` (~8 GB); later boots take 13–21 s (13 s with the weight tier still in the host page cache, 21 s an hour later).
|
| 205 |
+
- GPU comparison: RTX 5090 rows (2026-09-14) are NVIDIA's unmodified `Gr00tPolicy` path (`Isaac-GR00T` `n1.6.1-release`, PyTorch eager bf16 + flash-attn 2, `cudnn.benchmark` on, deterministic mode off), medians of 20 timed iterations after 5 warm-ups (`torch.cuda.synchronize()` around every call), GPU otherwise idle; the p150a row is the Stage-1 trace path incl. upload / readback. p150a power was not measured, so no efficiency comparison is made. Full table: [`GPU_COMPARISON.md`](GPU_COMPARISON.md).
|
| 206 |
+
|
| 207 |
+
### Licensing
|
| 208 |
+
|
| 209 |
+
- Weights: [nvidia/GR00T-N1.6-3B](https://huggingface.co/nvidia/GR00T-N1.6-3B), **NVIDIA License** (non-commercial: research or evaluation use only; verbatim copy in [`LICENSE`](LICENSE)). Not redistributed here; fetched into your HF cache by `tt-model serve` / `scripts/download_weights.sh`.
|
| 210 |
+
- Tokenizer files under `code/gr00t_p150/assets/tokenizer/n16/` (Qwen2 BPE + Eagle special tokens) are copied from [NVIDIA/Isaac-GR00T `n1.6.1-release`](https://github.com/NVIDIA/Isaac-GR00T) (`gr00t/model/modules/nvidia/Eagle-Block2A-2B-v2`), whose `LICENSE` is the same NVIDIA License.
|
| 211 |
+
- Port and serving code (`code/models/experimental/gr00t`, `code/gr00t_p150`, `code/scripts`): Apache-2.0 (SPDX headers), © 2026 Tenstorrent; distributed here under the same non-commercial use limitation as the weights (NVIDIA License §3.2). tt-metal (`code/models/common`, `code/models/tt_dit`, `code/models/demos`, and the image): Apache-2.0.
|
| 212 |
+
- Demo frame and state (`media/`, `code/gr00t_p150/demo/n16`): one GR1 PickNPlace step from the Isaac-GR00T demo data; the fp32 / bf16 reference actions shipped beside it were computed with NVIDIA's code on the pinned weights.
|