
Datasets:

daily largest-events refresh
Browse files- README.md +126 -0
- alias_merge.py +242 -0
- chart.svg +1 -0
- data/largest_layoff_events.csv +0 -0
- dataviz.py +270 -0
- hf_largest_events.py +514 -0
README.md
ADDED
|
@@ -0,0 +1,126 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
pretty_name: Largest US layoff events since 1988 - WARN Act notices clustered by employer
|
| 3 |
+
license: cc-by-4.0
|
| 4 |
+
language:
|
| 5 |
+
- en
|
| 6 |
+
task_categories:
|
| 7 |
+
- tabular-classification
|
| 8 |
+
tags:
|
| 9 |
+
- layoffs
|
| 10 |
+
- largest-layoffs
|
| 11 |
+
- biggest-layoffs
|
| 12 |
+
- layoff-events
|
| 13 |
+
- mass-layoffs
|
| 14 |
+
- warn-act
|
| 15 |
+
- warn-notices
|
| 16 |
+
- entity-resolution
|
| 17 |
+
- labor-market
|
| 18 |
+
- corporate-events
|
| 19 |
+
- public-records
|
| 20 |
+
- government-data
|
| 21 |
+
- alternative-data
|
| 22 |
+
- united-states
|
| 23 |
+
- daily-updated
|
| 24 |
+
- tabular
|
| 25 |
+
size_categories:
|
| 26 |
+
- 1K<n<10K
|
| 27 |
+
configs:
|
| 28 |
+
- config_name: default
|
| 29 |
+
data_files:
|
| 30 |
+
- split: train
|
| 31 |
+
path: data/largest_layoff_events.csv
|
| 32 |
+
---
|
| 33 |
+
|
| 34 |
+
# The 1,000 largest US layoff events on record under the WARN Act, 1988-2026
|
| 35 |
+
|
| 36 |
+
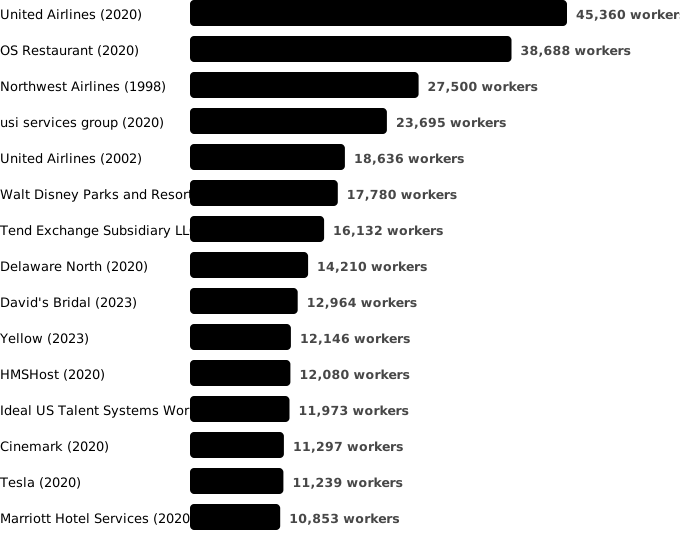
**Rebuilt 2026-09-12. Largest on file: United Airlines, 2020-07-01 to 2020-10-01 — 45,360
|
| 37 |
+
workers across 25 notices in 14 state(s). The table's floor is
|
| 38 |
+
835 workers; 558 of the 1,000 events span more than one notice and
|
| 39 |
+
380 span more than one state.**
|
| 40 |
+
|
| 41 |
+
A state WARN portal lists one row per site per notice. "What was the biggest layoff?" is an
|
| 42 |
+
employer-level question, and answering it takes three steps no portal performs: 48 agencies'
|
| 43 |
+
notices normalized into one schema daily, an employer's many spellings resolved to one name
|
| 44 |
+
(Boeing files under 22 of them, typos included), and its rolling per-site notices clustered into
|
| 45 |
+
one event. This dataset is the result, top 1,000 by reported workers, rebuilt daily.
|
| 46 |
+
|
| 47 |
+

|
| 48 |
+
|
| 49 |
+
## Read this before quoting a rank
|
| 50 |
+
|
| 51 |
+
* **Coverage is uneven before ~2020.** The archive reaches back to 1988 only for the states
|
| 52 |
+
whose portals kept history (Illinois and Oregon among them); most states begin between 2010
|
| 53 |
+
and 2023. `states_covered_in_year` says how many states the archive holds for the event's
|
| 54 |
+
year — an early-year rank is a rank among the states we hold, not the country.
|
| 55 |
+
* **An event is one employer's notices with no gap longer than 45 days between consecutive
|
| 56 |
+
notice dates, and no longer than 183 days end to end.** A rolling programme is one event;
|
| 57 |
+
a later round, or the seventh month of a continuous programme, is a separate event.
|
| 58 |
+
* **`workers_reported` can overstate a rolling programme.** Exact duplicate rows (same state,
|
| 59 |
+
location, count, notice date and effective date) are dropped (`duplicates_dropped`), but successive
|
| 60 |
+
notices for the same site are summed because a portal does not say whether the second is
|
| 61 |
+
cumulative. `sites` is the conservative companion figure.
|
| 62 |
+
* **`single_notice=true` means the whole event is one portal row.** It is only as reliable as
|
| 63 |
+
that row; check it at the source before repeating it.
|
| 64 |
+
* Employer names are resolved by [`alias_merge.py`](https://github.com/APVentureEngine/warn-act-notices/blob/main/product/alias_merge.py)
|
| 65 |
+
(token signature + purity-guarded prefix absorption); the resolver ships in this repo. It
|
| 66 |
+
merges spellings, not corporate parents: subsidiaries filing under their own names are their
|
| 67 |
+
own employers.
|
| 68 |
+
* The current year is a running total; `event_open=true` marks events that may still grow.
|
| 69 |
+
|
| 70 |
+
## Top 20 right now
|
| 71 |
+
|
| 72 |
+
| # | employer | period | workers | notices | states |
|
| 73 |
+
|---|---|---|---|---|---|
|
| 74 |
+
| 1 | United Airlines | 2020-07-01 to 2020-10-01 | 45,360 | 25 | CA;CO;FL;HI;IL;IN;MN;NJ;NV;NY;OH;PA;VA;WA |
|
| 75 |
+
| 2 | OS Restaurant | 2020-03-15 to 2020-05-15 | 38,688 | 128 | CA;FL;IN;KS;MD;MO;NC;NY;OH;PA;SC;TN |
|
| 76 |
+
| 3 | Northwest Airlines | 1998-08-11 to 1998-08-11 | 27,500 | 1 | OR |
|
| 77 |
+
| 4 | usi services group | 2020-03-01 to 2020-03-01 | 23,695 | 1 | NJ |
|
| 78 |
+
| 5 | United Airlines | 2002-12-30 to 2002-12-30 | 18,636 | 2 | IL |
|
| 79 |
+
| 6 | Walt Disney Parks and Resorts U.S | 2020-09-30 to 2020-11-18 | 17,780 | 19 | CA;FL |
|
| 80 |
+
| 7 | Tend Exchange Subsidiary LLC and Delaware Tender Staffing | 2025-05-20 to 2025-05-20 | 16,132 | 1 | CA |
|
| 81 |
+
| 8 | Delaware North | 2020-06-04 to 2020-07-28 | 14,210 | 32 | CA;CO;FL;MD;MI;MO;NY;OH;OK;SC;TN;VA;WI |
|
| 82 |
+
| 9 | David's Bridal | 2023-04-14 to 2023-08-11 | 12,964 | 78 | AK;AL;CA;CO;CT;GA;MA;ME;MN;MO;NC;NE;NJ;NM;NV;NY;OH;OR;TN;TX;WA;WI |
|
| 83 |
+
| 10 | Yellow | 2023-07-30 to 2023-08-18 | 12,146 | 73 | AL;AZ;CA;CO;DC;FL;ID;IL;IN;KS;ME;MI;MN;NC;ND;NM;NV;NY;OH;TX;VA;WA;WI |
|
| 84 |
+
| 11 | HMSHost | 2020-03-20 to 2020-08-18 | 12,080 | 78 | AK;CA;CO;DE;FL;HI;IL;MI;MO;NC;NJ;NV;NY;OH;OR;TN;WA |
|
| 85 |
+
| 12 | Ideal US Talent Systems Worker OpCo | 2026-05-04 to 2026-05-29 | 11,973 | 3 | GA;IL;RI |
|
| 86 |
+
| 13 | Cinemark | 2020-03-26 to 2020-04-17 | 11,297 | 140 | AZ;CA;CT;ID;IL;IN;KS;MD;MI;MT;NC;NV;NY;OH;PA;SC;TN;TX;UT;VA;WA;WI |
|
| 87 |
+
| 14 | Tesla | 2020-05-12 to 2020-05-12 | 11,239 | 2 | CA |
|
| 88 |
+
| 15 | Marriott Hotel Services | 2020-03-13 to 2020-06-11 | 10,853 | 32 | CA;CT;FL;NY;PA;TN;VA;WA |
|
| 89 |
+
| 16 | Great Atlantic and Pacific Tea | 2015-07-01 to 2015-11-12 | 10,039 | 102 | CT;NJ;PA |
|
| 90 |
+
| 17 | American Airlines | 2020-07-15 to 2020-07-29 | 10,013 | 15 | CA;CO;IL;NC;NY;OK;WA |
|
| 91 |
+
| 18 | Aramark | 2020-07-31 to 2020-11-18 | 9,977 | 50 | CA;CO;DC;DE;FL;IL;IN;MD;MI;MO;NJ;NV;NY;OH;OK;PA;TX;WA;WI |
|
| 92 |
+
| 19 | Hyatt Regency | 2020-03-21 to 2020-07-08 | 9,477 | 49 | CA;CO;DC;FL;HI;IL;MD;MN;NY;OH;OR;TX;VA;WI |
|
| 93 |
+
| 20 | Boeing | 2020-06-08 to 2020-10-19 | 8,783 | 12 | CA;WA |
|
| 94 |
+
|
| 95 |
+
## Columns
|
| 96 |
+
|
| 97 |
+
| column | meaning |
|
| 98 |
+
|---|---|
|
| 99 |
+
| `rank` | position by `workers_reported` (ties: earlier start first) |
|
| 100 |
+
| `employer` | most frequent canonical spelling inside the event |
|
| 101 |
+
| `event_start`, `event_end`, `year` | first and last notice date; `year` is the start year |
|
| 102 |
+
| `workers_reported` | sum of `employees_affected` over the event's de-duplicated notices |
|
| 103 |
+
| `notices`, `notices_with_worker_count` | notices in the event; how many carried a count |
|
| 104 |
+
| `sites` | distinct state + location pairs |
|
| 105 |
+
| `states`, `states_count` | semicolon-separated state codes |
|
| 106 |
+
| `largest_single_notice`, `largest_notice_state`, `largest_notice_location` | the biggest single filing inside the event |
|
| 107 |
+
| `notice_types` | distinct raw `notice_type` strings, as the portals wrote them |
|
| 108 |
+
| `single_notice` | `true` when the event is a single filing |
|
| 109 |
+
| `event_open` | `true` when the last notice is within 45 days of the rebuild date |
|
| 110 |
+
| `duplicates_dropped` | exact duplicate portal rows removed before summing |
|
| 111 |
+
| `states_covered_in_year` | states with any notice in the archive for `year` |
|
| 112 |
+
| `employer_page` | the employer's history page on the site, when one exists |
|
| 113 |
+
| `notice_ids` | semicolon-separated ids joining to the flagship notices CSV |
|
| 114 |
+
|
| 115 |
+
## Where the rows come from
|
| 116 |
+
|
| 117 |
+
The free, CC BY 4.0 [normalized WARN archive](https://huggingface.co/datasets/APProjects/us-warn-act-layoffs-notices-daily) rebuilt daily from 48 state portals
|
| 118 |
+
([site](https://approjects-warn-act-notices.static.hf.space), [GitHub](https://github.com/APVentureEngine/warn-act-notices)). Related cuts of the same archive: [employers filing in
|
| 119 |
+
several states](https://huggingface.co/datasets/APProjects/us-multi-state-layoffs-employers-warn-act) and [layoffs per capita by state](https://huggingface.co/datasets/APProjects/us-layoffs-per-capita-by-state-warn-act).
|
| 120 |
+
|
| 121 |
+
Get told the day an employer on your list files, in any of the 48 states: [free 30-day
|
| 122 |
+
watch](https://approj.gumroad.com/l/warn-free-watch) (no card) or [WARN Watch, $49/year](https://approj.gumroad.com/l/warn-watch) for a list of up to 500
|
| 123 |
+
employers.
|
| 124 |
+
|
| 125 |
+
*Automated publisher (APProjects). Not affiliated with any government agency. Verify critical
|
| 126 |
+
figures against the state source linked from each notice.*
|
alias_merge.py
ADDED
|
@@ -0,0 +1,242 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""alias_merge.py — group fragmented employer spellings into one history key.
|
| 3 |
+
|
| 4 |
+
WHY THIS EXISTS (c307, 2026-09-11). The paid product's headline feature is
|
| 5 |
+
"hand us your list; day one every name is scored against the 1988-present
|
| 6 |
+
archive". That report, the per-employer public pages, and the `history` line
|
| 7 |
+
attached to every alert are all built by `warn_watch.dossier_index()`, which
|
| 8 |
+
keys on the EXACT lowercased `company_canonical` string. The alert MATCHER,
|
| 9 |
+
by contrast, uses token-subset matching (`warn_watch.notice_matches`).
|
| 10 |
+
|
| 11 |
+
Those two disagree, and the disagreement is worst exactly where it hurts most:
|
| 12 |
+
|
| 13 |
+
Boeing files under 22 distinct spellings in the archive, including the
|
| 14 |
+
typos 'Boeing Compnay' and 'Thte Boeing Company'. A buyer watching
|
| 15 |
+
"Boeing" DOES get an alert when 'Boeing - El Paso' files (token subset),
|
| 16 |
+
but the history line on that alert looks up the key 'boeing - el paso'
|
| 17 |
+
and reports "2 prior notices" when the truth is 420 across 13 states.
|
| 18 |
+
|
| 19 |
+
Measured on the 59,134-row archive (c307):
|
| 20 |
+
- 34,154 distinct canonical keys.
|
| 21 |
+
- Tier 1 (stopword/punctuation only): 415 groups, 467 keys, 663 notices.
|
| 22 |
+
- Tier 2 (prefix absorption, purity >= 0.90): 4,615 keys, 7,238 notices.
|
| 23 |
+
=> ~7,900 notices (13% of the archive) gain a materially fuller history.
|
| 24 |
+
|
| 25 |
+
THE OVER-MERGE HAZARD, AND THE GUARD. Naive prefix absorption folds
|
| 26 |
+
'venture stores' into 'venture' and 'marriott international' into 'marriott',
|
| 27 |
+
which would attribute unrelated companies to each other ON PUBLIC PAGES --
|
| 28 |
+
strictly worse than under-counting, because it looks like evidence. The guard
|
| 29 |
+
is token PURITY: for a single-token parent P, the share of distinct canonical
|
| 30 |
+
keys containing token P that actually START with P.
|
| 31 |
+
|
| 32 |
+
boeing 0.93 verizon 0.94 ames 1.00 -> merged
|
| 33 |
+
meta 0.86 united 0.83 compass 0.78 -> blocked
|
| 34 |
+
sears 0.76 novartis 0.69 general 0.63 -> blocked
|
| 35 |
+
marriott 0.47 venture 0.21 -> blocked
|
| 36 |
+
|
| 37 |
+
At PURITY_MIN = 0.90 the rule deliberately UNDER-merges (it blocks the
|
| 38 |
+
genuinely-correct 'cvs health' -> 'cvs'). That asymmetry is intentional: a
|
| 39 |
+
missed merge under-reports a history, a false merge publishes a lie.
|
| 40 |
+
|
| 41 |
+
Multi-token parents ('thermo fisher', 'general dynamics', 'p f chang s') are
|
| 42 |
+
not purity-gated -- two or more tokens matching in order is already strong
|
| 43 |
+
evidence, and no false merge was found among them by inspection.
|
| 44 |
+
|
| 45 |
+
USAGE
|
| 46 |
+
python3 alias_merge.py --selftest # assert the known good/bad cases
|
| 47 |
+
python3 alias_merge.py --report # impact summary + examples
|
| 48 |
+
from alias_merge import build_alias_map
|
| 49 |
+
amap = build_alias_map(rows) # exact canonical (lower) -> group key
|
| 50 |
+
|
| 51 |
+
NOT YET WIRED INTO publish.sh. See BACKLOG 0-ALIAS-MERGE.
|
| 52 |
+
"""
|
| 53 |
+
|
| 54 |
+
import collections
|
| 55 |
+
import csv
|
| 56 |
+
import re
|
| 57 |
+
import sys
|
| 58 |
+
|
| 59 |
+
FULL_CSV = "out/full/warn_notices.csv"
|
| 60 |
+
|
| 61 |
+
STOP = {"inc", "llc", "corp", "corporation", "co", "company", "ltd", "the",
|
| 62 |
+
"of", "and", "incorporated", "lp", "llp", "plc"}
|
| 63 |
+
|
| 64 |
+
PURITY_MIN = 0.90 # single-token parents below this are never used
|
| 65 |
+
PARENT_MIN_NOTICES = 3 # a parent must itself be a real, repeatedly-filing employer
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
def tokens(s):
|
| 69 |
+
"""Same tokenizer as warn_watch.tokens -- keep these two in step."""
|
| 70 |
+
return [t for t in re.split(r"[^a-z0-9]+", str(s or "").lower()) if t]
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
def norm_sig(s):
|
| 74 |
+
"""Normalized token signature: lowercase, punctuation-free, stopwords dropped."""
|
| 75 |
+
return tuple(t for t in tokens(s) if t not in STOP)
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
def canon_of(row):
|
| 79 |
+
return (row.get("company_canonical") or row.get("company") or "").strip().lower()
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
def build_alias_map(rows, purity_min=PURITY_MIN, parent_min=PARENT_MIN_NOTICES):
|
| 83 |
+
"""exact lowercased canonical -> group key (also a lowercased canonical).
|
| 84 |
+
|
| 85 |
+
Identity entries are omitted; callers should treat a missing key as
|
| 86 |
+
'maps to itself'. Deterministic: no dict-ordering dependence.
|
| 87 |
+
"""
|
| 88 |
+
counts = collections.Counter()
|
| 89 |
+
for r in rows:
|
| 90 |
+
c = canon_of(r)
|
| 91 |
+
if c:
|
| 92 |
+
counts[c] += 1
|
| 93 |
+
|
| 94 |
+
# signature -> [canonical keys], and signature total notice count
|
| 95 |
+
by_sig = collections.defaultdict(list)
|
| 96 |
+
for k in counts:
|
| 97 |
+
by_sig[norm_sig(k)].append(k)
|
| 98 |
+
sig_total = {s: sum(counts[k] for k in ks) for s, ks in by_sig.items() if s}
|
| 99 |
+
|
| 100 |
+
# token -> distinct signatures containing it (for the purity guard)
|
| 101 |
+
tok2sigs = collections.defaultdict(set)
|
| 102 |
+
for s in sig_total:
|
| 103 |
+
for t in set(s):
|
| 104 |
+
tok2sigs[t].add(s)
|
| 105 |
+
|
| 106 |
+
parents = {s for s, n in sig_total.items() if n >= parent_min}
|
| 107 |
+
|
| 108 |
+
def purity(p):
|
| 109 |
+
if len(p) != 1:
|
| 110 |
+
return 1.0
|
| 111 |
+
sigs = tok2sigs.get(p[0]) or ()
|
| 112 |
+
if not sigs:
|
| 113 |
+
return 0.0
|
| 114 |
+
return sum(1 for s in sigs if s[:1] == p) / len(sigs)
|
| 115 |
+
|
| 116 |
+
# Tier 1: every key in a signature group collapses onto that group's
|
| 117 |
+
# highest-volume key (ties broken by the shorter, then lexically first name).
|
| 118 |
+
def rep_of(keys):
|
| 119 |
+
return sorted(keys, key=lambda k: (-counts[k], len(k), k))[0]
|
| 120 |
+
|
| 121 |
+
sig_rep = {s: rep_of(ks) for s, ks in by_sig.items() if s}
|
| 122 |
+
|
| 123 |
+
# Tier 2: a signature absorbs into its SHORTEST existing parent prefix.
|
| 124 |
+
absorb = {}
|
| 125 |
+
for s in sig_total:
|
| 126 |
+
for L in range(1, len(s)):
|
| 127 |
+
p = s[:L]
|
| 128 |
+
if p in parents and p != s and purity(p) >= purity_min:
|
| 129 |
+
absorb[s] = p
|
| 130 |
+
break
|
| 131 |
+
|
| 132 |
+
# Resolve prefix chains (a -> b -> c) to their terminal parent.
|
| 133 |
+
def resolve(s, _seen=None):
|
| 134 |
+
_seen = _seen or set()
|
| 135 |
+
while s in absorb and s not in _seen:
|
| 136 |
+
_seen.add(s)
|
| 137 |
+
s = absorb[s]
|
| 138 |
+
return s
|
| 139 |
+
|
| 140 |
+
amap = {}
|
| 141 |
+
for s, ks in by_sig.items():
|
| 142 |
+
if not s:
|
| 143 |
+
continue
|
| 144 |
+
target = sig_rep[resolve(s)]
|
| 145 |
+
for k in ks:
|
| 146 |
+
if k != target:
|
| 147 |
+
amap[k] = target
|
| 148 |
+
return amap
|
| 149 |
+
|
| 150 |
+
|
| 151 |
+
def load_rows(path=FULL_CSV):
|
| 152 |
+
with open(path, newline="", encoding="utf-8", errors="replace") as f:
|
| 153 |
+
return list(csv.DictReader(f))
|
| 154 |
+
|
| 155 |
+
|
| 156 |
+
# --------------------------------------------------------------------------
|
| 157 |
+
# selftest: the cases that justified the design. If these ever flip, the
|
| 158 |
+
# tokenizer, the purity guard or the archive changed -- investigate, do not
|
| 159 |
+
# "fix" the assertion.
|
| 160 |
+
# --------------------------------------------------------------------------
|
| 161 |
+
MUST_MERGE = [ # (child spelling, expected group token)
|
| 162 |
+
("boeing - el paso", "boeing"),
|
| 163 |
+
("boeing compnay", "boeing"),
|
| 164 |
+
("boeing commercial airplane group", "boeing"),
|
| 165 |
+
("boeing company - oregon location", "boeing"),
|
| 166 |
+
]
|
| 167 |
+
MUST_NOT_MERGE = [ # over-merge hazards: must stay separate
|
| 168 |
+
("venture stores", "venture"),
|
| 169 |
+
("marriott international", "marriott"),
|
| 170 |
+
("compass group", "compass"),
|
| 171 |
+
("sears holdings", "sears"),
|
| 172 |
+
]
|
| 173 |
+
|
| 174 |
+
|
| 175 |
+
def selftest():
|
| 176 |
+
rows = load_rows()
|
| 177 |
+
amap = build_alias_map(rows)
|
| 178 |
+
ok = True
|
| 179 |
+
|
| 180 |
+
for child, parent_tok in MUST_MERGE:
|
| 181 |
+
got = amap.get(child, child)
|
| 182 |
+
if norm_sig(got) != (parent_tok,):
|
| 183 |
+
print("FAIL merge: %r -> %r (wanted group %r)" % (child, got, parent_tok))
|
| 184 |
+
ok = False
|
| 185 |
+
|
| 186 |
+
for child, parent_tok in MUST_NOT_MERGE:
|
| 187 |
+
got = amap.get(child, child)
|
| 188 |
+
if norm_sig(got) == (parent_tok,):
|
| 189 |
+
print("FAIL over-merge: %r was folded into %r" % (child, parent_tok))
|
| 190 |
+
ok = False
|
| 191 |
+
|
| 192 |
+
# No key may map to itself, and every target must be a real canonical.
|
| 193 |
+
canon = {canon_of(r) for r in rows}
|
| 194 |
+
for k, v in amap.items():
|
| 195 |
+
if k == v:
|
| 196 |
+
print("FAIL identity entry: %r" % k); ok = False; break
|
| 197 |
+
if v not in canon:
|
| 198 |
+
print("FAIL target not a real employer: %r -> %r" % (k, v)); ok = False; break
|
| 199 |
+
|
| 200 |
+
# Boeing's grouped history must beat the ungrouped one.
|
| 201 |
+
grouped = collections.Counter()
|
| 202 |
+
for r in rows:
|
| 203 |
+
c = canon_of(r)
|
| 204 |
+
if c:
|
| 205 |
+
grouped[amap.get(c, c)] += 1
|
| 206 |
+
before = sum(1 for r in rows if canon_of(r) == "boeing")
|
| 207 |
+
after = grouped.get("boeing", 0)
|
| 208 |
+
states = {r.get("state") for r in rows
|
| 209 |
+
if amap.get(canon_of(r), canon_of(r)) == "boeing"}
|
| 210 |
+
print("boeing notices: %d -> %d | states: %d" % (before, after, len(states)))
|
| 211 |
+
if after <= before:
|
| 212 |
+
print("FAIL: grouping did not improve Boeing"); ok = False
|
| 213 |
+
|
| 214 |
+
print("alias_merge selftest:", "PASS" if ok else "FAIL")
|
| 215 |
+
return 0 if ok else 1
|
| 216 |
+
|
| 217 |
+
|
| 218 |
+
def report():
|
| 219 |
+
rows = load_rows()
|
| 220 |
+
amap = build_alias_map(rows)
|
| 221 |
+
canon = collections.Counter(canon_of(r) for r in rows if canon_of(r))
|
| 222 |
+
moved = sum(canon[k] for k in amap)
|
| 223 |
+
groups = collections.defaultdict(list)
|
| 224 |
+
for k, v in amap.items():
|
| 225 |
+
groups[v].append(k)
|
| 226 |
+
print("distinct canonical employers : %d" % len(canon))
|
| 227 |
+
print("keys folded into a group : %d" % len(amap))
|
| 228 |
+
print("notices re-homed : %d (%.1f%% of %d)"
|
| 229 |
+
% (moved, 100.0 * moved / max(1, len(rows)), len(rows)))
|
| 230 |
+
print("employers whose history grows: %d" % len(groups))
|
| 231 |
+
print("\nlargest regrouped employers:")
|
| 232 |
+
for tgt, ks in sorted(groups.items(),
|
| 233 |
+
key=lambda kv: -sum(canon[k] for k in kv[1]))[:12]:
|
| 234 |
+
print(" %-42s +%4d notices from %d spellings"
|
| 235 |
+
% (tgt[:42], sum(canon[k] for k in ks), len(ks)))
|
| 236 |
+
return 0
|
| 237 |
+
|
| 238 |
+
|
| 239 |
+
if __name__ == "__main__":
|
| 240 |
+
if "--selftest" in sys.argv:
|
| 241 |
+
sys.exit(selftest())
|
| 242 |
+
sys.exit(report())
|
chart.svg
ADDED
|
data/largest_layoff_events.csv
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
dataviz.py
ADDED
|
@@ -0,0 +1,270 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Inline-SVG charts from real data, for a venture's static pages.
|
| 2 |
+
|
| 3 |
+
Copy this file into ventures/<slug>/product/ and import it from your site
|
| 4 |
+
generator. Standard library only, like gen_site.py.
|
| 5 |
+
|
| 6 |
+
WHY INLINE SVG AND NOT A CHART LIBRARY. These pages are static files built by a
|
| 7 |
+
Python pipeline and served from GitHub Pages. A CDN chart library would add a
|
| 8 |
+
blocking third-party request, break the reviewer's no-unknown-script rule, show
|
| 9 |
+
nothing until JS runs, and render an empty box for anyone whose script blocked.
|
| 10 |
+
SVG generated at build time has the numbers baked in: it paints instantly, it
|
| 11 |
+
works with JS off, it survives being screenshotted into a post, and the figure
|
| 12 |
+
cannot silently disagree with the dataset because it IS the dataset.
|
| 13 |
+
|
| 14 |
+
WHAT A CHART IS FOR HERE. Not a research paper. A stranger gives the page about
|
| 15 |
+
two seconds. One number, large, that makes the scale of the thing land — then
|
| 16 |
+
the shape of the data underneath it. Accurate AND arresting; the accuracy is
|
| 17 |
+
what makes it arresting, because the numbers are real and specific.
|
| 18 |
+
|
| 19 |
+
Rules baked in so they cannot be forgotten:
|
| 20 |
+
* every mark is DIRECTLY LABELLED — no hover, no legend to decode, and it
|
| 21 |
+
keeps the palette legal for colour-blind readers;
|
| 22 |
+
* one axis, never two scales on one chart;
|
| 23 |
+
* a single series uses the sequential blue ramp; multiple series use a
|
| 24 |
+
validated categorical order, never cycled;
|
| 25 |
+
* text is ink-coloured, never series-coloured — a mark beside it carries
|
| 26 |
+
identity;
|
| 27 |
+
* grid and axes recede;
|
| 28 |
+
* every figure carries a caption naming the source and the date, because an
|
| 29 |
+
unattributed number on a page selling data is worth nothing;
|
| 30 |
+
* dark mode is honoured via prefers-color-scheme.
|
| 31 |
+
|
| 32 |
+
Palette validated with the dataviz palette checker (light and dark): lightness
|
| 33 |
+
band, chroma floor, CVD separation, normal-vision floor, contrast.
|
| 34 |
+
"""
|
| 35 |
+
import html
|
| 36 |
+
import math
|
| 37 |
+
|
| 38 |
+
# Sequential blue, light -> dark. Single-series magnitude uses the 450 step.
|
| 39 |
+
BLUE = {100: "#cde2fb", 200: "#9ec5f4", 300: "#6da7ec",
|
| 40 |
+
400: "#3987e5", 450: "#2a78d6", 550: "#1c5cab", 650: "#104281"}
|
| 41 |
+
# Categorical, in FIXED order. Never cycle; a 4th series means rethink the chart.
|
| 42 |
+
SERIES = ("#2a78d6", "#eb6834", "#1baf7a")
|
| 43 |
+
INK = "#1a1a19"
|
| 44 |
+
INK_DIM = "#5b5b57"
|
| 45 |
+
GRID = "#e6e6e3"
|
| 46 |
+
|
| 47 |
+
# Ink AND surface move together. Setting a dark text colour without a dark
|
| 48 |
+
# ground is how you get invisible numbers on a light page — caught by rendering
|
| 49 |
+
# this, not by reading it. The components carry their own surface so the library
|
| 50 |
+
# is safe to drop into a host page whose background it does not control, and the
|
| 51 |
+
# SVGs use currentColor so their text follows the same token.
|
| 52 |
+
CSS = """
|
| 53 |
+
.dv{
|
| 54 |
+
--dv-ink:%(ink)s; --dv-dim:%(dim)s; --dv-grid:%(grid)s;
|
| 55 |
+
--dv-surface:#fcfcfb; --dv-accent:%(accent)s;
|
| 56 |
+
--dv-line:%(line)s; --dv-area:%(area)s;
|
| 57 |
+
font:14px/1.4 -apple-system,system-ui,"Segoe UI",Roboto,sans-serif;
|
| 58 |
+
color:var(--dv-ink);
|
| 59 |
+
}
|
| 60 |
+
@media (prefers-color-scheme:dark){
|
| 61 |
+
.dv{--dv-ink:#f2f2f0; --dv-dim:#a9a9a4; --dv-grid:#333330;
|
| 62 |
+
--dv-surface:#1a1a19; --dv-accent:%(accent_dark)s;
|
| 63 |
+
/* dark takes its OWN steps from the same ramp, not a flipped light one */
|
| 64 |
+
--dv-line:%(line_dark)s; --dv-area:%(area_dark)s}
|
| 65 |
+
}
|
| 66 |
+
.dv figure{margin:0 0 28px}
|
| 67 |
+
.dv figcaption{margin-top:8px;font-size:12px;color:var(--dv-dim)}
|
| 68 |
+
.dv-kpis{display:grid;grid-template-columns:repeat(auto-fit,minmax(150px,1fr));gap:18px}
|
| 69 |
+
.dv-kpi{
|
| 70 |
+
padding:16px 18px;border:1px solid var(--dv-grid);border-radius:12px;
|
| 71 |
+
background:var(--dv-surface);color:var(--dv-ink);
|
| 72 |
+
}
|
| 73 |
+
.dv-kpi b{display:block;font-size:clamp(1.9rem,5vw,2.9rem);font-weight:800;
|
| 74 |
+
letter-spacing:-.03em;line-height:1;font-variant-numeric:tabular-nums;
|
| 75 |
+
color:var(--dv-ink)}
|
| 76 |
+
.dv-kpi span{display:block;margin-top:7px;font-size:12.5px;color:var(--dv-dim)}
|
| 77 |
+
.dv-kpi i{font-style:normal;font-size:12px;font-weight:700;color:var(--dv-accent)}
|
| 78 |
+
.dv-svg{display:block;max-width:100%%;height:auto;color:var(--dv-ink)}
|
| 79 |
+
.dv table{border-collapse:collapse;font-size:13px;color:var(--dv-ink)}
|
| 80 |
+
.dv th,.dv td{padding:5px 12px 5px 0;text-align:left;
|
| 81 |
+
border-bottom:1px solid var(--dv-grid)}
|
| 82 |
+
""" % {"ink": INK, "dim": INK_DIM, "grid": GRID,
|
| 83 |
+
"accent": BLUE[550], "accent_dark": BLUE[300],
|
| 84 |
+
"line": BLUE[450], "area": BLUE[100],
|
| 85 |
+
"line_dark": BLUE[400], "area_dark": BLUE[650]}
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
def _e(s) -> str:
|
| 89 |
+
return html.escape(str(s), quote=True)
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
def _num(v) -> str:
|
| 93 |
+
"""Thousands separators. A page selling 45,772 records must not print 45772."""
|
| 94 |
+
try:
|
| 95 |
+
f = float(v)
|
| 96 |
+
except (TypeError, ValueError):
|
| 97 |
+
return _e(v)
|
| 98 |
+
return f"{int(round(f)):,}" if abs(f - round(f)) < 1e-9 else f"{f:,.1f}"
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def _require(rows, what: str):
|
| 102 |
+
"""Refuse to draw nothing. A chart of placeholder data is worse than no
|
| 103 |
+
chart: it looks like evidence and is not."""
|
| 104 |
+
if not rows:
|
| 105 |
+
raise ValueError(
|
| 106 |
+
f"{what}: no data. Do not publish an empty or invented chart — "
|
| 107 |
+
"either pass the real rows or leave the figure out.")
|
| 108 |
+
|
| 109 |
+
|
| 110 |
+
def figure(svg: str, caption: str, source: str = "", asof: str = "") -> str:
|
| 111 |
+
bits = [caption]
|
| 112 |
+
if source:
|
| 113 |
+
bits.append(f"Source: {source}")
|
| 114 |
+
if asof:
|
| 115 |
+
bits.append(f"as of {asof}")
|
| 116 |
+
return (f'<figure>{svg}<figcaption>{_e(" · ".join(b for b in bits if b))}'
|
| 117 |
+
f"</figcaption></figure>")
|
| 118 |
+
|
| 119 |
+
|
| 120 |
+
def kpi_row(items) -> str:
|
| 121 |
+
"""The most important form on a landing page: a few real numbers, large.
|
| 122 |
+
|
| 123 |
+
items: [(value, label)] or [(value, label, note)] — note is a short delta
|
| 124 |
+
or qualifier ("last 90 days", "+12% vs Aug").
|
| 125 |
+
"""
|
| 126 |
+
_require(items, "kpi_row")
|
| 127 |
+
out = ['<div class="dv-kpis">']
|
| 128 |
+
for it in items:
|
| 129 |
+
value, label = it[0], it[1]
|
| 130 |
+
note = it[2] if len(it) > 2 else ""
|
| 131 |
+
out.append('<div class="dv-kpi">')
|
| 132 |
+
out.append(f"<b>{_e(_num(value))}</b>")
|
| 133 |
+
out.append(f"<span>{_e(label)}</span>")
|
| 134 |
+
if note:
|
| 135 |
+
out.append(f'<i style="color:{BLUE[550]}">{_e(note)}</i>')
|
| 136 |
+
out.append("</div>")
|
| 137 |
+
out.append("</div>")
|
| 138 |
+
return "".join(out)
|
| 139 |
+
|
| 140 |
+
|
| 141 |
+
def bar_chart(rows, unit: str = "", width: int = 680, bar_h: int = 26,
|
| 142 |
+
gap: int = 10, title: str = "") -> str:
|
| 143 |
+
"""Horizontal bars, sorted, every bar directly labelled.
|
| 144 |
+
|
| 145 |
+
rows: [(label, value)]. Horizontal because real category names are words,
|
| 146 |
+
not three-letter codes, and rotated x-labels are unreadable.
|
| 147 |
+
"""
|
| 148 |
+
_require(rows, "bar_chart")
|
| 149 |
+
rows = [(str(a), float(b)) for a, b in rows]
|
| 150 |
+
rows.sort(key=lambda r: -r[1])
|
| 151 |
+
top = max(v for _, v in rows) or 1.0
|
| 152 |
+
label_w = min(190, max(90, 8 * max(len(a) for a, _ in rows)))
|
| 153 |
+
# Size the value gutter from the widest label that will actually be drawn.
|
| 154 |
+
# A fixed gutter clipped "1,240 notices" to "1,240 notic" — the palette
|
| 155 |
+
# validator cannot see that; only rendering it can.
|
| 156 |
+
longest = max(len(_num(v) + unit) for _, v in rows)
|
| 157 |
+
val_w = max(46, int(longest * 7.1) + 14)
|
| 158 |
+
plot_w = max(80, width - label_w - val_w)
|
| 159 |
+
height = len(rows) * (bar_h + gap) + 8
|
| 160 |
+
|
| 161 |
+
p = [f'<svg class="dv-svg" viewBox="0 0 {width} {height}" width="100%" '
|
| 162 |
+
f'height="{height}" role="img" xmlns="http://www.w3.org/2000/svg" '
|
| 163 |
+
f'aria-label="{_e(title or "bar chart")}">']
|
| 164 |
+
if title:
|
| 165 |
+
p.append(f"<title>{_e(title)}</title>")
|
| 166 |
+
for i, (label, value) in enumerate(rows):
|
| 167 |
+
y = i * (bar_h + gap)
|
| 168 |
+
w = max(2.0, plot_w * (value / top))
|
| 169 |
+
p.append(f'<text x="0" y="{y + bar_h * 0.72:.0f}" font-size="13" '
|
| 170 |
+
f'fill="currentColor">{_e(label)}</text>')
|
| 171 |
+
# 4px rounded data-end, anchored flat to the baseline at x=label_w
|
| 172 |
+
p.append(f'<rect x="{label_w}" y="{y}" width="{w:.1f}" height="{bar_h}" '
|
| 173 |
+
f'rx="4" fill="var(--dv-line)"/>')
|
| 174 |
+
p.append(f'<text x="{label_w + w + 9:.1f}" y="{y + bar_h * 0.72:.0f}" '
|
| 175 |
+
f'font-size="12.5" font-weight="700" fill="currentColor" '
|
| 176 |
+
f'opacity=".72">'
|
| 177 |
+
f'{_e(_num(value))}{_e(unit)}</text>')
|
| 178 |
+
p.append("</svg>")
|
| 179 |
+
return "".join(p)
|
| 180 |
+
|
| 181 |
+
|
| 182 |
+
def trend(points, width: int = 680, height: int = 190, unit: str = "",
|
| 183 |
+
title: str = "") -> str:
|
| 184 |
+
"""One series over time, with the latest value labelled at the end.
|
| 185 |
+
|
| 186 |
+
points: [(label, value)] in chronological order. One axis only — if you
|
| 187 |
+
have two measures, draw two charts.
|
| 188 |
+
"""
|
| 189 |
+
_require(points, "trend")
|
| 190 |
+
vals = [float(v) for _, v in points]
|
| 191 |
+
if len(vals) < 2:
|
| 192 |
+
raise ValueError("trend: needs at least two points to show a trend")
|
| 193 |
+
lo, hi = min(vals), max(vals)
|
| 194 |
+
# c137 (partner report M007): this is a FILLED AREA chart, and a filled area
|
| 195 |
+
# implies magnitude measured from zero. Baselining at min(vals) made the fill
|
| 196 |
+
# lie: warn-feed's 412 -> 223 monthly series (a real but moderate ~46% decline)
|
| 197 |
+
# plunged from the top of the frame to the floor, reading as "layoffs stopped".
|
| 198 |
+
# Area and bar charts start at zero; only line-only charts may crop. If every
|
| 199 |
+
# value is non-negative we anchor at 0 and let the true proportion show.
|
| 200 |
+
base = 0.0 if lo >= 0 else lo
|
| 201 |
+
span = (hi - base) or 1.0
|
| 202 |
+
# Right pad sized from the end label, for the same reason bar_chart sizes
|
| 203 |
+
# its value gutter: a fixed 78 clipped "760 notices" to "760 notice".
|
| 204 |
+
end_label = _num(vals[-1]) + unit
|
| 205 |
+
pad_l, pad_t, pad_b = 8, 16, 26
|
| 206 |
+
pad_r = max(52, int(len(end_label) * 7.6) + 22)
|
| 207 |
+
pw = width - pad_l - pad_r
|
| 208 |
+
ph = height - pad_t - pad_b
|
| 209 |
+
|
| 210 |
+
def xy(i, v):
|
| 211 |
+
x = pad_l + pw * (i / (len(vals) - 1))
|
| 212 |
+
y = pad_t + ph * (1 - (v - base) / span)
|
| 213 |
+
return x, y
|
| 214 |
+
|
| 215 |
+
pts = [xy(i, v) for i, v in enumerate(vals)]
|
| 216 |
+
line = " ".join(f"{x:.1f},{y:.1f}" for x, y in pts)
|
| 217 |
+
area = (f"{pad_l},{pad_t + ph:.1f} " + line +
|
| 218 |
+
f" {pad_l + pw:.1f},{pad_t + ph:.1f}")
|
| 219 |
+
|
| 220 |
+
p = [f'<svg class="dv-svg" viewBox="0 0 {width} {height}" width="100%" '
|
| 221 |
+
f'height="{height}" role="img" xmlns="http://www.w3.org/2000/svg" '
|
| 222 |
+
f'aria-label="{_e(title or "trend")}">']
|
| 223 |
+
if title:
|
| 224 |
+
p.append(f"<title>{_e(title)}</title>")
|
| 225 |
+
p.append(f'<line x1="{pad_l}" y1="{pad_t + ph:.1f}" x2="{pad_l + pw:.1f}" '
|
| 226 |
+
f'y2="{pad_t + ph:.1f}" stroke="currentColor" stroke-opacity=".14" stroke-width="1"/>')
|
| 227 |
+
p.append(f'<polygon points="{area}" fill="var(--dv-area)" opacity="0.55"/>')
|
| 228 |
+
p.append(f'<polyline points="{line}" fill="none" stroke="var(--dv-line)" '
|
| 229 |
+
f'stroke-width="2" stroke-linejoin="round" stroke-linecap="round"/>')
|
| 230 |
+
lx, ly = pts[-1]
|
| 231 |
+
p.append(f'<circle cx="{lx:.1f}" cy="{ly:.1f}" r="4.5" fill="var(--dv-line)"/>')
|
| 232 |
+
p.append(f'<text x="{lx + 10:.1f}" y="{ly + 4:.0f}" font-size="13" '
|
| 233 |
+
f'font-weight="700" fill="currentColor">{_e(_num(vals[-1]))}{_e(unit)}</text>')
|
| 234 |
+
p.append(f'<text x="{pad_l}" y="{height - 6}" font-size="11.5" '
|
| 235 |
+
f'fill="currentColor" opacity=".72">{_e(points[0][0])}</text>')
|
| 236 |
+
p.append(f'<text x="{pad_l + pw:.1f}" y="{height - 6}" font-size="11.5" '
|
| 237 |
+
f'text-anchor="end" fill="currentColor" opacity=".72">{_e(points[-1][0])}</text>')
|
| 238 |
+
p.append("</svg>")
|
| 239 |
+
return "".join(p)
|
| 240 |
+
|
| 241 |
+
|
| 242 |
+
def sparkline(values, width: int = 120, height: int = 30) -> str:
|
| 243 |
+
"""A trend small enough to sit inside a sentence or a stat tile."""
|
| 244 |
+
_require(values, "sparkline")
|
| 245 |
+
vals = [float(v) for v in values]
|
| 246 |
+
if len(vals) < 2:
|
| 247 |
+
raise ValueError("sparkline: needs at least two values")
|
| 248 |
+
lo, hi = min(vals), max(vals)
|
| 249 |
+
span = (hi - lo) or 1.0
|
| 250 |
+
pts = " ".join(
|
| 251 |
+
f"{(width - 4) * i / (len(vals) - 1) + 2:.1f},"
|
| 252 |
+
f"{2 + (height - 4) * (1 - (v - lo) / span):.1f}"
|
| 253 |
+
for i, v in enumerate(vals))
|
| 254 |
+
return (f'<svg viewBox="0 0 {width} {height}" width="{width}" '
|
| 255 |
+
f'height="{height}" role="img" aria-label="trend" '
|
| 256 |
+
f'xmlns="http://www.w3.org/2000/svg">'
|
| 257 |
+
f'<polyline points="{pts}" fill="none" stroke="var(--dv-line)" '
|
| 258 |
+
f'stroke-width="2" stroke-linejoin="round"/></svg>')
|
| 259 |
+
|
| 260 |
+
|
| 261 |
+
def table_fallback(rows, headers=("", "")) -> str:
|
| 262 |
+
"""The same numbers as markup. Ship it beside any chart a screen reader or
|
| 263 |
+
a text-only client would otherwise get nothing from."""
|
| 264 |
+
_require(rows, "table_fallback")
|
| 265 |
+
head = "".join(f"<th>{_e(h)}</th>" for h in headers)
|
| 266 |
+
body = "".join(
|
| 267 |
+
"<tr>" + "".join(f"<td>{_e(_num(c) if i else c)}</td>"
|
| 268 |
+
for i, c in enumerate(r)) + "</tr>"
|
| 269 |
+
for r in rows)
|
| 270 |
+
return f"<table><thead><tr>{head}</tr></thead><tbody>{body}</tbody></table>"
|
hf_largest_events.py
ADDED
|
@@ -0,0 +1,514 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Publish the LARGEST US LAYOFF EVENTS (WARN Act, 1988-present) as its own HF
|
| 3 |
+
dataset. (c334, 2026-09-12 — board c333 repair item R2.)
|
| 4 |
+
|
| 5 |
+
WHY THIS EXISTS — the evidence, not a hunch:
|
| 6 |
+
* Standing rule from c319: a new HF dataset must be a COMPUTED CUT that owns a
|
| 7 |
+
query no existing artifact answers — never "the same rows, filtered".
|
| 8 |
+
* Checked on the Hub 2026-09-12 BEFORE publishing: `largest layoffs`,
|
| 9 |
+
`biggest layoffs` and `layoff events` each returned **0 datasets** hub-wide
|
| 10 |
+
(`mass layoffs` returned only our own closings-vs-layoffs set). Re-verify:
|
| 11 |
+
curl -s "https://huggingface.co/api/datasets?search=largest+layoffs"
|
| 12 |
+
* Why it cannot be copied from a portal scrape: a state portal lists one row
|
| 13 |
+
per SITE per NOTICE. "The largest layoff" is an EMPLOYER-level fact that
|
| 14 |
+
only exists after (1) 48 portals are in one schema, (2) the employer's 22
|
| 15 |
+
spellings are resolved to one group (alias_merge.py — the c309 join that is
|
| 16 |
+
this venture's actual moat), and (3) the rolling per-site notices are
|
| 17 |
+
clustered into one event. None of those three steps is on any portal.
|
| 18 |
+
|
| 19 |
+
WHAT AN "EVENT" IS (say it on the card, keep it in the columns):
|
| 20 |
+
* One employer GROUP (alias-merged), its notices sorted by date, split into
|
| 21 |
+
events wherever the gap between consecutive notice dates exceeds
|
| 22 |
+
EVENT_GAP_DAYS. A rolling programme (Boeing filed monthly Jun-Nov 2020) is
|
| 23 |
+
ONE event; the same employer's 2023 cuts are a separate event.
|
| 24 |
+
* `workers_reported` sums `employees_affected` over the event's notices AFTER
|
| 25 |
+
dropping exact duplicate rows (same state + location + count + notice date +
|
| 26 |
+
effective date — some portals list the same site twice). Successive notices for the
|
| 27 |
+
same site are NOT collapsed: we cannot tell from a portal whether a second
|
| 28 |
+
notice is cumulative or incremental, so the sum can overstate a rolling
|
| 29 |
+
programme. `sites` (distinct state+location) is the conservative companion.
|
| 30 |
+
|
| 31 |
+
HONESTY RAILS (read before editing):
|
| 32 |
+
1. Every event carries its `notice_ids` so any row can be re-derived from the
|
| 33 |
+
free flagship CSV; nothing here is hand-typed.
|
| 34 |
+
2. `single_notice=true` flags events built from ONE filing — those are only as
|
| 35 |
+
good as the one portal row (e.g. a 16,132-worker staffing-firm closure).
|
| 36 |
+
3. `states_covered_in_year` says how many states the archive holds any notice
|
| 37 |
+
for in the event's year. Pre-2020 the archive is thin (IL/OR go back to
|
| 38 |
+
1988; most states start 2010-2023), so an early-year ranking is a ranking
|
| 39 |
+
of the states we hold, not of the country. The card says so first.
|
| 40 |
+
4. The current year is a running total; events that started in the last
|
| 41 |
+
EVENT_GAP_DAYS days may still grow (`event_open=true`).
|
| 42 |
+
5. Every number is recounted from out/full/warn_notices.csv on every run; the
|
| 43 |
+
card, the chart and the CSV are written from ONE in-memory result.
|
| 44 |
+
|
| 45 |
+
Reads : out/full/warn_notices.csv (this build), out/employer_slugs.json
|
| 46 |
+
Writes: out/largest_events.csv, repo/data/largest_layoff_events.csv,
|
| 47 |
+
hf_largest_events_staging/ then uploads to <user>/DATASET_NAME
|
| 48 |
+
Usage (cwd = product/):
|
| 49 |
+
python3 hf_largest_events.py --selftest
|
| 50 |
+
HF_STAGE_ONLY=1 python3 hf_largest_events.py
|
| 51 |
+
.venv-hf/bin/python3 hf_largest_events.py
|
| 52 |
+
Env: HF_TOKEN. Non-fatal by convention in publish.sh.
|
| 53 |
+
"""
|
| 54 |
+
import collections
|
| 55 |
+
import csv
|
| 56 |
+
import datetime
|
| 57 |
+
import json
|
| 58 |
+
import os
|
| 59 |
+
import re
|
| 60 |
+
import shutil
|
| 61 |
+
import sys
|
| 62 |
+
|
| 63 |
+
HERE = os.path.dirname(os.path.abspath(__file__))
|
| 64 |
+
sys.path.insert(0, HERE)
|
| 65 |
+
import alias_merge # noqa: E402
|
| 66 |
+
import dataviz # noqa: E402
|
| 67 |
+
|
| 68 |
+
DATASET_NAME = "us-largest-layoff-events-warn-act"
|
| 69 |
+
STAGE = "hf_largest_events_staging"
|
| 70 |
+
NOTICES = os.path.join(HERE, "out", "full", "warn_notices.csv")
|
| 71 |
+
SLUGS = os.path.join(HERE, "out", "employer_slugs.json")
|
| 72 |
+
OUT_CSV = os.path.join(HERE, "out", "largest_events.csv")
|
| 73 |
+
REPO_CSV = os.path.join(HERE, "repo", "data", "largest_layoff_events.csv")
|
| 74 |
+
SITE = "https://approjects-warn-act-notices.static.hf.space"
|
| 75 |
+
REPO = "https://github.com/APVentureEngine/warn-act-notices"
|
| 76 |
+
NOTICE_DS = "https://huggingface.co/datasets/APProjects/us-warn-act-layoffs-notices-daily"
|
| 77 |
+
MULTI_DS = "https://huggingface.co/datasets/APProjects/us-multi-state-layoffs-employers-warn-act"
|
| 78 |
+
RATES_DS = "https://huggingface.co/datasets/APProjects/us-layoffs-per-capita-by-state-warn-act"
|
| 79 |
+
WATCH = "https://approj.gumroad.com/l/warn-watch"
|
| 80 |
+
FREE_WATCH = "https://approj.gumroad.com/l/warn-free-watch"
|
| 81 |
+
|
| 82 |
+
EVENT_GAP_DAYS = 45 # a gap longer than this between an employer's notices starts a new event
|
| 83 |
+
MAX_EVENT_DAYS = 183 # ...and an event never spans more than ~6 months (Boeing files in WA every
|
| 84 |
+
# few weeks for years; without this cap 2014-2018 chained into one "event")
|
| 85 |
+
TOP_N = 1000 # rows published
|
| 86 |
+
MIN_EVENTS = 200 # refuse to publish a table thinner than this
|
| 87 |
+
MIN_WORKERS = 1 # an event with no reported worker count cannot be ranked by workers
|
| 88 |
+
|
| 89 |
+
COLS = ["rank", "employer", "event_start", "event_end", "year", "workers_reported", "notices",
|
| 90 |
+
"notices_with_worker_count", "sites", "states", "states_count", "largest_single_notice",
|
| 91 |
+
"largest_notice_state", "largest_notice_location", "notice_types", "single_notice",
|
| 92 |
+
"event_open", "duplicates_dropped", "states_covered_in_year", "employer_page", "notice_ids"]
|
| 93 |
+
|
| 94 |
+
|
| 95 |
+
def _date(r):
|
| 96 |
+
d = (r.get("notice_date") or r.get("effective_date") or "")[:10]
|
| 97 |
+
try:
|
| 98 |
+
return datetime.date.fromisoformat(d)
|
| 99 |
+
except ValueError:
|
| 100 |
+
return None
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
def _int(v):
|
| 104 |
+
try:
|
| 105 |
+
n = int(float(str(v).replace(",", "")))
|
| 106 |
+
except (TypeError, ValueError):
|
| 107 |
+
return None
|
| 108 |
+
return n if n > 0 else None
|
| 109 |
+
|
| 110 |
+
|
| 111 |
+
def _loc(r):
|
| 112 |
+
return re.sub(r"\s+", " ", (r.get("location") or "").strip().lower())
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
def _display(rows_in_group, key, key_names):
|
| 116 |
+
"""The group key's own spelling as it appears anywhere in the archive (so a 2020 event of
|
| 117 |
+
14 Hyatt Regency hotels reads 'Hyatt Regency', not 'Hyatt Regency - Portland'); otherwise
|
| 118 |
+
the most frequent spelling inside the event, shortest on ties."""
|
| 119 |
+
if key in key_names:
|
| 120 |
+
return key_names[key]
|
| 121 |
+
c = collections.Counter((r.get("company_canonical") or r.get("company") or "").strip()
|
| 122 |
+
for r in rows_in_group)
|
| 123 |
+
return sorted(c.items(), key=lambda kv: (-kv[1], len(kv[0]), kv[0]))[0][0]
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
def build(rows=None, today=None, slugs=None, gap_days=EVENT_GAP_DAYS, top_n=TOP_N):
|
| 127 |
+
rows = rows if rows is not None else list(csv.DictReader(open(NOTICES, encoding="utf-8")))
|
| 128 |
+
today = today or datetime.date.today()
|
| 129 |
+
if slugs is None:
|
| 130 |
+
try:
|
| 131 |
+
slugs = json.load(open(SLUGS, encoding="utf-8"))
|
| 132 |
+
except (OSError, ValueError):
|
| 133 |
+
slugs = {}
|
| 134 |
+
amap = alias_merge.build_alias_map(rows)
|
| 135 |
+
groups = collections.defaultdict(list)
|
| 136 |
+
covered = collections.defaultdict(set)
|
| 137 |
+
spell = collections.defaultdict(collections.Counter) # lowercased canonical -> raw spellings
|
| 138 |
+
for r in rows:
|
| 139 |
+
c = alias_merge.canon_of(r)
|
| 140 |
+
raw = (r.get("company_canonical") or r.get("company") or "").strip()
|
| 141 |
+
if c and raw:
|
| 142 |
+
spell[c][raw] += 1
|
| 143 |
+
key_names = {k: sorted(v.items(), key=lambda kv: (-kv[1], kv[0]))[0][0] for k, v in spell.items()}
|
| 144 |
+
for r in rows:
|
| 145 |
+
d = _date(r)
|
| 146 |
+
if d is None or d > today + datetime.timedelta(days=730):
|
| 147 |
+
continue
|
| 148 |
+
st = (r.get("state") or "").upper()
|
| 149 |
+
covered[d.year].add(st)
|
| 150 |
+
c = alias_merge.canon_of(r)
|
| 151 |
+
if not c:
|
| 152 |
+
continue
|
| 153 |
+
groups[amap.get(c, c)].append((d, r))
|
| 154 |
+
gap = datetime.timedelta(days=gap_days)
|
| 155 |
+
events = []
|
| 156 |
+
for key, items in groups.items():
|
| 157 |
+
items.sort(key=lambda t: t[0])
|
| 158 |
+
cur = []
|
| 159 |
+
for d, r in items:
|
| 160 |
+
if cur and ((d - cur[-1][0]) > gap or (d - cur[0][0]).days > MAX_EVENT_DAYS):
|
| 161 |
+
events.append((key, cur))
|
| 162 |
+
cur = []
|
| 163 |
+
cur.append((d, r))
|
| 164 |
+
if cur:
|
| 165 |
+
events.append((key, cur))
|
| 166 |
+
out = []
|
| 167 |
+
for key, ev in events:
|
| 168 |
+
seen, kept, dups = set(), [], 0
|
| 169 |
+
for d, r in ev:
|
| 170 |
+
sig = ((r.get("state") or "").upper(), _loc(r), _int(r.get("employees_affected")),
|
| 171 |
+
(r.get("notice_date") or "")[:10], (r.get("effective_date") or "")[:10])
|
| 172 |
+
if sig in seen:
|
| 173 |
+
dups += 1
|
| 174 |
+
continue
|
| 175 |
+
seen.add(sig)
|
| 176 |
+
kept.append((d, r))
|
| 177 |
+
counts = [(_int(r.get("employees_affected")) or 0, r) for _, r in kept]
|
| 178 |
+
workers = sum(n for n, _ in counts)
|
| 179 |
+
if workers < MIN_WORKERS:
|
| 180 |
+
continue
|
| 181 |
+
big_n, big_r = max(counts, key=lambda t: t[0])
|
| 182 |
+
states = sorted({(r.get("state") or "").upper() for _, r in kept if r.get("state")})
|
| 183 |
+
types = sorted({(r.get("notice_type") or "").strip() for _, r in kept} - {""})
|
| 184 |
+
start, end = kept[0][0], kept[-1][0]
|
| 185 |
+
out.append({
|
| 186 |
+
"rank": 0,
|
| 187 |
+
"employer": _display([r for _, r in kept], key, key_names),
|
| 188 |
+
"event_start": start.isoformat(), "event_end": end.isoformat(), "year": start.year,
|
| 189 |
+
"workers_reported": workers, "notices": len(kept),
|
| 190 |
+
"notices_with_worker_count": sum(1 for n, _ in counts if n),
|
| 191 |
+
"sites": len({((r.get("state") or "").upper(), _loc(r)) for _, r in kept}),
|
| 192 |
+
"states": ";".join(states), "states_count": len(states),
|
| 193 |
+
"largest_single_notice": big_n,
|
| 194 |
+
"largest_notice_state": (big_r.get("state") or "").upper(),
|
| 195 |
+
"largest_notice_location": (big_r.get("location") or "").strip(),
|
| 196 |
+
"notice_types": ";".join(types)[:200],
|
| 197 |
+
"single_notice": "true" if len(kept) == 1 else "false",
|
| 198 |
+
"event_open": "true" if (today - end) <= gap else "false",
|
| 199 |
+
"duplicates_dropped": dups,
|
| 200 |
+
"states_covered_in_year": len(covered.get(start.year, ())),
|
| 201 |
+
"employer_page": (SITE + "/" + slugs[key]) if key in slugs else "",
|
| 202 |
+
"notice_ids": ";".join(r.get("id") or "" for _, r in kept),
|
| 203 |
+
})
|
| 204 |
+
out.sort(key=lambda e: (-e["workers_reported"], e["event_start"], e["employer"]))
|
| 205 |
+
out = out[:top_n]
|
| 206 |
+
for i, e in enumerate(out, 1):
|
| 207 |
+
e["rank"] = i
|
| 208 |
+
stats = {
|
| 209 |
+
"events_total": len(events), "rows": len(out),
|
| 210 |
+
"workers_in_table": sum(e["workers_reported"] for e in out),
|
| 211 |
+
"notices_in_table": sum(e["notices"] for e in out),
|
| 212 |
+
"multi_notice_rows": sum(1 for e in out if e["single_notice"] == "false"),
|
| 213 |
+
"multi_state_rows": sum(1 for e in out if e["states_count"] > 1),
|
| 214 |
+
"dups_dropped": sum(e["duplicates_dropped"] for e in out),
|
| 215 |
+
"years": sorted({e["year"] for e in out}),
|
| 216 |
+
"asof": today.isoformat(), "cur_year": today.year, "gap_days": gap_days,
|
| 217 |
+
"states_covered_now": len(covered.get(today.year, ())),
|
| 218 |
+
"min_workers_in_table": out[-1]["workers_reported"] if out else 0,
|
| 219 |
+
}
|
| 220 |
+
return {"rows": out, "stats": stats}
|
| 221 |
+
|
| 222 |
+
|
| 223 |
+
CARD = """---
|
| 224 |
+
pretty_name: Largest US layoff events since 1988 - WARN Act notices clustered by employer
|
| 225 |
+
license: cc-by-4.0
|
| 226 |
+
language:
|
| 227 |
+
- en
|
| 228 |
+
task_categories:
|
| 229 |
+
- tabular-classification
|
| 230 |
+
tags:
|
| 231 |
+
- layoffs
|
| 232 |
+
- largest-layoffs
|
| 233 |
+
- biggest-layoffs
|
| 234 |
+
- layoff-events
|
| 235 |
+
- mass-layoffs
|
| 236 |
+
- warn-act
|
| 237 |
+
- warn-notices
|
| 238 |
+
- entity-resolution
|
| 239 |
+
- labor-market
|
| 240 |
+
- corporate-events
|
| 241 |
+
- public-records
|
| 242 |
+
- government-data
|
| 243 |
+
- alternative-data
|
| 244 |
+
- united-states
|
| 245 |
+
- daily-updated
|
| 246 |
+
- tabular
|
| 247 |
+
size_categories:
|
| 248 |
+
- 1K<n<10K
|
| 249 |
+
configs:
|
| 250 |
+
- config_name: default
|
| 251 |
+
data_files:
|
| 252 |
+
- split: train
|
| 253 |
+
path: data/largest_layoff_events.csv
|
| 254 |
+
---
|
| 255 |
+
|
| 256 |
+
# The {rows:,} largest US layoff events on record under the WARN Act, {y0}-{y1}
|
| 257 |
+
|
| 258 |
+
**Rebuilt {asof}. Largest on file: {top_employer}, {top_start} to {top_end} — {top_workers:,}
|
| 259 |
+
workers across {top_notices} notices in {top_states} state(s). The table's floor is
|
| 260 |
+
{min_workers:,} workers; {multi_notice:,} of the {rows:,} events span more than one notice and
|
| 261 |
+
{multi_state:,} span more than one state.**
|
| 262 |
+
|
| 263 |
+
A state WARN portal lists one row per site per notice. "What was the biggest layoff?" is an
|
| 264 |
+
employer-level question, and answering it takes three steps no portal performs: 48 agencies'
|
| 265 |
+
notices normalized into one schema daily, an employer's many spellings resolved to one name
|
| 266 |
+
(Boeing files under 22 of them, typos included), and its rolling per-site notices clustered into
|
| 267 |
+
one event. This dataset is the result, top {rows:,} by reported workers, rebuilt daily.
|
| 268 |
+
|
| 269 |
+

|
| 270 |
+
|
| 271 |
+
## Read this before quoting a rank
|
| 272 |
+
|
| 273 |
+
* **Coverage is uneven before ~2020.** The archive reaches back to 1988 only for the states
|
| 274 |
+
whose portals kept history (Illinois and Oregon among them); most states begin between 2010
|
| 275 |
+
and 2023. `states_covered_in_year` says how many states the archive holds for the event's
|
| 276 |
+
year — an early-year rank is a rank among the states we hold, not the country.
|
| 277 |
+
* **An event is one employer's notices with no gap longer than {gap} days between consecutive
|
| 278 |
+
notice dates, and no longer than {maxdays} days end to end.** A rolling programme is one event;
|
| 279 |
+
a later round, or the seventh month of a continuous programme, is a separate event.
|
| 280 |
+
* **`workers_reported` can overstate a rolling programme.** Exact duplicate rows (same state,
|
| 281 |
+
location, count, notice date and effective date) are dropped (`duplicates_dropped`), but successive
|
| 282 |
+
notices for the same site are summed because a portal does not say whether the second is
|
| 283 |
+
cumulative. `sites` is the conservative companion figure.
|
| 284 |
+
* **`single_notice=true` means the whole event is one portal row.** It is only as reliable as
|
| 285 |
+
that row; check it at the source before repeating it.
|
| 286 |
+
* Employer names are resolved by [`alias_merge.py`]({repo}/blob/main/product/alias_merge.py)
|
| 287 |
+
(token signature + purity-guarded prefix absorption); the resolver ships in this repo. It
|
| 288 |
+
merges spellings, not corporate parents: subsidiaries filing under their own names are their
|
| 289 |
+
own employers.
|
| 290 |
+
* The current year is a running total; `event_open=true` marks events that may still grow.
|
| 291 |
+
|
| 292 |
+
## Top 20 right now
|
| 293 |
+
|
| 294 |
+
| # | employer | period | workers | notices | states |
|
| 295 |
+
|---|---|---|---|---|---|
|
| 296 |
+
{top20}
|
| 297 |
+
|
| 298 |
+
## Columns
|
| 299 |
+
|
| 300 |
+
| column | meaning |
|
| 301 |
+
|---|---|
|
| 302 |
+
| `rank` | position by `workers_reported` (ties: earlier start first) |
|
| 303 |
+
| `employer` | most frequent canonical spelling inside the event |
|
| 304 |
+
| `event_start`, `event_end`, `year` | first and last notice date; `year` is the start year |
|
| 305 |
+
| `workers_reported` | sum of `employees_affected` over the event's de-duplicated notices |
|
| 306 |
+
| `notices`, `notices_with_worker_count` | notices in the event; how many carried a count |
|
| 307 |
+
| `sites` | distinct state + location pairs |
|
| 308 |
+
| `states`, `states_count` | semicolon-separated state codes |
|
| 309 |
+
| `largest_single_notice`, `largest_notice_state`, `largest_notice_location` | the biggest single filing inside the event |
|
| 310 |
+
| `notice_types` | distinct raw `notice_type` strings, as the portals wrote them |
|
| 311 |
+
| `single_notice` | `true` when the event is a single filing |
|
| 312 |
+
| `event_open` | `true` when the last notice is within {gap} days of the rebuild date |
|
| 313 |
+
| `duplicates_dropped` | exact duplicate portal rows removed before summing |
|
| 314 |
+
| `states_covered_in_year` | states with any notice in the archive for `year` |
|
| 315 |
+
| `employer_page` | the employer's history page on the site, when one exists |
|
| 316 |
+
| `notice_ids` | semicolon-separated ids joining to the flagship notices CSV |
|
| 317 |
+
|
| 318 |
+
## Where the rows come from
|
| 319 |
+
|
| 320 |
+
The free, CC BY 4.0 [normalized WARN archive]({notice_ds}) rebuilt daily from 48 state portals
|
| 321 |
+
([site]({site}), [GitHub]({repo})). Related cuts of the same archive: [employers filing in
|
| 322 |
+
several states]({multi_ds}) and [layoffs per capita by state]({rates_ds}).
|
| 323 |
+
|
| 324 |
+
Get told the day an employer on your list files, in any of the 48 states: [free 30-day
|
| 325 |
+
watch]({free_watch}) (no card) or [WARN Watch, $49/year]({watch}) for a list of up to 500
|
| 326 |
+
employers.
|
| 327 |
+
|
| 328 |
+
*Automated publisher (APProjects). Not affiliated with any government agency. Verify critical
|
| 329 |
+
figures against the state source linked from each notice.*
|
| 330 |
+
"""
|
| 331 |
+
|
| 332 |
+
|
| 333 |
+
def render(res):
|
| 334 |
+
rows, st = res["rows"], res["stats"]
|
| 335 |
+
if st["rows"] < MIN_EVENTS:
|
| 336 |
+
raise SystemExit(f"hf_largest_events: only {st['rows']} events; refusing to render")
|
| 337 |
+
top = rows[0]
|
| 338 |
+
top20 = "\n".join(
|
| 339 |
+
f"| {e['rank']} | {e['employer']} | {e['event_start']} to {e['event_end']} | "
|
| 340 |
+
f"{e['workers_reported']:,} | {e['notices']} | {e['states']} |"
|
| 341 |
+
for e in rows[:20])
|
| 342 |
+
svg = dataviz.bar_chart([(f"{e['employer'][:28]} ({e['year']})", e["workers_reported"])
|
| 343 |
+
for e in rows[:15]], unit=" workers")
|
| 344 |
+
card = CARD.format(
|
| 345 |
+
rows=st["rows"], y0=min(st["years"]), y1=max(st["years"]), asof=st["asof"],
|
| 346 |
+
top_employer=top["employer"], top_start=top["event_start"], top_end=top["event_end"],
|
| 347 |
+
top_workers=top["workers_reported"], top_notices=top["notices"],
|
| 348 |
+
top_states=top["states_count"], min_workers=st["min_workers_in_table"],
|
| 349 |
+
multi_notice=st["multi_notice_rows"], multi_state=st["multi_state_rows"],
|
| 350 |
+
gap=st["gap_days"], maxdays=MAX_EVENT_DAYS, top20=top20, repo=REPO, notice_ds=NOTICE_DS, site=SITE,
|
| 351 |
+
multi_ds=MULTI_DS, rates_ds=RATES_DS, free_watch=FREE_WATCH, watch=WATCH,
|
| 352 |
+
)
|
| 353 |
+
return card, svg
|
| 354 |
+
|
| 355 |
+
|
| 356 |
+
README_ANCHOR = "<!--largest-events-readme-->"
|
| 357 |
+
README_PATH = os.path.join(HERE, "repo", "README.md")
|
| 358 |
+
HF_URL = f"https://huggingface.co/datasets/APProjects/{DATASET_NAME}"
|
| 359 |
+
|
| 360 |
+
|
| 361 |
+
def inject_readme(res, readme_path=README_PATH):
|
| 362 |
+
"""One idempotent README line under the per-capita line (GitHub = the human channel)."""
|
| 363 |
+
st = res["stats"]
|
| 364 |
+
if not res["rows"]:
|
| 365 |
+
return False
|
| 366 |
+
top = res["rows"][0]
|
| 367 |
+
line = (f"{README_ANCHOR} \U0001F3ED **[The {st['rows']:,} largest US layoff events since "
|
| 368 |
+
f"{min(st['years'])}](data/largest_layoff_events.csv)** — notices clustered per resolved "
|
| 369 |
+
f"employer (rolling programmes = one event); #1 {top['employer']} {top['year']}, "
|
| 370 |
+
f"{top['workers_reported']:,} workers over {top['notices']} notices. "
|
| 371 |
+
f"[Card on Hugging Face]({HF_URL}).")
|
| 372 |
+
txt = open(readme_path, encoding="utf-8").read()
|
| 373 |
+
txt = "\n".join(ln for ln in txt.split("\n") if README_ANCHOR not in ln)
|
| 374 |
+
for key in ("<!--state-rates-readme-->", "<!--metro-readme-->", "<!--county-readme-->"):
|
| 375 |
+
i = txt.find(key)
|
| 376 |
+
if i >= 0:
|
| 377 |
+
j = txt.find("\n", i)
|
| 378 |
+
txt = txt[:j + 1] + line + "\n" + txt[j + 1:]
|
| 379 |
+
break
|
| 380 |
+
else:
|
| 381 |
+
k = txt.find("\n## ")
|
| 382 |
+
txt = (txt[:k] + "\n\n" + line + "\n" + txt[k:]) if k >= 0 else txt + "\n\n" + line + "\n"
|
| 383 |
+
assert txt.count(README_ANCHOR) == 1
|
| 384 |
+
open(readme_path, "w", encoding="utf-8").write(txt)
|
| 385 |
+
print("hf_largest_events: README line injected")
|
| 386 |
+
return True
|
| 387 |
+
|
| 388 |
+
|
| 389 |
+
def write_csv(path, rows):
|
| 390 |
+
os.makedirs(os.path.dirname(path), exist_ok=True)
|
| 391 |
+
with open(path, "w", newline="", encoding="utf-8") as f:
|
| 392 |
+
w = csv.DictWriter(f, fieldnames=COLS)
|
| 393 |
+
w.writeheader()
|
| 394 |
+
w.writerows(rows)
|
| 395 |
+
|
| 396 |
+
|
| 397 |
+
def stage(res):
|
| 398 |
+
card, svg = render(res)
|
| 399 |
+
root = os.path.join(HERE, STAGE)
|
| 400 |
+
shutil.rmtree(root, ignore_errors=True)
|
| 401 |
+
os.makedirs(os.path.join(root, "data"), exist_ok=True)
|
| 402 |
+
open(os.path.join(root, "README.md"), "w", encoding="utf-8").write(card)
|
| 403 |
+
open(os.path.join(root, "chart.svg"), "w", encoding="utf-8").write(svg)
|
| 404 |
+
write_csv(os.path.join(root, "data", "largest_layoff_events.csv"), res["rows"])
|
| 405 |
+
for fn in ("hf_largest_events.py", "alias_merge.py", "dataviz.py"):
|
| 406 |
+
shutil.copy2(os.path.join(HERE, fn), os.path.join(root, fn))
|
| 407 |
+
print(f"hf_largest_events: staged {res['stats']['rows']} events "
|
| 408 |
+
f"(of {res['stats']['events_total']}) -> {STAGE}/")
|
| 409 |
+
return root
|
| 410 |
+
|
| 411 |
+
|
| 412 |
+
def upload():
|
| 413 |
+
token = os.environ.get("HF_TOKEN")
|
| 414 |
+
if not token:
|
| 415 |
+
print("HF_TOKEN not set - staged only, nothing uploaded.")
|
| 416 |
+
return 0
|
| 417 |
+
from huggingface_hub import HfApi
|
| 418 |
+
api = HfApi(token=token)
|
| 419 |
+
user = api.whoami()["name"]
|
| 420 |
+
repo_id = f"{user}/{DATASET_NAME}"
|
| 421 |
+
api.create_repo(repo_id, repo_type="dataset", exist_ok=True)
|
| 422 |
+
api.upload_folder(folder_path=os.path.join(HERE, STAGE), repo_id=repo_id,
|
| 423 |
+
repo_type="dataset", commit_message="daily largest-events refresh")
|
| 424 |
+
print(f"uploaded -> https://huggingface.co/datasets/{repo_id}")
|
| 425 |
+
return 0
|
| 426 |
+
|
| 427 |
+
|
| 428 |
+
def selftest():
|
| 429 |
+
def n(i, st, comp, wc, nd, loc="Plant", ed="", nt="Layoff"):
|
| 430 |
+
return {"id": f"id{i}", "state": st, "company": comp, "company_canonical": comp,
|
| 431 |
+
"employees_affected": wc, "notice_date": nd, "effective_date": ed,
|
| 432 |
+
"location": loc, "notice_type": nt}
|
| 433 |
+
rows = [
|
| 434 |
+
# Boeing: 3 notices within 45d = one event, plus one 200 days later = second event
|
| 435 |
+
n(1, "WA", "Boeing", "500", "2020-06-01"),
|
| 436 |
+
n(2, "WA", "Boeing", "300", "2020-07-01"), # (parent needs >= 3 exact rows)
|
| 437 |
+
n(3, "CA", "Boeing - El Paso", "50", "2020-08-10", loc="El Paso"), # alias-merged spelling
|
| 438 |
+
n(4, "WA", "Boeing", "100", "2021-03-01"),
|
| 439 |
+
# Rolling filer: 8 notices 30 days apart = 210 days -> must split at the 183-day cap
|
| 440 |
+
*[n(20 + i, "KS", "Roller", "10", (datetime.date(2019, 1, 1) + datetime.timedelta(days=30 * i)).isoformat())
|
| 441 |
+
for i in range(8)],
|
| 442 |
+
# exact duplicate portal row must be dropped, not summed
|
| 443 |
+
n(5, "TX", "Acme", "400", "2022-01-05", ed="2022-03-01"),
|
| 444 |
+
n(6, "TX", "Acme", "400", "2022-01-05", ed="2022-03-01"),
|
| 445 |
+
# single notice giant; no worker count row must not rank
|
| 446 |
+
n(7, "NJ", "Giant Staffing", "9000", "2025-05-20"),
|
| 447 |
+
n(8, "NJ", "Ghost", "", "2025-05-20"),
|
| 448 |
+
n(9, "NJ", "Bad Date", "10", "not-a-date"),
|
| 449 |
+
]
|
| 450 |
+
today = datetime.date(2026, 9, 12)
|
| 451 |
+
res = build(rows, today=today, slugs={"boeing": "employers/b/boeing.html"}, top_n=20)
|
| 452 |
+
by = {(e["employer"], e["event_start"]): e for e in res["rows"]}
|
| 453 |
+
b1 = by[("Boeing", "2020-06-01")]
|
| 454 |
+
assert b1["workers_reported"] == 850 and b1["notices"] == 3 and b1["states"] == "CA;WA", b1
|
| 455 |
+
assert b1["sites"] == 2 and b1["largest_single_notice"] == 500 and b1["largest_notice_state"] == "WA"
|
| 456 |
+
assert b1["employer_page"].endswith("employers/b/boeing.html")
|
| 457 |
+
assert ("Boeing", "2021-03-01") in by, "second round must be a separate event"
|
| 458 |
+
acme = by[("Acme", "2022-01-05")]
|
| 459 |
+
assert acme["workers_reported"] == 400 and acme["duplicates_dropped"] == 1 and acme["notices"] == 1
|
| 460 |
+
g = by[("Giant Staffing", "2025-05-20")]
|
| 461 |
+
assert g["single_notice"] == "true" and res["rows"][0] is g
|
| 462 |
+
assert not any(e["employer"] in ("Ghost", "Bad Date") for e in res["rows"])
|
| 463 |
+
assert all(e["event_open"] == "false" for e in res["rows"])
|
| 464 |
+
assert b1["states_covered_in_year"] == 2 and [e["rank"] for e in res["rows"]] == list(range(1, 7))
|
| 465 |
+
assert b1["notice_ids"] == "id1;id2;id3"
|
| 466 |
+
roll = [e for e in res["rows"] if e["employer"] == "Roller"]
|
| 467 |
+
assert len(roll) == 2 and sorted(e["notices"] for e in roll) == [1, 7], roll
|
| 468 |
+
# render must refuse a thin table, and must not leave placeholders when it renders
|
| 469 |
+
try:
|
| 470 |
+
render(res)
|
| 471 |
+
except SystemExit:
|
| 472 |
+
pass
|
| 473 |
+
else:
|
| 474 |
+
raise AssertionError("render must refuse < MIN_EVENTS events")
|
| 475 |
+
wide = [n(100 + i, "IL", f"Employer {i}", str(10 + i), f"2024-01-{1 + i % 28:02d}")
|
| 476 |
+
for i in range(MIN_EVENTS + 5)]
|
| 477 |
+
wide.append(n(999, "IL", "Employer 3", "5", "2026-09-01")) # open event in the current year
|
| 478 |
+
res2 = build(wide, today=today, slugs={}, top_n=TOP_N)
|
| 479 |
+
assert any(e["event_open"] == "true" for e in res2["rows"])
|
| 480 |
+
card, svg = render(res2)
|
| 481 |
+
left = re.findall(r"\{[a-z_0-9]+\}", card)
|
| 482 |
+
assert not left, f"unformatted placeholder: {left}"
|
| 483 |
+
assert "<svg" in svg and "| 1 | Employer" in card and "45 days" in card
|
| 484 |
+
import tempfile
|
| 485 |
+
tmp = tempfile.NamedTemporaryFile("w", suffix=".md", delete=False, encoding="utf-8")
|
| 486 |
+
tmp.write("# T\n\n<!--metro-readme--> metro line\n<!--state-rates-readme--> rates line\n\n## Next\n")
|
| 487 |
+
tmp.close()
|
| 488 |
+
inject_readme(res2, tmp.name); inject_readme(res2, tmp.name)
|
| 489 |
+
t = open(tmp.name, encoding="utf-8").read()
|
| 490 |
+
assert t.count(README_ANCHOR) == 1 and t.index("rates line") < t.index(README_ANCHOR)
|
| 491 |
+
os.unlink(tmp.name)
|
| 492 |
+
print(f"hf_largest_events selftest: ok ({len(res['rows'])} events in fixture, card {len(card)} chars)")
|
| 493 |
+
return 0
|
| 494 |
+
|
| 495 |
+
|
| 496 |
+
def main():
|
| 497 |
+
if "--selftest" in sys.argv:
|
| 498 |
+
return selftest()
|
| 499 |
+
res = build()
|
| 500 |
+
write_csv(OUT_CSV, res["rows"])
|
| 501 |
+
write_csv(REPO_CSV, res["rows"])
|
| 502 |
+
try:
|
| 503 |
+
inject_readme(res)
|
| 504 |
+
except Exception as e: # noqa: BLE001 — a README line must never block the upload
|
| 505 |
+
print(f"hf_largest_events: WARN README injection failed ({e})")
|
| 506 |
+
stage(res)
|
| 507 |
+
if os.environ.get("HF_STAGE_ONLY"):
|
| 508 |
+
print("HF_STAGE_ONLY set - not uploading.")
|
| 509 |
+
return 0
|
| 510 |
+
return upload()
|
| 511 |
+
|
| 512 |
+
|
| 513 |
+
if __name__ == "__main__":
|
| 514 |
+
sys.exit(main())
|