---
license: mit
task_categories:
- text-to-image
---
**i1: A Simple and Fully Open Recipe for Strong Text-to-Image Models**
[Boya Zeng](https://boyazeng.github.io), [Tianze Luo](https://luotianze666.github.io), [Shu Pu](https://urrealhero.github.io/MyPersonalWeb/), [Jucheng Shen](https://juchengshen.github.io), [Taiming Lu](https://taiminglu.com), [Gabriel Sarch](http://gabesarch.me), [Zhuang Liu](https://www.cs.princeton.edu/~zhuangl)
Princeton University
[[`arXiv`](https://arxiv.org/abs/2606.11289)][[`code`](https://github.com/zlab-princeton/i1)][[`model`](https://huggingface.co/zlab-princeton/i1-3B)][[`project page`](https://zlab-princeton.github.io/i1/)]
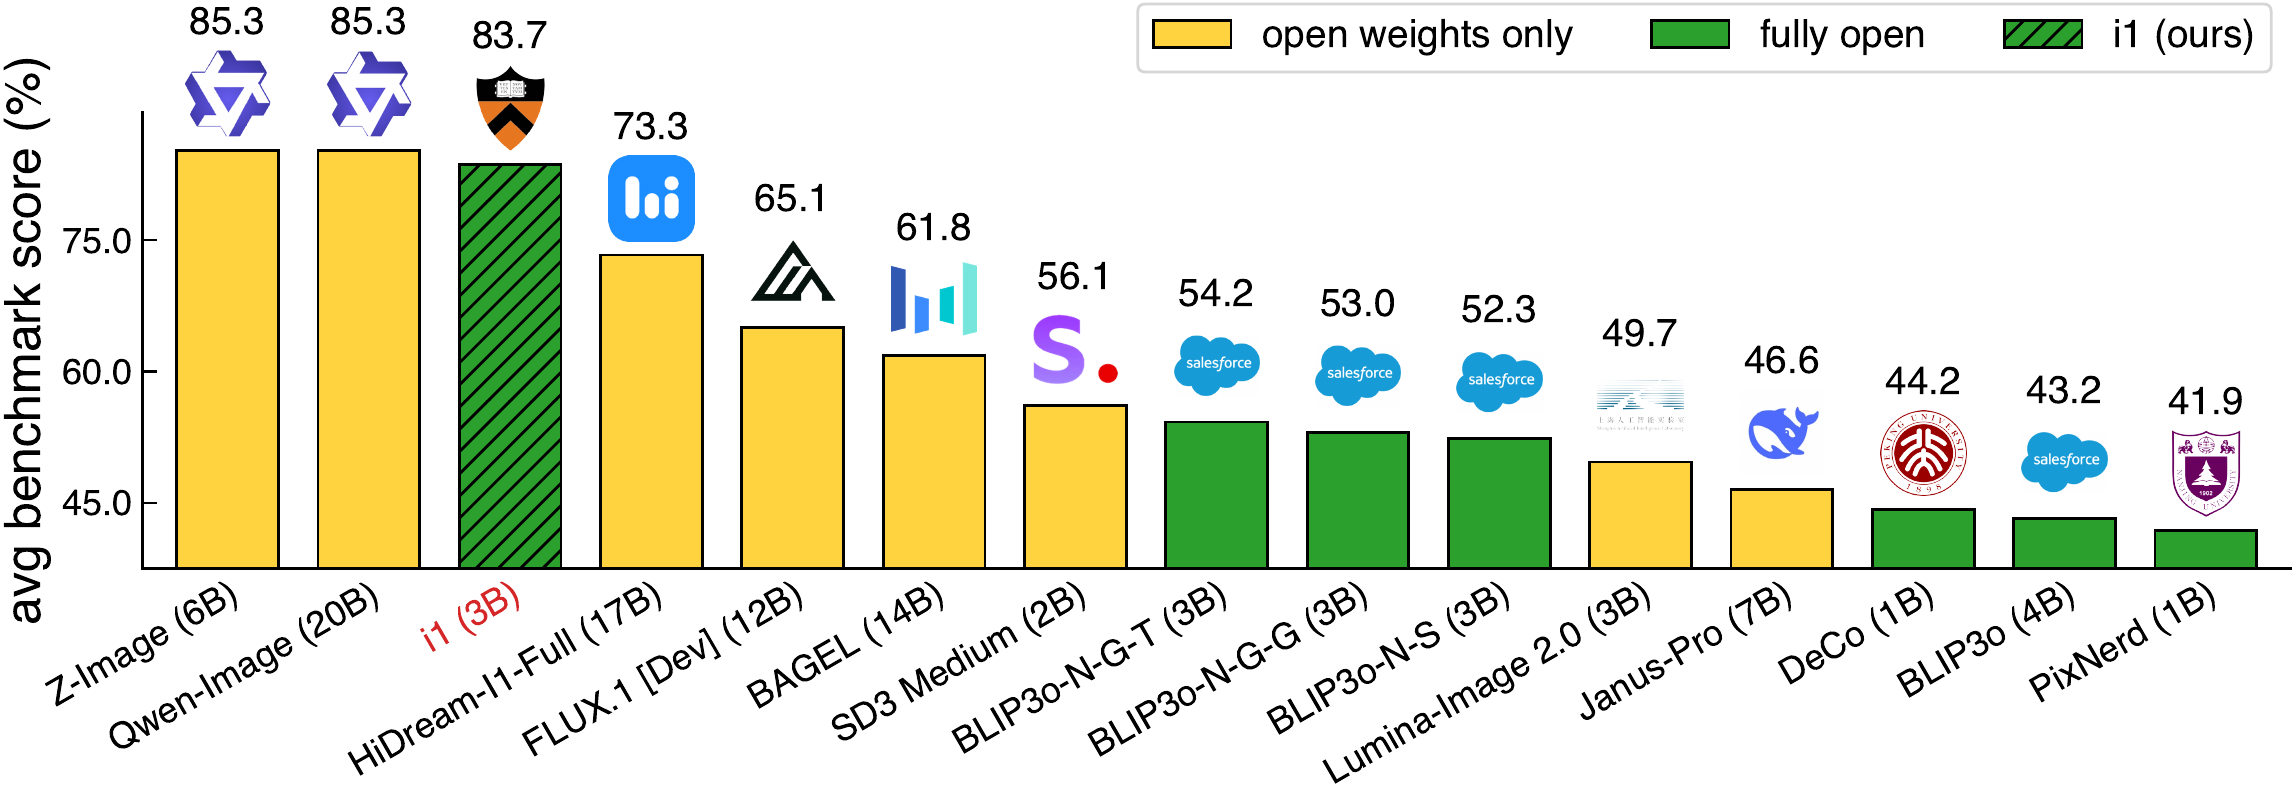
## Overview
To prepare the dataset for training, we store the image-caption pairs as TFRecords.
**This HuggingFace dataset contains the TFRecords corresponding to the `rendered_text` dataset at 512×512 resolution.** Concretely, we only retain raw images with a shorter edge of at least 512 pixels, center-crop them to squares, resize them to 512×512, and randomly subsample the resulting dataset to 1M images.
It also serves as an example of what a dataset processed using [our data processing pipeline](https://github.com/zlab-princeton/i1/tree/main/data_processing) looks like.
You can find processed TFRecords for other datasets and resolutions [here](https://huggingface.co/i1-datasets).
## Structure
`dataset-train.tfrecord-*-of-00128` are TFRecord shards, where 128 is the total number of shards.
`dataset_info.json` and `features.json` are TFDS metadata files needed by `tfds.builder_from_directory(...)` to load and decode the dataset correctly.
## Download
```bash
pip install -U "huggingface_hub"
hf download i1-datasets/i1-rendered_text-512-resolution-1m-tfrecord \
--repo-type dataset \
--local-dir /path/to/save/dataset
```
## Citation
If this dataset is useful for your research, please cite the following work:
```bibtex
@article{zeng2026i1,
title={i1: A Simple and Fully Open Recipe for Strong Text-to-Image Models},
author={Zeng, Boya and Luo, Tianze and Pu, Shu and Shen, Jucheng and Lu, Taiming and Sarch, Gabriel and Liu, Zhuang},
journal={arXiv preprint arXiv:2606.11289},
year={2026}
}
```