

Jake commited on
Add visual analysis charts
Browse files- README.md +46 -0
- scripts/build_visual_assets.py +383 -0
- visuals/dataset_filtering_10k.svg +15 -0
- visuals/eval_progression.svg +15 -0
- visuals/fixed_hermes_category_eval.svg +15 -0
- visuals/gguf_quant_size_quality.svg +15 -0
- visuals/group_sweep_memory_time.svg +15 -0
- visuals/memory_model.svg +15 -0
- visuals/pipeline_overview.svg +15 -0
- visuals/visual_manifest.json +19 -0
README.md
CHANGED
|
@@ -16,6 +16,52 @@ This repository documents a local Mac fine-tuning run for `LiquidAI/LFM2.5-8B-A1
|
|
| 16 |
|
| 17 |
It contains compact, reproducible artifacts only: configs, manifests, eval JSON, logs, and the focused tool-call repair dataset. Large model checkpoints are released separately under `sjakek/LFM-2.5-8B-1B-hermes-ft`.
|
| 18 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 19 |
## What Was Trained
|
| 20 |
|
| 21 |
The run had two stages.
|
|
|
|
| 16 |
|
| 17 |
It contains compact, reproducible artifacts only: configs, manifests, eval JSON, logs, and the focused tool-call repair dataset. Large model checkpoints are released separately under `sjakek/LFM-2.5-8B-1B-hermes-ft`.
|
| 18 |
|
| 19 |
+
## Visual Overview
|
| 20 |
+
|
| 21 |
+
These figures summarize the main mechanism and results. They are generated from the JSON reports in this repository with `scripts/build_visual_assets.py`, so the visuals are reproducible rather than hand-drawn.
|
| 22 |
+
|
| 23 |
+
### End-to-end training and export flow
|
| 24 |
+
|
| 25 |
+

|
| 26 |
+
|
| 27 |
+
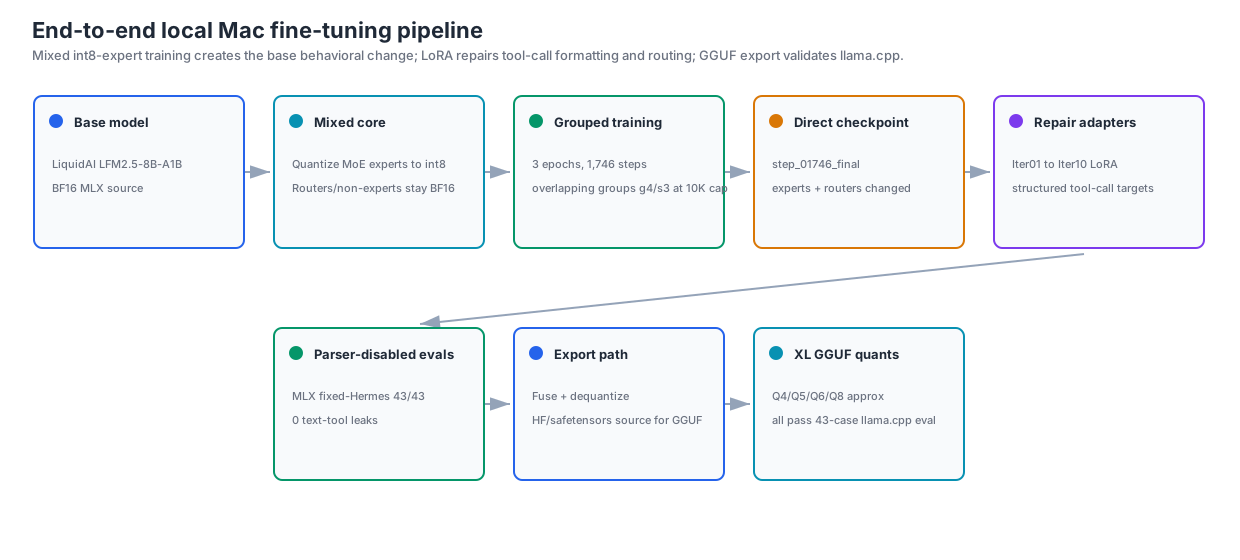
The project starts from the BF16 LFM2.5 MoE checkpoint, constructs an int8-expert/BF16-router mixed core, runs grouped MoE expert/router updates for three epochs, uses eval failures to build focused LoRA repair datasets, then validates both MLX and llama.cpp exports.
|
| 28 |
+
|
| 29 |
+
### Why the mixed-quant runtime matters
|
| 30 |
+
|
| 31 |
+

|
| 32 |
+
|
| 33 |
+
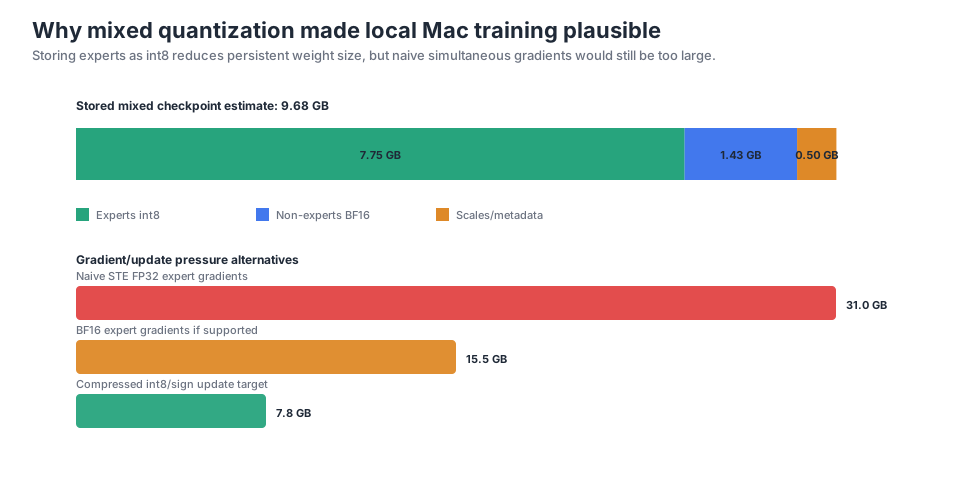
The core memory move is storing MoE experts as int8 while keeping routers and non-expert layers in BF16. This makes the checkpoint small enough to work with locally, but the chart also shows why a naive simultaneous gradient over all experts would still be expensive. The implemented route is grouped semi-full-gradient training: update multiple MoE layers together, then requantize before moving to the next group.
|
| 34 |
+
|
| 35 |
+
### Selecting the grouped training size
|
| 36 |
+
|
| 37 |
+

|
| 38 |
+
|
| 39 |
+
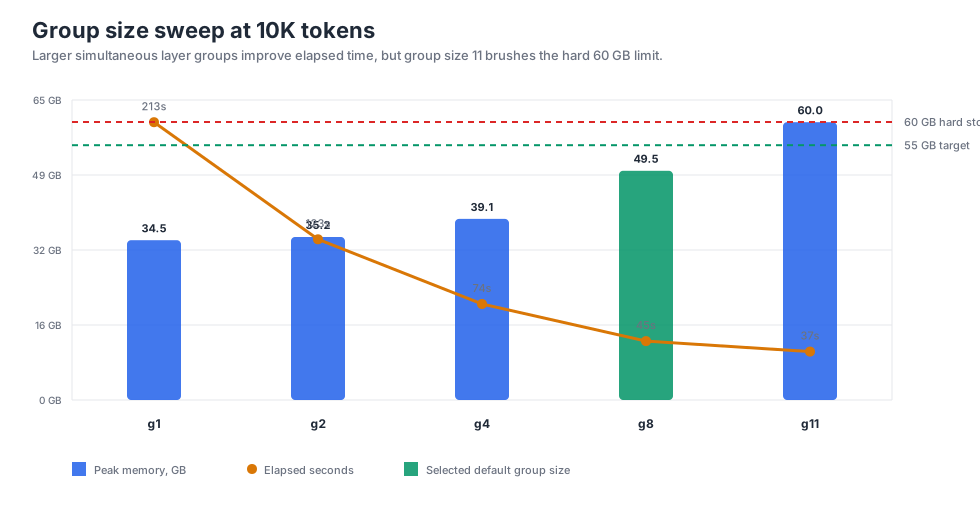
The 10K-token group sweep showed the practical Mac tradeoff. Larger groups improved elapsed time, but group size 11 approached the 60 GB hard stop. The selected run used overlapping groups of four layers with stride three for stability, while the sweep demonstrated that larger grouped updates were mechanically possible on this 64 GB machine.
|
| 40 |
+
|
| 41 |
+
### Dataset filtering at the 10K cap
|
| 42 |
+
|
| 43 |
+

|
| 44 |
+
|
| 45 |
+
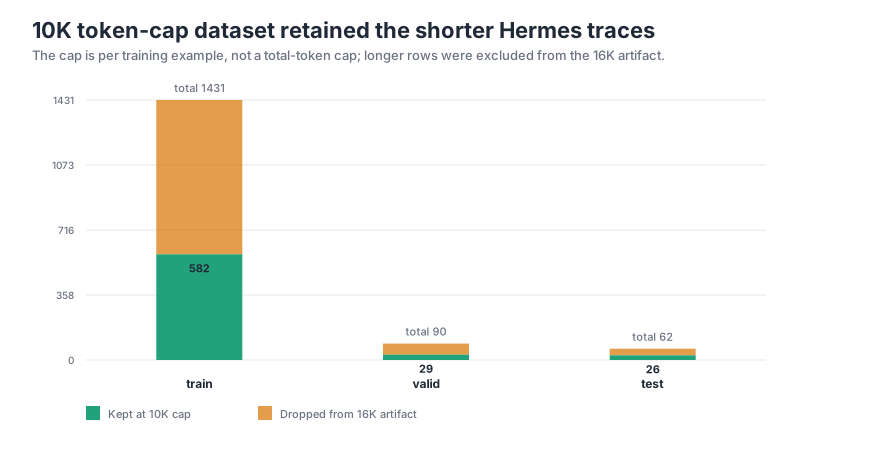
The token cap is per example. The 10K artifact retained 582 train examples, 29 validation examples, and 26 test examples from the filtered Hermes trace pool after dropping longer rows from the earlier 16K artifact.
|
| 46 |
+
|
| 47 |
+
### Reliability across repair stages
|
| 48 |
+
|
| 49 |
+

|
| 50 |
+
|
| 51 |
+
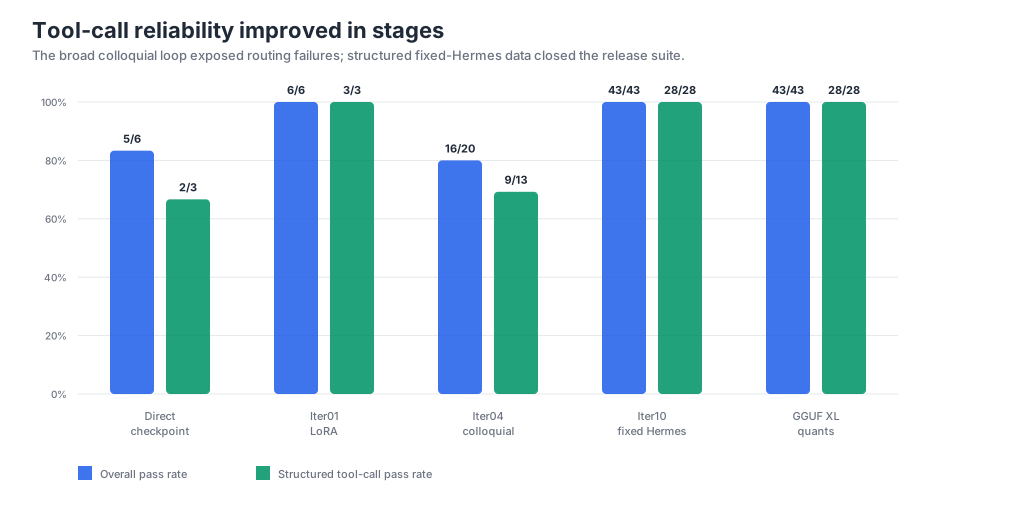
The broad colloquial router attempts preserved structured tool-call parsing but failed to fix terminal/file routing. The successful iter10 repair used structured chat rows with `assistant.tool_calls`, prompt masking, and the exact fixed Hermes tool schema.
|
| 52 |
+
|
| 53 |
+
### Final fixed-Hermes coverage
|
| 54 |
+
|
| 55 |
+

|
| 56 |
+
|
| 57 |
+
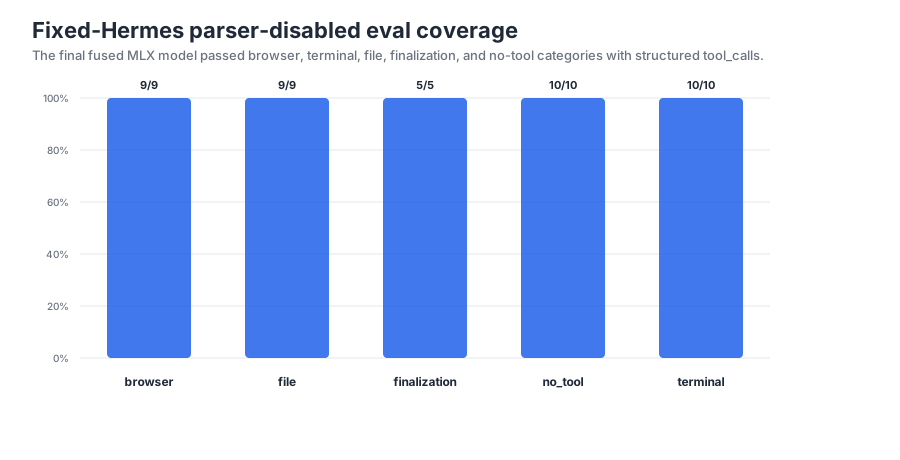
The accepted fused MLX checkpoint passed the parser-disabled fixed-Hermes suite across browser, terminal, file, no-tool, and tool-result finalization categories with zero text-tool leaks.
|
| 58 |
+
|
| 59 |
+
### GGUF quant export result
|
| 60 |
+
|
| 61 |
+

|
| 62 |
+
|
| 63 |
+
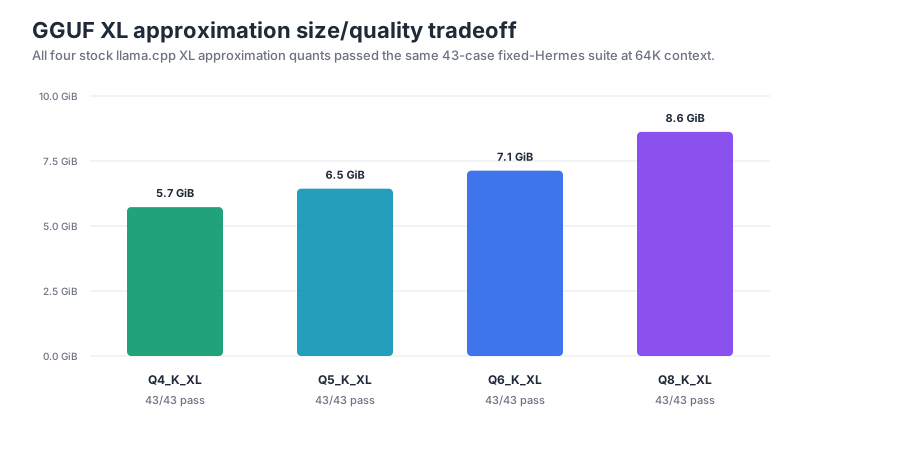
The GGUF path exports from a dequantized BF16/HF source, then produces stock llama.cpp XL-approximation quants using tensor-type policies and the Hermes/tool-router imatrix. All four released quants passed the same 43-case fixed-Hermes eval at 64K context.
|
| 64 |
+
|
| 65 |
## What Was Trained
|
| 66 |
|
| 67 |
The run had two stages.
|
scripts/build_visual_assets.py
ADDED
|
@@ -0,0 +1,383 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/usr/bin/env python3
|
| 2 |
+
"""Build small SVG visualizations for the Hugging Face analysis repo.
|
| 3 |
+
|
| 4 |
+
The renderer intentionally avoids third-party plotting dependencies so the
|
| 5 |
+
figures can be regenerated on a fresh Mac with only the standard library.
|
| 6 |
+
"""
|
| 7 |
+
|
| 8 |
+
from __future__ import annotations
|
| 9 |
+
|
| 10 |
+
import html
|
| 11 |
+
import json
|
| 12 |
+
from pathlib import Path
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
ROOT = Path(__file__).resolve().parents[1]
|
| 16 |
+
OUT = ROOT / "visuals"
|
| 17 |
+
|
| 18 |
+
BG = "#ffffff"
|
| 19 |
+
INK = "#1f2937"
|
| 20 |
+
MUTED = "#6b7280"
|
| 21 |
+
GRID = "#e5e7eb"
|
| 22 |
+
BLUE = "#2563eb"
|
| 23 |
+
TEAL = "#0891b2"
|
| 24 |
+
GREEN = "#059669"
|
| 25 |
+
ORANGE = "#d97706"
|
| 26 |
+
RED = "#dc2626"
|
| 27 |
+
PURPLE = "#7c3aed"
|
| 28 |
+
SLATE = "#475569"
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
def esc(value: object) -> str:
|
| 32 |
+
return html.escape(str(value), quote=True)
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
def write_svg(path: Path, width: int, height: int, body: str) -> None:
|
| 36 |
+
path.parent.mkdir(parents=True, exist_ok=True)
|
| 37 |
+
path.write_text(
|
| 38 |
+
f"""<svg xmlns="http://www.w3.org/2000/svg" width="{width}" height="{height}" viewBox="0 0 {width} {height}" role="img">
|
| 39 |
+
<rect width="100%" height="100%" fill="{BG}"/>
|
| 40 |
+
<style>
|
| 41 |
+
.title {{ font: 700 22px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {INK}; }}
|
| 42 |
+
.subtitle {{ font: 400 13px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {MUTED}; }}
|
| 43 |
+
.label {{ font: 600 12px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {INK}; }}
|
| 44 |
+
.small {{ font: 400 11px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {MUTED}; }}
|
| 45 |
+
.axis {{ stroke: {GRID}; stroke-width: 1; }}
|
| 46 |
+
.tick {{ font: 400 10px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {MUTED}; }}
|
| 47 |
+
.value {{ font: 700 11px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {INK}; }}
|
| 48 |
+
.node-title {{ font: 700 13px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {INK}; }}
|
| 49 |
+
.node-text {{ font: 400 11px -apple-system, BlinkMacSystemFont, "Segoe UI", sans-serif; fill: {MUTED}; }}
|
| 50 |
+
</style>
|
| 51 |
+
{body}
|
| 52 |
+
</svg>
|
| 53 |
+
""",
|
| 54 |
+
encoding="utf-8",
|
| 55 |
+
)
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
def load_json(rel: str) -> dict:
|
| 59 |
+
return json.loads((ROOT / rel).read_text(encoding="utf-8"))
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
def header(title: str, subtitle: str) -> str:
|
| 63 |
+
return (
|
| 64 |
+
f'<text x="32" y="38" class="title">{esc(title)}</text>'
|
| 65 |
+
f'<text x="32" y="60" class="subtitle">{esc(subtitle)}</text>'
|
| 66 |
+
)
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
def line_chart_path(points: list[tuple[float, float]]) -> str:
|
| 70 |
+
if not points:
|
| 71 |
+
return ""
|
| 72 |
+
start = f"M {points[0][0]:.1f} {points[0][1]:.1f}"
|
| 73 |
+
rest = " ".join(f"L {x:.1f} {y:.1f}" for x, y in points[1:])
|
| 74 |
+
return f"{start} {rest}"
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
def render_pipeline() -> None:
|
| 78 |
+
width, height = 1240, 560
|
| 79 |
+
nodes = [
|
| 80 |
+
("Base model", "LiquidAI LFM2.5-8B-A1B", "BF16 MLX source", 34, 96, BLUE),
|
| 81 |
+
("Mixed core", "Quantize MoE experts to int8", "Routers/non-experts stay BF16", 274, 96, TEAL),
|
| 82 |
+
("Grouped training", "3 epochs, 1,746 steps", "overlapping groups g4/s3 at 10K cap", 514, 96, GREEN),
|
| 83 |
+
("Direct checkpoint", "step_01746_final", "experts + routers changed", 754, 96, ORANGE),
|
| 84 |
+
("Repair adapters", "Iter01 to Iter10 LoRA", "structured tool-call targets", 994, 96, PURPLE),
|
| 85 |
+
("Parser-disabled evals", "MLX fixed-Hermes 43/43", "0 text-tool leaks", 274, 328, GREEN),
|
| 86 |
+
("Export path", "Fuse + dequantize", "HF/safetensors source for GGUF", 514, 328, BLUE),
|
| 87 |
+
("XL GGUF quants", "Q4/Q5/Q6/Q8 approx", "all pass 43-case llama.cpp eval", 754, 328, TEAL),
|
| 88 |
+
]
|
| 89 |
+
body = header(
|
| 90 |
+
"End-to-end local Mac fine-tuning pipeline",
|
| 91 |
+
"Mixed int8-expert training creates the base behavioral change; LoRA repairs tool-call formatting and routing; GGUF export validates llama.cpp.",
|
| 92 |
+
)
|
| 93 |
+
body += '<defs><marker id="arrow" markerWidth="10" markerHeight="10" refX="9" refY="3" orient="auto"><path d="M0,0 L0,6 L9,3 z" fill="#94a3b8"/></marker></defs>'
|
| 94 |
+
|
| 95 |
+
arrows = [
|
| 96 |
+
(214, 172, 270, 172),
|
| 97 |
+
(454, 172, 510, 172),
|
| 98 |
+
(694, 172, 750, 172),
|
| 99 |
+
(934, 172, 990, 172),
|
| 100 |
+
(1084, 254, 420, 324),
|
| 101 |
+
(454, 404, 510, 404),
|
| 102 |
+
(694, 404, 750, 404),
|
| 103 |
+
]
|
| 104 |
+
for x1, y1, x2, y2 in arrows:
|
| 105 |
+
body += f'<line x1="{x1}" y1="{y1}" x2="{x2}" y2="{y2}" stroke="#94a3b8" stroke-width="2" marker-end="url(#arrow)"/>'
|
| 106 |
+
|
| 107 |
+
for title, l1, l2, x, y, color in nodes:
|
| 108 |
+
body += f'<rect x="{x}" y="{y}" width="210" height="152" rx="8" fill="#f8fafc" stroke="{color}" stroke-width="2"/>'
|
| 109 |
+
body += f'<circle cx="{x+22}" cy="{y+25}" r="7" fill="{color}"/>'
|
| 110 |
+
body += f'<text x="{x+40}" y="{y+31}" class="node-title">{esc(title)}</text>'
|
| 111 |
+
body += f'<text x="{x+18}" y="{y+72}" class="node-text">{esc(l1)}</text>'
|
| 112 |
+
body += f'<text x="{x+18}" y="{y+96}" class="node-text">{esc(l2)}</text>'
|
| 113 |
+
write_svg(OUT / "pipeline_overview.svg", width, height, body)
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
def render_group_sweep() -> None:
|
| 117 |
+
data = load_json("reports/group_sweep_10k.json")
|
| 118 |
+
rows = [r for r in data["results"] if r.get("ok")]
|
| 119 |
+
width, height = 980, 520
|
| 120 |
+
left, top, chart_w, chart_h = 72, 100, 820, 300
|
| 121 |
+
max_mem = max(r["peak_memory_gb"] for r in rows) * 1.08
|
| 122 |
+
max_time = max(r["elapsed_s"] for r in rows) * 1.08
|
| 123 |
+
x_step = chart_w / len(rows)
|
| 124 |
+
bar_w = 54
|
| 125 |
+
body = header(
|
| 126 |
+
"Group size sweep at 10K tokens",
|
| 127 |
+
"Larger simultaneous layer groups improve elapsed time, but group size 11 brushes the hard 60 GB limit.",
|
| 128 |
+
)
|
| 129 |
+
for i in range(0, 5):
|
| 130 |
+
y = top + chart_h - i * chart_h / 4
|
| 131 |
+
body += f'<line x1="{left}" y1="{y:.1f}" x2="{left+chart_w}" y2="{y:.1f}" class="axis"/>'
|
| 132 |
+
body += f'<text x="{left-10}" y="{y+4:.1f}" text-anchor="end" class="tick">{max_mem*i/4:.0f} GB</text>'
|
| 133 |
+
body += f'<line x1="{left}" y1="{top}" x2="{left}" y2="{top+chart_h}" stroke="{GRID}"/>'
|
| 134 |
+
body += f'<line x1="{left+chart_w}" y1="{top}" x2="{left+chart_w}" y2="{top+chart_h}" stroke="{GRID}"/>'
|
| 135 |
+
|
| 136 |
+
time_points = []
|
| 137 |
+
for idx, row in enumerate(rows):
|
| 138 |
+
cx = left + x_step * idx + x_step / 2
|
| 139 |
+
mem_h = chart_h * row["peak_memory_gb"] / max_mem
|
| 140 |
+
x = cx - bar_w / 2
|
| 141 |
+
y = top + chart_h - mem_h
|
| 142 |
+
fill = GREEN if row["group_size"] == data["recommended_group_size"] else BLUE
|
| 143 |
+
body += f'<rect x="{x:.1f}" y="{y:.1f}" width="{bar_w}" height="{mem_h:.1f}" rx="4" fill="{fill}" opacity="0.86"/>'
|
| 144 |
+
body += f'<text x="{cx:.1f}" y="{y-8:.1f}" text-anchor="middle" class="value">{row["peak_memory_gb"]:.1f}</text>'
|
| 145 |
+
body += f'<text x="{cx:.1f}" y="{top+chart_h+28}" text-anchor="middle" class="label">g{row["group_size"]}</text>'
|
| 146 |
+
ty = top + chart_h - chart_h * row["elapsed_s"] / max_time
|
| 147 |
+
time_points.append((cx, ty))
|
| 148 |
+
body += f'<path d="{line_chart_path(time_points)}" fill="none" stroke="{ORANGE}" stroke-width="3"/>'
|
| 149 |
+
for (cx, ty), row in zip(time_points, rows):
|
| 150 |
+
body += f'<circle cx="{cx:.1f}" cy="{ty:.1f}" r="5" fill="{ORANGE}"/>'
|
| 151 |
+
body += f'<text x="{cx:.1f}" y="{ty-12:.1f}" text-anchor="middle" class="small">{row["elapsed_s"]:.0f}s</text>'
|
| 152 |
+
|
| 153 |
+
body += f'<line x1="{left}" y1="{top+chart_h*(1-55/max_mem):.1f}" x2="{left+chart_w}" y2="{top+chart_h*(1-55/max_mem):.1f}" stroke="{GREEN}" stroke-dasharray="6 5" stroke-width="2"/>'
|
| 154 |
+
body += f'<line x1="{left}" y1="{top+chart_h*(1-60/max_mem):.1f}" x2="{left+chart_w}" y2="{top+chart_h*(1-60/max_mem):.1f}" stroke="{RED}" stroke-dasharray="6 5" stroke-width="2"/>'
|
| 155 |
+
body += f'<text x="{left+chart_w+12}" y="{top+chart_h*(1-55/max_mem)+4:.1f}" class="small">55 GB target</text>'
|
| 156 |
+
body += f'<text x="{left+chart_w+12}" y="{top+chart_h*(1-60/max_mem)+4:.1f}" class="small">60 GB hard stop</text>'
|
| 157 |
+
body += f'<rect x="{left}" y="{height-58}" width="14" height="14" fill="{BLUE}" opacity="0.86"/><text x="{left+22}" y="{height-46}" class="small">Peak memory, GB</text>'
|
| 158 |
+
body += f'<circle cx="{left+180}" cy="{height-51}" r="5" fill="{ORANGE}"/><text x="{left+192}" y="{height-46}" class="small">Elapsed seconds</text>'
|
| 159 |
+
body += f'<rect x="{left+332}" y="{height-58}" width="14" height="14" fill="{GREEN}" opacity="0.86"/><text x="{left+354}" y="{height-46}" class="small">Selected default group size</text>'
|
| 160 |
+
write_svg(OUT / "group_sweep_memory_time.svg", width, height, body)
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
def render_dataset_filtering() -> None:
|
| 164 |
+
data = load_json("datasets/hermes_filtered_text_10k_manifest.json")["splits"]
|
| 165 |
+
width, height = 880, 460
|
| 166 |
+
left, top, chart_w, chart_h = 86, 100, 680, 260
|
| 167 |
+
labels = list(data.keys())
|
| 168 |
+
max_total = max(v["kept"] + v["dropped_from_16k_artifact"] for v in data.values())
|
| 169 |
+
body = header(
|
| 170 |
+
"10K token-cap dataset retained the shorter Hermes traces",
|
| 171 |
+
"The cap is per training example, not a total-token cap; longer rows were excluded from the 16K artifact.",
|
| 172 |
+
)
|
| 173 |
+
for i in range(5):
|
| 174 |
+
y = top + chart_h - i * chart_h / 4
|
| 175 |
+
body += f'<line x1="{left}" y1="{y:.1f}" x2="{left+chart_w}" y2="{y:.1f}" class="axis"/>'
|
| 176 |
+
body += f'<text x="{left-12}" y="{y+4:.1f}" text-anchor="end" class="tick">{max_total*i/4:.0f}</text>'
|
| 177 |
+
slot = chart_w / len(labels)
|
| 178 |
+
bar_w = 86
|
| 179 |
+
for idx, label in enumerate(labels):
|
| 180 |
+
kept = data[label]["kept"]
|
| 181 |
+
dropped = data[label]["dropped_from_16k_artifact"]
|
| 182 |
+
total = kept + dropped
|
| 183 |
+
x = left + idx * slot + slot / 2 - bar_w / 2
|
| 184 |
+
kept_h = chart_h * kept / max_total
|
| 185 |
+
drop_h = chart_h * dropped / max_total
|
| 186 |
+
y_kept = top + chart_h - kept_h
|
| 187 |
+
y_drop = y_kept - drop_h
|
| 188 |
+
body += f'<rect x="{x:.1f}" y="{y_drop:.1f}" width="{bar_w}" height="{drop_h:.1f}" fill="{ORANGE}" opacity="0.72"/>'
|
| 189 |
+
body += f'<rect x="{x:.1f}" y="{y_kept:.1f}" width="{bar_w}" height="{kept_h:.1f}" fill="{GREEN}" opacity="0.88"/>'
|
| 190 |
+
body += f'<text x="{x+bar_w/2:.1f}" y="{y_kept+18:.1f}" text-anchor="middle" class="value" fill="#fff">{kept}</text>'
|
| 191 |
+
body += f'<text x="{x+bar_w/2:.1f}" y="{y_drop-8:.1f}" text-anchor="middle" class="small">total {total}</text>'
|
| 192 |
+
body += f'<text x="{x+bar_w/2:.1f}" y="{top+chart_h+28}" text-anchor="middle" class="label">{esc(label)}</text>'
|
| 193 |
+
body += f'<rect x="{left}" y="{height-54}" width="14" height="14" fill="{GREEN}" opacity="0.88"/><text x="{left+22}" y="{height-42}" class="small">Kept at 10K cap</text>'
|
| 194 |
+
body += f'<rect x="{left+172}" y="{height-54}" width="14" height="14" fill="{ORANGE}" opacity="0.72"/><text x="{left+194}" y="{height-42}" class="small">Dropped from 16K artifact</text>'
|
| 195 |
+
write_svg(OUT / "dataset_filtering_10k.svg", width, height, body)
|
| 196 |
+
|
| 197 |
+
|
| 198 |
+
def render_eval_progression() -> None:
|
| 199 |
+
colloquial = load_json("reports/colloquial_tool_router_repair_report.json")["eval_summaries"]
|
| 200 |
+
iter04 = colloquial["iter04_masked_colloquial_openai_parser_disabled"]
|
| 201 |
+
stages = [
|
| 202 |
+
("Direct\ncheckpoint", 5, 6, 2, 3),
|
| 203 |
+
("Iter01\nLoRA", 6, 6, 3, 3),
|
| 204 |
+
("Iter04\ncolloquial", iter04["passed"], iter04["total"], iter04["structured_tool_cases_passed"], iter04["tool_cases"]),
|
| 205 |
+
("Iter10\nfixed Hermes", 43, 43, 28, 28),
|
| 206 |
+
("GGUF XL\nquants", 43, 43, 28, 28),
|
| 207 |
+
]
|
| 208 |
+
width, height = 1020, 520
|
| 209 |
+
left, top, chart_w, chart_h = 78, 102, 820, 292
|
| 210 |
+
body = header(
|
| 211 |
+
"Tool-call reliability improved in stages",
|
| 212 |
+
"The broad colloquial loop exposed routing failures; structured fixed-Hermes data closed the release suite.",
|
| 213 |
+
)
|
| 214 |
+
for i in range(6):
|
| 215 |
+
y = top + chart_h - i * chart_h / 5
|
| 216 |
+
body += f'<line x1="{left}" y1="{y:.1f}" x2="{left+chart_w}" y2="{y:.1f}" class="axis"/>'
|
| 217 |
+
body += f'<text x="{left-12}" y="{y+4:.1f}" text-anchor="end" class="tick">{i*20}%</text>'
|
| 218 |
+
slot = chart_w / len(stages)
|
| 219 |
+
for idx, (label, passed, total, tool_passed, tool_total) in enumerate(stages):
|
| 220 |
+
cx = left + idx * slot + slot / 2
|
| 221 |
+
overall = passed / total
|
| 222 |
+
structured = tool_passed / tool_total
|
| 223 |
+
for j, (rate, color, val) in enumerate([(overall, BLUE, f"{passed}/{total}"), (structured, GREEN, f"{tool_passed}/{tool_total}")]):
|
| 224 |
+
bw = 44
|
| 225 |
+
x = cx - 50 + j * 56
|
| 226 |
+
h = chart_h * rate
|
| 227 |
+
y = top + chart_h - h
|
| 228 |
+
body += f'<rect x="{x:.1f}" y="{y:.1f}" width="{bw}" height="{h:.1f}" rx="4" fill="{color}" opacity="0.88"/>'
|
| 229 |
+
body += f'<text x="{x+bw/2:.1f}" y="{y-8:.1f}" text-anchor="middle" class="value">{val}</text>'
|
| 230 |
+
y0 = top + chart_h + 26
|
| 231 |
+
for line in label.split("\n"):
|
| 232 |
+
body += f'<text x="{cx:.1f}" y="{y0:.1f}" text-anchor="middle" class="small">{esc(line)}</text>'
|
| 233 |
+
y0 += 15
|
| 234 |
+
body += f'<rect x="{left}" y="{height-54}" width="14" height="14" fill="{BLUE}" opacity="0.88"/><text x="{left+22}" y="{height-42}" class="small">Overall pass rate</text>'
|
| 235 |
+
body += f'<rect x="{left+178}" y="{height-54}" width="14" height="14" fill="{GREEN}" opacity="0.88"/><text x="{left+200}" y="{height-42}" class="small">Structured tool-call pass rate</text>'
|
| 236 |
+
write_svg(OUT / "eval_progression.svg", width, height, body)
|
| 237 |
+
|
| 238 |
+
|
| 239 |
+
def render_quant_size() -> None:
|
| 240 |
+
data = load_json("release_summary.json")
|
| 241 |
+
rows = []
|
| 242 |
+
for name, item in data["gguf_quants"].items():
|
| 243 |
+
if "Q4" in name:
|
| 244 |
+
label = "Q4_K_XL"
|
| 245 |
+
elif "Q5" in name:
|
| 246 |
+
label = "Q5_K_XL"
|
| 247 |
+
elif "Q6" in name:
|
| 248 |
+
label = "Q6_K_XL"
|
| 249 |
+
else:
|
| 250 |
+
label = "Q8_K_XL"
|
| 251 |
+
rows.append((label, item["bytes"] / 1024**3))
|
| 252 |
+
rows.sort(key=lambda x: x[1])
|
| 253 |
+
width, height = 900, 460
|
| 254 |
+
left, top, chart_w, chart_h = 90, 96, 680, 260
|
| 255 |
+
max_size = max(v for _, v in rows) * 1.16
|
| 256 |
+
body = header(
|
| 257 |
+
"GGUF XL approximation size/quality tradeoff",
|
| 258 |
+
"All four stock llama.cpp XL approximation quants passed the same 43-case fixed-Hermes suite at 64K context.",
|
| 259 |
+
)
|
| 260 |
+
for i in range(5):
|
| 261 |
+
y = top + chart_h - i * chart_h / 4
|
| 262 |
+
body += f'<line x1="{left}" y1="{y:.1f}" x2="{left+chart_w}" y2="{y:.1f}" class="axis"/>'
|
| 263 |
+
body += f'<text x="{left-12}" y="{y+4:.1f}" text-anchor="end" class="tick">{max_size*i/4:.1f} GiB</text>'
|
| 264 |
+
slot = chart_w / len(rows)
|
| 265 |
+
for idx, (label, gib) in enumerate(rows):
|
| 266 |
+
cx = left + idx * slot + slot / 2
|
| 267 |
+
h = chart_h * gib / max_size
|
| 268 |
+
x = cx - 48
|
| 269 |
+
y = top + chart_h - h
|
| 270 |
+
color = [GREEN, TEAL, BLUE, PURPLE][idx]
|
| 271 |
+
body += f'<rect x="{x:.1f}" y="{y:.1f}" width="96" height="{h:.1f}" rx="4" fill="{color}" opacity="0.88"/>'
|
| 272 |
+
body += f'<text x="{cx:.1f}" y="{y-10:.1f}" text-anchor="middle" class="value">{gib:.1f} GiB</text>'
|
| 273 |
+
body += f'<text x="{cx:.1f}" y="{top+chart_h+28}" text-anchor="middle" class="label">{esc(label)}</text>'
|
| 274 |
+
body += f'<text x="{cx:.1f}" y="{top+chart_h+48}" text-anchor="middle" class="small">43/43 pass</text>'
|
| 275 |
+
write_svg(OUT / "gguf_quant_size_quality.svg", width, height, body)
|
| 276 |
+
|
| 277 |
+
|
| 278 |
+
def render_memory_model() -> None:
|
| 279 |
+
data = load_json("reports/memory_estimate.json")
|
| 280 |
+
stored = data["stored_weights_gb"]
|
| 281 |
+
gradients = data["training_gradient_pressure_gb"]
|
| 282 |
+
width, height = 980, 500
|
| 283 |
+
body = header(
|
| 284 |
+
"Why mixed quantization made local Mac training plausible",
|
| 285 |
+
"Storing experts as int8 reduces persistent weight size, but naive simultaneous gradients would still be too large.",
|
| 286 |
+
)
|
| 287 |
+
x0, y0 = 76, 128
|
| 288 |
+
max_w = 760
|
| 289 |
+
total = stored["total_estimate"][1]
|
| 290 |
+
parts = [
|
| 291 |
+
("Experts int8", stored["experts_int8"], GREEN),
|
| 292 |
+
("Non-experts BF16", stored["non_experts_bf16"], BLUE),
|
| 293 |
+
("Scales/metadata", stored["scale_metadata_estimate"][1], ORANGE),
|
| 294 |
+
]
|
| 295 |
+
body += f'<text x="{x0}" y="{y0-18}" class="label">Stored mixed checkpoint estimate: {total:.2f} GB</text>'
|
| 296 |
+
cur = x0
|
| 297 |
+
for label, value, color in parts:
|
| 298 |
+
w = max_w * value / total
|
| 299 |
+
body += f'<rect x="{cur:.1f}" y="{y0}" width="{w:.1f}" height="52" fill="{color}" opacity="0.86"/>'
|
| 300 |
+
body += f'<text x="{cur+w/2:.1f}" y="{y0+31}" text-anchor="middle" class="value" fill="#fff">{value:.2f} GB</text>'
|
| 301 |
+
cur += w
|
| 302 |
+
legend_y = y0 + 80
|
| 303 |
+
lx = x0
|
| 304 |
+
for label, _, color in parts:
|
| 305 |
+
body += f'<rect x="{lx}" y="{legend_y}" width="13" height="13" fill="{color}" opacity="0.86"/><text x="{lx+20}" y="{legend_y+11}" class="small">{esc(label)}</text>'
|
| 306 |
+
lx += 180
|
| 307 |
+
|
| 308 |
+
bars = [
|
| 309 |
+
("Naive STE FP32 expert gradients", gradients["expert_grad_float32_if_naive_ste"], RED),
|
| 310 |
+
("BF16 expert gradients if supported", gradients["expert_grad_bf16_if_supported"], ORANGE),
|
| 311 |
+
("Compressed int8/sign update target", gradients["expert_grad_int8_sign_if_custom_optimizer"], GREEN),
|
| 312 |
+
]
|
| 313 |
+
bx, by, bw_max, bh = 76, 286, 760, 34
|
| 314 |
+
max_g = max(v for _, v, _ in bars)
|
| 315 |
+
body += f'<text x="{bx}" y="{by-22}" class="label">Gradient/update pressure alternatives</text>'
|
| 316 |
+
for idx, (label, value, color) in enumerate(bars):
|
| 317 |
+
y = by + idx * 54
|
| 318 |
+
w = bw_max * value / max_g
|
| 319 |
+
body += f'<text x="{bx}" y="{y-6}" class="small">{esc(label)}</text>'
|
| 320 |
+
body += f'<rect x="{bx}" y="{y}" width="{w:.1f}" height="{bh}" rx="4" fill="{color}" opacity="0.82"/>'
|
| 321 |
+
body += f'<text x="{bx+w+10:.1f}" y="{y+23}" class="value">{value:.1f} GB</text>'
|
| 322 |
+
write_svg(OUT / "memory_model.svg", width, height, body)
|
| 323 |
+
|
| 324 |
+
|
| 325 |
+
def render_category_eval() -> None:
|
| 326 |
+
summary = load_json("evals/iter10_fused_all_fixed_hermes_parser_disabled.json")["summary"]
|
| 327 |
+
metrics = summary["category_metrics"]
|
| 328 |
+
rows = [(k, v["passed"], v["total"]) for k, v in metrics.items()]
|
| 329 |
+
width, height = 900, 460
|
| 330 |
+
left, top, chart_w, chart_h = 80, 98, 690, 260
|
| 331 |
+
body = header(
|
| 332 |
+
"Fixed-Hermes parser-disabled eval coverage",
|
| 333 |
+
"The final fused MLX model passed browser, terminal, file, finalization, and no-tool categories with structured tool_calls.",
|
| 334 |
+
)
|
| 335 |
+
for i in range(6):
|
| 336 |
+
y = top + chart_h - i * chart_h / 5
|
| 337 |
+
body += f'<line x1="{left}" y1="{y:.1f}" x2="{left+chart_w}" y2="{y:.1f}" class="axis"/>'
|
| 338 |
+
body += f'<text x="{left-12}" y="{y+4:.1f}" text-anchor="end" class="tick">{i*20}%</text>'
|
| 339 |
+
slot = chart_w / len(rows)
|
| 340 |
+
for idx, (label, passed, total) in enumerate(rows):
|
| 341 |
+
rate = passed / total
|
| 342 |
+
cx = left + idx * slot + slot / 2
|
| 343 |
+
h = chart_h * rate
|
| 344 |
+
x = cx - 42
|
| 345 |
+
y = top + chart_h - h
|
| 346 |
+
body += f'<rect x="{x:.1f}" y="{y:.1f}" width="84" height="{h:.1f}" rx="4" fill="{BLUE}" opacity="0.86"/>'
|
| 347 |
+
body += f'<text x="{cx:.1f}" y="{y-9:.1f}" text-anchor="middle" class="value">{passed}/{total}</text>'
|
| 348 |
+
body += f'<text x="{cx:.1f}" y="{top+chart_h+28}" text-anchor="middle" class="label">{esc(label)}</text>'
|
| 349 |
+
write_svg(OUT / "fixed_hermes_category_eval.svg", width, height, body)
|
| 350 |
+
|
| 351 |
+
|
| 352 |
+
def main() -> None:
|
| 353 |
+
render_pipeline()
|
| 354 |
+
render_group_sweep()
|
| 355 |
+
render_dataset_filtering()
|
| 356 |
+
render_eval_progression()
|
| 357 |
+
render_quant_size()
|
| 358 |
+
render_memory_model()
|
| 359 |
+
render_category_eval()
|
| 360 |
+
summary = {
|
| 361 |
+
"generated": [
|
| 362 |
+
"visuals/pipeline_overview.svg",
|
| 363 |
+
"visuals/group_sweep_memory_time.svg",
|
| 364 |
+
"visuals/dataset_filtering_10k.svg",
|
| 365 |
+
"visuals/eval_progression.svg",
|
| 366 |
+
"visuals/gguf_quant_size_quality.svg",
|
| 367 |
+
"visuals/memory_model.svg",
|
| 368 |
+
"visuals/fixed_hermes_category_eval.svg",
|
| 369 |
+
],
|
| 370 |
+
"sources": [
|
| 371 |
+
"reports/group_sweep_10k.json",
|
| 372 |
+
"datasets/hermes_filtered_text_10k_manifest.json",
|
| 373 |
+
"reports/colloquial_tool_router_repair_report.json",
|
| 374 |
+
"release_summary.json",
|
| 375 |
+
"reports/memory_estimate.json",
|
| 376 |
+
"evals/iter10_fused_all_fixed_hermes_parser_disabled.json",
|
| 377 |
+
],
|
| 378 |
+
}
|
| 379 |
+
(OUT / "visual_manifest.json").write_text(json.dumps(summary, indent=2), encoding="utf-8")
|
| 380 |
+
|
| 381 |
+
|
| 382 |
+
if __name__ == "__main__":
|
| 383 |
+
main()
|
visuals/dataset_filtering_10k.svg
ADDED
|
visuals/eval_progression.svg
ADDED
|
visuals/fixed_hermes_category_eval.svg
ADDED
|
visuals/gguf_quant_size_quality.svg
ADDED
|
visuals/group_sweep_memory_time.svg
ADDED
|
visuals/memory_model.svg
ADDED
|
visuals/pipeline_overview.svg
ADDED
|
visuals/visual_manifest.json
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"generated": [
|
| 3 |
+
"visuals/pipeline_overview.svg",
|
| 4 |
+
"visuals/group_sweep_memory_time.svg",
|
| 5 |
+
"visuals/dataset_filtering_10k.svg",
|
| 6 |
+
"visuals/eval_progression.svg",
|
| 7 |
+
"visuals/gguf_quant_size_quality.svg",
|
| 8 |
+
"visuals/memory_model.svg",
|
| 9 |
+
"visuals/fixed_hermes_category_eval.svg"
|
| 10 |
+
],
|
| 11 |
+
"sources": [
|
| 12 |
+
"reports/group_sweep_10k.json",
|
| 13 |
+
"datasets/hermes_filtered_text_10k_manifest.json",
|
| 14 |
+
"reports/colloquial_tool_router_repair_report.json",
|
| 15 |
+
"release_summary.json",
|
| 16 |
+
"reports/memory_estimate.json",
|
| 17 |
+
"evals/iter10_fused_all_fixed_hermes_parser_disabled.json"
|
| 18 |
+
]
|
| 19 |
+
}
|