

ProactiveInquirer-Qwen3-8B: the Q&D questioner (seed 1 at the root, seed 2 in seed2/), prompts, example and model card
Browse files- .gitattributes +1 -0
- README.md +198 -0
- adapter_config.json +50 -0
- adapter_model.safetensors +3 -0
- assets/figure1.png +3 -0
- assets/results_frontier.png +0 -0
- example.py +53 -0
- prompts/fragment_user_channel_placebo.txt +4 -0
- prompts/inquirer_prompted.txt +48 -0
- seed2/adapter_config.json +50 -0
- seed2/adapter_model.safetensors +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,4 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/figure1.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,198 @@
|
|
|
|
|
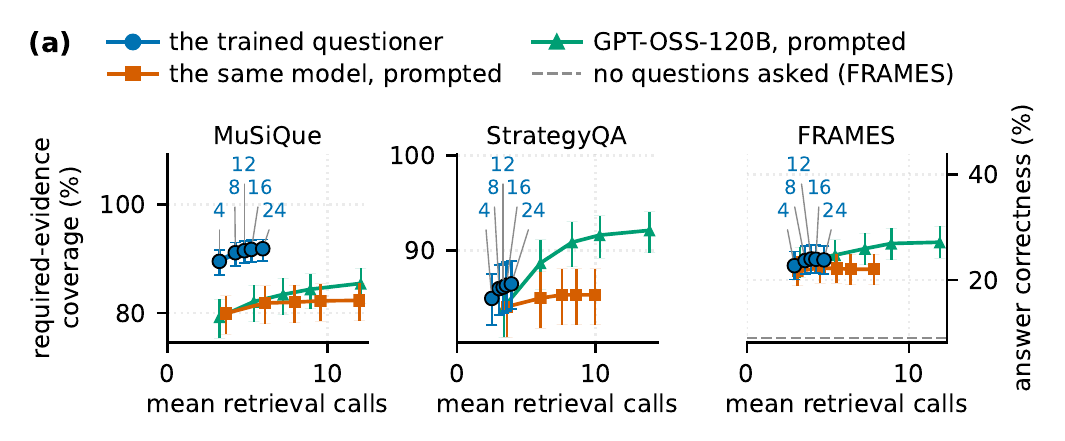
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model: Qwen/Qwen3-8B
|
| 4 |
+
library_name: peft
|
| 5 |
+
pipeline_tag: text-generation
|
| 6 |
+
language:
|
| 7 |
+
- en
|
| 8 |
+
tags:
|
| 9 |
+
- proactive-agents
|
| 10 |
+
- information-seeking
|
| 11 |
+
- question-asking
|
| 12 |
+
- agents
|
| 13 |
+
- retrieval-augmented-generation
|
| 14 |
+
- multi-hop-qa
|
| 15 |
+
- tau2-bench
|
| 16 |
+
- dpo
|
| 17 |
+
- lora
|
| 18 |
+
- qwen3
|
| 19 |
+
datasets:
|
| 20 |
+
- dgslibisey/MuSiQue
|
| 21 |
+
- ChilleD/StrategyQA
|
| 22 |
+
- xanhho/2WikiMultihopQA
|
| 23 |
+
---
|
| 24 |
+
|
| 25 |
+
<div align="center">
|
| 26 |
+
|
| 27 |
+
# ProactiveInquirer-Qwen3-8B
|
| 28 |
+
|
| 29 |
+
**A questioner that asks for what was never requested**
|
| 30 |
+
|
| 31 |
+
[](https://github.com/dolev31/ProactiveInquirer)
|
| 32 |
+
[](https://github.com/dolev31/ProactiveInquirer)
|
| 33 |
+
[](https://www.apache.org/licenses/LICENSE-2.0)
|
| 34 |
+
|
| 35 |
+
</div>
|
| 36 |
+
|
| 37 |
+
This is the trained **questioner** from *Asking for What Was Never Requested: Horizontal and Vertical
|
| 38 |
+
Proactivity in Agents*, by Ido Levy, Asaf Yehudai, Segev Shlomov, Asaf Adi and Leshem Choshen (IBM and the Weizmann Institute of Science). It is a LoRA adapter on
|
| 39 |
+
[Qwen3-8B](https://huggingface.co/Qwen/Qwen3-8B), trained with **Q&D** (questioner and drafter).
|
| 40 |
+
|
| 41 |
+
A tool-using agent usually does what it is asked, yet a task often needs information the user never
|
| 42 |
+
mentions. This model decides, one step at a time, which question to send to the agent's retriever next,
|
| 43 |
+
or that it is time to stop. It goes after two kinds of unstated need:
|
| 44 |
+
|
| 45 |
+
- **Horizontal proactivity:** a need the current state already names. A customer gives a name and a
|
| 46 |
+
ZIP code, so the agent looks up the account.
|
| 47 |
+
- **Vertical proactivity:** a need that only newly found evidence names. The account lists the order,
|
| 48 |
+
the order names the product, and the product lists the size-8 variant.
|
| 49 |
+
|
| 50 |
+

|
| 51 |
+
|
| 52 |
+
## Results
|
| 53 |
+
|
| 54 |
+
These numbers are from the paper, on held-out test splits. The MuSiQue reading compares policies after
|
| 55 |
+
the same number of questions, so asking more cannot pass for asking better. The τ²-bench readings are
|
| 56 |
+
the benchmark's own task success under the same per-dialogue caps.
|
| 57 |
+
|
| 58 |
+
| Setting | Measure | Qwen3-8B, prompted | **This model** |
|
| 59 |
+
|---|---|---|---|
|
| 60 |
+
| MuSiQue, equal retrieval spend | Required evidence recovered | 78% | **90%** |
|
| 61 |
+
| τ²-bench retail (base prompt), no further training | Task success | 13% | **34%** |
|
| 62 |
+
| τ²-bench retail (stop prompt), no further training | Task success | 12% | **32%** |
|
| 63 |
+
|
| 64 |
+
- At equal retrieval spend it improves both forms of proactivity over the same model, prompted, on
|
| 65 |
+
held-out splits of three multi-hop QA benchmarks, and outperforms GPT-OSS-120B, a prompted model 15×
|
| 66 |
+
larger in the same role, on two of the three.
|
| 67 |
+
- The gain comes from what it asks, not from asking more or longer questions: it holds against a
|
| 68 |
+
question-volume control and a length control.
|
| 69 |
+
- Placed in a customer-service agent with a simulated customer, with no further training, it completes
|
| 70 |
+
more retail tasks than GPT-OSS-120B with fewer follow-up turns from the customer.
|
| 71 |
+
|
| 72 |
+

|
| 73 |
+
|
| 74 |
+
## How to use it
|
| 75 |
+
|
| 76 |
+
The questioner reads one prompt, the template it was trained on, and replies with one JSON action. The
|
| 77 |
+
two template files are in [`prompts/`](prompts/).
|
| 78 |
+
|
| 79 |
+
```python
|
| 80 |
+
import re
|
| 81 |
+
|
| 82 |
+
import torch
|
| 83 |
+
from huggingface_hub import hf_hub_download
|
| 84 |
+
from peft import PeftModel
|
| 85 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 86 |
+
|
| 87 |
+
REPO = "dolev31/ProactiveInquirer-Qwen3-8B"
|
| 88 |
+
tok = AutoTokenizer.from_pretrained("Qwen/Qwen3-8B")
|
| 89 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-8B", dtype=torch.bfloat16, device_map="auto")
|
| 90 |
+
model = PeftModel.from_pretrained(model, REPO) # seed 1; add subfolder="seed2" for the second seed
|
| 91 |
+
|
| 92 |
+
template = open(hf_hub_download(REPO, "prompts/inquirer_prompted.txt"), encoding="utf-8").read()
|
| 93 |
+
placebo = open(hf_hub_download(REPO, "prompts/fragment_user_channel_placebo.txt"), encoding="utf-8").read()
|
| 94 |
+
|
| 95 |
+
|
| 96 |
+
def next_action(**state):
|
| 97 |
+
fields = dict(state, user_channel=placebo.strip())
|
| 98 |
+
prompt = re.sub(r"\{\{(\w+)\}\}", lambda m: str(fields[m.group(1)]), template)
|
| 99 |
+
ids = tok.apply_chat_template(
|
| 100 |
+
[{"role": "user", "content": prompt}],
|
| 101 |
+
add_generation_prompt=True,
|
| 102 |
+
enable_thinking=False,
|
| 103 |
+
return_tensors="pt",
|
| 104 |
+
return_dict=True,
|
| 105 |
+
).to(model.device)
|
| 106 |
+
out = model.generate(**ids, max_new_tokens=200, do_sample=False)
|
| 107 |
+
return tok.decode(out[0, ids["input_ids"].shape[1] :], skip_special_tokens=True)
|
| 108 |
+
|
| 109 |
+
|
| 110 |
+
question = "Who was the spouse of the director of the film The Great Flamarion?"
|
| 111 |
+
instructions = (
|
| 112 |
+
"Answer the question using a closed pool of 20 paragraphs. You may issue retrieval "
|
| 113 |
+
"queries against that pool before answering; several paragraphs are distractors, and "
|
| 114 |
+
"the answer usually requires composing facts from more than one of them."
|
| 115 |
+
)
|
| 116 |
+
print(next_action(
|
| 117 |
+
question=question, instructions=instructions, evidence="(nothing retrieved yet)",
|
| 118 |
+
draft="(no draft yet)", history="(nothing asked yet)",
|
| 119 |
+
))
|
| 120 |
+
evidence = (
|
| 121 |
+
"[3f2a9c1b7d4e] The Great Flamarion\n"
|
| 122 |
+
"The Great Flamarion is a 1945 American film noir directed by Anthony Mann and starring "
|
| 123 |
+
"Erich von Stroheim, Mary Beth Hughes and Dan Duryea."
|
| 124 |
+
)
|
| 125 |
+
print(next_action(
|
| 126 |
+
question=question, instructions=instructions, evidence=evidence,
|
| 127 |
+
draft="The film was directed by Anthony Mann; his spouse is not yet known.",
|
| 128 |
+
history="Q1: Who directed the film The Great Flamarion?\n"
|
| 129 |
+
"A1: The Great Flamarion (1945) was directed by Anthony Mann.",
|
| 130 |
+
))
|
| 131 |
+
```
|
| 132 |
+
|
| 133 |
+
Output, with greedy decoding (run on one A100 with transformers 5.17, peft 0.20 and torch 2.14):
|
| 134 |
+
|
| 135 |
+
```json
|
| 136 |
+
{"action": "ASK", "question": "Who directed the film The Great Flamarion?", "rationale": "Identify the director to later find their spouse"}
|
| 137 |
+
{"action": "ASK", "question": "Who was the spouse of film director Anthony Mann?", "rationale": "Need the spouse of the director to answer the task"}
|
| 138 |
+
```
|
| 139 |
+
|
| 140 |
+
The first question is horizontal: the task names the film, so the questioner goes after its director.
|
| 141 |
+
The second is vertical: it uses a value only the retrieved evidence named, Anthony Mann. Compare the
|
| 142 |
+
`action` field case-insensitively, since the model may write `ASK` or `ask`.
|
| 143 |
+
|
| 144 |
+
Inside an agent, feed each answer back: retrieved paragraphs go into `evidence` as `[uid] title` plus
|
| 145 |
+
text, questions and answers into `history` as `Q1:`/`A1:` lines, and the drafter's text into `draft`.
|
| 146 |
+
The [ProactiveInquirer library](https://github.com/dolev31/ProactiveInquirer) runs the whole loop
|
| 147 |
+
(questioner, retriever, drafter, answerer) and the paper's evaluation.
|
| 148 |
+
|
| 149 |
+
To serve it with vLLM, download the adapter and pass it as a LoRA module (rank 32):
|
| 150 |
+
|
| 151 |
+
```bash
|
| 152 |
+
huggingface-cli download dolev31/ProactiveInquirer-Qwen3-8B --local-dir proactive-inquirer
|
| 153 |
+
vllm serve Qwen/Qwen3-8B --enable-lora --max-lora-rank 32 \
|
| 154 |
+
--lora-modules proactive-inquirer=./proactive-inquirer
|
| 155 |
+
```
|
| 156 |
+
|
| 157 |
+
## Training
|
| 158 |
+
|
| 159 |
+
- **Method.** Q&D trains the questioner from the consequences of its own questions. A run is forked
|
| 160 |
+
at one state and continued after several candidate questions (and after stopping). The candidate
|
| 161 |
+
whose continuation retrieves more of the required evidence is preferred, and asking is preferred
|
| 162 |
+
over stopping while evidence is still missing. The drafter is frozen, so every change in what the
|
| 163 |
+
agent holds is caused by a question. No reward model or model judge is involved.
|
| 164 |
+
- **Stages.** Three. First imitation: where the required evidence was already in hand the target is to
|
| 165 |
+
stop, and otherwise the best sampled question, if its consequence score clears a fixed floor. Then
|
| 166 |
+
direct preference optimization on question pairs, and last on question pairs and stop contrasts
|
| 167 |
+
together, which rank asking above stopping at unfinished states. This adapter is the last stage.
|
| 168 |
+
- **Data.** Training splits of MuSiQue, StrategyQA and 2WikiMultiHopQA. The final stage uses 31,473
|
| 169 |
+
preference pairs over 19,124 states (11,305 question-vs-question, 1,249 question-vs-stop and 18,919
|
| 170 |
+
synthetic question-vs-stop pairs). Nothing from τ²-bench is used in training.
|
| 171 |
+
- **Hyperparameters.** LoRA r = 32, α = 64, dropout 0.05 on all attention and MLP projections. DPO with
|
| 172 |
+
the sigmoid loss, β = 0.1, learning rate 5e-6, one epoch, gradient accumulation 16, bf16, sequences up to
|
| 173 |
+
5,120 tokens, Qwen3 chat template with thinking disabled.
|
| 174 |
+
- **Seeds.** The paper reports two training seeds: seed 1 is at the root of this repository, seed 2 in
|
| 175 |
+
[`seed2/`](seed2/).
|
| 176 |
+
|
| 177 |
+
## Limitations
|
| 178 |
+
|
| 179 |
+
- It has learned what to ask more readily than when to stop.
|
| 180 |
+
- The extra evidence it finds does not yet translate into better final answers.
|
| 181 |
+
- User-facing results come from a simulated customer, not from real people.
|
| 182 |
+
- It is a component inside an agent, meant to be called with the template above. It is not a chat
|
| 183 |
+
assistant, and it was trained and evaluated in English.
|
| 184 |
+
|
| 185 |
+
## Citation
|
| 186 |
+
|
| 187 |
+
```bibtex
|
| 188 |
+
@article{levy2026asking,
|
| 189 |
+
title = {Asking for What Was Never Requested: Horizontal and Vertical Proactivity in Agents},
|
| 190 |
+
author = {Levy, Ido and Yehudai, Asaf and Shlomov, Segev and Adi, Asaf and Choshen, Leshem},
|
| 191 |
+
journal = {arXiv preprint},
|
| 192 |
+
year = {2026}
|
| 193 |
+
}
|
| 194 |
+
```
|
| 195 |
+
|
| 196 |
+
## License
|
| 197 |
+
|
| 198 |
+
Apache-2.0, like the base model [Qwen3-8B](https://huggingface.co/Qwen/Qwen3-8B).
|
adapter_config.json
ADDED
|
@@ -0,0 +1,50 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"alora_invocation_tokens": null,
|
| 3 |
+
"alpha_pattern": {},
|
| 4 |
+
"arrow_config": null,
|
| 5 |
+
"auto_mapping": null,
|
| 6 |
+
"base_model_name_or_path": "Qwen/Qwen3-8B",
|
| 7 |
+
"bias": "none",
|
| 8 |
+
"corda_config": null,
|
| 9 |
+
"ensure_weight_tying": false,
|
| 10 |
+
"eva_config": null,
|
| 11 |
+
"exclude_modules": null,
|
| 12 |
+
"fan_in_fan_out": false,
|
| 13 |
+
"inference_mode": true,
|
| 14 |
+
"init_lora_weights": true,
|
| 15 |
+
"layer_replication": null,
|
| 16 |
+
"layers_pattern": null,
|
| 17 |
+
"layers_to_transform": null,
|
| 18 |
+
"loftq_config": {},
|
| 19 |
+
"lora_alpha": 64,
|
| 20 |
+
"lora_bias": false,
|
| 21 |
+
"lora_dropout": 0.05,
|
| 22 |
+
"lora_ga_config": null,
|
| 23 |
+
"megatron_config": null,
|
| 24 |
+
"megatron_core": "megatron.core",
|
| 25 |
+
"modules_to_save": null,
|
| 26 |
+
"monteclora_config": null,
|
| 27 |
+
"peft_type": "LORA",
|
| 28 |
+
"peft_version": "0.20.0",
|
| 29 |
+
"qalora_group_size": 16,
|
| 30 |
+
"r": 32,
|
| 31 |
+
"rank_pattern": {},
|
| 32 |
+
"revision": null,
|
| 33 |
+
"target_modules": [
|
| 34 |
+
"down_proj",
|
| 35 |
+
"v_proj",
|
| 36 |
+
"q_proj",
|
| 37 |
+
"up_proj",
|
| 38 |
+
"o_proj",
|
| 39 |
+
"k_proj",
|
| 40 |
+
"gate_proj"
|
| 41 |
+
],
|
| 42 |
+
"target_parameters": null,
|
| 43 |
+
"task_type": "CAUSAL_LM",
|
| 44 |
+
"trainable_token_indices": null,
|
| 45 |
+
"use_bdlora": null,
|
| 46 |
+
"use_dora": false,
|
| 47 |
+
"use_qalora": false,
|
| 48 |
+
"use_rslora": false,
|
| 49 |
+
"velora_config": null
|
| 50 |
+
}
|
adapter_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c33d3e6e0b7fd666ef99f102e4714849367d55dcbbfc3862a906caf3ec59f5b0
|
| 3 |
+
size 349243752
|
assets/figure1.png
ADDED

|
Git LFS Details
|
assets/results_frontier.png
ADDED
|
example.py
ADDED
|
@@ -0,0 +1,53 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""The model card's example: two steps of the questioner on a two-hop question."""
|
| 2 |
+
|
| 3 |
+
import re
|
| 4 |
+
|
| 5 |
+
import torch
|
| 6 |
+
from huggingface_hub import hf_hub_download
|
| 7 |
+
from peft import PeftModel
|
| 8 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer
|
| 9 |
+
|
| 10 |
+
REPO = "dolev31/ProactiveInquirer-Qwen3-8B"
|
| 11 |
+
tok = AutoTokenizer.from_pretrained("Qwen/Qwen3-8B")
|
| 12 |
+
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen3-8B", dtype=torch.bfloat16, device_map="auto")
|
| 13 |
+
model = PeftModel.from_pretrained(model, REPO) # seed 1; add subfolder="seed2" for the second seed
|
| 14 |
+
|
| 15 |
+
template = open(hf_hub_download(REPO, "prompts/inquirer_prompted.txt"), encoding="utf-8").read()
|
| 16 |
+
placebo = open(hf_hub_download(REPO, "prompts/fragment_user_channel_placebo.txt"), encoding="utf-8").read()
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
def next_action(**state):
|
| 20 |
+
fields = dict(state, user_channel=placebo.strip())
|
| 21 |
+
prompt = re.sub(r"\{\{(\w+)\}\}", lambda m: str(fields[m.group(1)]), template)
|
| 22 |
+
ids = tok.apply_chat_template(
|
| 23 |
+
[{"role": "user", "content": prompt}],
|
| 24 |
+
add_generation_prompt=True,
|
| 25 |
+
enable_thinking=False,
|
| 26 |
+
return_tensors="pt",
|
| 27 |
+
return_dict=True,
|
| 28 |
+
).to(model.device)
|
| 29 |
+
out = model.generate(**ids, max_new_tokens=200, do_sample=False)
|
| 30 |
+
return tok.decode(out[0, ids["input_ids"].shape[1] :], skip_special_tokens=True)
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
question = "Who was the spouse of the director of the film The Great Flamarion?"
|
| 34 |
+
instructions = (
|
| 35 |
+
"Answer the question using a closed pool of 20 paragraphs. You may issue retrieval "
|
| 36 |
+
"queries against that pool before answering; several paragraphs are distractors, and "
|
| 37 |
+
"the answer usually requires composing facts from more than one of them."
|
| 38 |
+
)
|
| 39 |
+
print(next_action(
|
| 40 |
+
question=question, instructions=instructions, evidence="(nothing retrieved yet)",
|
| 41 |
+
draft="(no draft yet)", history="(nothing asked yet)",
|
| 42 |
+
))
|
| 43 |
+
evidence = (
|
| 44 |
+
"[3f2a9c1b7d4e] The Great Flamarion\n"
|
| 45 |
+
"The Great Flamarion is a 1945 American film noir directed by Anthony Mann and starring "
|
| 46 |
+
"Erich von Stroheim, Mary Beth Hughes and Dan Duryea."
|
| 47 |
+
)
|
| 48 |
+
print(next_action(
|
| 49 |
+
question=question, instructions=instructions, evidence=evidence,
|
| 50 |
+
draft="The film was directed by Anthony Mann; his spouse is not yet known.",
|
| 51 |
+
history="Q1: Who directed the film The Great Flamarion?\n"
|
| 52 |
+
"A1: The Great Flamarion (1945) was directed by Anthony Mann.",
|
| 53 |
+
))
|
prompts/fragment_user_channel_placebo.txt
ADDED
|
@@ -0,0 +1,4 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
A NOTE ON THIS SECTION
|
| 2 |
+
This paragraph is reserved. It appears in every one of the conditions so that the surrounding
|
| 3 |
+
text has the same size in each, and it carries no instruction, no preference and no
|
| 4 |
+
information about the task, the evidence or the answer.
|
prompts/inquirer_prompted.txt
ADDED
|
@@ -0,0 +1,48 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
You are the Inquirer. A Drafter is preparing an answer to the task below and you interrogate
|
| 2 |
+
it, one internal question at a time, until the answer would not change if you asked again.
|
| 3 |
+
You are an internal component. You never address the end user and you never write the answer
|
| 4 |
+
yourself. Your only output is the next question, or a decision to stop.
|
| 5 |
+
|
| 6 |
+
TASK
|
| 7 |
+
{{question}}
|
| 8 |
+
|
| 9 |
+
SUITE INSTRUCTIONS
|
| 10 |
+
{{instructions}}
|
| 11 |
+
|
| 12 |
+
EVIDENCE RETRIEVED SO FAR
|
| 13 |
+
{{evidence}}
|
| 14 |
+
|
| 15 |
+
CURRENT DRAFT
|
| 16 |
+
{{draft}}
|
| 17 |
+
|
| 18 |
+
QUESTIONS ALREADY ASKED, AND WHAT CAME BACK
|
| 19 |
+
{{history}}
|
| 20 |
+
|
| 21 |
+
HOW TO CHOOSE
|
| 22 |
+
Ask about a need the task requires and the evidence above does not yet resolve. A need is
|
| 23 |
+
latent when the task does not name it: it becomes visible only once earlier evidence has
|
| 24 |
+
been read. Prefer such a need over one already named in the task statement, and prefer
|
| 25 |
+
either over a rephrasing of a question already asked. Name the entity you are asking about
|
| 26 |
+
explicitly, because the retriever matches text and cannot resolve a pronoun. Cite in
|
| 27 |
+
parent_uids the units whose content made you aware of this need, or leave it empty if the
|
| 28 |
+
need is stated in the task itself.
|
| 29 |
+
|
| 30 |
+
WHEN TO STOP
|
| 31 |
+
Stop when every need the task requires is resolved by the evidence above, or when the next
|
| 32 |
+
question you can think of would return something the evidence already contains. Stopping is
|
| 33 |
+
a decision on the same footing as asking, not a failure.
|
| 34 |
+
|
| 35 |
+
{{user_channel}}
|
| 36 |
+
|
| 37 |
+
RESERVED
|
| 38 |
+
This block is reserved. It appears in every condition so that the amount of text surrounding the
|
| 39 |
+
task is the same in each. It states no requirement and expresses no preference. It carries no
|
| 40 |
+
fact about the task, about the evidence or about the answer. It is not a hint, and nothing in it
|
| 41 |
+
should be treated as one. It describes neither what to ask nor when to stop. It names no entity
|
| 42 |
+
and refers to no document.
|
| 43 |
+
|
| 44 |
+
OUTPUT
|
| 45 |
+
Reply with exactly one JSON object and no other text, no markdown fence, no commentary:
|
| 46 |
+
{"action": "ask", "question": "<a single question>", "rationale": "<one clause>", "parent_uids": ["<uid>"]}
|
| 47 |
+
or
|
| 48 |
+
{"action": "stop", "rationale": "<one clause>"}
|
seed2/adapter_config.json
ADDED
|
@@ -0,0 +1,50 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"alora_invocation_tokens": null,
|
| 3 |
+
"alpha_pattern": {},
|
| 4 |
+
"arrow_config": null,
|
| 5 |
+
"auto_mapping": null,
|
| 6 |
+
"base_model_name_or_path": "Qwen/Qwen3-8B",
|
| 7 |
+
"bias": "none",
|
| 8 |
+
"corda_config": null,
|
| 9 |
+
"ensure_weight_tying": false,
|
| 10 |
+
"eva_config": null,
|
| 11 |
+
"exclude_modules": null,
|
| 12 |
+
"fan_in_fan_out": false,
|
| 13 |
+
"inference_mode": true,
|
| 14 |
+
"init_lora_weights": true,
|
| 15 |
+
"layer_replication": null,
|
| 16 |
+
"layers_pattern": null,
|
| 17 |
+
"layers_to_transform": null,
|
| 18 |
+
"loftq_config": {},
|
| 19 |
+
"lora_alpha": 64,
|
| 20 |
+
"lora_bias": false,
|
| 21 |
+
"lora_dropout": 0.05,
|
| 22 |
+
"lora_ga_config": null,
|
| 23 |
+
"megatron_config": null,
|
| 24 |
+
"megatron_core": "megatron.core",
|
| 25 |
+
"modules_to_save": null,
|
| 26 |
+
"monteclora_config": null,
|
| 27 |
+
"peft_type": "LORA",
|
| 28 |
+
"peft_version": "0.20.0",
|
| 29 |
+
"qalora_group_size": 16,
|
| 30 |
+
"r": 32,
|
| 31 |
+
"rank_pattern": {},
|
| 32 |
+
"revision": null,
|
| 33 |
+
"target_modules": [
|
| 34 |
+
"o_proj",
|
| 35 |
+
"down_proj",
|
| 36 |
+
"up_proj",
|
| 37 |
+
"gate_proj",
|
| 38 |
+
"k_proj",
|
| 39 |
+
"v_proj",
|
| 40 |
+
"q_proj"
|
| 41 |
+
],
|
| 42 |
+
"target_parameters": null,
|
| 43 |
+
"task_type": "CAUSAL_LM",
|
| 44 |
+
"trainable_token_indices": null,
|
| 45 |
+
"use_bdlora": null,
|
| 46 |
+
"use_dora": false,
|
| 47 |
+
"use_qalora": false,
|
| 48 |
+
"use_rslora": false,
|
| 49 |
+
"velora_config": null
|
| 50 |
+
}
|
seed2/adapter_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8e8603830b15353512f96b1d73f6e296bcf482a4fa868656318a15170102243d
|
| 3 |
+
size 349243752
|