---
license: apache-2.0
language:
- en
- zh
- ja
- ko
- fr
- de
- es
- pt
- ru
- ar
- it
- tr
- nl
- hi
tags:
- qwen
- qwen3.5
- gguf
- on-device
- ios
- mobile
- thinking
- hybrid-attention
- deltanet
model_name: Qwen3.5-9B Q4_K_M GGUF
base_model: Qwen/Qwen3.5-9B
quantized_by: jc-builds
pipeline_tag: text-generation
---
# Qwen3.5-9B Q4_K_M GGUF
> **4-bit quantized GGUF** of [Qwen/Qwen3.5-9B](https://huggingface.co/Qwen/Qwen3.5-9B) optimized for **on-device iOS inference** via [llama.cpp](https://github.com/ggml-org/llama.cpp). The most capable model you can run on an iPhone.
| Property | Value |
|---|---|
| **Parameters** | 9 billion |
| **Quantization** | Q4_K_M (4-bit, medium quality) |
| **File Size** | 5.3 GB |
| **Context Window** | 262,144 tokens (native) |
| **Architecture** | Hybrid Gated DeltaNet + Attention |
| **License** | Apache 2.0 |
| **Languages** | 201 languages/dialects |
## Key Features
- **Best-in-Class On-Device AI**: Matches or beats models 9-13x its size
- **Thinking Mode**: `...` chain-of-thought reasoning
- **Hybrid Architecture**: Gated DeltaNet + Attention for efficient, high-quality inference
- **Natively Multimodal**: Trained with early vision fusion
- **Massive Context**: 262K native, extendable to 1M+ with YaRN
## Benchmarks
### Qwen3.5-9B vs Models 9-13x Larger
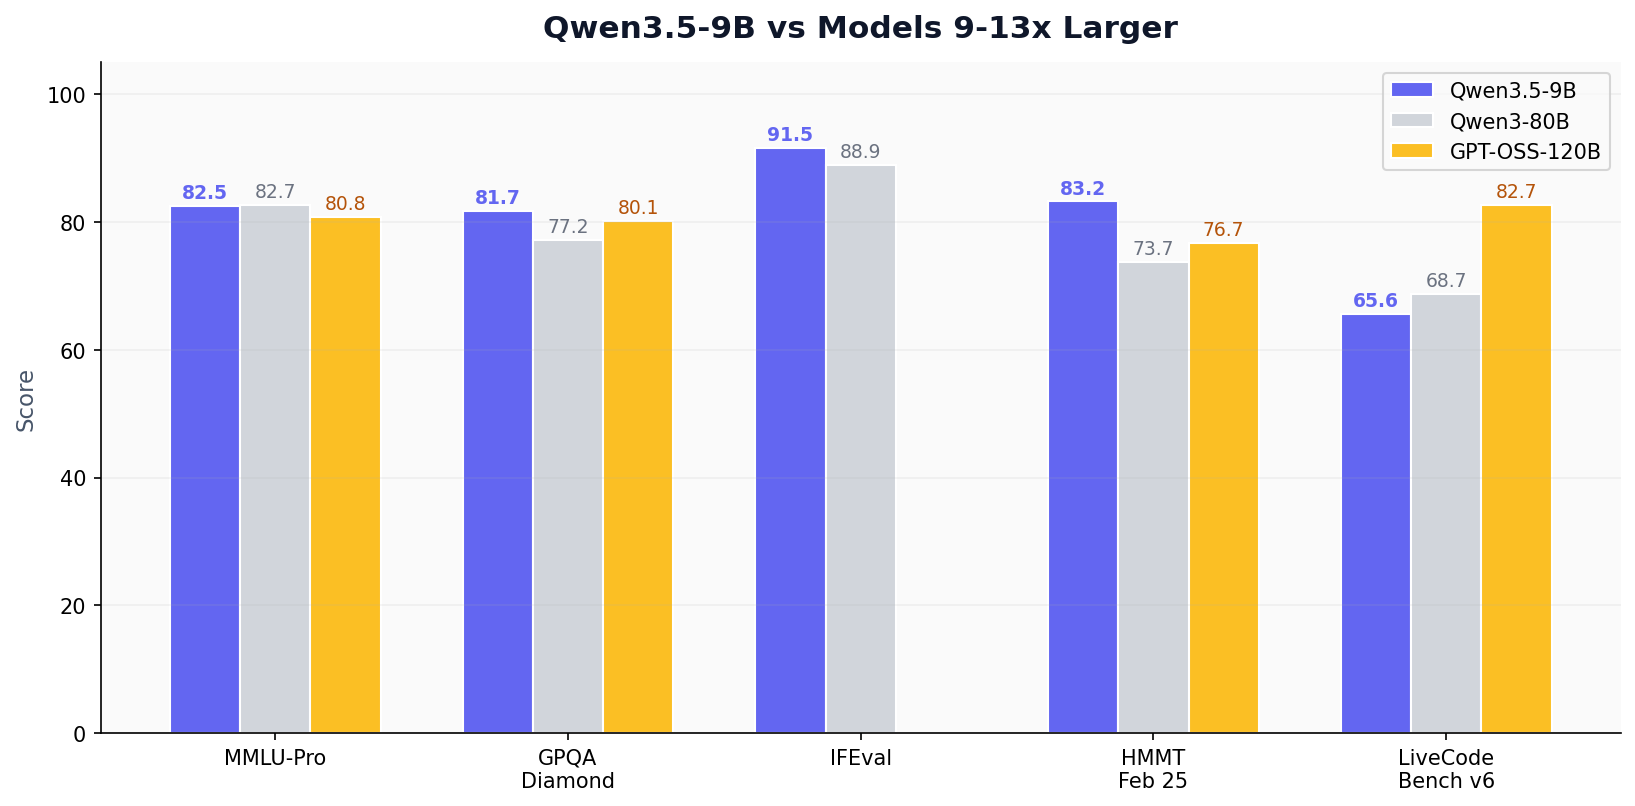
The 9B model **beats Qwen3-80B** on GPQA Diamond (81.7 vs 77.2), IFEval (91.5 vs 88.9), and HMMT math (83.2 vs 73.7). It also **outperforms GPT-OSS-120B** on MMLU-Pro (82.5 vs 80.8) and GPQA Diamond (81.7 vs 80.1).
### MMLU-Pro: Size Class Comparison
| Model | Params | MMLU-Pro |
|---|---|---|
| **Qwen3.5-9B** | **9B** | **82.5** |
| Qwen3-30B | 30B | 80.9 |
| GPT-OSS-120B | 120B | 80.8 |
| Qwen3.5-4B | 4B | 79.1 |
| Gemma2-9B | 9B | ~55* |
| Phi-4-mini | 3.8B | 52.8 |
### On-Device Inference Speed

### Vision Capabilities

The 9B model outperforms the dedicated Qwen3-VL-30B (3x its size) on MMMU, MMMU-Pro, MathVision, OmniDocBench, and VideoMME.
### Full Benchmark Table
| Benchmark | Qwen3.5-9B | Qwen3-30B | Qwen3-80B | GPT-OSS-120B |
|---|---|---|---|---|
| **MMLU-Pro** | 82.5 | 80.9 | 82.7 | 80.8 |
| **MMLU-Redux** | 91.1 | 91.4 | 92.5 | 91.0 |
| **GPQA Diamond** | 81.7 | 73.4 | 77.2 | 80.1 |
| **IFEval** | 91.5 | 88.9 | 88.9 | - |
| **HMMT Feb 25** | 83.2 | 63.1 | 73.7 | 76.7 |
| **HMMT Nov 25** | 82.9 | 73.8 | 81.2 | 81.8 |
| **LiveCodeBench v6** | 65.6 | 66.0 | 68.7 | 82.7 |
| **BFCL-V4 (Tool Use)** | 66.1 | 42.4 | - | - |
| **C-Eval** | 88.2 | 87.4 | 89.7 | 76.2 |
| **SuperGPQA** | 58.2 | 56.8 | 60.8 | 54.6 |
### Vision Benchmarks
| Benchmark | Qwen3.5-9B | Qwen3-VL-30B | GPT-5-Nano |
|---|---|---|---|
| **MMMU** | 78.4 | 76.0 | 75.8 |
| **MMMU-Pro** | 70.1 | 63.0 | 57.2 |
| **MathVision** | 78.9 | 65.7 | 62.2 |
| **OmniDocBench** | 87.7 | 86.8 | 55.9 |
| **VideoMME** | 84.5 | 79.9 | 71.7 |
| **OSWorld** | 41.8 | 30.6 | - |
## Device Compatibility
| Device | RAM | Compatible | Speed |
|---|---|---|---|
| iPhone 16 Pro Max | 8 GB | Yes | ~22-28 tok/s |
| iPhone 16 Pro | 8 GB | Yes | ~20-25 tok/s |
| iPhone 16 / 15 Pro | 8 GB | Possible (tight) | ~15-20 tok/s |
| iPhone 15 and older | 6 GB | Not recommended | - |
| iPad Pro (M-series) | 8-16 GB | Yes | ~25-40 tok/s |
| Mac (Apple Silicon) | 16+ GB | Yes | ~30-50 tok/s |
> **Note**: The 9B model at 5.3 GB requires devices with 8 GB+ RAM. For older devices, use the [Qwen3.5-4B](https://huggingface.co/jc-builds/Qwen3.5-4B-Q4_K_M-GGUF) instead.
## Usage
### With llama.cpp
```bash
# Download
huggingface-cli download jc-builds/Qwen3.5-9B-Q4_K_M-GGUF Qwen3.5-9B-Q4_K_M.gguf
# Run (with thinking mode)
./llama-cli -m Qwen3.5-9B-Q4_K_M.gguf -p "Prove that there are infinitely many primes." -ngl 99
```
### With Ollama
```bash
ollama run qwen3.5:9b
```
### In HaploAI (iOS)
This model is available directly in the [HaploAI](https://apps.apple.com/app/haploai/id6503772307) iOS app (v1.18+). Download it from the model selection page.
## Prompt Format
Uses ChatML format:
```
<|im_start|>system
You are a helpful assistant.<|im_end|>
<|im_start|>user
Hello!<|im_end|>
<|im_start|>assistant
```
### Thinking Mode
```
<|im_start|>assistant
Let me reason through this carefully...
First, assume there are finitely many primes p1, p2, ..., pn.
Consider N = p1 * p2 * ... * pn + 1.
N is not divisible by any pi, so either N is prime or has a prime factor not in our list.
This contradicts our assumption.
There are infinitely many primes. Here is Euclid's classic proof...
```
## Architecture Details
Qwen3.5 introduces a **hybrid Gated DeltaNet + Gated Attention** architecture:
- **3:1 ratio**: 3 layers of Gated DeltaNet (linear attention) per 1 layer of full softmax attention
- **32 total layers**: 8 blocks x (3 DeltaNet + 1 Attention)
- **Hidden dimension**: 4,096
- **Near-constant memory**: DeltaNet layers maintain bounded memory
- **GQA**: 16 query heads, 4 KV heads for attention layers
- **FFN intermediate**: 12,288
- **RoPE**: `theta=10,000,000` with YaRN extension
## Why Qwen3.5-9B?
This model represents a paradigm shift in on-device AI:
1. **9B params that beat 80B**: On GPQA Diamond, IFEval, and math benchmarks
2. **Hybrid attention is the future**: DeltaNet layers provide near-constant memory, enabling huge context on mobile
3. **Natively multimodal**: No separate vision encoder needed for basic image understanding
4. **201 languages**: Broadest language support in its class
5. **Apache 2.0**: Fully open, commercially usable
## Credits
- **Original model**: [Qwen/Qwen3.5-9B](https://huggingface.co/Qwen/Qwen3.5-9B) by Alibaba Cloud
- **GGUF conversion**: [Unsloth](https://huggingface.co/unsloth/Qwen3.5-9B-GGUF)
- **Quantization**: Q4_K_M via llama.cpp
- **Optimized for iOS**: [jc-builds](https://huggingface.co/jc-builds)