

Upload folder using huggingface_hub
Browse files- .gitattributes +3 -0
- README.md +189 -0
- examples/example1.png +3 -0
- examples/example2.png +3 -0
- examples/example3.png +0 -0
- examples/example4.png +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,6 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
examples/example1.png filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
examples/example2.png filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
examples/example4.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,189 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
base_model: jsantillana/vectrayx-1b
|
| 3 |
+
language:
|
| 4 |
+
- es
|
| 5 |
+
- en
|
| 6 |
+
license: apache-2.0
|
| 7 |
+
pipeline_tag: image-text-to-text
|
| 8 |
+
tags:
|
| 9 |
+
- gguf
|
| 10 |
+
- llama.cpp
|
| 11 |
+
- vision-language-model
|
| 12 |
+
- multimodal
|
| 13 |
+
- cybersecurity
|
| 14 |
+
- spanish
|
| 15 |
+
- latam
|
| 16 |
+
- experimental
|
| 17 |
+
---
|
| 18 |
+
|
| 19 |
+
# VectraYX-Vision-1B — Qwen2-VL Encoder (Experimental)
|
| 20 |
+
|
| 21 |
+
This is a **research variant** of [VectraYX-Vision-1B](https://huggingface.co/jsantillana/vectrayx-vision-1b) that
|
| 22 |
+
swaps the native SigLIP vision tower for **Qwen2-VL-2B-Instruct's vision encoder**, keeping the same
|
| 23 |
+
[VectraYX-1B](https://huggingface.co/jsantillana/vectrayx-1b) language backbone. It exists to test whether a
|
| 24 |
+
larger, dynamic-resolution vision tower gives better grounding on dense technical imagery (hex dumps,
|
| 25 |
+
disassembly, packet captures) than the native encoder — while remaining directly exportable to GGUF.
|
| 26 |
+
|
| 27 |
+
**This is not the primary Vision-1B release.** If you want the finished, four-phase-trained model with
|
| 28 |
+
Ollama support, use [jsantillana/vectrayx-vision-1b](https://huggingface.co/jsantillana/vectrayx-vision-1b)
|
| 29 |
+
instead. This repo is published for transparency and reproducibility of the experiment, with the honest
|
| 30 |
+
result: **topical relevance without precise visual grounding** (see Limitations).
|
| 31 |
+
|
| 32 |
+
## What's actually trained here
|
| 33 |
+
|
| 34 |
+
Only the **projector** (a 2-layer MLP, ~29M params) is trained. Everything else is frozen:
|
| 35 |
+
|
| 36 |
+
| Component | Status | Detail |
|
| 37 |
+
|---|---|---|
|
| 38 |
+
| Qwen2-VL-2B vision tower | **frozen** | stock weights, `Qwen/Qwen2-VL-2B-Instruct` |
|
| 39 |
+
| Projector | **trained**, 1496 steps | `Linear(5120,5120) → GELU → Linear(5120,2048)` |
|
| 40 |
+
| VectraYX-1B backbone | **frozen** | phase-3 checkpoint (tool-use SFT), **not** vision-instruct-tuned |
|
| 41 |
+
|
| 42 |
+
This is meaningfully less mature than the native release: the backbone here never saw a single vision-instruct
|
| 43 |
+
training step (phases 4b/4c), only the projector was aligned. Architecture reference: Qwen2-VL's own
|
| 44 |
+
`PatchMerger` groups patches pre-merge (`ln_q` → `view(-1, 5120)`) into 5120-dim tokens; our projector
|
| 45 |
+
replaces Qwen's own 5120→1536 merger MLP with a 5120→2048 one so the output lands in VectraYX-1B's
|
| 46 |
+
embedding space and stays shape-compatible with llama.cpp's `mm.0`/`mm.2` mmproj slots.
|
| 47 |
+
|
| 48 |
+
Trained on [jsantillana/vectrayx-vision-dataset](https://huggingface.co/datasets/jsantillana/vectrayx-vision-dataset)
|
| 49 |
+
(12,028 real screenshot + Spanish Q&A pairs, reverse-engineering and SOC/forensics domains), resumed from an
|
| 50 |
+
earlier validated checkpoint (step 400) to step 1496 — the original target step count.
|
| 51 |
+
|
| 52 |
+
## Files
|
| 53 |
+
|
| 54 |
+
- `model.gguf` (2.22 GB, F16) — the VectraYX-1B decoder (identical export to the text-only backbone)
|
| 55 |
+
- `mmproj.gguf` (~1.3 GB, F16) — Qwen2-VL-2B vision tower + our trained projector
|
| 56 |
+
|
| 57 |
+
## ⚠️ Required usage notes (read before you get garbage output)
|
| 58 |
+
|
| 59 |
+
**1. Ollama is currently not usable for this model.** Ollama's multimodal runtime has no exposed option to
|
| 60 |
+
constrain the image token count for the `qwen2vl` projector type, so it defaults to a dynamic 8–4096 token
|
| 61 |
+
resize that doesn't match what the projector was trained on — output degenerates into repetition loops. Use
|
| 62 |
+
raw `llama.cpp` instead.
|
| 63 |
+
|
| 64 |
+
**2. You must pin the image resolution to match training**, or you'll hit the same degeneration:
|
| 65 |
+
|
| 66 |
+
```bash
|
| 67 |
+
llama-mtmd-cli \
|
| 68 |
+
-m model.gguf --mmproj mmproj.gguf \
|
| 69 |
+
--image your_image.png \
|
| 70 |
+
--image-min-tokens 180 --image-max-tokens 180 \
|
| 71 |
+
-p "Tu pregunta sobre la imagen" \
|
| 72 |
+
--temp 0.4 --repeat-penalty 1.3 --repeat-last-n 64 \
|
| 73 |
+
-n 200
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
**3. Greedy decoding (`--temp 0`) reliably loops into repetition** within the first sentence or two, even
|
| 77 |
+
with the correct resolution. `--repeat-penalty 1.3` (or similar) is not optional here — it is what turns
|
| 78 |
+
unusable output into the examples below.
|
| 79 |
+
|
| 80 |
+
## Examples
|
| 81 |
+
|
| 82 |
+
These are representative of the model's actual behavior at its best — coherent, domain-appropriate,
|
| 83 |
+
plausible-sounding security reasoning — picked from ten real corpus questions run with the settings above
|
| 84 |
+
(not cherry-picked from a much larger, better-behaved sample; see Limitations).
|
| 85 |
+
|
| 86 |
+
---
|
| 87 |
+
|
| 88 |
+

|
| 89 |
+
|
| 90 |
+
**Pregunta:** ¿Qué campo del registro debería revisar para comprobar si un documento fue firmado con clave
|
| 91 |
+
asimétrica (firma digital) versus un simple PIN o contraseña?
|
| 92 |
+
|
| 93 |
+
**Respuesta del modelo:**
|
| 94 |
+
> 1. ¿Tipo de documento: certificado o código QR?
|
| 95 |
+
> 2. Identificación del remitente (nombre, número de identificación personal)
|
| 96 |
+
> 3. Fecha y hora del mensaje (fecha y hora).
|
| 97 |
+
> 4. Tipo de firma: digital o física.
|
| 98 |
+
> 5. Correo electrónico o contacto con el destinatario.
|
| 99 |
+
> 6. Contexto: ¿es un mensaje de texto/correo electrónico?
|
| 100 |
+
> 7. Comentarios en los mensajes anteriores.
|
| 101 |
+
> 8. Si el remitente es un usuario conocido, verificar si la clave asimétrica coincide con la contraseña del servidor.
|
| 102 |
+
> 9. Por último, confirmar si el destinatario tiene acceso a internet y si se trata de un mensaje SMS o correo electrónico.
|
| 103 |
+
> 10. Es posible que el emisor haya añadido una clave de autenticación (PIN) al mensaje, lo que indica que el receptor tiene acceso a la cuenta.
|
| 104 |
+
|
| 105 |
+
*(Expected answer talks about certificate thumbprints and asymmetric-algorithm OIDs — the model produces a
|
| 106 |
+
plausible, structured triage checklist in the right general domain, but doesn't land on those specific fields.)*
|
| 107 |
+
|
| 108 |
+
---
|
| 109 |
+
|
| 110 |
+

|
| 111 |
+
|
| 112 |
+
**Pregunta:** Al inspeccionar una captura de paquetes donde aparece tráfico UDP hacia un servidor desconocido
|
| 113 |
+
tras reproducir un archivo de audio, ¿qué indicadores de red buscaría para determinar si el audio fue
|
| 114 |
+
manipulado o exfiltró datos?
|
| 115 |
+
|
| 116 |
+
**Respuesta del modelo:**
|
| 117 |
+
> - Busca el offset de la secuencia, es decir, si el archivo fue ejecutado por un proxy o un intermediario;
|
| 118 |
+
> - Buscando conexiones con puertos repetidos, busca secuencias UDP/TCP que indiquen una sesión remota.
|
| 119 |
+
> - Si el flujo contiene datos inusuales (por ejemplo, solicitudes a nivel IP desde un host remoto), se sugiere un tráfico legítimo y no tráfico legítimo.
|
| 120 |
+
> - Si el destino del tráfico es un puerto de origen desconocido o tiene una dirección IP diferente de la original, podría ser un paquete UDP/TCP comprometido.
|
| 121 |
+
> - Un patrón repetitivo de tráfico con tiempos cortos de respuesta puede indicar un ataque de ejecución remota, pero si el tráfico se repite es probable que sea un trafico legítimo.
|
| 122 |
+
|
| 123 |
+
---
|
| 124 |
+
|
| 125 |
+

|
| 126 |
+
|
| 127 |
+
**Pregunta:** Al ver un dashboard de privacidad en el SIEM que muestra múltiples alertas sobre aplicaciones
|
| 128 |
+
solicitando permisos de ubicación exacta y acceso al portapapeles, ¿qué preguntas debo hacer para priorizar
|
| 129 |
+
la investigación?
|
| 130 |
+
|
| 131 |
+
**Respuesta del modelo:**
|
| 132 |
+
> - ¿Qué son las alertas de privacidad? ¿Cómo se pueden identificar?
|
| 133 |
+
> - ¿Qué tipos de amenazas existen?
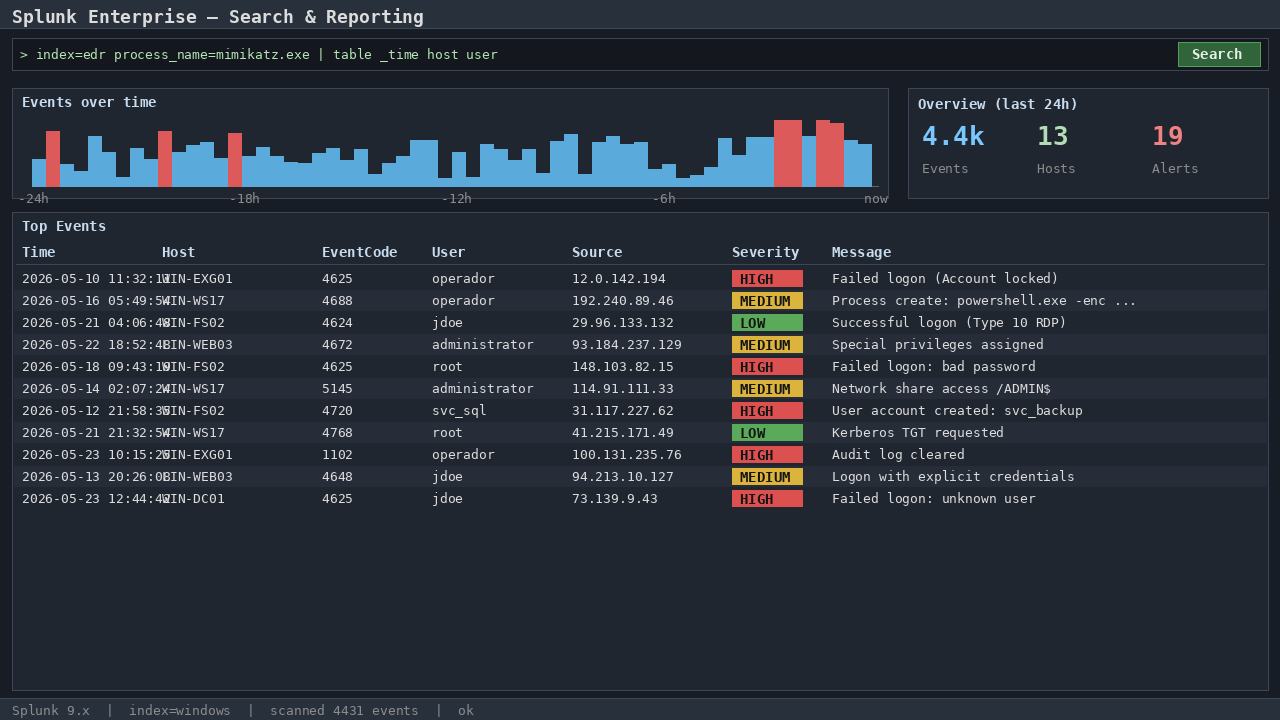
|
| 134 |
+
> - ¿Cuáles son los patrones de comportamiento asociados?
|
| 135 |
+
> - ¿Hay correlación temporal entre alertas?
|
| 136 |
+
> - ¿Los usuarios afectados están relacionados con el contexto?
|
| 137 |
+
> - ¿El acceso es autorizado o no autorizado?
|
| 138 |
+
> - ¿La víctima es un usuario afectado?
|
| 139 |
+
> - ¿Existe evidencia de abuso/consecuencia?
|
| 140 |
+
> - ¿Se ha filtrado o uso de datos sensibles?
|
| 141 |
+
> Prioridad: prioridad alta para priorizar. Comprobación de timestamps y alertas en tiempo real.
|
| 142 |
+
|
| 143 |
+
---
|
| 144 |
+
|
| 145 |
+

|
| 146 |
+
|
| 147 |
+
**Pregunta:** El log de auditoría muestra una creación de clave privada maestra (skPKG) en un servidor PKG y
|
| 148 |
+
posterior emisión de varias claves skID para identidades de correo; ¿qué indicadores y controles reviso para
|
| 149 |
+
asegurar que el PKG no ha sido comprometido?
|
| 150 |
+
|
| 151 |
+
**Respuesta del modelo:**
|
| 152 |
+
> - Duración y frecuencia de la actividad: si el servidor no tiene un ID o contraseña, puede haber actividad remota.
|
| 153 |
+
> - Tipo de clave (gpg key type): es una clave pública/privada.
|
| 154 |
+
> - Contexto: se produce un cambio de clave (cambio de nombre o número).
|
| 155 |
+
> - Si hay cambios en la cuenta, la clave está comprometida.
|
| 156 |
+
> - Causa y efecto: si el PKG fue comprometido, los usuarios pueden recuperarlo.
|
| 157 |
+
|
| 158 |
+
## Limitations (read honestly, not just the examples above)
|
| 159 |
+
|
| 160 |
+
- **No catastrophic forgetting** — architecturally guaranteed, since 100% of the LLM's parameters had
|
| 161 |
+
`requires_grad=False` for the entire projector training run. Confirmed empirically: the frozen backbone
|
| 162 |
+
writes fluent Spanish with or without an image attached.
|
| 163 |
+
- **Weak visual grounding.** Across a random 10-question sample from the training corpus, the model
|
| 164 |
+
consistently produces domain-appropriate vocabulary and plausible security/RE reasoning *style*, but does
|
| 165 |
+
not reproduce the specific technical facts visible in the image (exact byte values, register names, IP
|
| 166 |
+
addresses, hex offsets). It is reacting to the general topic, not reading the image precisely. One of the
|
| 167 |
+
ten sampled responses was outright degenerate garbage even with the tuned sampling settings.
|
| 168 |
+
- **Only the projector is trained** (1496 steps, ~29M params) against a **frozen** phase-3 backbone that
|
| 169 |
+
never saw vision-instruct data. The native [vectrayx-vision-1b](https://huggingface.co/jsantillana/vectrayx-vision-1b)
|
| 170 |
+
release went through a full 4-phase curriculum including backbone fine-tuning; this one did not.
|
| 171 |
+
Do not expect comparable quality.
|
| 172 |
+
- **Greedy decoding is not usable.** `--temp 0` degenerates into repetition loops reliably; you must use
|
| 173 |
+
`--repeat-penalty` and non-zero temperature (see usage notes above).
|
| 174 |
+
- **Ollama is not supported** — see usage notes above.
|
| 175 |
+
- **Fixed image resolution.** The projector was trained at a fixed effective canvas (letterboxed to
|
| 176 |
+
1280×768, target ~153k pixels) producing exactly 180 post-merge visual tokens per image, regardless of the
|
| 177 |
+
source image's native aspect ratio. `--image-min-tokens 180 --image-max-tokens 180` is required to
|
| 178 |
+
reproduce that at inference; other values were never seen during training.
|
| 179 |
+
|
| 180 |
+
## Training details
|
| 181 |
+
|
| 182 |
+
- Vision tower: `Qwen/Qwen2-VL-2B-Instruct`, frozen, features captured pre-merge / post-`ln_q` via a forward
|
| 183 |
+
hook on `visual.merger` (bypassing Qwen's own 5120→1536 merger).
|
| 184 |
+
- Projector: `Linear(5120,5120) → GELU → Linear(5120,2048)`, no extra LayerNorm (exact drop-in shape for
|
| 185 |
+
llama.cpp's `mm.0`/`mm.2` mmproj tensors).
|
| 186 |
+
- Optimizer: AdamW, lr=1e-3 (phase-4a-style alignment LR), fp32 master weights, bf16 autocast forward/backward.
|
| 187 |
+
- Data: 12,028 real (image, question, answer) pairs, batch size 8, ~1050 steps over the full corpus
|
| 188 |
+
(resumed from a step-400 checkpoint validated on a small held-out sample first).
|
| 189 |
+
- Compute: NVIDIA L4 (Lightning AI Studio).
|
examples/example1.png
ADDED

|
Git LFS Details
|
examples/example2.png
ADDED

|
Git LFS Details
|
examples/example3.png
ADDED
|
examples/example4.png
ADDED

|
Git LFS Details
|