Feature Extraction
Transformers
Safetensors
GGUF
English
Korean
qwen3_5_text
qwen3.5
backbone
headless
classification-backbone
knowledge-distillation
model-compression
vocabulary-pruning
korean
edge-ai
conversational
Instructions to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with libraries, inference providers, notebooks, and local apps. Follow these links to get started.
- Libraries
- Transformers
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with Transformers:
# Use a pipeline as a high-level helper from transformers import pipeline pipe = pipeline("feature-extraction", model="mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless") messages = [ {"role": "user", "content": "Who are you?"}, ] pipe(messages)# Load model directly from transformers import AutoTokenizer, AutoModel tokenizer = AutoTokenizer.from_pretrained("mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless") model = AutoModel.from_pretrained("mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless", device_map="auto") messages = [ {"role": "user", "content": "Who are you?"}, ] inputs = tokenizer.apply_chat_template( messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt", ).to(model.device) outputs = model.generate(**inputs, max_new_tokens=40) print(tokenizer.decode(outputs[0][inputs["input_ids"].shape[-1]:])) - Notebooks
- Google Colab
- Kaggle
- Local Apps Settings
- llama.cpp
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with llama.cpp:
Install (macOS, Linux)
curl -LsSf https://llama.app/install.sh | sh # Start a local OpenAI-compatible server with a web UI: llama serve -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0 # Run inference directly in the terminal: llama cli -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Install from WinGet (Windows)
winget install llama.cpp # Start a local OpenAI-compatible server with a web UI: llama serve -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0 # Run inference directly in the terminal: llama cli -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Use pre-built binary
# Download pre-built binary from: # https://github.com/ggerganov/llama.cpp/releases # Start a local OpenAI-compatible server with a web UI: ./llama-server -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0 # Run inference directly in the terminal: ./llama-cli -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Build from source code
git clone https://github.com/ggerganov/llama.cpp.git cd llama.cpp cmake -B build cmake --build build -j --target llama-server llama-cli # Start a local OpenAI-compatible server with a web UI: ./build/bin/llama-server -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0 # Run inference directly in the terminal: ./build/bin/llama-cli -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Use Docker
docker model run hf.co/mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
- LM Studio
- Jan
- Ollama
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with Ollama:
ollama run hf.co/mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
- Unsloth Desktop
- Pi
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with Pi:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Configure the model in Pi
# Install Pi: npm install -g @earendil-works/pi-coding-agent # Add to ~/.pi/agent/models.json: { "providers": { "llama-cpp": { "baseUrl": "http://localhost:8080/v1", "api": "openai-completions", "apiKey": "none", "models": [ { "id": "mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0" } ] } } }Run Pi
# Start Pi in your project directory: pi
- Docker Model Runner
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with Docker Model Runner:
docker model run hf.co/mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
- Lemonade
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with Lemonade:
Pull the model
# Download Lemonade from https://lemonade-server.ai/ lemonade pull mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Run and chat with the model
lemonade run user.qwen3.5-4l-vocab40k-en-ko-headless-Q8_0
List all available models
lemonade list
- Hermes Agent
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with Hermes Agent:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Configure Hermes
# Install Hermes: curl -fsSL https://hermes-agent.nousresearch.com/install.sh | bash hermes setup # Point Hermes at the local server: hermes config set model.provider custom hermes config set model.base_url http://127.0.0.1:8080/v1 hermes config set model.default mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Run Hermes
hermes
- Atomic Chat
- OpenClaw
How to use mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless with OpenClaw:
Start the llama.cpp server
# Install llama.cpp: brew install llama.cpp # Start a local OpenAI-compatible server: llama serve -hf mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0
Configure OpenClaw
# Install OpenClaw: npm install -g openclaw@latest # Register the local server and set it as the default model: openclaw onboard --non-interactive --mode local \ --auth-choice custom-api-key \ --custom-base-url http://127.0.0.1:8080/v1 \ --custom-model-id "mp-juuuns/qwen3.5-4l-vocab40k-en-ko-headless:Q8_0" \ --custom-provider-id llama-cpp \ --custom-compatibility openai \ --custom-text-input \ --accept-risk \ --skip-health
Run OpenClaw
openclaw agent --local --agent main --message "Hello from Hugging Face"
Update root 4L base to token-string-remapped 128k vocabulary
Browse filesPreserve nested specialized and distillation trees; update root weights, tokenizer, README, figures, manifest, and remove obsolete root full-tokenizer files.
- SHA256SUMS +2 -2
- benchmark/figures/v128k_quality_storage.png +0 -0
- release_manifest.json +2 -2
SHA256SUMS
CHANGED
|
@@ -21,7 +21,7 @@ f2a34cbcd700b2663cf761a5fb1dbd3aa99f310a96d4b4477a3a4529bee1a1b3 benchmark/figu
|
|
| 21 |
3d2c9fcf9c6cc7da1a885968b70a42eaa38659d317c9d3290a2b3066f3f9ee6a benchmark/figures/source_summary.json
|
| 22 |
078b4f34897e0a1b9bcff66ce21ba0feb28d72c86eaa8cef608f110c48f52f2e benchmark/figures/v128k_compression.csv
|
| 23 |
014da12a435e3404b31470e2642d180dc111eb608fb8513fd993097019698b7a benchmark/figures/v128k_quality_efficiency.csv
|
| 24 |
-
|
| 25 |
66d5da977653e326893da3d34b5babb2e078ca1381753112e74ef76bace80193 benchmark/figures/v128k_vocabulary_size.png
|
| 26 |
ffc21be32b2106c7bf1df3854097a975ac370da01ac1b732eb5c2ba9075ddeda benchmark/per_label_metrics.csv
|
| 27 |
c8e3876abf6cfe960c9332d3bc9d1fbde2f3213f3111351acf83b21bbb184049 benchmark/per_label_summary.csv
|
|
@@ -87,7 +87,7 @@ ec734855870758cbfef99031dac2ded85b54c496532e5c514a9a4f63287c3493 provenance/bas
|
|
| 87 |
b9ce99b993c4f4563bc2521fc731bfd82f5e8149c141133599fbd8f982ba43d9 provenance/task_agnostic_stages/24to8.json
|
| 88 |
ec734855870758cbfef99031dac2ded85b54c496532e5c514a9a4f63287c3493 provenance/task_agnostic_stages/6to4.json
|
| 89 |
65e5383afbbcfe0b7dd78a5411c319ed6bf2586659fb1892aca9ecbd5dfd4993 provenance/task_agnostic_stages/8to6.json
|
| 90 |
-
|
| 91 |
7b48e7811e56e552fc4aef44189e1d7c9b1352c85d2b3f10ff0bdd1ea5cdd824 requirements.txt
|
| 92 |
dd2b27bbd4f5f650c7200300013ef03ee01efe620b128343163521bf04806fc8 tokenizer.json
|
| 93 |
2215318fe27878ec67e772931bb5f40a98658348d33f2672a575f766a2190d35 tokenizer_config.json
|
|
|
|
| 21 |
3d2c9fcf9c6cc7da1a885968b70a42eaa38659d317c9d3290a2b3066f3f9ee6a benchmark/figures/source_summary.json
|
| 22 |
078b4f34897e0a1b9bcff66ce21ba0feb28d72c86eaa8cef608f110c48f52f2e benchmark/figures/v128k_compression.csv
|
| 23 |
014da12a435e3404b31470e2642d180dc111eb608fb8513fd993097019698b7a benchmark/figures/v128k_quality_efficiency.csv
|
| 24 |
+
644e5b7469c0b4e0b63d5ecaa1c0f2fc8e07af8bb5d9e4d3ae5a88166de374f3 benchmark/figures/v128k_quality_storage.png
|
| 25 |
66d5da977653e326893da3d34b5babb2e078ca1381753112e74ef76bace80193 benchmark/figures/v128k_vocabulary_size.png
|
| 26 |
ffc21be32b2106c7bf1df3854097a975ac370da01ac1b732eb5c2ba9075ddeda benchmark/per_label_metrics.csv
|
| 27 |
c8e3876abf6cfe960c9332d3bc9d1fbde2f3213f3111351acf83b21bbb184049 benchmark/per_label_summary.csv
|
|
|
|
| 87 |
b9ce99b993c4f4563bc2521fc731bfd82f5e8149c141133599fbd8f982ba43d9 provenance/task_agnostic_stages/24to8.json
|
| 88 |
ec734855870758cbfef99031dac2ded85b54c496532e5c514a9a4f63287c3493 provenance/task_agnostic_stages/6to4.json
|
| 89 |
65e5383afbbcfe0b7dd78a5411c319ed6bf2586659fb1892aca9ecbd5dfd4993 provenance/task_agnostic_stages/8to6.json
|
| 90 |
+
04dcec9ca0b06a4d0bdb1f1a1cbe01079ea99f31fee42601686933342b219a90 release_manifest.json
|
| 91 |
7b48e7811e56e552fc4aef44189e1d7c9b1352c85d2b3f10ff0bdd1ea5cdd824 requirements.txt
|
| 92 |
dd2b27bbd4f5f650c7200300013ef03ee01efe620b128343163521bf04806fc8 tokenizer.json
|
| 93 |
2215318fe27878ec67e772931bb5f40a98658348d33f2672a575f766a2190d35 tokenizer_config.json
|
benchmark/figures/v128k_quality_storage.png
CHANGED
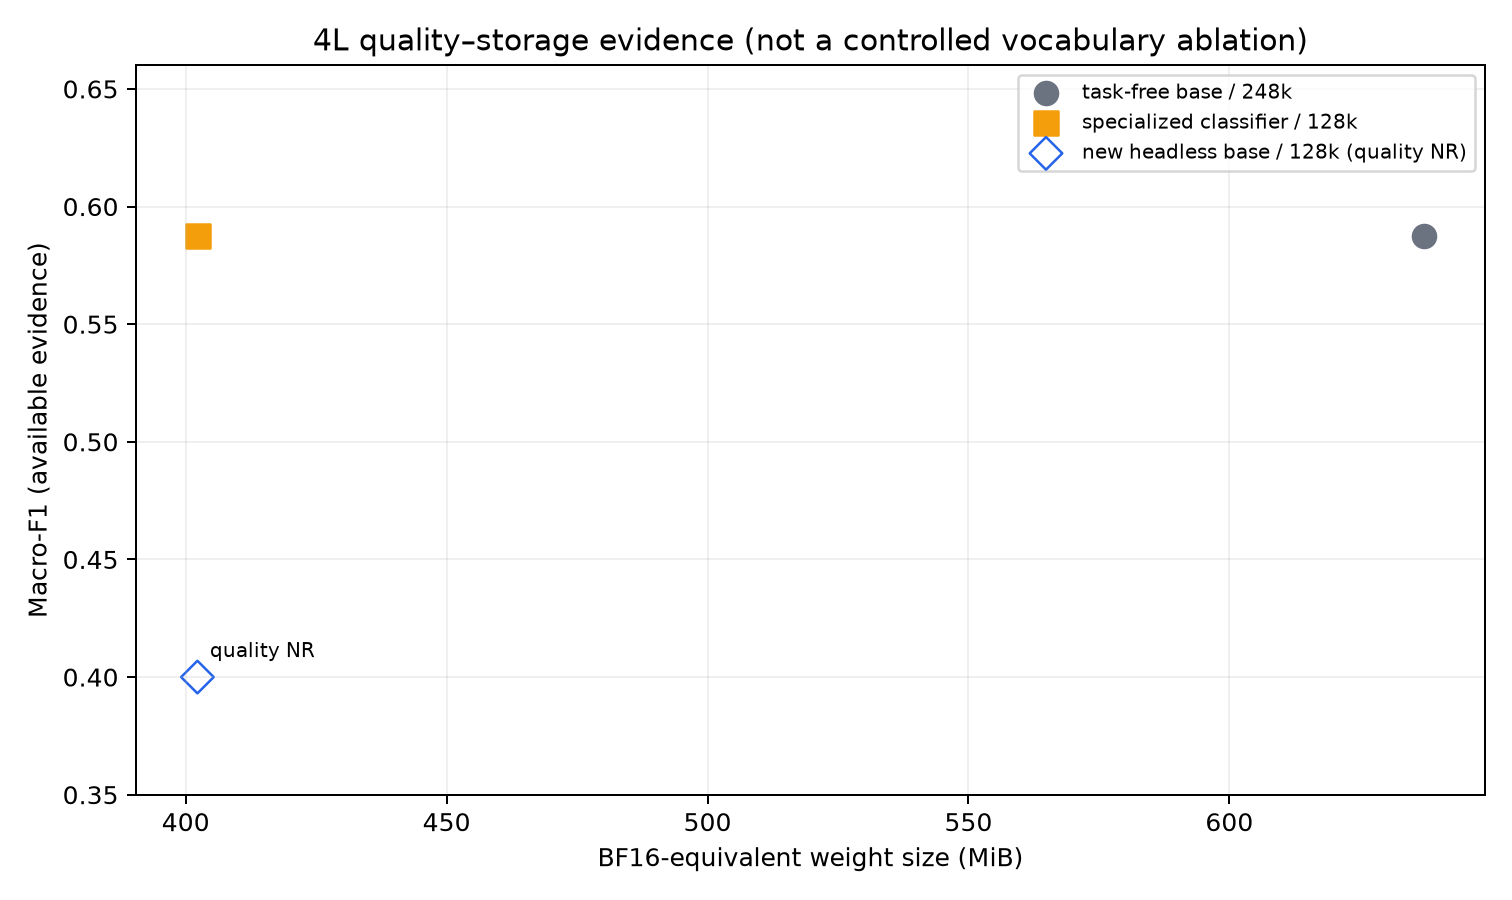
|
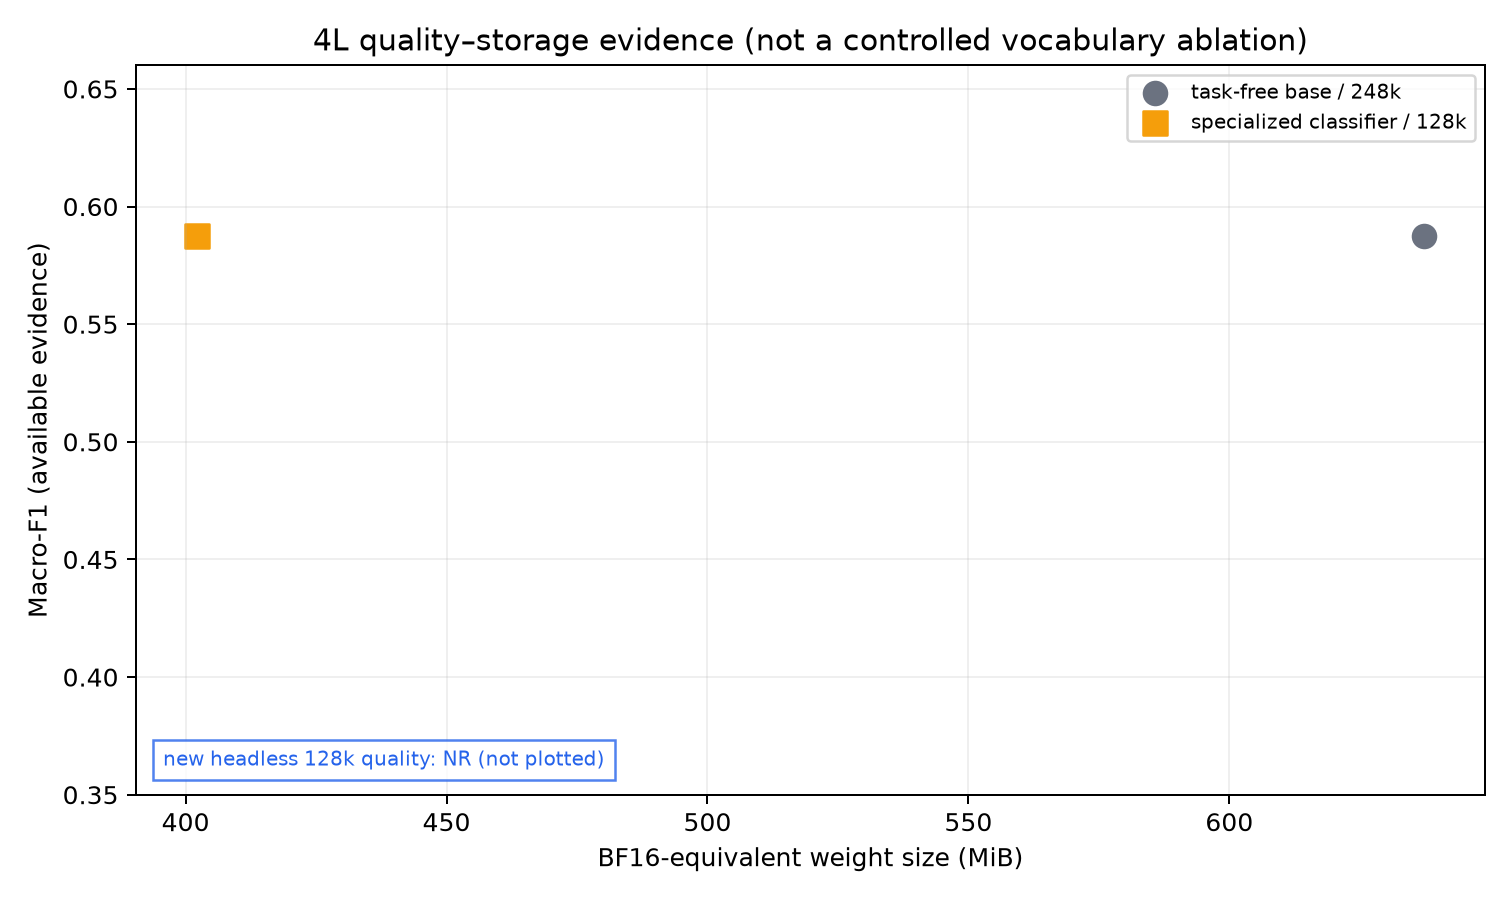
|
release_manifest.json
CHANGED
|
@@ -179,8 +179,8 @@
|
|
| 179 |
"path": "benchmark/figures/v128k_quality_storage.png",
|
| 180 |
"role": "generated v128k update artifact",
|
| 181 |
"source": "generated",
|
| 182 |
-
"bytes":
|
| 183 |
-
"sha256": "
|
| 184 |
},
|
| 185 |
{
|
| 186 |
"path": "benchmark/figures/v128k_vocabulary_size.png",
|
|
|
|
| 179 |
"path": "benchmark/figures/v128k_quality_storage.png",
|
| 180 |
"role": "generated v128k update artifact",
|
| 181 |
"source": "generated",
|
| 182 |
+
"bytes": 73388,
|
| 183 |
+
"sha256": "644e5b7469c0b4e0b63d5ecaa1c0f2fc8e07af8bb5d9e4d3ae5a88166de374f3"
|
| 184 |
},
|
| 185 |
{
|
| 186 |
"path": "benchmark/figures/v128k_vocabulary_size.png",
|