

Benchmark-as-Teacher
Collection
Turning benchmark to data generation and post-training infrastructure in agentic AI • 9 items • Updated • 1
docker model run hf.co/MitakaKuma/BaT-Qwen3.5-9B-0815This repository is publicly accessible, but you have to accept the conditions to access its files and content.
Please provide your affiliation and a brief description of your research. Access requests are reviewed manually.
Log in or Sign Up to review the conditions and access this model content.
BaT develops agentic workflow skills through stage-level feedback, building on Qwen3.5-9B.
Training scope: BaT post-training data covers agentic skills only, not professional medical reasoning or medical knowledge. Benchmark performance does not establish clinical expertise. Research use only; not for diagnosis or treatment.
Original paper results; checkpoint correspondence remains unverified. Scores: 0–100, higher is better.
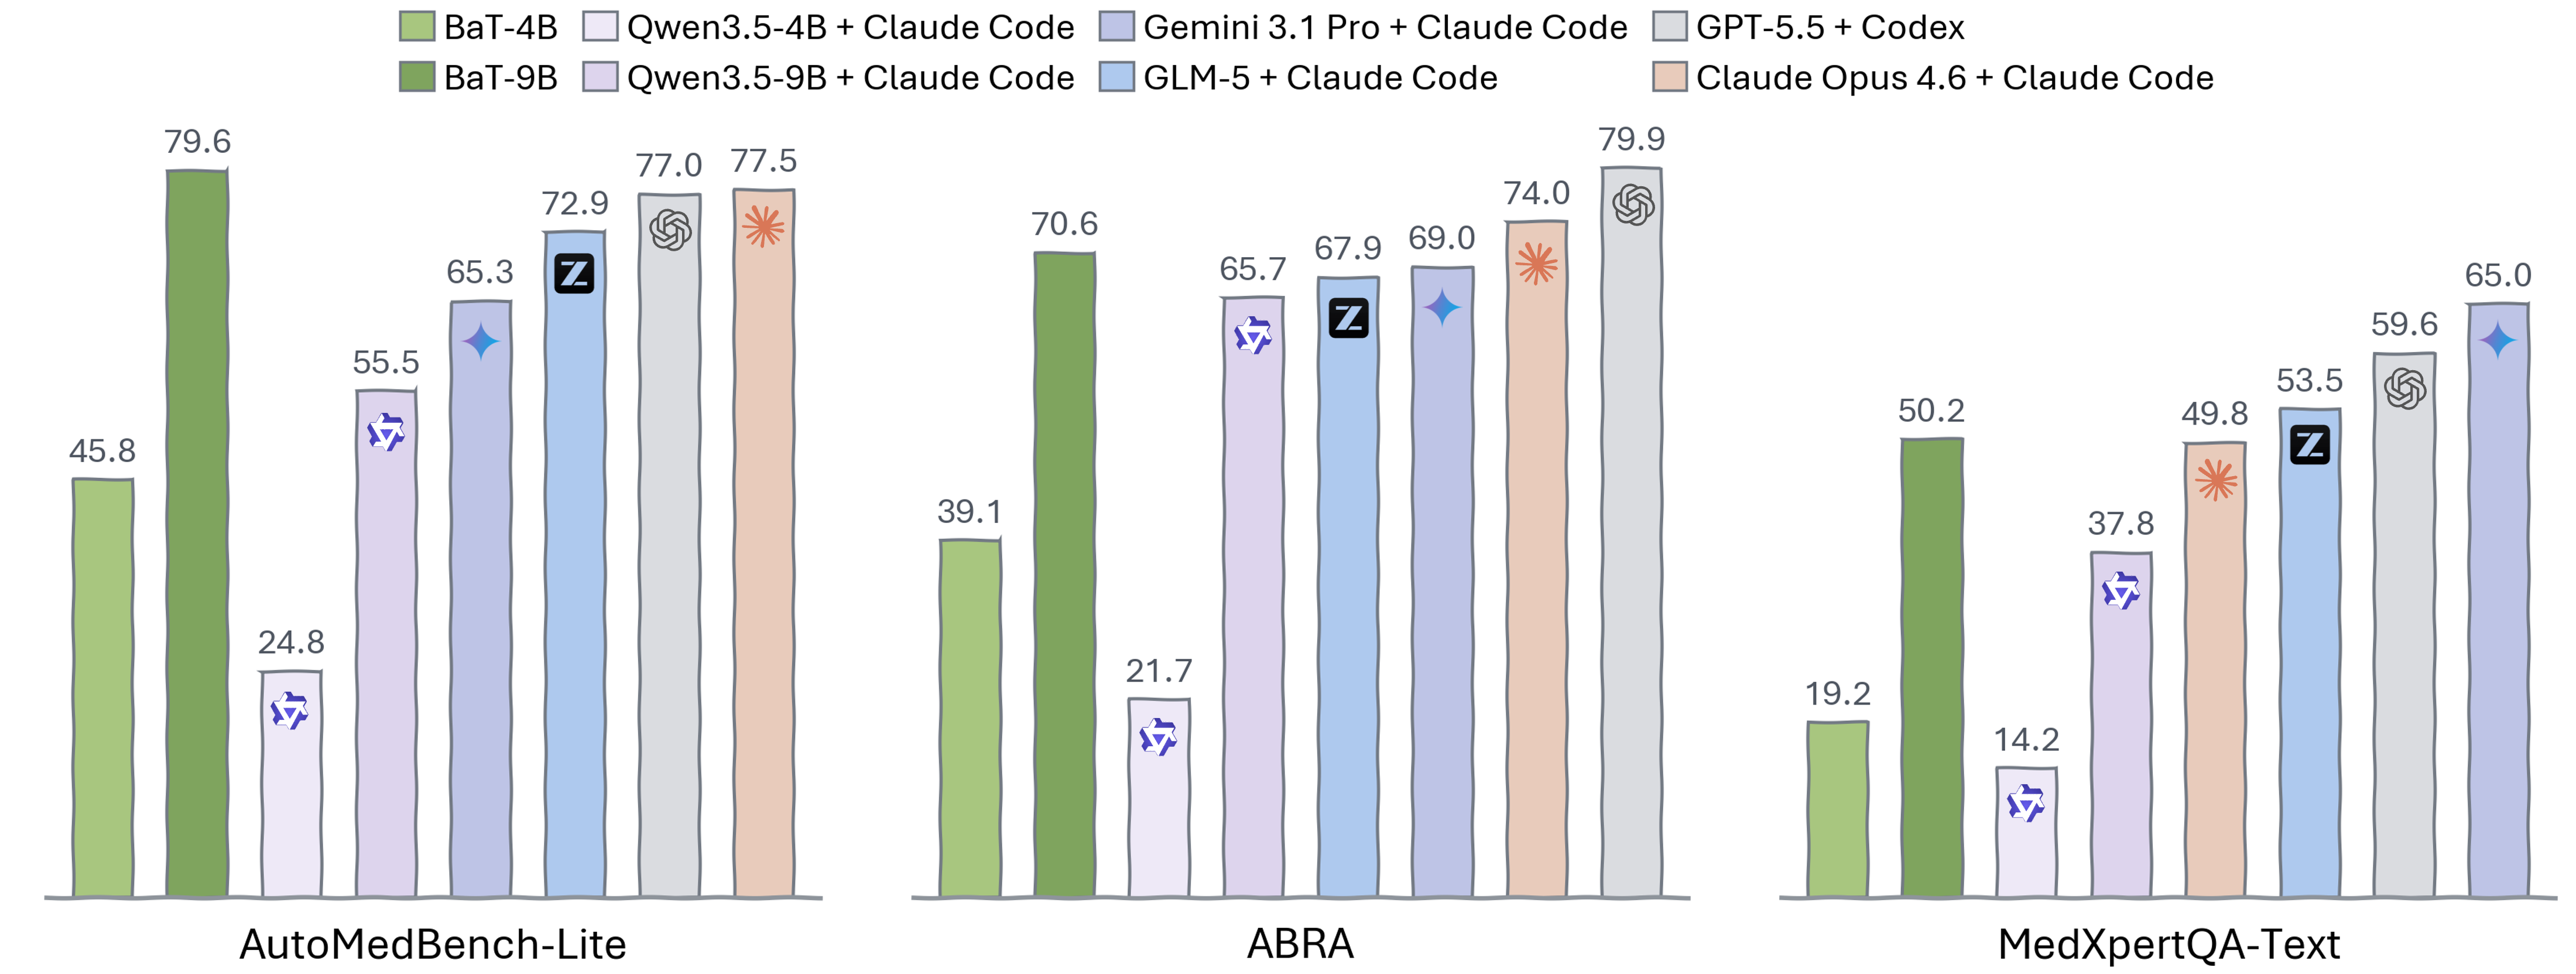
BaT uses OpenHands; other systems use the Codex or Claude Code harness shown in the legend. Comparisons follow each benchmark's scorer; MedXpertQA-Text evaluates text responses.
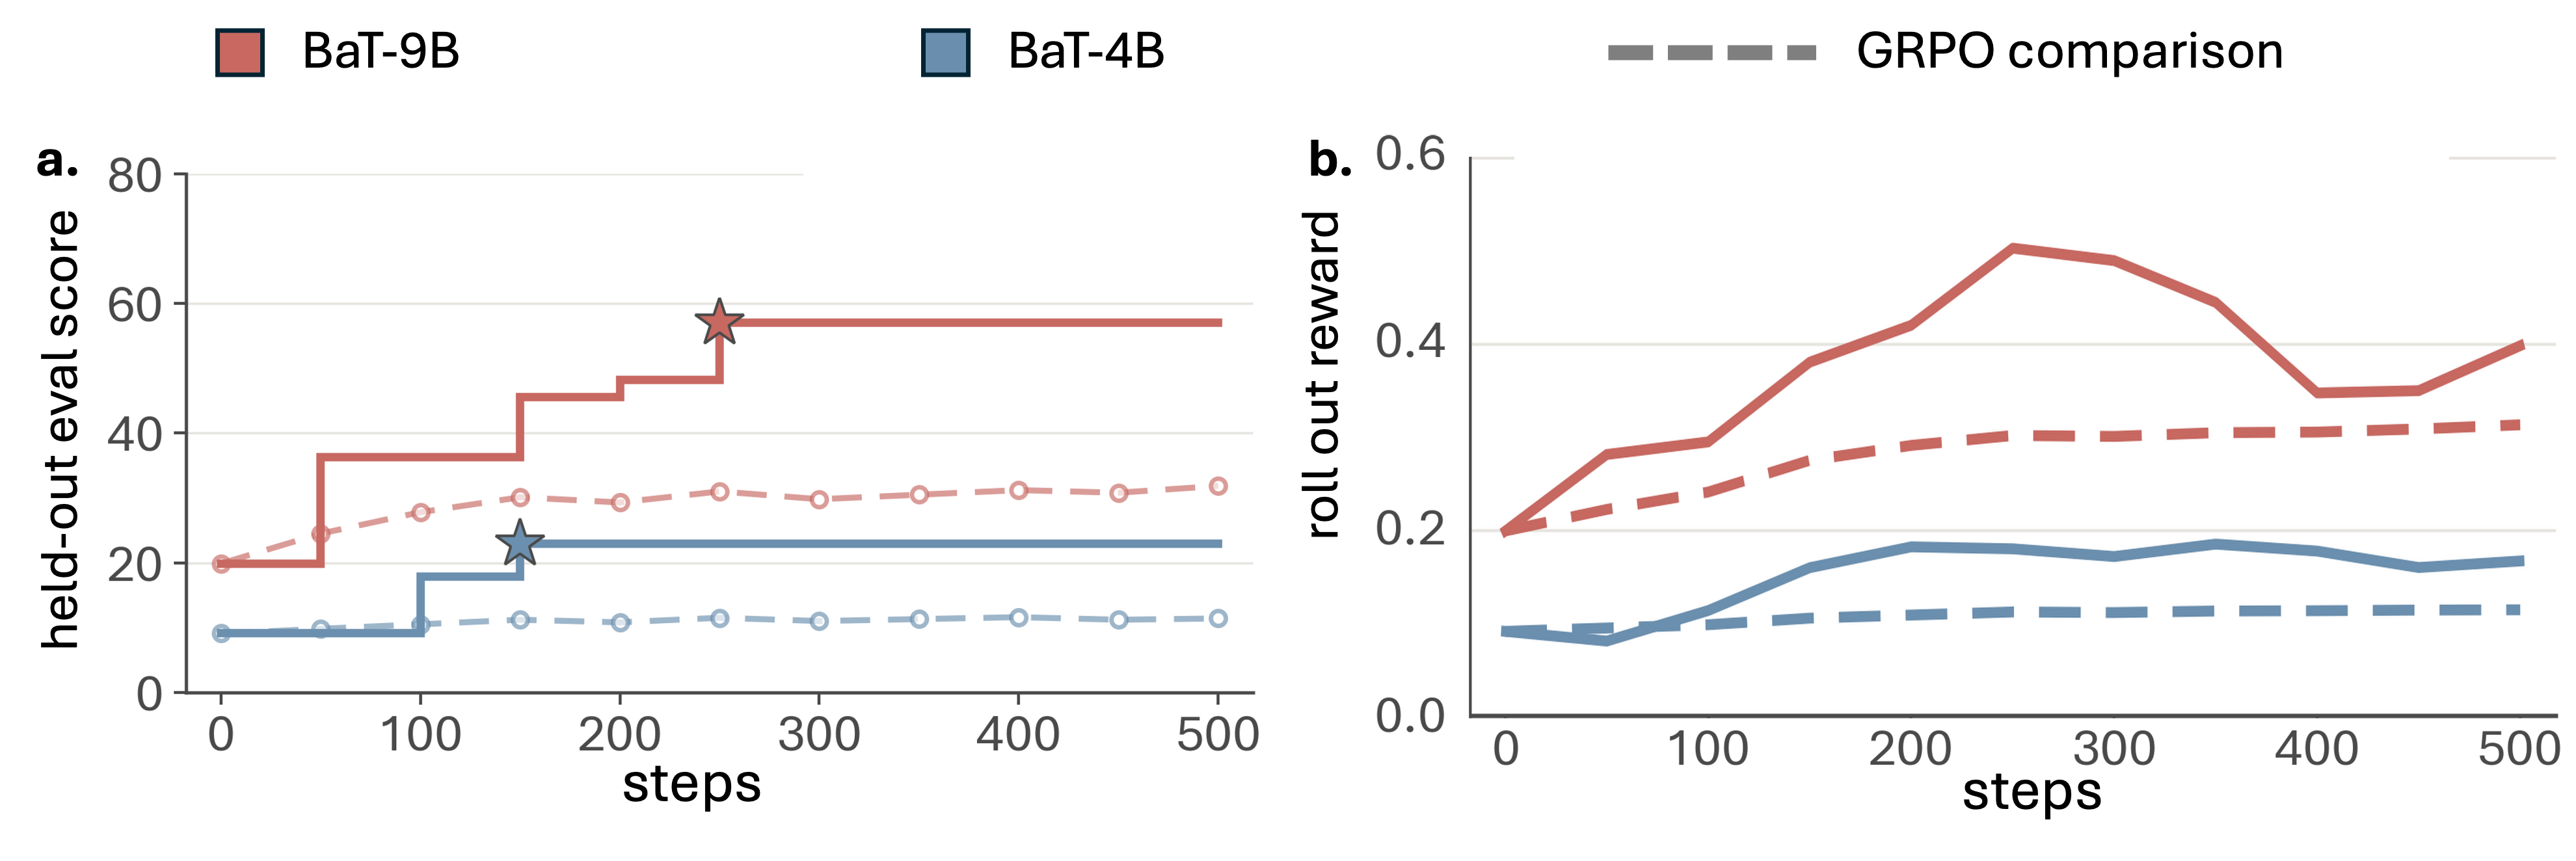
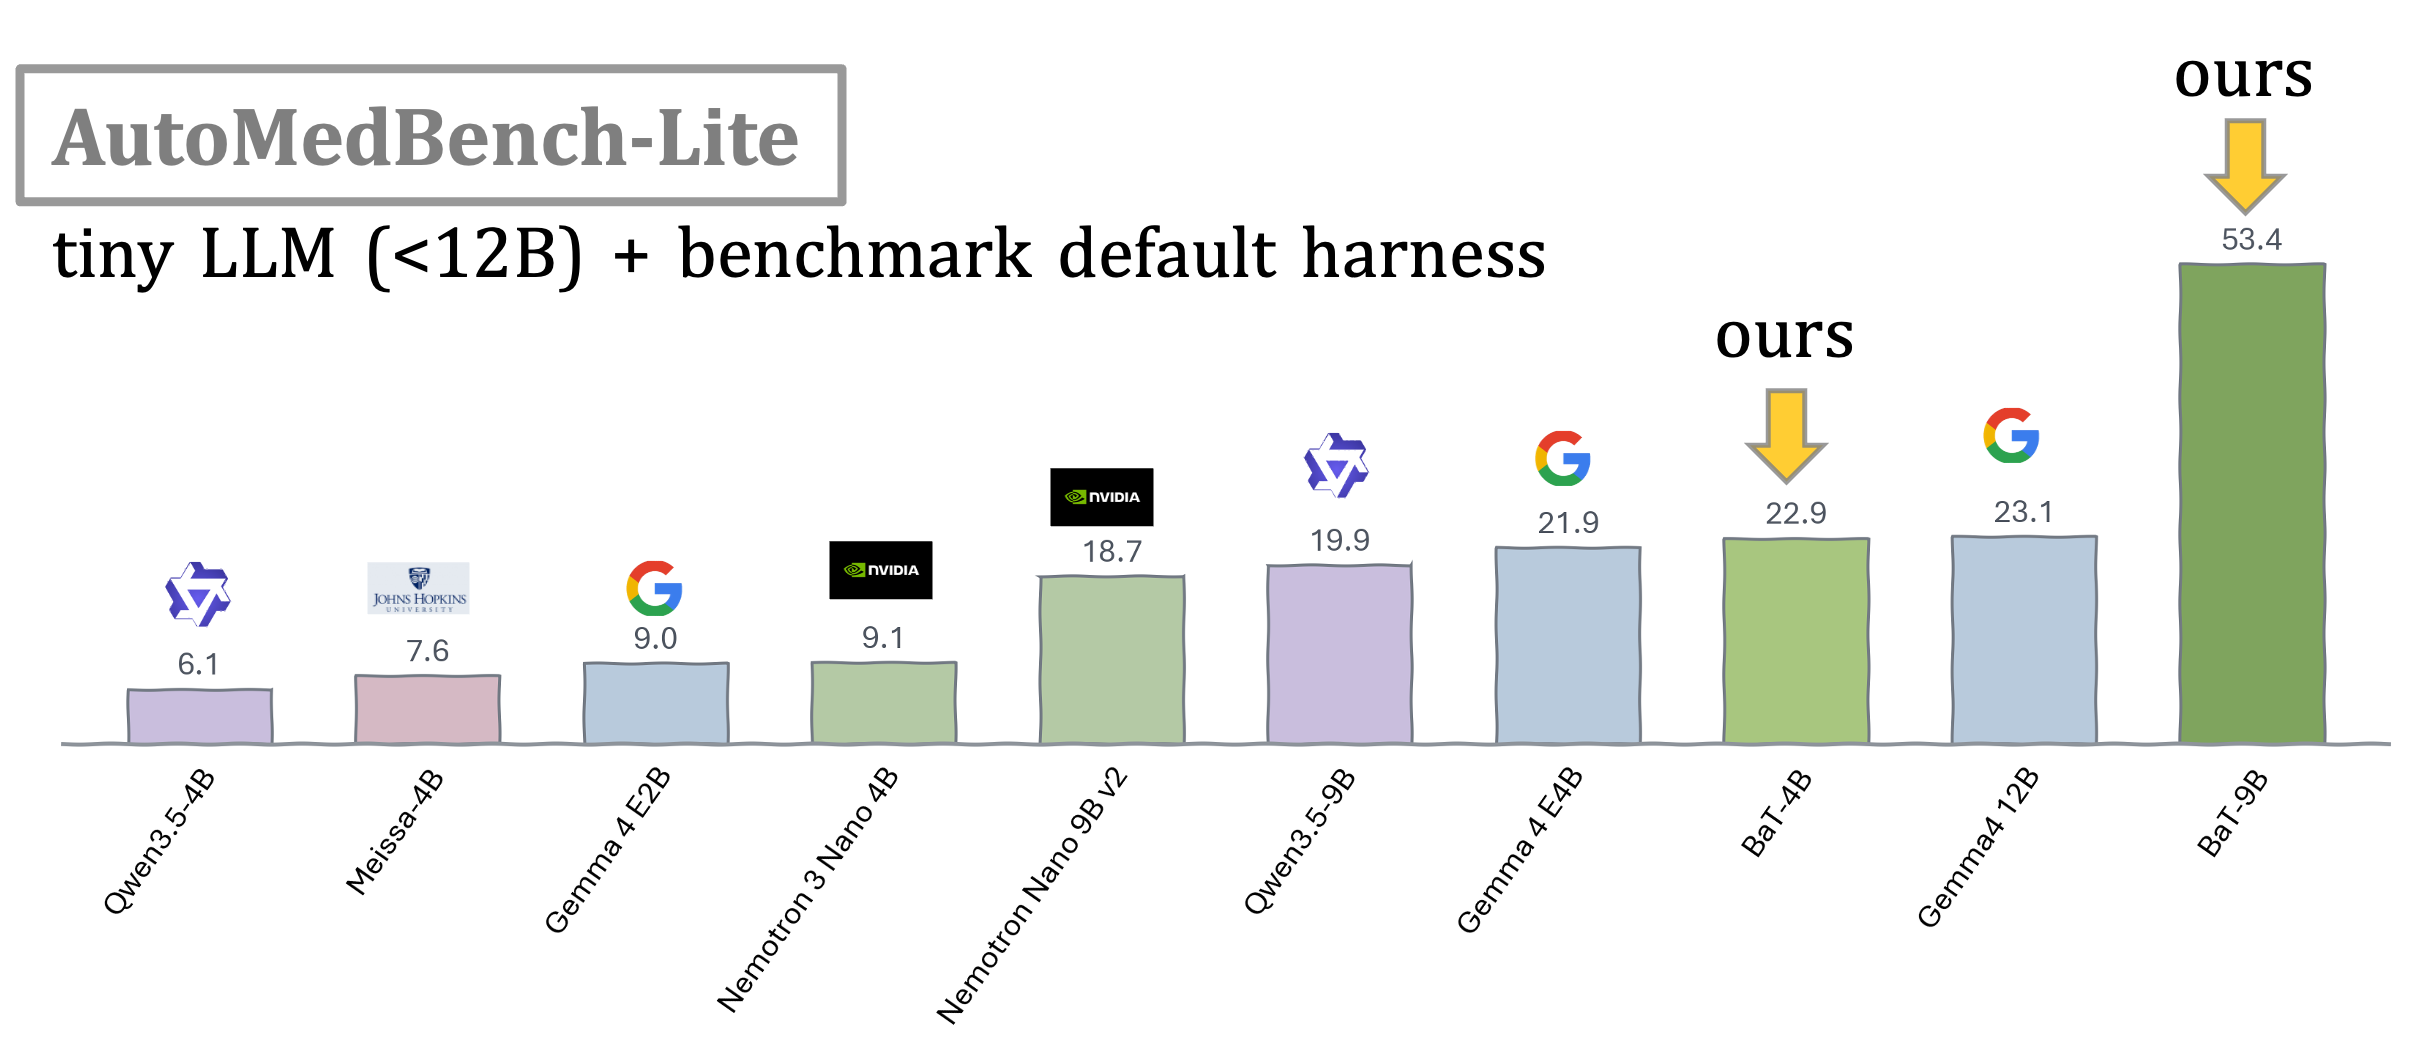
Policy comparisons use the default OpenHands runner. Overall = (Task + Agentic) / 2. These differ from full-agent results above.
| Model / training | Overall | Agentic | Task |
|---|---|---|---|
| Qwen3.5-9B (base) | 19.9 | 11.3 | 28.4 |
| Qwen3.5-9B + SFT | 12.9 | 21.6 | 4.1 |
| Qwen3.5-9B + GRPO | 31.9 | 39.2 | 24.5 |
| BaT-9B (BiCuRL) | 53.4 | 64.7 | 42.1 |
xhigh effort, 64K output tokens per request, 200K context window.xhigh effort; Codex with 258K context and Claude Code with 1M context.Direct model API evaluation, compared only with the corresponding base model under the same protocol. Interactive tasks retain benchmark tools and environments.
| Benchmark | Qwen3.5-9B (base) | BaT-9B | Change (pp) |
|---|---|---|---|
| AIME 2025 | 88.3 | 83.6 | -4.7 |
| AIME 2026 | 92.5 | 86.7 | -5.8 |
| GPQA-Diamond | 81.7 | 78.3 | -3.4 |
| τ²-Bench | 79.1 | 84.5 | +5.4 |
| BFCL-Parity | 79.4 | 68.3 | -11.1 |
| GAIA | 24.9 | 21.2 | -3.7 |
| SWE-bench Verified | 49.0 | 51.8 | +2.8 |
| Terminal Bench 2.0 | 19.9 | 21.3 | +1.4 |
@article{liu2026bat,
title = {BaT: Towards Self-Evolving Medical Research Agent with Stage Rubrics},
author = {Liu, Junqi and He, Yufan and He, Yexiao and Guo, Pengfei and Yang, Dong and Myronenko, Andriy and Zhao, Can and Ye, Hanrong and Qi, Tianhao and Zhou, Yuyin and Xu, Daguang and Tang, Yucheng},
journal = {arXiv preprint arXiv:2608.16211},
year = {2026},
url = {https://arxiv.org/abs/2608.16211}
}
# Gated model: Login with a HF token with gated access permission
hf auth login