

LTX-2: Efficient Joint Audio-Visual Foundation Model
Paper • 2601.03233 • Published • 199
This repository is publicly accessible, but you have to accept the conditions to access its files and content.
Read and accept the LTX-2 Community License, including its commercial-use conditions, before downloading.
Log in or Sign Up to review the conditions and access this model content.
Install the HFTrainer repository before running the commands below. This repository hosts the processed pretrained base; the public-data training outputs are separate. Artifact provenance.
Text-to-audio-video generation with repository-owned model, trainer and inference code.
Verified: 20 real-data training steps, saved checkpoint and native checkpoint-only base inference. Convergence is not established.
All models · Settings · Train · Infer · Evidence · Demos
| Property | Released setting |
|---|---|
| Model | 22B Dev · two-stage + distilled stage-two LoRA |
| Training | Rank-2 LoRA on cached audio/video/text features |
| Training input | 256 × 256 × 49 frames; synchronized audio |
| Public dataset | crema_d_mini |
| Runtime | Local HFTrainer implementation; supporting PyTorch/media libraries and model assets remain dependencies |
Original paper / report · Original code
The original repository is provenance, not a runtime checkout requirement. Third-party notices preserve implementation and asset terms.
| Setting | Training config | Processed checkpoint | Access |
|---|---|---|---|
| 22B Dev · two-stage + distilled stage-two LoRA | config.py | HFTrainer-LTX-2.5-22B-Dev | Accept agreement |
Only the setting above is a released HFTrainer artifact. Its root config.json, weights and all task-required component configs, processors and schedulers are included together. Inference needs only the checkpoint path or Hub ID, plus task inputs.
Pinned weight revision: 7183113f99d3. Original conversion evidence describes the initial export; the current revision adds checkpoint-only dispatch metadata without changing tensors.
Run from the repository root:
python -m pip install -e ".[ltx-video]"
python -m pip install "huggingface_hub>=0.34,<2"
Verified on one NVIDIA H200 with PyTorch 2.8.0+cu128. This is the tested environment, not a measured minimum-memory requirement. The complete artifact is about 75 GB; it includes the projected Gemma encoder, both VAEs, upsampler and second-stage LoRA. Install system FFmpeg (ffmpeg and ffprobe) for media preparation.
Access: Accept agreement. Open the checkpoint page, satisfy its model agreement, and run hf auth login before the commands below.
The recipe downloads ZeyuLing/hftrainer_crema_d_mini to data/hftrainer_crema_d_mini. Split counts: 24 train / 8 validation / 0 test. Dataset source, license, transformations and checksum verification are documented in Public demo datasets.
Model features are cached locally. Remove this model's directory under data/hftrainer_crema_d_mini/.cache/ before changing the base checkpoint or preprocessing geometry. The script never substitutes synthetic samples for missing real media.
One command downloads pinned data and weights, prepares required caches, and runs the 20-step recipe:
python tools/run_public_demo.py ltx_video
Reuse downloaded weights with --checkpoint path/to/complete_bundle; change the output directory with --work-dir path/to/run. The underlying command is python tools/train.py configs/public_data/ltx_video.py. Seed: 42. Training logs and checkpoints are saved under work_dirs/public_data/ltx_video/. If you reused a custom checkpoint directory, set HFTRAINER_CHECKPOINT to that directory before directly invoking training, resume or export commands.
The managed trainer writes metrics.jsonl, a LoRA safetensors file and a full training-state checkpoint. See the resume and adapter contract.
Resume with python tools/train.py configs/public_data/ltx_video.py --auto-resume --cfg-options trainer.native_config.optimization.steps=40. This recipe saves full optimizer state alongside its LoRA.
Run the processed pretrained base, independently of any training config:
python tools/infer.py --model ZeyuLing/HFTrainer-LTX-2.5-22B-Dev \
  --revision 7183113f99d3bbe80500ecb852c6a6897d593cbf --device cuda --seed 42 \
  --prompt "A close-up of a woman speaking calmly to the camera, natural facial expressions, soft daylight, detailed face, steady camera." \
  --height 512 --width 768 --num-frames 121 --num-steps 30 --output outputs/ltx.mp4
--model also accepts a local complete checkpoint directory. A resumable training checkpoint is not a standalone model: export with tools/export_model.py using the matching training config, then pass the exported directory to --model. Artifact and configuration contract.
To package this training run as a complete checkpoint (including its frozen base components):
python tools/export_model.py --config configs/public_data/ltx_video.py \
  --checkpoint work_dirs/public_data/ltx_video/checkpoints/lora_weights_step_00020.safetensors --output exports/ltx_video
Then run the inference command above with --model exports/ltx_video and omit --revision. Complete exports duplicate the base weights; allow sufficient disk space.
Detailed implementation notes · Historical official comparison protocol and measurements.
Earlier independent official dev comparisons matched conditioning and both denoising stages. The face sample matched decoded pixels and audio when both sides used deterministic audio decoding. This comparison used the base, not the new CREMA-D adapter.
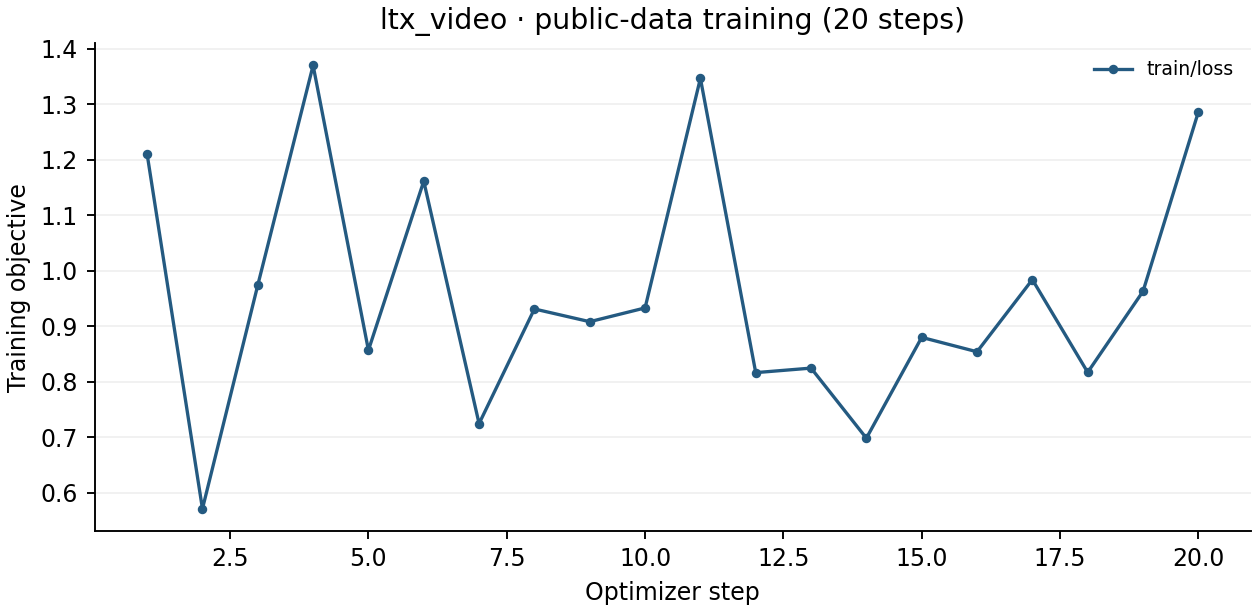
Raw training record · Training log
These are raw, unsmoothed objectives on the public dataset. Twenty steps establish pipeline execution, not convergence. Loss values are not comparable across models.
No held-out perceptual quality metric was measured for this short run.
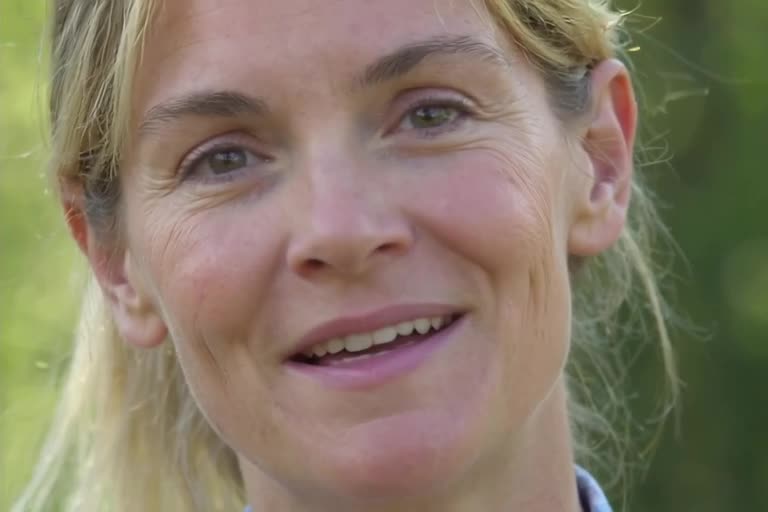
Play/download the generated video. Untouched published base, seed 42; prompt and sampler settings match the inference command above. Includes generated stereo audio. This is separate from the short public-data fine-tuning run.
The paper link describes the LTX-2 foundation; the original repository documents the 2.5 release. Separate distilled weights, HDR, image conditioning and multi-GPU execution were not fully validated. Image-conditioned Gemma prompt enhancement is unsupported. Accept the LTX-2.x model agreement before downloading.
@misc{hacohen2026ltx2,
  title = {LTX-2: Efficient Joint Audio-Visual Foundation Model},
  author = {Yoav HaCohen and others},
  year = {2026},
  eprint = {2601.03233},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2601.03233}
}
Also retain the dataset citation and attribution.