

KVpop -- Key-Value Cache Compression with Predictive Online Pruning
Paper • 2607.05061 • Published • 21
# pip install -U transformers accelerate
# Load model directly
from transformers import AutoModelForCausalLM
model = AutoModelForCausalLM.from_pretrained("sirluk/Qwen3-8B-KVpop-4x", trust_remote_code=True, device_map="auto")

KVpop uses future-attention targets to train lightweight importance scorers; at inference it keeps a bounded sink + scored top-k + recent-window cache.
Qwen3-8B-KVpop-4x is a self-contained, KV-cache-compressed variant of Qwen3-8B, retrofitted with KVpop. Each self-attention layer uses a small, per-KV-head mLSTM scorer to predict which older tokens will be useful to future queries. The inference cache keeps only
[ sink tokens ] + [ top-k scored tokens ] + [ sliding window ]
The model was distilled at a 16,384-token context with ~75% KV-cache
compression (4x). The cache holds at most 4,032 entries per head: 4 sink +
3,772 scored long-range + 256 recent tokens. A literal quarter of 16,384 is
4,096; the remaining 64-entry equivalent is reserved for the stateful scorer
memory so the overall memory budget remains comparable.
This repository is self-contained: the model code, the custom cache, and
the weights are all included and loaded through trust_remote_code. The
required mLSTM kernels are vendored in kvpop_mlstm_kernels.py; the external
mlstm_kernels Python package is not required.
The stateful scorer waits until a token leaves the protected recent window before assigning its long-range score, allowing its mLSTM memory to incorporate near-future context. In the paper ablation, delayed readout improves token accuracy by 0.2 percentage points over immediate mLSTM scoring after 2,000 training steps.

Token accuracy during training with and without delayed readout.
In the paper's batch-size-1 Qwen3-8B benchmark at 75% KV-cache compression, KVpop's uniform per-head cache yields substantially lower end-to-end latency as generation length grows. Measurements are benchmark-specific; see the paper for the full protocol.
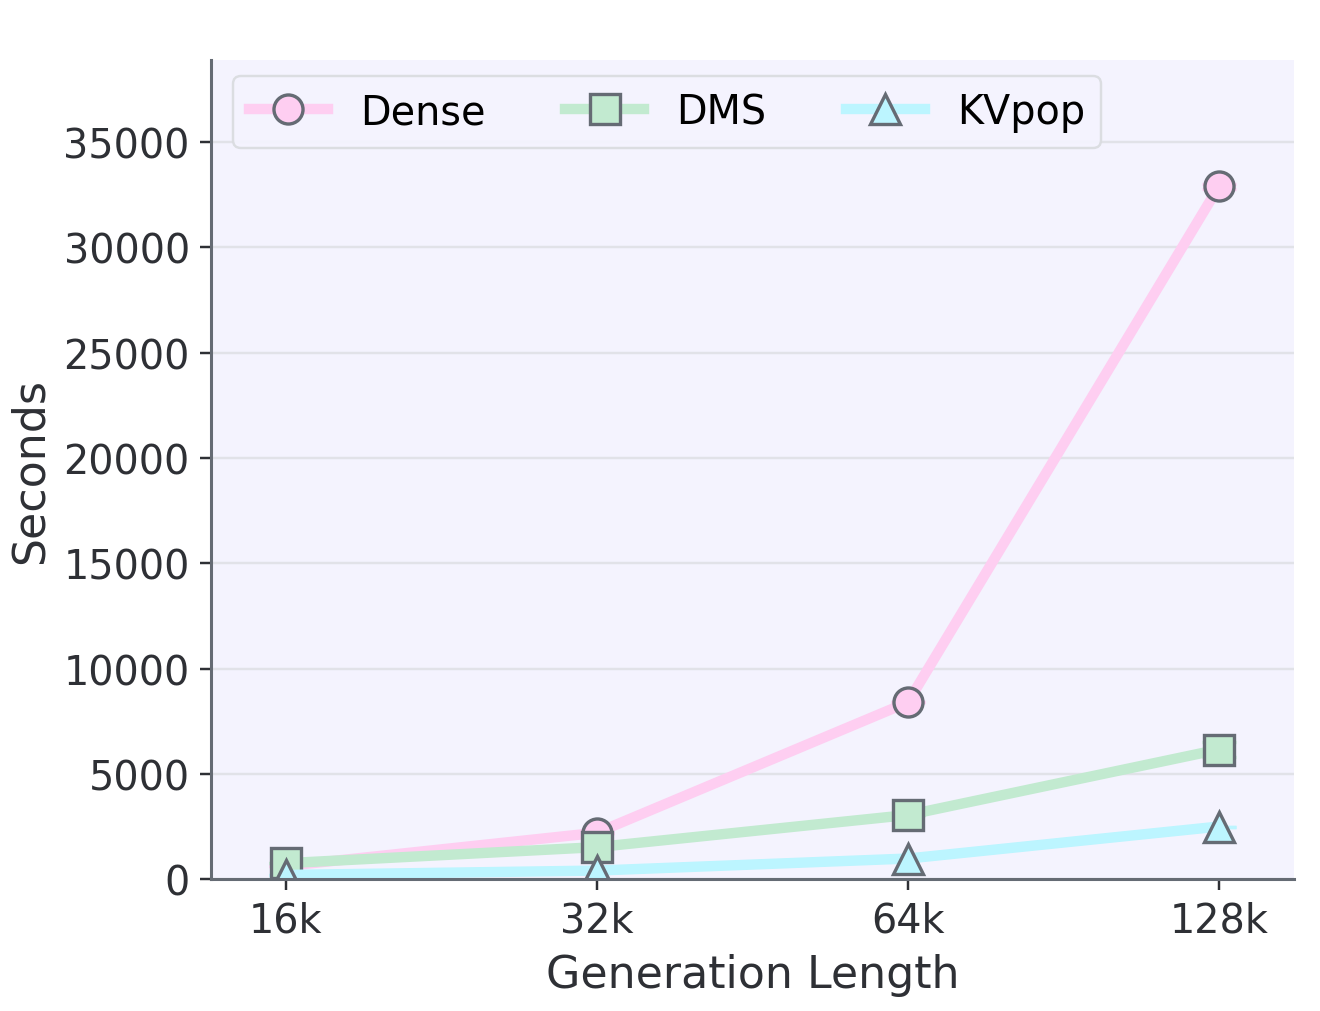
End-to-end decoding latency for dense attention, DMS, and KVpop.
Pass@1 is estimated with 16 rollouts per prompt. Abs. is the mean across the
four benchmarks and Rel. is relative to the dense teacher.
| Model | Compression | AIME 2024 | AIME 2025 | HMMT 2502 | HMMT 2511 | Avg. Abs. | Avg. Rel. |
|---|---|---|---|---|---|---|---|
| Dense Qwen3-8B teacher | — | 0.58 | 0.49 | 0.28 | 0.37 | 0.43 | 1.00 |
| Qwen3-8B-KVpop-4x (this checkpoint) | 75% | 0.57 | 0.48 | 0.31 | 0.38 | 0.44 | 1.00 |
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer
model_id = "sirluk/Qwen3-8B-KVpop-4x" # or a local path to this folder
tok = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
model_id,
trust_remote_code=True,
dtype=torch.bfloat16,
).to("cuda").eval()
messages = [{"role": "user", "content": "Explain why the sky is blue."}]
inputs = tok.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt").to("cuda")
out = model.generate(inputs, max_new_tokens=256, do_sample=False) # use_cache=True by default
print(tok.decode(out[0, inputs.shape[1]:], skip_special_tokens=True))
A ready-to-run check is included: python verify_generation.py.
Note — A CUDA GPU is required. The scorer uses a triton kernel (prefix top-k thresholds) and the mLSTM backend, which do not run on CPU. The model constructs and loads on CPU, but generation must run on GPU.
The sparse KV cache comes in two flavours; both keep the same fixed budget:
| Backend | Default | How to select | Notes |
|---|---|---|---|
| Dynamic | ✅ | (default) | Grows then prunes. Robust, no torch.compile needed. |
| Static | config.use_static_cache=True or env USE_STATIC_CACHE=1 |
Fixed-size buffers with the same sink + scored top-k + sliding-window budget. |
To force the static cache for a whole Python process, set USE_STATIC_CACHE=1 before loading the model:
USE_STATIC_CACHE=1 python verify_generation.py
USE_STATIC_CACHE=1 python your_generation_script.py
You can also select it in Python after loading and before calling generate():
model.config.use_static_cache = True
out = model.generate(inputs, max_new_tokens=256)
model.generate(...) defaults use_cache=True so the sparse cache is always
engaged. With use_cache=False the model still produces correct outputs but
recomputes attention densely each step (no compression benefit).
The maximum context (max_position_embeddings) is 40960 (inherited from
Qwen3-8B); the model was distilled at a 16384-token context.
python>=3.10
torch>=2.7.0
transformers>=4.57.1
safetensors
triton # required (ships with torch on Linux/CUDA)
flash-attn # optional; SDPA fallback if absent
See requirements.txt.
| File | Purpose |
|---|---|
configuration_qwen3_kvpop.py |
Qwen3KVPopConfig (Qwen3 config + sparse-attention hyperparameters) |
modeling_qwen3_kvpop.py |
Qwen3KVPopForCausalLM / Qwen3KVPopModel (attention swap + cache injection) |
kvpop_attention.py |
the sparse-attention layer (Qwen3SparseAttnLinear, inference path) |
kvpop_cache.py |
the sink + top-k + sliding-window KV cache (dynamic & static) |
kvpop_kernels.py |
headwise projections, mLSTM scorer backend, learnable decay, triton top-k |
kvpop_mlstm_kernels.py |
vendored mLSTM chunkwise/recurrent kernels; replaces the external mlstm_kernels dependency |
resources/ |
paper figures displayed in the model card (PNG) |
verify_generation.py |
GPU smoke test |
LICENSE, LICENSE-APACHE-2.0, NOTICE |
governing license and third-party attribution material |
| Parameter | Value |
|---|---|
KV budget (sparse_attention_budget) |
4032 |
Sliding window (sliding_window_bias) |
256 |
Sink tokens (sink_bias) |
4 |
| Scored top-k budget | 3772 |
| Scorer | mLSTM, hedgehog features, no value projection, chunkwise--native_custbw |
| Learnable per-head decay | yes |
| Base model | Qwen/Qwen3-8B (36 layers, 4096 hidden, 32 / 8 heads, head_dim 128) |
| dtype | bfloat16 |
This model and the NXAI-authored inference code are released under the NXAI Community License. Built with technology from NXAI.
The package also contains Apache-2.0-licensed Qwen3/Transformers-derived material and third-party components retained from the vendored mLSTM kernels. See LICENSE-APACHE-2.0 and NOTICE for the component attributions and applicable notices.
The paper figures under resources/ are reproduced from the KVpop paper under
CC BY 4.0. See NOTICE
for attribution.
If you use this model, please cite the KVpop paper.
@misc{kvpop2026,
title={KVpop -- Key-Value Cache Compression with Predictive Online Pruning},
author={Lukas Hauzenberger and Niklas Schmidinger and Anamaria-Roberta Hartl and David Stap and Thomas Schmied and Sebastian Böck and Günter Klambauer and Sepp Hochreiter},
year={2026},
eprint={2607.05061},
archivePrefix={arXiv},
primaryClass={cs.LG},
url={https://arxiv.org/abs/2607.05061},
}
# Use a pipeline as a high-level helper
from transformers import pipeline

pipe = pipeline("text-generation", model="sirluk/Qwen3-8B-KVpop-4x", trust_remote_code=True)
messages = [
    {"role": "user", "content": "Who are you?"},
]
pipe(messages)